Q9ZQR6
Gene name |
At2g14540 (T13P21.8) |
Protein name |
Serpin-Z2 |
Names |
ArathZ2 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT2G14540 |
EC number |
|
Protein Class |
|
Descriptions
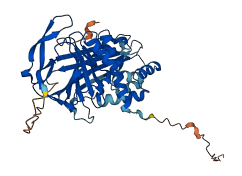
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9ZQR6
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9ZQR6-F1 | Predicted | AlphaFoldDB |
167 variants for Q9ZQR6
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH05462563 | 2 | D>N | No | 1000Genomes | |
| tmp_2_6199377_C_T | 5 | R>K | No | 1000Genomes | |
| ENSVATH01787940 | 7 | N>K | No | 1000Genomes | |
| tmp_2_6199366_C_A | 9 | E>* | No | 1000Genomes | |
| ENSVATH05462562 | 11 | S>I | No | 1000Genomes | |
| ENSVATH01787939 | 12 | T>I | No | 1000Genomes | |
| ENSVATH14450278 | 13 | S>L | No | 1000Genomes | |
| tmp_2_6199347_G_T | 15 | T>N | No | 1000Genomes | |
| ENSVATH13092832 | 16 | A>T | No | 1000Genomes | |
| ENSVATH14450277 | 28 | K>R | No | 1000Genomes | |
| tmp_2_6199302_T_A | 30 | D>V | No | 1000Genomes | |
| ENSVATH14450276 | 34 | A>T | No | 1000Genomes | |
| tmp_2_6199285_T_A | 36 | K>* | No | 1000Genomes | |
| tmp_2_6199276_T_C | 39 | N>D | No | 1000Genomes | |
| ENSVATH14450275 | 39 | N>I | No | 1000Genomes | |
| ENSVATH05462559 | 40 | E>D | No | 1000Genomes | |
| tmp_2_6199254_A_C | 46 | V>G | No | 1000Genomes | |
| ENSVATH05462558 | 47 | G>R | No | 1000Genomes | |
| ENSVATH05462557 | 52 | A>T | No | 1000Genomes | |
| ENSVATH05462555 | 63 | P>L | No | 1000Genomes | |
| tmp_2_6199200_G_T | 64 | A>E | No | 1000Genomes | |
| ENSVATH01787937 | 65 | S>F | No | 1000Genomes | |
| tmp_2_6199191_T_G | 67 | N>T | No | 1000Genomes | |
| ENSVATH00228730 | 69 | V>F | No | 1000Genomes | |
| ENSVATH00228730 | 69 | V>I | No | 1000Genomes | |
| tmp_2_6199180_T_G | 71 | T>P | No | 1000Genomes | |
| ENSVATH00228729 | 76 | N>T | No | 1000Genomes | |
| tmp_2_6199161_G_A | 77 | T>I | No | 1000Genomes | |
| ENSVATH05462553 | 79 | N>S | No | 1000Genomes | |
| ENSVATH05462552 | 87 | L>F | No | 1000Genomes | |
| ENSVATH14450243 | 92 | S>F | No | 1000Genomes | |
| tmp_2_6199113_G_A | 93 | S>F | No | 1000Genomes | |
| ENSVATH13092826 | 95 | T>I | No | 1000Genomes | |
| ENSVATH05462549 | 107 | S>F | No | 1000Genomes | |
| ENSVATH05462549 | 107 | S>Y | No | 1000Genomes | |
| ENSVATH07863470 | 112 | D>A | No | 1000Genomes | |
| ENSVATH05462548 | 112 | D>E | No | 1000Genomes | |
| ENSVATH05462546 | 113 | G>E | No | 1000Genomes | |
| ENSVATH05462547 | 113 | G>R | No | 1000Genomes | |
| ENSVATH05462545 | 116 | T>I | No | 1000Genomes | |
| ENSVATH05462545 | 116 | T>R | No | 1000Genomes | |
| ENSVATH05462543 | 124 | V>F | No | 1000Genomes | |
| tmp_2_6199014_C_G | 126 | G>A | No | 1000Genomes | |
| tmp_2_6198985_T_C | 136 | N>D | No | 1000Genomes | |
| ENSVATH14450242 | 137 | P>L | No | 1000Genomes | |
| ENSVATH05462541 | 139 | W>R | No | 1000Genomes | |
| ENSVATH05462538 | 144 | L>P | No | 1000Genomes | |
| ENSVATH05462538 | 144 | L>R | No | 1000Genomes | |
| ENSVATH05462536 | 152 | A>P | No | 1000Genomes | |
| ENSVATH13092804 | 154 | V>F | No | 1000Genomes | |
| ENSVATH13092804 | 154 | V>I | No | 1000Genomes | |
| tmp_2_6198928_C_G | 155 | D>H | No | 1000Genomes | |
| ENSVATH05462535 | 157 | R>* | No | 1000Genomes | |
| ENSVATH05462534 | 159 | K>T | No | 1000Genomes | |
| ENSVATH05462514 | 165 | L>M | No | 1000Genomes | |
| ENSVATH05462514 | 165 | L>V | No | 1000Genomes | |
| ENSVATH05462512 | 166 | D>E | No | 1000Genomes | |
| tmp_2_6198640_G_A | 169 | T>M | No | 1000Genomes | |
| ENSVATH01787933 | 173 | R>C | No | 1000Genomes | |
| tmp_2_6198622_G_C | 175 | T>S | No | 1000Genomes | |
| ENSVATH13092798 | 176 | N>Y | No | 1000Genomes | |
| ENSVATH05462510 | 177 | D>N | No | 1000Genomes | |
| tmp_2_6198613_A_C | 178 | L>R | No | 1000Genomes | |
| ENSVATH13092797 | 185 | R>H | No | 1000Genomes | |
| ENSVATH05462509 | 188 | V>A | No | 1000Genomes | |
| ENSVATH01787932 | 189 | T>R | No | 1000Genomes | |
| tmp_2_6198564_C_T | 194 | W>* | No | 1000Genomes | |
| tmp_2_6198554_T_G | 198 | N>H | No | 1000Genomes | |
| ENSVATH05462507 | 211 | D>N | No | 1000Genomes | |
| ENSVATH13092796 | 214 | M>T | No | 1000Genomes | |
| ENSVATH05462506 | 215 | T>K | No | 1000Genomes | |
| ENSVATH05462506 | 215 | T>R | No | 1000Genomes | |
| ENSVATH05462505 | 217 | D>H | No | 1000Genomes | |
| ENSVATH05462505 | 217 | D>N | No | 1000Genomes | |
| ENSVATH05462503 | 219 | P>Q | No | 1000Genomes | |
| ENSVATH05462502 | 220 | F>S | No | 1000Genomes | |
| ENSVATH05462500 | 225 | G>D | No | 1000Genomes | |
| tmp_2_6198460_G_A | 229 | S>F | No | 1000Genomes | |
| ENSVATH05462499 | 229 | S>T | No | 1000Genomes | |
| tmp_2_6198450_G_T | 232 | F>L | No | 1000Genomes | |
| ENSVATH05462498 | 234 | R>G | No | 1000Genomes | |
| ENSVATH01787931 | 234 | R>I | No | 1000Genomes | |
| tmp_2_6198439_T_A,G | 236 | Y>F | No | 1000Genomes | |
| tmp_2_6198439_T_A,G | 236 | Y>S | No | 1000Genomes | |
| ENSVATH05462497 | 237 | E>K | No | 1000Genomes | |
| ENSVATH05462497 | 237 | E>Q | No | 1000Genomes | |
| ENSVATH13092795 | 238 | K>N | No | 1000Genomes | |
| ENSVATH01787930 | 238 | K>R | No | 1000Genomes | |
| ENSVATH05462496 | 242 | E>Q | No | 1000Genomes | |
| ENSVATH13092774 | 243 | A>T | No | 1000Genomes | |
| ENSVATH05462495 | 246 | G>S | No | 1000Genomes | |
| tmp_2_6198395_G_A | 251 | R>C | No | 1000Genomes | |
| ENSVATH05462494 | 252 | L>F | No | 1000Genomes | |
| ENSVATH05462493 | 257 | G>R | No | 1000Genomes | |
| ENSVATH13092772 | 260 | D>E | No | 1000Genomes | |
| ENSVATH14450236 | 263 | R>C | No | 1000Genomes | |
| ENSVATH14450236 | 263 | R>S | No | 1000Genomes | |
| ENSVATH00228726 | 264 | E>K | No | 1000Genomes | |
| tmp_2_6198349_GA_GAA,AA,G | 266 | S>L | No | 1000Genomes | |
| ENSVATH13092771 | 271 | L>F | No | 1000Genomes | |
| ENSVATH05462489 | 272 | P>H | No | 1000Genomes | |
| ENSVATH05462489 | 272 | P>L | No | 1000Genomes | |
| tmp_2_6198332_G_A | 272 | P>S | No | 1000Genomes | |
| ENSVATH01787928 | 277 | E>G | No | 1000Genomes | |
| ENSVATH14450235 | 281 | L>F | No | 1000Genomes | |
| tmp_2_6198295_C_A | 284 | R>I | No | 1000Genomes | |
| ENSVATH01787925 | 285 | I>M | No | 1000Genomes | |
| ENSVATH01787926 | 285 | I>V | No | 1000Genomes | |
| ENSVATH01787924 | 288 | N>T | No | 1000Genomes | |
| ENSVATH01787923 | 289 | P>S | No | 1000Genomes | |
| tmp_2_6198278_C_A | 290 | G>* | No | 1000Genomes | |
| ENSVATH01787922 | 292 | L>F | No | 1000Genomes | |
| ENSVATH01787921 | 295 | H>D | No | 1000Genomes | |
| tmp_2_6198260_T_C | 296 | I>V | No | 1000Genomes | |
| tmp_2_6198257_G_C,A | 297 | P>A | No | 1000Genomes | |
| ENSVATH01787920 | 297 | P>L | No | 1000Genomes | |
| ENSVATH01787920 | 297 | P>Q | No | 1000Genomes | |
| tmp_2_6198257_G_C,A | 297 | P>S | No | 1000Genomes | |
| ENSVATH01787919 | 298 | E>K | No | 1000Genomes | |
| ENSVATH05462488 | 298 | E>V | No | 1000Genomes | |
| tmp_2_6198248_G_A,C | 300 | R>C | No | 1000Genomes | |
| tmp_2_6198248_G_A,C | 300 | R>G | No | 1000Genomes | |
| ENSVATH13092769 | 300 | R>H | No | 1000Genomes | |
| ENSVATH13092769 | 300 | R>L | No | 1000Genomes | |
| ENSVATH00228725 | 301 | V>I | No | 1000Genomes | |
| tmp_2_6198233_C_T | 305 | D>N | No | 1000Genomes | |
| ENSVATH01787917 | 308 | I>F | No | 1000Genomes | |
| ENSVATH01787916 | 308 | I>N | No | 1000Genomes | |
| tmp_2_6198220_G_A | 309 | P>L | No | 1000Genomes | |
| tmp_2_6198221_G_A | 309 | P>S | No | 1000Genomes | |
| ENSVATH13092768 | 312 | K>Q | No | 1000Genomes | |
| tmp_2_6198194_C_G | 318 | E>Q | No | 1000Genomes | |
| ENSVATH05462485 | 319 | A>V | No | 1000Genomes | |
| ENSVATH05462484 | 331 | S>L | No | 1000Genomes | |
| ENSVATH05462483 | 333 | H>L | No | 1000Genomes | |
| tmp_2_6198147_G_T | 333 | H>Q | No | 1000Genomes | |
| ENSVATH00228724 | 334 | Q>H | No | 1000Genomes | |
| ENSVATH05462482 | 343 | E>D | No | 1000Genomes | |
| ENSVATH05462481 | 348 | A>T | No | 1000Genomes | |
| ENSVATH13092766 | 349 | A>G | No | 1000Genomes | |
| tmp_2_6198101_C_T | 349 | A>T | No | 1000Genomes | |
| ENSVATH05462480 | 351 | T>S | No | 1000Genomes | |
| ENSVATH01787911 | 353 | V>I | No | 1000Genomes | |
| tmp_2_6198083_C_T | 355 | V>I | No | 1000Genomes | |
| ENSVATH00228723 | 357 | T>I | No | 1000Genomes | |
| ENSVATH07863467 | 358 | G>D | No | 1000Genomes | |
| tmp_2_6198067_C_A | 360 | C>F | No | 1000Genomes | |
| tmp_2_6198041_C_T | 369 | D>N | No | 1000Genomes | |
| ENSVATH05462477 | 371 | V>M | No | 1000Genomes | |
| tmp_2_6198012_A_T | 378 | F>L | No | 1000Genomes | |
| ENSVATH01787909 | 378 | F>Y | No | 1000Genomes | |
| ENSVATH05462476 | 379 | L>F | No | 1000Genomes | |
| ENSVATH01787908 | 382 | E>V | No | 1000Genomes | |
| ENSVATH13092743 | 386 | G>E | No | 1000Genomes | |
| tmp_2_6197990_C_T | 386 | G>R | No | 1000Genomes | |
| ENSVATH01787907 | 389 | L>F | No | 1000Genomes | |
| ENSVATH05462472 | 391 | A>V | No | 1000Genomes | |
| ENSVATH05462471 | 392 | G>R | No | 1000Genomes | |
| ENSVATH13092741 | 399 | E>* | No | 1000Genomes | |
| ENSVATH05462470 | 401 | S>F | No | 1000Genomes | |
| ENSVATH05462469 | 402 | S>F | No | 1000Genomes | |
| ENSVATH01787905 | 403 | A>P | No | 1000Genomes | |
| ENSVATH01787905 | 403 | A>T | No | 1000Genomes | |
| ENSVATH05462468 | 403 | A>V | No | 1000Genomes | |
| ENSVATH05462467 | 406 | R>Q | No | 1000Genomes | |
| ENSVATH00228722 | 406 | R>W | No | 1000Genomes | |
| ENSVATH01787903 | 407 | A>S | No | 1000Genomes |
No associated diseases with Q9ZQR6
2 GO annotations of cellular component
| Name | Definition |
|---|---|
| extracellular space | That part of a multicellular organism outside the cells proper, usually taken to be outside the plasma membranes, and occupied by fluid. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
1 GO annotations of molecular function
| Name | Definition |
|---|---|
| serine-type endopeptidase inhibitor activity | Binds to and stops, prevents or reduces the activity of serine-type endopeptidases, enzymes that catalyze the hydrolysis of nonterminal peptide bonds in a polypeptide chain; a serine residue (and a histidine residue) are at the active center of the enzyme. |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| cellular response to DNA damage stimulus | Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a stimulus indicating damage to its DNA from environmental insults or errors during metabolism. |
| DNA repair | The process of restoring DNA after damage. Genomes are subject to damage by chemical and physical agents in the environment (e.g. UV and ionizing radiations, chemical mutagens, fungal and bacterial toxins, etc.) and by free radicals or alkylating agents endogenously generated in metabolism. DNA is also damaged because of errors during its replication. A variety of different DNA repair pathways have been reported that include direct reversal, base excision repair, nucleotide excision repair, photoreactivation, bypass, double-strand break repair pathway, and mismatch repair pathway. |
39 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q1JPB0 | SERPINB1 | Leukocyte elastase inhibitor | Bos taurus (Bovine) | PR |
| Q9N2I2 | SERPINA5 | Plasma serine protease inhibitor | Bos taurus (Bovine) | PR |
| Q9TTE1 | SERPINA3-1 | Serpin A3-1 | Bos taurus (Bovine) | PR |
| P41361 | SERPINC1 | Antithrombin-III | Bos taurus (Bovine) | PR |
| P13909 | SERPINE1 | Plasminogen activator inhibitor 1 | Bos taurus (Bovine) | PR |
| A2I7N1 | SERPINA3-5 | Serpin A3-5 | Bos taurus (Bovine) | PR |
| A6QPQ2 | SERPINA3-8 | Serpin A3-8 | Bos taurus (Bovine) | PR |
| A2I7M9 | SERPINA3-2 | Serpin A3-2 | Bos taurus (Bovine) | PR |
| A2I7N2 | SERPINA3-6 | Serpin A3-6 | Bos taurus (Bovine) | PR |
| O73790 | SERPINB10 | Heterochromatin-associated protein MENT | Gallus gallus (Chicken) | PR |
| P05619 | SERPINB1 | Leukocyte elastase inhibitor | Equus caballus (Horse) | PR |
| P01008 | SERPINC1 | Antithrombin-III | Homo sapiens (Human) | PR |
| P08697 | SERPINF2 | Alpha-2-antiplasmin | Homo sapiens (Human) | PR |
| Q96P15 | SERPINB11 | Serpin B11 | Homo sapiens (Human) | PR |
| Q9UK55 | SERPINA10 | Protein Z-dependent protease inhibitor | Homo sapiens (Human) | PR |
| P05121 | SERPINE1 | Plasminogen activator inhibitor 1 | Homo sapiens (Human) | PR |
| P05155 | SERPING1 | Plasma protease C1 inhibitor | Homo sapiens (Human) | PR |
| P01011 | SERPINA3 | Alpha-1-antichymotrypsin | Homo sapiens (Human) | PR |
| Q86WD7 | SERPINA9 | Serpin A9 | Homo sapiens (Human) | PR |
| P07093 | SERPINE2 | Glia-derived nexin | Homo sapiens (Human) | PR |
| P12388 | Serpinb2 | Plasminogen activator inhibitor 2, macrophage | Mus musculus (Mouse) | PR |
| P32261 | Serpinc1 | Antithrombin-III | Mus musculus (Mouse) | PR |
| Q07235 | Serpine2 | Glia-derived nexin | Mus musculus (Mouse) | PR |
| Q5SV42 | Serpinb1c | Leukocyte elastase inhibitor C | Mus musculus (Mouse) | PR |
| Q80X76 | Serpina3f | Serine protease inhibitor A3F | Mus musculus (Mouse) | PR |
| Q8BYY9 | Serpina3b | Serine protease inhibitor A3B | Mus musculus (Mouse) | PR |
| Q9D154 | Serpinb1a | Leukocyte elastase inhibitor A | Mus musculus (Mouse) | PR |
| Q9JK88 | Serpini2 | Serpin I2 | Mus musculus (Mouse) | PR |
| Q8CDC0 | Serpinb13 | Serpin B13 | Mus musculus (Mouse) | PR |
| P22777 | Serpine1 | Plasminogen activator inhibitor 1 | Mus musculus (Mouse) | PR |
| Q5I2A0 | Serpina3g | Serine protease inhibitor A3G | Mus musculus (Mouse) | PR |
| Q62975 | Serpina10 | Protein Z-dependent protease inhibitor | Rattus norvegicus (Rat) | PR |
| P29524 | Serpinb2 | Plasminogen activator inhibitor 2 type A | Rattus norvegicus (Rat) | PR |
| Q6P734 | Serping1 | Plasma protease C1 inhibitor | Rattus norvegicus (Rat) | PR |
| P05545 | Serpina3k | Serine protease inhibitor A3K | Rattus norvegicus (Rat) | PR |
| P07092 | Serpine2 | Glia-derived nexin | Rattus norvegicus (Rat) | PR |
| P05544 | Serpina3l | Serine protease inhibitor A3L | Rattus norvegicus (Rat) | PR |
| O48706 | At2g26390 | Serpin-Z3 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9M1T7 | At3g45220 | Serpin-Z4 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MDSKRKNQEL | STSETADPSL | SKTNKKQKID | MQEAMKNQNE | VSLLLVGKVI | SAVAKNSNCV |
| 70 | 80 | 90 | 100 | 110 | 120 |
| FSPASINAVL | TVTAANTDNK | TLRSFILSFL | KSSSTEETNA | IFHELASVVF | KDGSETGGPK |
| 130 | 140 | 150 | 160 | 170 | 180 |
| IAAVNGVWME | QSLSCNPDWE | DLFLNFFKAS | FAKVDFRHKA | EEVRLDVNTW | ASRHTNDLIK |
| 190 | 200 | 210 | 220 | 230 | 240 |
| EILPRGSVTS | LTNWIYGNAL | YFKGAWEKAF | DKSMTRDKPF | HLLNGKSVSV | PFMRSYEKQF |
| 250 | 260 | 270 | 280 | 290 | 300 |
| IEAYDGFKVL | RLPYRQGRDD | TNREFSMYLY | LPDKKGELDN | LLERITSNPG | FLDSHIPEYR |
| 310 | 320 | 330 | 340 | 350 | 360 |
| VDVGDFRIPK | FKIEFGFEAS | SVFNDFELNV | SLHQKALIEI | DEEGTEAAAA | TTVVVVTGSC |
| 370 | 380 | 390 | 400 | ||
| LWEPKKKIDF | VADHPFLFLI | REDKTGTLLF | AGQIFDPSEL | SSALDRA |