Q9SXD9
Gene name |
At1g62580 (T3P18.14) |
Protein name |
Flavin-containing monooxygenase FMO GS-OX-like 7 |
Names |
Flavin-monooxygenase glucosinolate S-oxygenase-like 7 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT1G62580 |
EC number |
|
Protein Class |
|
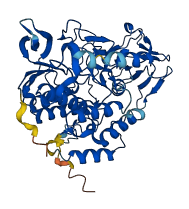
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9SXD9
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9SXD9-F1 | Predicted | AlphaFoldDB |
229 variants for Q9SXD9
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| tmp_1_23173336_G_A | 2 | V>I | No | 1000Genomes | |
| ENSVATH05037979 | 4 | A>S | No | 1000Genomes | |
| ENSVATH05037979 | 4 | A>T | No | 1000Genomes | |
| tmp_1_23173343_C_T | 4 | A>V | No | 1000Genomes | |
| tmp_1_23173352_C_T | 7 | P>L | No | 1000Genomes | |
| ENSVATH13699005 | 8 | P>L | No | 1000Genomes | |
| ENSVATH01440698 | 12 | N>H | No | 1000Genomes | |
| tmp_1_23173372_G_A | 14 | V>M | No | 1000Genomes | |
| ENSVATH01440699 | 15 | A>V | No | 1000Genomes | |
| ENSVATH13699013 | 18 | G>D | No | 1000Genomes | |
| ENSVATH13699012 | 18 | G>S | No | 1000Genomes | |
| ENSVATH05037980 | 19 | A>V | No | 1000Genomes | |
| ENSVATH14390689 | 20 | G>E | No | 1000Genomes | |
| ENSVATH01440701 | 20 | G>R | No | 1000Genomes | |
| tmp_1_23173394_C_T | 21 | A>V | No | 1000Genomes | |
| ENSVATH14390690 | 22 | A>T | No | 1000Genomes | |
| ENSVATH14390691 | 23 | G>E | No | 1000Genomes | |
| ENSVATH05037982 | 23 | G>R | No | 1000Genomes | |
| ENSVATH05037983 | 24 | L>F | No | 1000Genomes | |
| ENSVATH05037983 | 24 | L>V | No | 1000Genomes | |
| ENSVATH05037984 | 25 | V>L | No | 1000Genomes | |
| ENSVATH13699016 | 26 | A>V | No | 1000Genomes | |
| tmp_1_23173414_C_T | 28 | R>* | No | 1000Genomes | |
| ENSVATH05037986 | 30 | L>F | No | 1000Genomes | |
| ENSVATH05037986 | 30 | L>V | No | 1000Genomes | |
| ENSVATH13699019 | 31 | R>C | No | 1000Genomes | |
| tmp_1_23173424_G_A | 31 | R>H | No | 1000Genomes | |
| ENSVATH01440703 | 32 | R>L | No | 1000Genomes | |
| ENSVATH13699022 | 35 | H>Y | No | 1000Genomes | |
| ENSVATH01440704 | 37 | V>I | No | 1000Genomes | |
| tmp_1_23173447_G_A | 39 | V>I | No | 1000Genomes | |
| ENSVATH07670195 | 40 | F>L | No | 1000Genomes | |
| ENSVATH13699024 | 41 | E>K | No | 1000Genomes | |
| ENSVATH07670199 | 42 | R>C | No | 1000Genomes | |
| ENSVATH01440705 | 42 | R>H | No | 1000Genomes | |
| ENSVATH01440705 | 42 | R>P | No | 1000Genomes | |
| ENSVATH05037987 | 43 | G>E | No | 1000Genomes | |
| tmp_1_23173463_A_G | 44 | N>S | No | 1000Genomes | |
| ENSVATH01440707 | 45 | H>Q | No | 1000Genomes | |
| ENSVATH01440708 | 49 | V>M | No | 1000Genomes | |
| tmp_1_23173482_G_A | 50 | W>* | No | 1000Genomes | |
| tmp_1_23173483_G_A | 51 | A>T | No | 1000Genomes | |
| ENSVATH13699025 | 51 | A>V | No | 1000Genomes | |
| tmp_1_23173490_C_T | 53 | T>M | No | 1000Genomes | |
| ENSVATH00114243 | 54 | P>S | No | 1000Genomes | |
| tmp_1_23173498_G_A | 56 | V>I | No | 1000Genomes | |
| ENSVATH13699026 | 57 | E>K | No | 1000Genomes | |
| ENSVATH01440709 | 58 | P>L | No | 1000Genomes | |
| ENSVATH05037990 | 59 | D>N | No | 1000Genomes | |
| ENSVATH05037991 | 61 | L>F | No | 1000Genomes | |
| ENSVATH05037993 | 63 | I>T | No | 1000Genomes | |
| ENSVATH13699027 | 64 | D>N | No | 1000Genomes | |
| tmp_1_23173523_A_T | 64 | D>V | No | 1000Genomes | |
| tmp_1_23173525_C_T | 65 | P>S | No | 1000Genomes | |
| tmp_1_23173531_C_T | 67 | R>* | No | 1000Genomes | |
| ENSVATH05037994 | 68 | P>S | No | 1000Genomes | |
| ENSVATH13699030 | 69 | V>I | No | 1000Genomes | |
| ENSVATH14390694 | 71 | H>Y | No | 1000Genomes | |
| ENSVATH05037995 | 72 | S>L | No | 1000Genomes | |
| tmp_1_23173549_AG_TG,A | 73 | S>C | No | 1000Genomes | |
| ENSVATH04064652 | 73 | S>N | No | 1000Genomes | |
| tmp_1_23173562_C_T,A | 77 | S>F | No | 1000Genomes | |
| tmp_1_23173562_C_T,A | 77 | S>Y | No | 1000Genomes | |
| ENSVATH05038000 | 79 | R>* | No | 1000Genomes | |
| ENSVATH01440711 | 79 | R>Q | No | 1000Genomes | |
| tmp_1_23173571_C_T | 80 | T>I | No | 1000Genomes | |
| tmp_1_23173574_T_C | 81 | I>T | No | 1000Genomes | |
| tmp_1_23173576_A_G | 82 | I>V | No | 1000Genomes | |
| tmp_1_23173580_C_T | 83 | P>L | No | 1000Genomes | |
| ENSVATH13699031 | 83 | P>T | No | 1000Genomes | |
| tmp_1_23173582_C_T | 84 | Q>* | No | 1000Genomes | |
| ENSVATH01440712 | 84 | Q>R | No | 1000Genomes | |
| ENSVATH01440713 | 85 | E>* | No | 1000Genomes | |
| ENSVATH01440713 | 85 | E>K | No | 1000Genomes | |
| tmp_1_23173593_G_C | 87 | M>I | No | 1000Genomes | |
| ENSVATH05038004 | 88 | G>S | No | 1000Genomes | |
| ENSVATH05038006 | 91 | D>N | No | 1000Genomes | |
| ENSVATH01440714 | 92 | F>L | No | 1000Genomes | |
| tmp_1_23173610_C_T | 93 | P>L | No | 1000Genomes | |
| ENSVATH13699034 | 93 | P>S | No | 1000Genomes | |
| ENSVATH01440715 | 95 | S>L | No | 1000Genomes | |
| ENSVATH14390729 | 96 | T>N | No | 1000Genomes | |
| ENSVATH05038008 | 97 | R>G | No | 1000Genomes | |
| ENSVATH13699036 | 97 | R>I | No | 1000Genomes | |
| tmp_1_23173624_C_T | 98 | L>F | No | 1000Genomes | |
| ENSVATH05038009 | 99 | E>K | No | 1000Genomes | |
| ENSVATH01440716 | 101 | G>R | No | 1000Genomes | |
| tmp_1_23173640_G_C | 103 | R>T | No | 1000Genomes | |
| ENSVATH14390731 | 107 | R>K | No | 1000Genomes | |
| ENSVATH01440717 | 109 | P>S | No | 1000Genomes | |
| ENSVATH01440717 | 109 | P>T | No | 1000Genomes | |
| ENSVATH01440718 | 110 | G>C | No | 1000Genomes | |
| tmp_1_23173661_G_A | 110 | G>D | No | 1000Genomes | |
| ENSVATH01440718 | 110 | G>S | No | 1000Genomes | |
| ENSVATH05038011 | 112 | S>I | No | 1000Genomes | |
| ENSVATH05038011 | 112 | S>N | No | 1000Genomes | |
| tmp_1_23173668_T_A | 112 | S>R | No | 1000Genomes | |
| ENSVATH13699038 | 113 | E>D | No | 1000Genomes | |
| tmp_1_23173669_G_A | 113 | E>K | No | 1000Genomes | |
| tmp_1_23173672_G_A | 114 | V>I | No | 1000Genomes | |
| ENSVATH13699039 | 115 | L>F | No | 1000Genomes | |
| ENSVATH01440719 | 116 | A>S | No | 1000Genomes | |
| ENSVATH01440719 | 116 | A>T | No | 1000Genomes | |
| ENSVATH05038012 | 119 | R>K | No | 1000Genomes | |
| tmp_1_23173690_G_A | 120 | D>N | No | 1000Genomes | |
| tmp_1_23173693_T_C | 121 | F>L | No | 1000Genomes | |
| ENSVATH00114244 | 122 | V>A | No | 1000Genomes | |
| tmp_1_23173700_G_T | 123 | R>M | No | 1000Genomes | |
| ENSVATH05038014 | 123 | R>S | No | 1000Genomes | |
| tmp_1_23173702_G_A | 124 | E>K | No | 1000Genomes | |
| ENSVATH01440720 | 128 | E>D | No | 1000Genomes | |
| ENSVATH05038015 | 130 | M>I | No | 1000Genomes | |
| ENSVATH14390732 | 130 | M>K | No | 1000Genomes | |
| tmp_1_23173726_C_T | 132 | R>C | No | 1000Genomes | |
| ENSVATH05038016 | 132 | R>H | No | 1000Genomes | |
| ENSVATH05038016 | 132 | R>P | No | 1000Genomes | |
| tmp_1_23173732_G_A | 134 | E>K | No | 1000Genomes | |
| ENSVATH13699040 | 135 | T>M | No | 1000Genomes | |
| ENSVATH01440721 | 137 | V>I | No | 1000Genomes | |
| ENSVATH05038019 | 138 | V>M | No | 1000Genomes | |
| ENSVATH13699042 | 139 | R>K | No | 1000Genomes | |
| ENSVATH05038020 | 140 | V>I | No | 1000Genomes | |
| ENSVATH14390733 | 141 | E>K | No | 1000Genomes | |
| ENSVATH05038021 | 142 | Q>H | No | 1000Genomes | |
| tmp_1_23173763_G_A,C | 144 | G>A | No | 1000Genomes | |
| tmp_1_23173763_G_A,C | 144 | G>E | No | 1000Genomes | |
| ENSVATH01440723 | 144 | G>R | No | 1000Genomes | |
| ENSVATH01440723 | 144 | G>W | No | 1000Genomes | |
| ENSVATH01440724 | 145 | E>K | No | 1000Genomes | |
| tmp_1_23173772_C_T | 147 | P>L | No | 1000Genomes | |
| tmp_1_23173771_C_T | 147 | P>S | No | 1000Genomes | |
| ENSVATH13699043 | 148 | K>R | No | 1000Genomes | |
| ENSVATH13699044 | 149 | K>N | No | 1000Genomes | |
| ENSVATH05038023 | 150 | W>* | No | 1000Genomes | |
| tmp_1_23173784_G_A | 151 | R>K | No | 1000Genomes | |
| ENSVATH13699045 | 152 | V>F | No | 1000Genomes | |
| ENSVATH13699045 | 152 | V>I | No | 1000Genomes | |
| tmp_1_23173789_A_G | 153 | K>E | No | 1000Genomes | |
| ENSVATH01440726 | 153 | K>N | No | 1000Genomes | |
| ENSVATH01440727 | 154 | S>F | No | 1000Genomes | |
| ENSVATH01440727 | 154 | S>Y | No | 1000Genomes | |
| tmp_1_23173796_G_A | 155 | R>K | No | 1000Genomes | |
| ENSVATH05038024 | 155 | R>S | No | 1000Genomes | |
| tmp_1_23173801_T_G | 157 | F>V | No | 1000Genomes | |
| tmp_1_23173805_G_A | 158 | G>D | No | 1000Genomes | |
| ENSVATH05038027 | 158 | G>S | No | 1000Genomes | |
| ENSVATH13699046 | 162 | D>N | No | 1000Genomes | |
| ENSVATH14390734 | 163 | E>* | No | 1000Genomes | |
| ENSVATH00114245 | 165 | Y>C | No | 1000Genomes | |
| ENSVATH05038028 | 166 | D>N | No | 1000Genomes | |
| ENSVATH13699047 | 167 | A>T | No | 1000Genomes | |
| tmp_1_23173832_C_T | 167 | A>V | No | 1000Genomes | |
| tmp_1_23173835_T_C | 168 | V>A | No | 1000Genomes | |
| ENSVATH13699048 | 169 | V>F | No | 1000Genomes | |
| ENSVATH13699048 | 169 | V>I | No | 1000Genomes | |
| ENSVATH13699048 | 169 | V>L | No | 1000Genomes | |
| ENSVATH13699049 | 170 | V>A | No | 1000Genomes | |
| ENSVATH05038029 | 170 | V>I | No | 1000Genomes | |
| ENSVATH13699050 | 171 | C>Y | No | 1000Genomes | |
| ENSVATH05038031 | 173 | G>D | No | 1000Genomes | |
| ENSVATH05038030 | 173 | G>S | No | 1000Genomes | |
| ENSVATH13699052 | 175 | Y>N | No | 1000Genomes | |
| ENSVATH05038032 | 176 | T>I | No | 1000Genomes | |
| ENSVATH05038032 | 176 | T>R | No | 1000Genomes | |
| ENSVATH05038033 | 177 | E>D | No | 1000Genomes | |
| ENSVATH05038034 | 179 | R>C | No | 1000Genomes | |
| ENSVATH05038035 | 179 | R>H | No | 1000Genomes | |
| ENSVATH05038037 | 181 | A>V | No | 1000Genomes | |
| ENSVATH13699053 | 183 | I>L | No | 1000Genomes | |
| tmp_1_23173883_C_T | 184 | P>L | No | 1000Genomes | |
| tmp_1_23173882_C_T | 184 | P>S | No | 1000Genomes | |
| ENSVATH05038059 | 185 | G>D | No | 1000Genomes | |
| tmp_1_23175692_A_T | 188 | T>S | No | 1000Genomes | |
| tmp_1_23175719_C_T | 197 | H>Y | No | 1000Genomes | |
| tmp_1_23175731_G_A | 201 | V>I | No | 1000Genomes | |
| tmp_1_23175739_A_T | 203 | E>D | No | 1000Genomes | |
| tmp_1_23175743_G_T | 205 | V>F | No | 1000Genomes | |
| ENSVATH05038060 | 206 | K>Q | No | 1000Genomes | |
| tmp_1_23175752_C_G | 208 | Q>E | No | 1000Genomes | |
| tmp_1_23175753_A_C | 208 | Q>P | No | 1000Genomes | |
| ENSVATH05038063 | 220 | V>A | No | 1000Genomes | |
| ENSVATH13699287 | 224 | R>I | No | 1000Genomes | |
| tmp_1_23175877_C_A | 225 | D>E | No | 1000Genomes | |
| ENSVATH01440774 | 241 | K>T | No | 1000Genomes | |
| tmp_1_23175937_C_G | 245 | Y>* | No | 1000Genomes | |
| tmp_1_23175938_G_A | 246 | E>K | No | 1000Genomes | |
| ENSVATH13699288 | 249 | P>S | No | 1000Genomes | |
| ENSVATH05038066 | 252 | D>E | No | 1000Genomes | |
| tmp_1_23175971_C_T | 257 | H>Y | No | 1000Genomes | |
| ENSVATH01440775 | 258 | S>T | No | 1000Genomes | |
| tmp_1_23175978_A_G | 259 | N>S | No | 1000Genomes | |
| ENSVATH13699293 | 261 | E>* | No | 1000Genomes | |
| ENSVATH13699294 | 261 | E>G | No | 1000Genomes | |
| tmp_1_23176074_C_G | 264 | R>G | No | 1000Genomes | |
| ENSVATH05038069 | 267 | G>D | No | 1000Genomes | |
| ENSVATH13699298 | 272 | K>R | No | 1000Genomes | |
| ENSVATH05038070 | 276 | T>M | No | 1000Genomes | |
| tmp_1_23176110_A_C | 276 | T>P | No | 1000Genomes | |
| ENSVATH05038071 | 279 | A>T | No | 1000Genomes | |
| tmp_1_23176120_C_T | 279 | A>V | No | 1000Genomes | |
| ENSVATH13699303 | 287 | G>E | No | 1000Genomes | |
| ENSVATH05038075 | 289 | K>I | No | 1000Genomes | |
| ENSVATH13699305 | 299 | G>C | No | 1000Genomes | |
| ENSVATH14390848 | 303 | V>F | No | 1000Genomes | |
| tmp_1_23176273_A_G | 306 | N>S | No | 1000Genomes | |
| tmp_1_23176275_C_T | 307 | R>C | No | 1000Genomes | |
| tmp_1_23176305_C_T | 317 | P>S | No | 1000Genomes | |
| ENSVATH13699307 | 320 | L>F | No | 1000Genomes | |
| ENSVATH05038081 | 328 | G>E | No | 1000Genomes | |
| ENSVATH05038084 | 340 | E>D | No | 1000Genomes | |
| ENSVATH13699310 | 344 | K>E | No | 1000Genomes | |
| ENSVATH01440790 | 351 | A>T | No | 1000Genomes | |
| tmp_1_23176498_C_T | 351 | A>V | No | 1000Genomes | |
| tmp_1_23176519_C_T | 358 | S>L | No | 1000Genomes | |
| ENSVATH00114247 | 359 | Q>L | No | 1000Genomes | |
| tmp_1_23176544_G_C | 366 | K>N | No | 1000Genomes | |
| ENSVATH01440793 | 370 | L>S | No | 1000Genomes | |
| ENSVATH01440794 | 371 | K>M | No | 1000Genomes | |
| ENSVATH13699314 | 379 | K>E | No | 1000Genomes | |
| ENSVATH05038085 | 382 | T>S | No | 1000Genomes | |
| ENSVATH01440796 | 383 | H>Q | No | 1000Genomes | |
| ENSVATH13699315 | 385 | M>I | No | 1000Genomes | |
| tmp_1_23176612_A_T | 389 | D>V | No | 1000Genomes | |
| ENSVATH01440799 | 395 | N>D | No | 1000Genomes | |
| ENSVATH05038088 | 398 | L>V | No | 1000Genomes | |
| ENSVATH09351418 | 406 | R>Q | No | 1000Genomes | |
| ENSVATH01440802 | 426 | A>S | No | 1000Genomes | |
| ENSVATH09351419 | 427 | S>N | No | 1000Genomes | |
| ENSVATH09351420 | 435 | D>N | No | 1000Genomes |
No associated diseases with Q9SXD9
No regional properties for Q9SXD9
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for Q9SXD9 | |||
No GO annotations of cellular component
| Name | Definition |
|---|---|
| No GO annotations for cellular component |
6 GO annotations of molecular function
| Name | Definition |
|---|---|
| flavin adenine dinucleotide binding | Binding to FAD, flavin-adenine dinucleotide, the coenzyme or the prosthetic group of various flavoprotein oxidoreductase enzymes, in either the oxidized form, FAD, or the reduced form, FADH2. |
| guanylate cyclase activity | Catalysis of the reaction: GTP = 3',5'-cyclic GMP + diphosphate. |
| N,N-dimethylaniline monooxygenase activity | Catalysis of the reaction: N,N-dimethylaniline + NADPH + H+ + O2 = N,N-dimethylaniline N-oxide + NADP+ + H2O. |
| NADP binding | Binding to nicotinamide-adenine dinucleotide phosphate, a coenzyme involved in many redox and biosynthetic reactions; binding may be to either the oxidized form, NADP+, or the reduced form, NADPH. |
| nitric oxide binding | Binding to nitric oxide (NO). |
| oxygen binding | Binding to oxygen (O2). |
1 GO annotations of biological process
| Name | Definition |
|---|---|
| stomatal closure | The process of closing of stomata, pores in the epidermis of leaves and stems bordered by two guard cells and serving in gas exchange. |
12 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P31512 | FMO4 | Dimethylaniline monooxygenase [N-oxide-forming] 4 | Homo sapiens (Human) | PR |
| P49326 | FMO5 | Flavin-containing monooxygenase 5 | Homo sapiens (Human) | PR |
| P97501 | Fmo3 | Dimethylaniline monooxygenase [N-oxide-forming] 3 | Mus musculus (Mouse) | PR |
| P97872 | Fmo5 | Flavin-containing monooxygenase 5 | Mus musculus (Mouse) | PR |
| Q8K2I3 | Fmo2 | Dimethylaniline monooxygenase [N-oxide-forming] 2 | Mus musculus (Mouse) | PR |
| Q8VHG0 | Fmo4 | Dimethylaniline monooxygenase [N-oxide-forming] 4 | Mus musculus (Mouse) | PR |
| Q8K4B7 | Fmo4 | Dimethylaniline monooxygenase [N-oxide-forming] 4 | Rattus norvegicus (Rat) | PR |
| Q9EQ76 | Fmo3 | Dimethylaniline monooxygenase [N-oxide-forming] 3 | Rattus norvegicus (Rat) | PR |
| Q6IRI9 | Fmo2 | Dimethylaniline monooxygenase [N-oxide-forming] 2 | Rattus norvegicus (Rat) | PR |
| Q8K4C0 | Fmo5 | Flavin-containing monooxygenase 5 | Rattus norvegicus (Rat) | PR |
| Q9SVU0 | YUC8 | Probable indole-3-pyruvate monooxygenase YUCCA8 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9C8T8 | At1g63340 | Putative flavin-containing monooxygenase FMO GS-OX-like 10 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MVPAVNPPTT | SNHVAVIGAG | AAGLVAAREL | RREGHSVVVF | ERGNHIGGVW | AYTPNVEPDP |
| 70 | 80 | 90 | 100 | 110 | 120 |
| LSIDPTRPVI | HSSLYSSLRT | IIPQECMGFT | DFPFSTRLEN | GSRDPRRHPG | HSEVLAYLRD |
| 130 | 140 | 150 | 160 | 170 | 180 |
| FVREFKIEEM | IRFETEVVRV | EQAGENPKKW | RVKSRNFGDI | SDEIYDAVVV | CNGHYTEPRH |
| 190 | 200 | 210 | 220 | 230 | 240 |
| ALIPGIDTWP | GKQIHSHNYR | VPEQVKDQVV | VVIGSSVSGV | DISRDIANVT | KEVHISSRST |
| 250 | 260 | 270 | 280 | 290 | 300 |
| KPETYEKLPG | YDNLWLHSNI | ETVREDGSVV | FKNGKTVYAD | TIMHCTGYKY | YFPFLDTKGE |
| 310 | 320 | 330 | 340 | 350 | 360 |
| VTVEDNRVGP | LYKHVFPPAL | SPGLSFIGLP | WQVIPFPMFE | LQSKWVAAVL | AGRVSLPSQE |
| 370 | 380 | 390 | 400 | 410 | 420 |
| EMEDTKMFYL | KLEASCIPKR | YTHLMAELDS | QFVYNNWLAD | QCDYPRIEKW | REQMFYKVFK |
| 430 | 440 | 450 | 460 | ||
| RIQSQASTYK | DDWDDDHLIA | EAYEDFVKFP | SNYPSSLIER | EYTS |