Q6STE5
Gene name |
SMARCD3 (BAF60C) |
Protein name |
SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 3 |
Names |
60 kDa BRG-1/Brm-associated factor subunit C, BRG1-associated factor 60C, BAF60C |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:6604 |
EC number |
|
Protein Class |
|
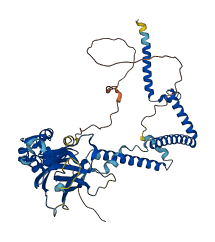
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q6STE5
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q6STE5-F1 | Predicted | AlphaFoldDB |
274 variants for Q6STE5
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs776716845 CA4575760 |
3 | A>E | No |
ClinGen ExAC gnomAD |
|
|
CA4575758 rs760286919 |
4 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1262822826 CA370068970 |
4 | D>G | No |
ClinGen TOPMed |
|
|
CA169150722 rs866457221 |
7 | A>V | No |
ClinGen Ensembl |
|
|
rs1387907376 CA370068915 |
8 | G>* | No |
ClinGen TOPMed |
|
|
rs1387907376 CA370068920 |
8 | G>R | No |
ClinGen TOPMed |
|
|
CA370068912 rs1239760372 |
8 | G>V | No |
ClinGen gnomAD |
|
|
CA370068870 rs1311518370 |
11 | R>L | No |
ClinGen gnomAD |
|
|
CA4575757 rs771801679 |
13 | A>P | No |
ClinGen ExAC gnomAD |
|
|
CA4575756 rs771801679 |
13 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs1371317225 CA370068789 |
16 | S>I | No |
ClinGen gnomAD |
|
|
rs1455244035 CA370068780 |
17 | K>Q | No |
ClinGen TOPMed |
|
|
CA370068726 rs1319411127 |
20 | E>A | No |
ClinGen gnomAD |
|
|
CA4575754 rs779388635 |
20 | E>Q | No |
ClinGen ExAC |
|
|
CA370068660 rs1377008495 |
24 | H>Y | No |
ClinGen TOPMed |
|
|
rs1584876874 CA370068631 |
26 | V>G | No |
ClinGen Ensembl |
|
|
CA169150700 rs1044895900 |
26 | V>M | No |
ClinGen Ensembl |
|
|
rs1405522801 CA370068311 |
27 | R>S | No |
ClinGen TOPMed |
|
|
CA370068299 rs1186777928 |
29 | G>R | No |
ClinGen gnomAD |
|
|
CA370068262 rs1486617462 |
34 | A>G | No |
ClinGen gnomAD |
|
|
rs1450529066 CA370068265 |
34 | A>T | No |
ClinGen TOPMed |
|
| TCGA novel | 37 | P>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA169148607 rs573737118 |
47 | G>S | No |
ClinGen 1000Genomes |
|
|
rs1009526741 CA169148601 |
49 | P>Q | No |
ClinGen TOPMed |
|
|
rs1227199574 CA370068166 |
49 | P>S | No |
ClinGen TOPMed |
|
|
CA169148581 rs890467169 |
51 | M>I | No |
ClinGen TOPMed gnomAD |
|
|
rs959934298 CA370068154 |
51 | M>L | No |
ClinGen TOPMed |
|
|
CA370068153 rs1460493465 |
51 | M>T | No |
ClinGen TOPMed |
|
|
rs959934298 CA169148592 |
51 | M>V | No |
ClinGen TOPMed |
|
|
rs1263804951 CA370068148 |
52 | G>S | No |
ClinGen TOPMed |
|
|
rs927219105 CA169148569 |
54 | P>L | No |
ClinGen TOPMed |
|
|
rs1400724007 CA370068116 |
57 | R>* | No |
ClinGen gnomAD |
|
|
rs899283546 CA169148541 |
62 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA370068078 rs1481291088 |
64 | G>S | No |
ClinGen TOPMed |
|
|
CA370068068 rs1177493099 |
65 | M>T | No |
ClinGen TOPMed |
|
|
CA370068047 rs1296686550 |
68 | A>S | No |
ClinGen gnomAD |
|
|
rs1305165673 CA370068040 |
69 | R>H | No |
ClinGen gnomAD |
|
|
CA370068007 rs1468306442 |
74 | P>L | No |
ClinGen TOPMed |
|
|
rs1386342674 CA370068006 |
75 | P>T | No |
ClinGen TOPMed |
|
|
rs1365719185 CA370067999 |
76 | P>A | No |
ClinGen TOPMed gnomAD |
|
|
CA169148540 rs1022296899 |
76 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1347857519 CA370067995 |
77 | G>R | No |
ClinGen TOPMed |
|
|
rs1283530013 CA370067984 |
78 | Q>L | No |
ClinGen TOPMed |
|
| TCGA novel | 81 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA169148534 rs941243723 |
82 | Q>* | No |
ClinGen Ensembl |
|
|
CA370067921 rs1367466591 |
87 | P>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1350721604 CA370067917 |
87 | P>L | No |
ClinGen TOPMed |
|
|
rs1350721604 CA370067918 |
87 | P>R | No |
ClinGen TOPMed |
|
|
rs1490784060 CA370067916 |
88 | V>M | No |
ClinGen TOPMed |
|
|
CA4575722 rs778165767 |
99 | K>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4575721 rs754782541 |
100 | R>K | No |
ClinGen ExAC gnomAD |
|
|
rs1335432340 CA370067820 |
101 | R>K | No |
ClinGen TOPMed |
|
|
CA4575718 rs756138565 |
102 | K>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs887959385 CA370067795 |
104 | A>P | No |
ClinGen gnomAD |
|
|
rs887959385 CA169147155 |
104 | A>T | No |
ClinGen gnomAD |
|
|
CA169147148 rs981649717 |
107 | I>M | No |
ClinGen TOPMed gnomAD |
|
|
CA4575716 rs766988633 |
108 | L>F | No |
ClinGen ExAC gnomAD |
|
|
CA4575714 rs557064155 |
109 | P>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
| TCGA novel | 111 | R>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4575685 rs771378283 |
113 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1584868006 CA370066225 |
113 | R>W | No |
ClinGen Ensembl |
|
|
rs907315567 CA169146300 |
117 | P>T | No |
ClinGen TOPMed |
|
|
rs748318445 CA4575681 |
118 | E>K | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 120 | Q>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1052482244 CA169146283 |
123 | M>T | No |
ClinGen gnomAD |
|
|
CA4575678 rs745683759 |
131 | K>R | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 133 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs757191231 CA4575676 |
136 | I>L | No |
ClinGen ExAC gnomAD |
|
|
rs757191231 CA169146256 |
136 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs751056496 CA4575675 |
137 | M>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs751056496 CA169146250 |
137 | M>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA370065898 rs751056496 |
137 | M>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs757917046 CA4575673 |
138 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs777197030 CA4575674 |
138 | R>W | No |
ClinGen ExAC gnomAD |
|
|
CA4575671 rs764826999 |
140 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs1050100 CA370065864 |
140 | R>W | No |
ClinGen gnomAD |
|
|
rs1387892847 CA370065848 |
141 | V>A | No |
ClinGen gnomAD |
|
|
rs1251012916 CA370065854 |
141 | V>L | No |
ClinGen TOPMed |
|
|
CA370065813 rs1441349651 |
144 | Q>E | No |
ClinGen TOPMed |
|
| TCGA novel | 144 | Q>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 145 | E>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA370065789 rs1187784745 |
145 | E>V | No |
ClinGen gnomAD |
|
|
rs1236348559 CA370065730 |
150 | P>T | No |
ClinGen gnomAD |
|
|
rs766892523 CA4575668 |
151 | M>T | No |
ClinGen ExAC TOPMed |
|
|
CA4575669 COSM1449329 rs368891567 COSM1449330 |
151 | M>V | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA4575635 rs367712260 |
155 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA4575636 COSM1596907 rs778350608 COSM1087439 |
155 | R>W | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA4575632 rs756509887 |
158 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs373612855 CA4575627 |
160 | Y>* | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs182299814 CA4575628 |
160 | Y>C | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA4575629 rs182299814 |
160 | Y>F | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA4575630 rs768116859 |
160 | Y>H | No |
ClinGen ExAC gnomAD |
|
|
rs368824815 CA169145832 |
166 | N>S | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA4575624 rs760438835 |
168 | A>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs760438835 CA4575623 |
168 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4575621 rs771988742 |
169 | K>M | No |
ClinGen ExAC gnomAD |
|
|
VAR_020884 CA169145752 rs1050101 |
170 | P>S | No |
ClinGen UniProt TOPMed dbSNP gnomAD |
|
|
CA169145753 rs1050101 |
170 | P>T | No |
ClinGen TOPMed gnomAD |
|
|
CA4575620 rs747964769 |
173 | E>Q | No |
ClinGen ExAC TOPMed |
|
|
rs1308881559 CA370065135 |
175 | S>A | No |
ClinGen gnomAD |
|
|
rs139354855 CA169145733 |
176 | D>N | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs150260765 CA4575618 |
177 | G>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1220849449 CA370065092 |
177 | G>D | No |
ClinGen TOPMed |
|
|
CA4575617 rs150260765 |
177 | G>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs576224313 CA4575616 |
178 | S>N | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1319289461 CA370065057 |
179 | I>T | No |
ClinGen gnomAD |
|
|
CA370065067 rs1563651283 |
179 | I>V | No |
ClinGen Ensembl |
|
|
CA4575615 rs755881486 |
180 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA4575613 rs370900978 |
184 | L>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1433016347 COSM291629 CA370064959 |
185 | R>W | large_intestine [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs1393624271 CA370064930 |
186 | V>A | No |
ClinGen gnomAD |
|
|
CA370064926 rs1393624271 |
186 | V>G | No |
ClinGen gnomAD |
|
| TCGA novel | 187 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4575611 rs751960257 |
191 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA370064813 rs751960257 |
191 | L>Q | No |
ClinGen ExAC gnomAD |
|
|
rs758998732 CA4575591 |
194 | P>T | No |
ClinGen ExAC gnomAD |
|
|
rs752712415 CA4575590 |
195 | S>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4575588 rs755060310 |
199 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4575589 rs778893769 |
199 | R>W | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 200 | K>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs766623741 CA4575586 |
202 | S>F | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
COSM1087436 rs751479414 CA169145337 COSM1596910 |
206 | K>N | endometrium [Cosmic] | No |
ClinGen cosmic curated Ensembl |
| TCGA novel | 207 | S>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4575584 rs751422864 |
211 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA370064216 rs1393081873 |
213 | D>N | No |
ClinGen TOPMed |
|
|
rs1164103717 COSM3431393 COSM3431392 CA370064142 |
216 | L>I | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
CA370064005 rs1390556224 |
224 | V>I | No |
ClinGen TOPMed |
|
|
CA4575558 rs772748621 |
227 | H>Y | No |
ClinGen ExAC gnomAD |
|
|
rs757872167 CA169145137 |
228 | R>Q | No |
ClinGen gnomAD |
|
|
rs1241576455 CA370063840 |
228 | R>W | No |
ClinGen gnomAD |
|
|
rs748546644 CA4575556 |
230 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs1396854026 CA370063797 |
231 | T>M | No |
ClinGen gnomAD |
|
|
rs865898946 CA169145110 |
234 | E>K | No |
ClinGen Ensembl |
|
|
rs1461894366 CA370063716 |
235 | T>M | No |
ClinGen TOPMed gnomAD |
|
|
CA370063688 rs1455195875 COSM206138 |
237 | G>S | large_intestine [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA370063567 rs1254353539 |
242 | R>L | No |
ClinGen TOPMed gnomAD |
|
|
CA370063570 rs1254353539 |
242 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1452176561 CA370063573 |
242 | R>W | No |
ClinGen gnomAD |
|
|
rs879553158 CA169145078 |
246 | L>M | No |
ClinGen Ensembl |
|
|
CA4575550 rs746045536 |
247 | S>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1006868588 CA169145074 |
249 | R>C | No |
ClinGen TOPMed gnomAD |
|
|
CA4575549 rs374935911 |
249 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA169145059 rs952920471 |
250 | C>Y | No |
ClinGen Ensembl |
|
|
CA4575548 rs758236448 |
251 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1434399699 CA370063427 |
253 | L>F | No |
ClinGen gnomAD |
|
|
CA169145045 rs978791521 |
253 | L>H | No |
ClinGen TOPMed |
|
|
COSM1193660 rs1385480915 COSM1193659 CA370063380 |
257 | D>N | lung [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA370063342 rs1584866068 |
259 | Q>R | No |
ClinGen Ensembl |
|
|
CA370063271 rs1443318989 |
260 | P>T | No |
ClinGen TOPMed |
|
|
rs1280965846 CA370063251 |
261 | P>L | No |
ClinGen gnomAD |
|
|
CA370063235 rs1447053794 |
262 | Q>H | No |
ClinGen gnomAD |
|
|
rs1369123677 CA370063215 |
264 | K>T | No |
ClinGen gnomAD |
|
|
rs1369687572 CA370063169 |
268 | R>C | No |
ClinGen gnomAD |
|
|
rs770251720 CA4575514 |
268 | R>H | No |
ClinGen ExAC gnomAD |
|
|
CA370063162 rs1563648376 |
269 | L>V | No |
ClinGen Ensembl |
|
|
CA4575513 rs759646857 |
270 | A>G | No |
ClinGen ExAC gnomAD |
|
|
rs1167680279 CA370063140 |
271 | R>P | No |
ClinGen TOPMed gnomAD |
|
|
CA370063141 rs1167680279 |
271 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1158866842 CA370063119 |
274 | G>R | No |
ClinGen gnomAD |
|
|
rs1453945025 CA370063067 |
278 | Q>* | No |
ClinGen gnomAD |
|
|
rs143377555 CA4575509 |
278 | Q>H | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1195534343 CA370063042 |
280 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs139896646 COSM1166292 COSM1166293 CA4575508 |
280 | R>H | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ESP ExAC NCI-TCGA gnomAD |
| TCGA novel | 282 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs756066902 CA370063021 |
283 | I>M | No |
ClinGen ExAC gnomAD |
|
|
CA4575506 rs374674300 |
283 | I>T | No |
ClinGen ESP ExAC gnomAD |
|
|
CA370063018 rs1286067676 |
284 | V>F | No |
ClinGen gnomAD |
|
|
CA370063006 rs1480152859 |
286 | A>T | No |
ClinGen gnomAD |
|
| TCGA novel | 289 | Q>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4575501 rs776238430 |
301 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs144383962 CA370062879 |
303 | E>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA370062855 rs1434368795 |
306 | N>K | No |
ClinGen gnomAD |
|
|
rs1393450952 COSM3366864 COSM3366863 CA370062851 |
307 | G>E | kidney [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA169144633 rs568531520 |
308 | D>N | No |
ClinGen 1000Genomes |
|
|
rs577653157 CA370061920 |
316 | D>E | No |
ClinGen gnomAD |
|
|
rs758051223 CA4575478 |
316 | D>Y | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA4575477 rs752398124 |
317 | C>R | No |
ClinGen ExAC |
|
|
CA4575476 rs765462133 |
319 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
CA370061856 rs1392136097 |
320 | L>M | No |
ClinGen gnomAD |
|
|
rs1481414265 CA370061830 |
321 | K>T | No |
ClinGen gnomAD |
|
| TCGA novel | 323 | S>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA370061781 rs1458254257 |
323 | S>Y | No |
ClinGen gnomAD |
|
|
rs1225095366 CA370061721 |
326 | P>L | No |
ClinGen TOPMed |
|
| TCGA novel | 326 | P>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA370061713 rs1363001932 |
327 | Q>* | No |
ClinGen gnomAD |
|
|
COSM1329958 rs1231086453 COSM1329959 CA370061705 |
327 | Q>H | ovary Variant assessed as Somatic; impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
CA4575475 rs755388815 |
328 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs754353068 CA4575474 |
328 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA169143807 rs754353068 |
328 | R>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1274917186 CA370061660 |
331 | A>S | No |
ClinGen TOPMed |
|
|
rs1210925632 CA370061570 |
336 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs981548228 CA169143785 |
336 | P>S | No |
ClinGen Ensembl |
|
|
rs1350499117 CA370061563 |
337 | D>N | No |
ClinGen gnomAD |
|
|
CA370061511 rs1259324680 |
339 | I>T | No |
ClinGen gnomAD |
|
|
rs767777695 CA4575470 |
340 | V>I | No |
ClinGen ExAC gnomAD |
|
|
rs1481780355 CA370061478 |
341 | I>F | No |
ClinGen TOPMed |
|
|
COSM1736224 COSM1736225 CA4575438 rs778405721 |
347 | V>M | central_nervous_system [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs780502038 CA4575436 |
354 | K>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4575435 rs780502038 |
354 | K>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4575434 rs756565197 |
355 | T>M | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 356 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs781738901 CA4575432 COSM206137 |
356 | A>V | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
CA370061049 rs1195252145 |
357 | C>W | No |
ClinGen gnomAD |
|
|
CA370060984 rs1413370635 |
360 | I>T | No |
ClinGen TOPMed |
|
|
rs1584862435 CA370060918 |
362 | V>G | No |
ClinGen Ensembl |
|
|
rs139186577 CA370060929 |
362 | V>L | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs139186577 CA169143467 |
362 | V>M | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA4575428 rs763093196 |
363 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA4575427 rs752929802 |
364 | V>G | No |
ClinGen ExAC gnomAD |
|
|
rs1360499019 CA370060880 |
364 | V>M | No |
ClinGen gnomAD |
|
|
rs766113740 CA4575426 |
365 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA370060698 rs1417598266 |
369 | K>N | No |
ClinGen TOPMed gnomAD |
|
|
rs1054946041 CA169143425 |
370 | G>E | No |
ClinGen Ensembl |
|
|
CA370060688 rs1563643872 |
370 | G>R | No |
ClinGen Ensembl |
|
|
rs772092145 CA4575422 |
379 | T>M | Variant assessed as Somatic; 4.624e-05 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs768288742 CA4575419 |
382 | Q>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs768288742 CA4575420 |
382 | Q>E | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 385 | I>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4575417 rs779879920 |
386 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA370060302 rs1563643679 |
386 | S>T | No |
ClinGen Ensembl |
|
|
rs1272356089 CA370060293 |
387 | A>T | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 392 | I>= | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA370060071 rs1418138683 |
393 | H>R | No |
ClinGen gnomAD |
|
|
CA370060029 rs1382355300 |
395 | T>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs369969827 CA4575393 |
396 | I>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs778282934 CA4575391 |
407 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA169143052 rs924674510 |
410 | L>I | No |
ClinGen Ensembl |
|
|
CA370059781 rs1489382572 |
414 | R>K | No |
ClinGen gnomAD |
|
| TCGA novel | 415 | D>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 415 | D>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs758437181 CA4575390 |
418 | G>A | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 420 | V>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA370059740 rs1445029853 |
420 | V>L | No |
ClinGen Ensembl |
|
|
CA169143048 rs945176606 |
422 | D>E | No |
ClinGen gnomAD |
|
|
CA169143032 rs1028309748 |
425 | R>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA4575389 rs748272691 |
425 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs143802296 CA4575388 |
427 | Q>* | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1319043832 CA370059645 |
428 | S>N | No |
ClinGen gnomAD |
|
|
rs1287767312 CA370059638 |
428 | S>R | No |
ClinGen gnomAD |
|
|
rs773357722 CA4575387 |
429 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
CA169143019 rs912479106 |
429 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs1377188635 CA370059543 |
433 | V>M | No |
ClinGen gnomAD |
|
|
CA4575368 rs749481516 CA370059519 |
434 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs780174447 CA4575367 |
435 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA370059490 rs1466650077 |
437 | V>I | No |
ClinGen TOPMed gnomAD |
|
|
rs757049303 CA4575366 |
438 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4575364 rs140006247 |
439 | G>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA4575363 rs758478352 |
441 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA370059453 rs758478352 |
441 | P>T | No |
ClinGen ExAC gnomAD |
|
|
CA4575362 rs752687441 |
444 | E>G | No |
ClinGen ExAC gnomAD |
|
|
rs913580776 CA169142825 |
445 | R>C | No |
ClinGen TOPMed |
|
|
COSM1449322 COSM1449321 rs903282679 CA169142824 |
445 | R>H | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
CA370059418 rs147471635 |
446 | R>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs147471635 CA4575360 |
446 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
COSM1087430 rs1183209411 CA370059421 COSM1596916 |
446 | R>W | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
CA169142808 rs890943517 |
453 | P>R | No |
ClinGen Ensembl |
|
|
CA370059369 rs1223843619 |
453 | P>S | No |
ClinGen Ensembl |
|
|
rs1310298394 CA370059346 |
456 | Q>L | No |
ClinGen TOPMed |
|
|
CA370059341 rs1233110652 |
457 | E>K | No |
ClinGen gnomAD |
|
|
CA4575353 rs774864067 |
459 | V>I | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 461 | R>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1329321387 CA370059061 |
464 | Y>S | No |
ClinGen gnomAD |
|
|
rs1444513797 CA370059056 |
465 | C>G | No |
ClinGen gnomAD |
|
|
rs1432963883 CA370058945 |
467 | I>M | No |
ClinGen gnomAD |
|
|
rs753343590 CA4575339 |
470 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA370058813 rs1295025786 |
473 | E>A | No |
ClinGen gnomAD |
|
|
rs1156424477 CA370058780 |
475 | E>Q | No |
ClinGen gnomAD |
|
|
CA4575336 rs750086442 |
476 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
CA4575335 rs199976092 |
477 | S>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1269953162 CA370058701 |
479 | V>I | No |
ClinGen gnomAD |
|
|
CA370058685 rs1210762050 |
480 | V>L | No |
ClinGen gnomAD |
|
|
rs1488157272 CA370058664 COSM252834 |
481 | R>C | ovary [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA4575331 rs763076132 |
481 | R>H | No |
ClinGen ExAC gnomAD |
|
|
CA4575332 rs763076132 |
481 | R>L | No |
ClinGen ExAC gnomAD |
No associated diseases with Q6STE5
8 GO annotations of cellular component
| Name | Definition |
|---|---|
| brahma complex | A SWI/SNF-type complex that contains 8 to 14 proteins, including both conserved (core) and nonconserved components; contains the ATPase product of the Drosophila brm (brahma) or mammalian SMARCA2/BAF190B/BRM gene, or an ortholog thereof. |
| chromatin | The ordered and organized complex of DNA, protein, and sometimes RNA, that forms the chromosome. |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| nBAF complex | A SWI/SNF-type complex that is found in post-mitotic neurons, and in human contains actin and proteins encoded by the ARID1A/BAF250A or ARID1B/BAF250B, SMARCD1/BAF60A, SMARCD3/BAF60C, SMARCA2/BRM/BAF190B, SMARCA4/BRG1/BAF190A, SMARCB1/BAF47, SMARCC1/BAF155, SMARCE1/BAF57, SMARCC2/BAF170, DPF1/BAF45B, DPF3/BAF45C, ACTL6B/BAF53B genes. The nBAF complex along with CREST plays a role regulating the activity of genes essential for dendrite growth. |
| npBAF complex | A SWI/SNF-type complex that is found in neural stem or progenitor cells, and in human contains actin and proteins encoded by the ARID1A/BAF250A or ARID1B/BAF250B, SMARCD1/BAF60A, SMARCD3/BAF60C, SMARCA2/BRM/BAF190B, SMARCA4/BRG1/BAF190A, SMARCB1/BAF47, SMARCC1/BAF155, SMARCE1/BAF57, SMARCC2/BAF170, PHF10/BAF45A, ACTL6A/BAF53A genes. The npBAF complex is essential for the self-renewal/proliferative capacity of the multipotent neural stem cells. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| SWI/SNF complex | A SWI/SNF-type complex that contains 8 to 14 proteins, including both conserved (core) and nonconserved components; contains the ATPase product of the yeast SNF2 or mammalian SMARCA4/BAF190A/BRG1 gene, or an ortholog thereof. |
7 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA-binding transcription factor binding | Binding to a DNA-binding transcription factor, a protein that interacts with a specific DNA sequence (sometimes referred to as a motif) within the regulatory region of a gene to modulate transcription. |
| nuclear receptor binding | Binding to a nuclear receptor protein. Nuclear receptor proteins are DNA-binding transcription factors which are regulated by binding to a ligand. |
| nuclear receptor coactivator activity | A transcription coactivator activity that activates or increases the transcription of specific gene sets via binding to a DNA-bound nuclear receptor, either on its own or as part of a complex. Coactivators often act by altering chromatin structure and modifications. For example, one class of transcription coregulators modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. A fourth class of coactivator activity is the bridging of a DNA-binding transcription factor to the general (basal) transcription machinery. The Mediator complex, which bridges sequence-specific DNA binding transcription factors and RNA polymerase, is also a transcription coactivator. |
| signaling receptor binding | Binding to one or more specific sites on a receptor molecule, a macromolecule that undergoes combination with a hormone, neurotransmitter, drug or intracellular messenger to initiate a change in cell function. |
| transcription coactivator activity | A transcription coregulator activity that activates or increases the transcription of specific gene sets via binding to a DNA-bound DNA-binding transcription factor, either on its own or as part of a complex. Coactivators often act by altering chromatin structure and modifications. For example, one class of transcription coactivators modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. A fourth class of coactivator activity is the bridging of a DNA-binding transcription factor to the general (basal) transcription machinery. The Mediator complex, which bridges sequence-specific DNA binding transcription factors and RNA polymerase, is also a transcription coactivator. |
| transcription coregulator activity | A transcription regulator activity that modulates the transcription of specific gene sets via binding to a DNA-bound DNA-binding transcription factor, either on its own or as part of a complex. Coregulators often act by altering chromatin structure and modifications. For example, one class of transcription coregulators modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. |
| transcription coregulator binding | Binding to a transcription coregulator, a protein involved in regulation of transcription via protein-protein interactions with transcription factors and other transcription regulatory proteins. Cofactors do not bind DNA directly, but rather mediate protein-protein interactions between regulatory transcription factors and the basal transcription machinery. |
19 GO annotations of biological process
| Name | Definition |
|---|---|
| cardiac right ventricle formation | The developmental process pertaining to the initial formation of a right cardiac ventricle from unspecified parts. |
| chromatin remodeling | A dynamic process of chromatin reorganization resulting in changes to chromatin structure. These changes allow DNA metabolic processes such as transcriptional regulation, DNA recombination, DNA repair, and DNA replication. |
| muscle cell differentiation | The process in which a relatively unspecialized cell acquires specialized features of a muscle cell. |
| nervous system development | The process whose specific outcome is the progression of nervous tissue over time, from its formation to its mature state. |
| neural retina development | The progression of the neural retina over time from its initial formation to the mature structure. The neural retina is the part of the retina that contains neurons and photoreceptor cells. |
| nucleosome disassembly | The controlled breakdown of nucleosomes, the beadlike structural units of eukaryotic chromatin composed of histones and DNA. |
| positive regulation of cell differentiation | Any process that activates or increases the frequency, rate or extent of cell differentiation. |
| positive regulation of DNA-templated transcription | Any process that activates or increases the frequency, rate or extent of cellular DNA-templated transcription. |
| positive regulation of double-strand break repair | Any process that activates or increases the frequency, rate or extent of double-strand break repair. |
| positive regulation of myoblast differentiation | Any process that activates or increases the frequency, rate or extent of myoblast differentiation. A myoblast is a mononucleate cell type that, by fusion with other myoblasts, gives rise to the myotubes that eventually develop into skeletal muscle fibers. |
| positive regulation of neuroblast proliferation | Any process that activates or increases the rate of neuroblast proliferation. |
| positive regulation of T cell differentiation | Any process that activates or increases the frequency, rate or extent of T cell differentiation. |
| regulation of G0 to G1 transition | A cell cycle process that modulates the rate or extent of the transition from the G0 quiescent state to the G1 phase. |
| regulation of G1/S transition of mitotic cell cycle | Any signalling pathway that modulates the activity of a cell cycle cyclin-dependent protein kinase to modulate the switch from G1 phase to S phase of the mitotic cell cycle. |
| regulation of mitotic metaphase/anaphase transition | Any process that modulates the frequency, rate or extent of the cell cycle process in which a cell progresses from metaphase to anaphase during mitosis, triggered by the activation of the anaphase promoting complex by Cdc20/Sleepy homolog which results in the degradation of Securin. |
| regulation of nucleotide-excision repair | Any process that modulates the frequency, rate or extent of nucleotide-excision repair. |
| regulation of protein binding | Any process that modulates the frequency, rate or extent of protein binding. |
| regulation of transcription by RNA polymerase II | Any process that modulates the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| secondary heart field specification | The process that results in the delineation of a specific region of the lateral mesoderm into the area which will form the majority of the mesodermal component of the right ventricle, arterial pole (outflow tract) and venous pole (inflow tract). |
9 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q2TBN1 | SMARCD1 | SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 1 | Bos taurus (Bovine) | PR |
| E1BJD1 | SMARCD2 | SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 2 | Bos taurus (Bovine) | PR |
| Q9VYG2 | Bap60 | Brahma-associated protein of 60 kDa | Drosophila melanogaster (Fruit fly) | PR |
| Q92925 | SMARCD2 | SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 2 | Homo sapiens (Human) | PR |
| Q96GM5 | SMARCD1 | SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 1 | Homo sapiens (Human) | PR |
| Q61466 | Smarcd1 | SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 1 | Mus musculus (Mouse) | PR |
| Q99JR8 | Smarcd2 | SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 2 | Mus musculus (Mouse) | PR |
| Q6P9Z1 | Smarcd3 | SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 3 | Mus musculus (Mouse) | PR |
| O54772 | Smarcd2 | SWI/SNF-related matrix-associated actin-dependent regulator of chromatin subfamily D member 2 | Rattus norvegicus (Rat) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAADEVAGGA | RKATKSKLFE | FLVHGVRPGM | PSGARMPHQG | APMGPPGSPY | MGSPAVRPGL |
| 70 | 80 | 90 | 100 | 110 | 120 |
| APAGMEPARK | RAAPPPGQSQ | AQSQGQPVPT | APARSRSAKR | RKMADKILPQ | RIRELVPESQ |
| 130 | 140 | 150 | 160 | 170 | 180 |
| AYMDLLAFER | KLDQTIMRKR | VDIQEALKRP | MKQKRKLRLY | ISNTFNPAKP | DAEDSDGSIA |
| 190 | 200 | 210 | 220 | 230 | 240 |
| SWELRVEGKL | LDDPSKQKRK | FSSFFKSLVI | ELDKDLYGPD | NHLVEWHRTP | TTQETDGFQV |
| 250 | 260 | 270 | 280 | 290 | 300 |
| KRPGDLSVRC | TLLLMLDYQP | PQFKLDPRLA | RLLGLHTQSR | SAIVQALWQY | VKTNRLQDSH |
| 310 | 320 | 330 | 340 | 350 | 360 |
| DKEYINGDKY | FQQIFDCPRL | KFSEIPQRLT | ALLLPPDPIV | INHVISVDPS | DQKKTACYDI |
| 370 | 380 | 390 | 400 | 410 | 420 |
| DVEVEEPLKG | QMSSFLLSTA | NQQEISALDS | KIHETIESIN | QLKIQRDFML | SFSRDPKGYV |
| 430 | 440 | 450 | 460 | 470 | 480 |
| QDLLRSQSRD | LKVMTDVAGN | PEEERRAEFY | HQPWSQEAVS | RYFYCKIQQR | RQELEQSLVV |
| RNT |