P0CH31
Gene name |
At1g43140 (F1I21.19) |
Protein name |
Putative cullin-like protein 1 |
Names |
|
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT1G43140 |
EC number |
|
Protein Class |
|
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
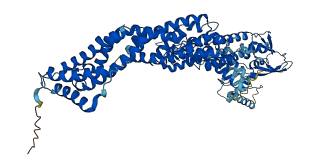
1 structures for P0CH31
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-P0CH31-F1 | Predicted | AlphaFoldDB |
165 variants for P0CH31
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH01265838 | 2 | A>D | No | 1000Genomes | |
| ENSVATH04835741 | 5 | L>F | No | 1000Genomes | |
| tmp_1_16232929_TA_GA,T | 9 | I>R | No | 1000Genomes | |
| ENSVATH13294906 | 11 | M>K | No | 1000Genomes | |
| ENSVATH13294905 | 11 | M>V | No | 1000Genomes | |
| ENSVATH01265844 | 13 | E>K | No | 1000Genomes | |
| ENSVATH01265845 | 14 | L>I | No | 1000Genomes | |
| ENSVATH00077194 | 18 | E>D | No | 1000Genomes | |
| ENSVATH04835743 | 23 | V>L | No | 1000Genomes | |
| ENSVATH00077195 | 25 | K>E | No | 1000Genomes | |
| ENSVATH04835744 | 26 | T>I | No | 1000Genomes | |
| tmp_1_16232994_C_A | 31 | L>I | No | 1000Genomes | |
| ENSVATH13294909 | 36 | E>K | No | 1000Genomes | |
| ENSVATH13294910 | 44 | D>E | No | 1000Genomes | |
| ENSVATH04835745 | 45 | P>A | No | 1000Genomes | |
| ENSVATH04835745 | 45 | P>S | No | 1000Genomes | |
| ENSVATH01265849 | 46 | G>R | No | 1000Genomes | |
| ENSVATH01265849 | 46 | G>S | No | 1000Genomes | |
| ENSVATH04835749 | 54 | I>T | No | 1000Genomes | |
| ENSVATH04835750 | 62 | Q>K | No | 1000Genomes | |
| tmp_1_16233168_G_A | 66 | D>N | No | 1000Genomes | |
| ENSVATH01265855 | 72 | Y>C | No | 1000Genomes | |
| ENSVATH13294947 | 73 | N>I | No | 1000Genomes | |
| ENSVATH00077198 | 79 | V>I | No | 1000Genomes | |
| ENSVATH01265856 | 81 | H>D | No | 1000Genomes | |
| tmp_1_16233219_A_G | 83 | N>D | No | 1000Genomes | |
| ENSVATH01265860 | 98 | Y>F | No | 1000Genomes | |
| tmp_1_16233344_C_A | 100 | L>M | No | 1000Genomes | |
| tmp_1_16233356_G_A | 104 | V>I | No | 1000Genomes | |
| ENSVATH13294953 | 105 | K>N | No | 1000Genomes | |
| ENSVATH13294954 | 142 | F>V | No | 1000Genomes | |
| ENSVATH04835756 | 147 | D>E | No | 1000Genomes | |
| ENSVATH04835757 | 153 | I>K | No | 1000Genomes | |
| tmp_1_16233515_G_C | 157 | A>P | No | 1000Genomes | |
| ENSVATH00077201 | 159 | D>N | No | 1000Genomes | |
| ENSVATH00077201 | 159 | D>Y | No | 1000Genomes | |
| ENSVATH04835758 | 163 | A>S | No | 1000Genomes | |
| ENSVATH04835758 | 163 | A>T | No | 1000Genomes | |
| ENSVATH01265869 | 170 | E>D | No | 1000Genomes | |
| ENSVATH14190544 | 172 | E>Q | No | 1000Genomes | |
| ENSVATH04835760 | 173 | Q>K | No | 1000Genomes | |
| tmp_1_16233663_A_G | 180 | K>E | No | 1000Genomes | |
| ENSVATH01265870 | 185 | V>I | No | 1000Genomes | |
| tmp_1_16233684_T_C | 187 | C>R | No | 1000Genomes | |
| ENSVATH13294971 | 192 | G>R | No | 1000Genomes | |
| tmp_1_16233711_A_G | 196 | I>V | No | 1000Genomes | |
| tmp_1_16233714_T_G | 197 | Y>D | No | 1000Genomes | |
| tmp_1_16233740_G_T | 205 | L>F | No | 1000Genomes | |
| tmp_1_16233754_C_G | 210 | A>G | No | 1000Genomes | |
| ENSVATH13294998 | 215 | R>H | No | 1000Genomes | |
| ENSVATH01265873 | 217 | A>T | No | 1000Genomes | |
| ENSVATH00077204 | 219 | R>K | Leaf number was scored as the number of rosette leaves and the number of cauline leaves when the bolt reached 5cm [20-22c and natural light from the middle of october 2002 till march 2003. vernalized for 8wks at 4c and 8hrs daylight] Number of days required for the bolt height to reach 5cm [23c and 16hrs daylight. vernalized for 8 wks at 5c and 8hrs daylight] [EnsemblGenome] | No | 1000Genomes |
| tmp_1_16233789_C_T | 222 | Q>* | No | 1000Genomes | |
| ENSVATH04835763 | 230 | M>K | No | 1000Genomes | |
| tmp_1_16233845_G_T | 240 | E>D | No | 1000Genomes | |
| ENSVATH07614015 | 250 | S>P | No | 1000Genomes | |
| ENSVATH13294999 | 254 | P>S | No | 1000Genomes | |
| ENSVATH04835766 | 266 | V>A | No | 1000Genomes | |
| ENSVATH01265883 | 270 | K>T | No | 1000Genomes | |
| tmp_1_16234024_C_A | 271 | Q>K | No | 1000Genomes | |
| tmp_1_16234031_T_G | 273 | I>R | No | 1000Genomes | |
| ENSVATH14190578 | 278 | S>F | No | 1000Genomes | |
| tmp_1_16234048_G_A | 279 | G>R | No | 1000Genomes | |
| ENSVATH13295001 | 281 | L>F | No | 1000Genomes | |
| ENSVATH04835767 | 281 | L>R | No | 1000Genomes | |
| ENSVATH13295002 | 286 | D>N | No | 1000Genomes | |
| tmp_1_16234327_C_G | 293 | S>W | No | 1000Genomes | |
| ENSVATH09329927 | 301 | L>Q | No | 1000Genomes | |
| ENSVATH09329927 | 301 | L>R | No | 1000Genomes | |
| tmp_1_16234357_C_T | 303 | P>L | No | 1000Genomes | |
| ENSVATH04835781 | 305 | G>W | No | 1000Genomes | |
| ENSVATH04835782 | 308 | P>H | No | 1000Genomes | |
| ENSVATH01265907 | 310 | A>T | No | 1000Genomes | |
| ENSVATH07614017 | 315 | Q>* | No | 1000Genomes | |
| ENSVATH07614017 | 315 | Q>K | No | 1000Genomes | |
| tmp_1_16234393_AG_GG,CG,A | 315 | Q>P | No | 1000Genomes | |
| tmp_1_16234393_AG_GG,CG,A | 315 | Q>R | No | 1000Genomes | |
| tmp_1_16234399_T_C | 317 | V>A | No | 1000Genomes | |
| ENSVATH04835783 | 318 | T>S | No | 1000Genomes | |
| ENSVATH01265908 | 319 | A>V | No | 1000Genomes | |
| ENSVATH13295045 | 320 | E>K | No | 1000Genomes | |
| tmp_1_16234414_A_T | 322 | N>I | No | 1000Genomes | |
| ENSVATH04835784 | 325 | I>T | No | 1000Genomes | |
| ENSVATH00077210 | 330 | D>E | No | 1000Genomes | |
| ENSVATH04835785 | 331 | A>T | No | 1000Genomes | |
| tmp_1_16234444_C_T | 332 | A>V | No | 1000Genomes | |
| ENSVATH13295047 | 337 | A>V | No | 1000Genomes | |
| tmp_1_16234464_G_A | 339 | A>T | No | 1000Genomes | |
| ENSVATH04835786 | 340 | S>I | No | 1000Genomes | |
| tmp_1_16234467_A_C | 340 | S>R | No | 1000Genomes | |
| ENSVATH01265910 | 347 | E>D | No | 1000Genomes | |
| ENSVATH04835787 | 351 | H>Y | No | 1000Genomes | |
| tmp_1_16234521_G_A | 358 | V>I | No | 1000Genomes | |
| ENSVATH01265912 | 371 | L>V | No | 1000Genomes | |
| ENSVATH13295050 | 372 | L>* | No | 1000Genomes | |
| ENSVATH13295049 | 372 | L>I | No | 1000Genomes | |
| ENSVATH01265915 | 375 | A>T | No | 1000Genomes | |
| ENSVATH01265917 | 380 | C>Y | No | 1000Genomes | |
| ENSVATH01265918 | 383 | T>A | No | 1000Genomes | |
| ENSVATH04835790 | 383 | T>I | No | 1000Genomes | |
| tmp_1_16234611_T_G | 388 | S>A | No | 1000Genomes | |
| ENSVATH14190605 | 389 | S>T | No | 1000Genomes | |
| ENSVATH01265920 | 390 | A>P | No | 1000Genomes | |
| ENSVATH14190606 | 399 | N>K | No | 1000Genomes | |
| tmp_1_16234647_A_G | 400 | I>V | No | 1000Genomes | |
| ENSVATH04835792 | 404 | R>I | No | 1000Genomes | |
| ENSVATH04835793 | 417 | I>S | No | 1000Genomes | |
| ENSVATH04835793 | 417 | I>T | No | 1000Genomes | |
| ENSVATH04835794 | 427 | V>I | No | 1000Genomes | |
| tmp_1_16234734_A_T | 429 | I>L | No | 1000Genomes | |
| ENSVATH01265923 | 430 | S>N | No | 1000Genomes | |
| tmp_1_16234744_A_G | 432 | K>R | No | 1000Genomes | |
| ENSVATH13295070 | 455 | M>T | No | 1000Genomes | |
| tmp_1_16235059_C_G | 459 | T>R | No | 1000Genomes | |
| tmp_1_16235068_C_A | 462 | T>K | No | 1000Genomes | |
| ENSVATH01265932 | 467 | L>F | No | 1000Genomes | |
| ENSVATH04835800 | 498 | P>S | No | 1000Genomes | |
| ENSVATH04835801 | 503 | T>I | No | 1000Genomes | |
| tmp_1_16235214_A_T | 511 | M>L | No | 1000Genomes | |
| tmp_1_16235312_T_C | 515 | V>A | No | 1000Genomes | |
| ENSVATH04835808 | 517 | A>T | No | 1000Genomes | |
| ENSVATH04835809 | 517 | A>V | No | 1000Genomes | |
| ENSVATH01265939 | 519 | K>R | No | 1000Genomes | |
| ENSVATH04835810 | 522 | Y>* | No | 1000Genomes | |
| ENSVATH04835812 | 531 | L>I | No | 1000Genomes | |
| ENSVATH04835812 | 531 | L>V | No | 1000Genomes | |
| ENSVATH04835813 | 533 | W>L | No | 1000Genomes | |
| tmp_1_16235375_C_A | 536 | S>Y | No | 1000Genomes | |
| ENSVATH13295082 | 539 | T>N | No | 1000Genomes | |
| ENSVATH13295083 | 542 | I>V | No | 1000Genomes | |
| ENSVATH04835814 | 547 | E>K | No | 1000Genomes | |
| ENSVATH01265941 | 548 | K>R | No | 1000Genomes | |
| ENSVATH01265942 | 563 | L>F | No | 1000Genomes | |
| ENSVATH04835816 | 564 | L>F | No | 1000Genomes | |
| tmp_1_16235461_C_T | 565 | L>F | No | 1000Genomes | |
| ENSVATH01265944 | 569 | A>V | No | 1000Genomes | |
| ENSVATH04835817 | 571 | R>S | No | 1000Genomes | |
| ENSVATH04835818 | 578 | S>A | No | 1000Genomes | |
| ENSVATH04835819 | 584 | S>I | No | 1000Genomes | |
| ENSVATH01265947 | 591 | L>V | No | 1000Genomes | |
| ENSVATH04835820 | 604 | I>R | No | 1000Genomes | |
| ENSVATH13295095 | 605 | K>E | No | 1000Genomes | |
| ENSVATH13295096 | 617 | T>S | No | 1000Genomes | |
| ENSVATH04835821 | 619 | E>K | No | 1000Genomes | |
| ENSVATH01265950 | 622 | S>F | No | 1000Genomes | |
| ENSVATH01265950 | 622 | S>Y | No | 1000Genomes | |
| ENSVATH04835822 | 623 | K>N | No | 1000Genomes | |
| ENSVATH00077215 | 626 | D>N | No | 1000Genomes | |
| tmp_1_16235650_A_T | 628 | M>L | No | 1000Genomes | |
| ENSVATH01265955 | 634 | P>L | No | 1000Genomes | |
| ENSVATH01265956 | 642 | K>E | No | 1000Genomes | |
| tmp_1_16235778_G_A | 644 | V>I | No | 1000Genomes | |
| ENSVATH01265958 | 654 | Y>N | No | 1000Genomes | |
| tmp_1_16235819_T_A | 657 | D>E | No | 1000Genomes | |
| ENSVATH13295102 | 669 | V>M | No | 1000Genomes | |
| tmp_1_16235874_G_C | 676 | V>L | No | 1000Genomes | |
| ENSVATH01265961 | 677 | S>C | No | 1000Genomes | |
| tmp_1_16235902_A_T | 685 | K>I | No | 1000Genomes | |
| ENSVATH01265971 | 692 | K>M | No | 1000Genomes | |
| tmp_1_16236032_C_T | 697 | R>W | No | 1000Genomes | |
| ENSVATH14190636 | 703 | N>K | No | 1000Genomes | |
| ENSVATH04835830 | 712 | E>D | No | 1000Genomes | |
| ENSVATH01265975 | 712 | E>K | No | 1000Genomes | |
| tmp_1_16236084_C_A | 714 | A>D | No | 1000Genomes | |
| tmp_1_16236094_C_G | 717 | F>L | No | 1000Genomes |
No associated diseases with P0CH31
4 regional properties for P0CH31
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Cullin, N-terminal | 30 - 452 | IPR001373-1 |
| domain | Cullin, N-terminal | 458 - 624 | IPR001373-2 |
| domain | Cullin homology domain | 388 - 596 | IPR016158 |
| domain | Cullin protein, neddylation domain | 648 - 715 | IPR019559 |
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| cullin-RING ubiquitin ligase complex | Any ubiquitin ligase complex in which the catalytic core consists of a member of the cullin family and a RING domain protein; the core is associated with one or more additional proteins that confer substrate specificity. |
1 GO annotations of molecular function
| Name | Definition |
|---|---|
| ubiquitin protein ligase binding | Binding to a ubiquitin protein ligase enzyme, any of the E3 proteins. |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| protein ubiquitination | The process in which one or more ubiquitin groups are added to a protein. |
| ubiquitin-dependent protein catabolic process | The chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of a ubiquitin group, or multiple ubiquitin groups, to the protein. |
8 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q12018 | CDC53 | Cell division control protein 53 | Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) | PR |
| Q24311 | Cul1 | Cullin homolog 1 | Drosophila melanogaster (Fruit fly) | PR |
| Q13619 | CUL4A | Cullin-4A | Homo sapiens (Human) | PR |
| Q13620 | CUL4B | Cullin-4B | Homo sapiens (Human) | PR |
| Q13616 | CUL1 | Cullin-1 | Homo sapiens (Human) | PR |
| A2A432 | Cul4b | Cullin-4B | Mus musculus (Mouse) | PR |
| Q3TCH7 | Cul4a | Cullin-4A | Mus musculus (Mouse) | PR |
| Q17392 | cul-4 | Cullin-4 | Caenorhabditis elegans | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MATILFKVIM | MKELILLEEG | WSVMKTGVAK | LQRILEDLSE | PPFDPGQYIN | LYTIIYDMCL |
| 70 | 80 | 90 | 100 | 110 | 120 |
| QQPPNDYSQE | LYNKYRGVVD | HYNKETVLPS | MRERHGEYML | RELVKRWANH | KILVRWLSRF |
| 130 | 140 | 150 | 160 | 170 | 180 |
| CFYLDRFYVA | RRGLPTLNDV | GFTSFHDLVY | QEIQSEAKDV | LLALIHKERE | GEQIDRTLVK |
| 190 | 200 | 210 | 220 | 230 | 240 |
| NVIDVYCGNG | VGQMVIYEED | FESFLLQDTA | SYYSRKASRW | SQEDSCPDYM | LKAEECLKLE |
| 250 | 260 | 270 | 280 | 290 | 300 |
| KERVTNYLHS | TTEPKLVEKV | QNELLVVVAK | QLIENEHSGC | LALLRDDKMG | DLSRMYRLYR |
| 310 | 320 | 330 | 340 | 350 | 360 |
| LIPQGLEPIA | DLFKQHVTAE | GNALIKQAAD | AATNQDASAS | QVLVRKEIEL | HDKYMVYVDE |
| 370 | 380 | 390 | 400 | 410 | 420 |
| CFQKHSLFHK | LLKEAFEVFC | NKTVAGASSA | EILATYCDNI | LKTRGGSEKL | SDEATEITLE |
| 430 | 440 | 450 | 460 | 470 | 480 |
| KVVNLLVYIS | DKDLFAEFYR | KKQARRLLFD | RSGIMKEVTD | ITLARELQTN | FVDYLSANMT |
| 490 | 500 | 510 | 520 | 530 | 540 |
| TKLGIDFTVT | VLTTGFWPSY | KTTDLNLPTE | MVNCVEAFKV | FYGTKTNSRR | LSWIYSLGTC |
| 550 | 560 | 570 | 580 | 590 | 600 |
| HILGKFEKKT | MELVVSTYQA | AVLLLFNNAE | RLSYTEISEQ | LNLSHEDLVR | LLHSLSCLKY |
| 610 | 620 | 630 | 640 | 650 | 660 |
| KILIKEPMSR | TISKTDTFEF | NSKFTDKMRK | IRVPLPPMDE | RKKVVEDVDK | DRRYAIDAAL |
| 670 | 680 | 690 | 700 | 710 | 720 |
| VRIMKSRKVL | AHQQLVSECV | EHLSKMFKPD | IKMIKKRIED | LINRDYLERD | TENANTFKYV |
| A |