Q9UKT7
Gene name |
FBXL3 (FBL3A, FBXL3A) |
Protein name |
F-box/LRR-repeat protein 3 |
Names |
F-box and leucine-rich repeat protein 3A, F-box/LRR-repeat protein 3A |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:26224 |
EC number |
|
Protein Class |
|
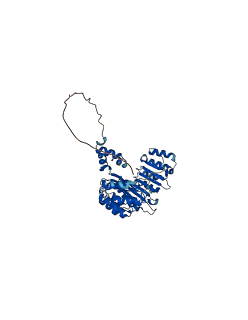
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
2 structures for Q9UKT7
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 4I6J | X-ray | 270 A | B | 1-428 | PDB |
| AF-Q9UKT7-F1 | Predicted | AlphaFoldDB |
201 variants for Q9UKT7
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
RCV000767371 CA388320470 rs374431043 |
149 | R>* | Intellectual disability, short stature, facial anomalies, and joint dislocations [ClinVar] | Yes |
ClinGen ClinVar ESP ExAC TOPMed dbSNP gnomAD |
| VAR_082209 | 149 | R>del | IDDSFAS [UniProt] | Yes | UniProt |
|
rs764008859 RCV000767372 |
295 | L>missing | Intellectual disability, short stature, facial anomalies, and joint dislocations [ClinVar] | Yes |
ClinVar dbSNP |
|
CA388317235 RCV000767373 VAR_082210 rs1566225872 |
358 | C>R | Intellectual disability, short stature, facial anomalies, and joint dislocations IDDSFAS [ClinVar, UniProt] | Yes |
ClinGen ClinVar UniProt Ensembl dbSNP |
|
rs758124709 CA7007515 |
3 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs752598486 CA7007514 |
5 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs199677324 CA252185004 |
7 | D>E | No |
ClinGen 1000Genomes TOPMed |
|
|
CA252185007 rs764791962 |
7 | D>H | No |
ClinGen gnomAD |
|
|
CA388322199 rs764791962 |
7 | D>N | No |
ClinGen gnomAD |
|
|
CA7007513 rs779089895 |
8 | S>N | No |
ClinGen ExAC gnomAD |
|
|
CA388322174 rs1384283923 |
9 | D>E | No |
ClinGen gnomAD |
|
|
rs755236079 CA7007512 |
10 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7007511 rs754093926 |
10 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs754093926 CA252185000 |
10 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388322156 rs1380868444 |
12 | S>L | No |
ClinGen gnomAD |
|
|
CA388322154 rs1179294511 |
13 | S>P | No |
ClinGen gnomAD |
|
|
rs756859518 CA252184996 |
16 | G>R | No |
ClinGen Ensembl |
|
|
CA388322111 rs766385956 |
18 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7007510 rs766385956 |
18 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs760810775 CA7007509 |
21 | S>F | No |
ClinGen ExAC gnomAD |
|
|
rs1241508808 CA388322070 |
21 | S>P | No |
ClinGen TOPMed gnomAD |
|
|
CA388322065 rs760810775 |
21 | S>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA7007507 rs193234231 |
22 | K>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1203765127 CA388322053 |
22 | K>R | No |
ClinGen gnomAD |
|
|
CA388322045 rs1353551240 |
23 | K>Q | No |
ClinGen gnomAD |
|
|
CA7007504 rs1003951744 |
26 | T>I | No |
ClinGen TOPMed |
|
|
CA388321986 rs1380001729 |
27 | T>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1313907109 CA388321930 |
31 | S>P | No |
ClinGen gnomAD |
|
|
CA252184937 COSM1639378 rs904456346 |
32 | Q>* | stomach [Cosmic] | No |
ClinGen cosmic curated Ensembl |
|
rs769172956 CA7007502 |
33 | T>A | No |
ClinGen ExAC gnomAD |
|
|
rs1486744567 CA388321901 |
33 | T>N | No |
ClinGen TOPMed |
|
|
rs373585221 CA252184930 |
36 | W>L | No |
ClinGen ESP |
|
|
CA388321647 rs1360553215 |
37 | G>S | No |
ClinGen gnomAD |
|
|
rs1389511778 CA388321606 |
42 | D>V | No |
ClinGen gnomAD |
|
|
CA252184919 rs199988301 |
43 | I>V | No |
ClinGen Ensembl |
|
|
rs201719570 CA252184915 |
49 | K>Q | No |
ClinGen Ensembl |
|
|
rs770501959 CA7007499 |
49 | K>T | No |
ClinGen ExAC gnomAD |
|
|
rs746596303 CA7007498 |
54 | L>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388321528 rs1361056308 |
54 | L>V | No |
ClinGen gnomAD |
|
|
CA7007497 rs777558812 |
55 | D>E | No |
ClinGen ExAC gnomAD |
|
|
COSM1367716 CA388321516 rs1383545118 |
56 | R>W | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
rs772100049 CA7007496 |
57 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs747868204 CA7007495 |
57 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs754793412 CA7007493 |
58 | H>R | No |
ClinGen ExAC gnomAD |
|
|
CA7007494 rs778642310 |
58 | H>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1488190074 CA388321466 |
64 | R>C | No |
ClinGen gnomAD |
|
|
rs753990250 CA7007492 |
64 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs780319441 CA388321460 |
65 | N>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs371851666 CA388321457 |
65 | N>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs780319441 CA7007491 |
65 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs780319441 CA388321459 |
65 | N>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs367807769 CA7007489 |
69 | V>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA388321409 rs1285430756 |
72 | M>K | No |
ClinGen TOPMed |
|
|
rs922294840 CA252184851 |
72 | M>L | No |
ClinGen TOPMed gnomAD |
|
|
rs922294840 CA252184853 |
72 | M>V | No |
ClinGen TOPMed gnomAD |
|
|
rs767878877 CA388321350 |
80 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs767878877 CA7007488 |
80 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA7007487 rs762339853 |
85 | Q>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs976513633 CA388321307 |
86 | P>S | No |
ClinGen gnomAD |
|
|
CA252184842 rs976513633 |
86 | P>T | No |
ClinGen gnomAD |
|
|
CA388321302 rs1299961095 |
87 | A>T | No |
ClinGen gnomAD |
|
|
CA252184839 rs200924298 |
89 | S>T | No |
ClinGen TOPMed |
|
|
rs764497283 CA7007485 |
91 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs371133632 CA7007484 |
98 | L>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7007483 rs776419080 |
99 | I>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7007482 rs770675461 |
100 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388321126 rs1196305170 |
103 | I>T | No |
ClinGen gnomAD |
|
|
rs1264431793 CA388321131 |
103 | I>V | No |
ClinGen gnomAD |
|
|
rs1489988724 CA388321098 |
105 | R>K | No |
ClinGen gnomAD |
|
|
CA252184831 rs796829861 |
108 | N>T | No |
ClinGen TOPMed |
|
| TCGA novel | 115 | F>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7007453 rs772764851 |
126 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs761377191 CA7007451 |
130 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA388320672 rs1177245925 |
132 | S>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs749047548 CA7007448 |
138 | S>P | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 142 | L>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7007447 rs775314543 |
142 | L>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 143 | G>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs370379122 CA7007446 |
145 | I>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs138133067 CA7007445 |
146 | S>* | No |
ClinGen ESP ExAC |
|
|
CA388320487 rs1315214026 |
147 | T>S | No |
ClinGen TOPMed |
|
|
rs1239596856 CA388320474 |
148 | A>V | No |
ClinGen gnomAD |
|
|
rs374431043 CA252183672 |
149 | R>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1482803798 CA388320467 |
149 | R>Q | No |
ClinGen gnomAD |
|
|
CA7007442 rs747145560 |
152 | F>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1315013976 CA388320412 |
153 | M>T | No |
ClinGen gnomAD |
|
|
rs1461073390 CA388320402 |
154 | D>Y | No |
ClinGen TOPMed |
|
|
CA388320202 rs1420774136 |
158 | S>C | No |
ClinGen TOPMed gnomAD |
|
|
CA388320198 rs1420774136 |
158 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
rs779295651 CA7007414 |
159 | H>P | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 159 | H>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA388320155 rs1457005101 |
161 | I>M | No |
ClinGen TOPMed gnomAD |
|
|
CA388320118 rs1367466203 |
165 | T>I | No |
ClinGen TOPMed |
|
|
CA7007411 rs201531118 |
169 | V>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ExAC NCI-TCGA TOPMed gnomAD |
| TCGA novel | 172 | K>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs751234212 CA7007409 |
175 | S>Y | No |
ClinGen ExAC gnomAD |
|
|
COSM253720 rs560551710 CA7007408 |
176 | S>L | urinary_tract [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs752676139 CA7007406 |
177 | L>R | No |
ClinGen ExAC gnomAD |
|
|
rs1277900686 CA388319902 |
182 | T>N | No |
ClinGen gnomAD |
|
|
rs765146279 CA7007405 |
183 | P>Q | No |
ClinGen ExAC gnomAD |
|
|
CA388319829 rs1283637983 |
187 | P>L | No |
ClinGen gnomAD |
|
|
CA7007402 rs770884350 |
190 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs760932907 CA7007401 |
190 | K>R | No |
ClinGen ExAC |
|
|
rs1593928803 CA388319743 |
195 | N>K | No |
ClinGen Ensembl |
|
|
rs1422497382 CA388319723 |
197 | S>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1227107106 CA388319703 |
198 | D>G | No |
ClinGen TOPMed |
|
|
rs879147435 CA252182477 |
205 | M>I | No |
ClinGen Ensembl |
|
|
rs1375842051 CA388319555 |
213 | P>S | No |
ClinGen gnomAD |
|
|
CA7007397 rs779448827 |
214 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs1566226219 CA388318882 |
216 | I>M | No |
ClinGen Ensembl |
|
|
rs1309529067 CA388318870 |
218 | C>F | No |
ClinGen TOPMed gnomAD |
|
|
rs1309529067 CA388318872 |
218 | C>Y | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 220 | A>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs753618541 CA7007372 |
221 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA388318855 rs1357085859 |
221 | D>N | No |
ClinGen gnomAD |
|
|
rs746288188 CA7007370 |
225 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 228 | E>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA388318790 rs199748270 |
230 | A>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs199748270 CA7007369 |
230 | A>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1179351155 CA388318759 |
234 | H>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA7007368 rs758028722 |
234 | H>Y | No |
ClinGen ExAC gnomAD |
|
|
rs565151928 CA252179641 |
237 | S>T | No |
ClinGen Ensembl |
|
|
rs775483274 CA252179637 |
239 | E>G | No |
ClinGen Ensembl |
|
| TCGA novel | 249 | H>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA388318645 rs1462227471 |
251 | R>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs1566226148 CA388318622 |
254 | H>L | No |
ClinGen Ensembl |
|
|
CA388318614 rs1215174703 |
255 | L>F | No |
ClinGen TOPMed gnomAD |
|
|
CA252179629 rs888492011 |
255 | L>V | No |
ClinGen TOPMed |
|
|
COSM3764483 CA7007364 rs753765117 |
256 | R>C | central_nervous_system [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
CA7007363 rs766494461 COSM275140 |
256 | R>H | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
rs766494461 CA388318610 |
256 | R>L | No |
ClinGen ExAC gnomAD |
|
|
rs1290004770 CA388318589 |
259 | V>G | No |
ClinGen TOPMed |
|
|
rs1224992538 CA388318574 |
262 | E>Q | No |
ClinGen gnomAD |
|
|
CA7007362 rs374182615 |
264 | P>L | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1039802350 CA252179620 |
267 | T>A | No |
ClinGen Ensembl |
|
|
rs1283278542 CA388318535 |
267 | T>I | No |
ClinGen gnomAD |
|
|
rs943735886 CA252179617 |
268 | H>R | No |
ClinGen Ensembl |
|
|
CA388318532 rs1355430950 |
268 | H>Y | No |
ClinGen TOPMed |
|
|
CA388318505 rs1048504343 |
272 | I>L | No |
ClinGen TOPMed gnomAD |
|
|
CA252179611 rs1048504343 |
272 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
CA7007360 rs767449785 |
279 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA388318428 rs1243293815 |
282 | R>K | No |
ClinGen gnomAD |
|
|
rs202030737 CA252179604 |
285 | P>S | No |
ClinGen 1000Genomes |
|
|
rs1402564584 CA388318404 |
286 | K>Q | No |
ClinGen gnomAD |
|
|
rs1411865046 CA388318401 |
286 | K>T | No |
ClinGen gnomAD |
|
|
rs764011537 CA7007357 |
289 | L>S | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 294 | F>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7007356 rs763159668 |
295 | L>I | No |
ClinGen ExAC gnomAD |
|
|
rs1216357687 CA388318334 |
295 | L>S | No |
ClinGen TOPMed |
|
| rs764008859 | 295 | L>Y | Variant assessed as Somatic; 0.0001495 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7007352 rs746200234 |
296 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs373258013 CA388318330 |
296 | Y>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7007353 rs373258013 |
296 | Y>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 300 | F>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 301 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs760763712 CA252179577 |
302 | P>S | No |
ClinGen gnomAD |
|
|
rs369788246 CA7007348 |
305 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs754446542 CA7007347 |
305 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA7007346 rs141339299 |
306 | Y>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA252179565 rs573517886 |
308 | I>T | No |
ClinGen TOPMed gnomAD |
|
|
CA7007345 rs780103627 |
308 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1300011178 CA388318231 |
310 | A>V | No |
ClinGen gnomAD |
|
|
rs1555275091 CA388318218 |
312 | H>R | No |
ClinGen Ensembl |
|
|
rs1375531139 CA388318174 |
319 | V>I | No |
ClinGen TOPMed |
|
|
rs373072488 CA252179552 |
322 | D>N | No |
ClinGen ESP |
|
|
rs1593921137 CA388318149 |
322 | D>V | No |
ClinGen Ensembl |
|
|
CA7007342 rs767156725 |
324 | L>R | No |
ClinGen ExAC |
|
|
CA388318126 rs1440959774 |
326 | R>C | No |
ClinGen TOPMed |
|
| TCGA novel | 327 | V>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 331 | C>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs869051475 CA252179543 |
343 | G>V | No |
ClinGen Ensembl |
|
|
CA7007338 rs762998083 |
345 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1221689576 CA388317391 |
349 | E>D | No |
ClinGen gnomAD |
|
|
rs745444479 CA7007335 |
353 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA388317322 rs745444479 |
353 | R>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs759989436 CA7007334 |
357 | R>C | No |
ClinGen ExAC gnomAD |
|
|
rs1338037603 CA388317207 |
360 | N>H | No |
ClinGen gnomAD |
|
|
rs771136982 CA7007332 |
364 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388317115 rs1566225840 |
367 | G>A | No |
ClinGen Ensembl |
|
|
rs375666314 CA7007328 |
369 | C>Y | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7007327 rs779659265 |
370 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA388317004 rs1178134325 |
382 | M>I | No |
ClinGen TOPMed |
|
|
rs1394857989 CA388316981 |
386 | R>C | No |
ClinGen TOPMed |
|
|
rs756988737 CA7007323 COSM948483 |
386 | R>H | Variant assessed as Somatic; impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA |
| TCGA novel | 388 | S>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1431894670 CA388316945 |
392 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
CA388316938 rs1191233744 |
393 | M>V | No |
ClinGen gnomAD |
|
| TCGA novel | 394 | E>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1395119742 CA388316916 |
395 | E>D | No |
ClinGen TOPMed |
|
|
CA7007320 rs777828187 |
396 | V>E | No |
ClinGen ExAC gnomAD |
|
|
CA388316904 rs1457940322 |
398 | I>L | No |
ClinGen gnomAD |
|
|
CA7007318 rs752940172 |
400 | D>H | No |
ClinGen ExAC gnomAD |
|
|
rs1235087092 CA388316851 |
405 | L>V | No |
ClinGen gnomAD |
|
|
CA388316819 rs1446244000 |
409 | H>P | No |
ClinGen gnomAD |
|
|
rs1326336613 CA388316815 |
409 | H>Q | No |
ClinGen TOPMed |
|
|
rs1307343175 CA388316820 |
409 | H>Y | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA388316814 rs1355916066 |
410 | W>R | No |
ClinGen TOPMed |
|
|
rs1566225724 CA388316778 |
414 | K>N | No |
ClinGen Ensembl |
|
|
rs760929977 CA7007313 |
420 | W>* | No |
ClinGen ExAC gnomAD |
|
|
CA7007311 rs772342610 COSM1206781 |
423 | D>N | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs767543712 CA252179496 |
425 | M>L | No |
ClinGen Ensembl |
1 associated diseases with Q9UKT7
[MIM: 606220]: Intellectual developmental disorder with short stature, facial anomalies, and speech defects (IDDSFAS)
An autosomal recessive disorder characterized by global developmental delay, mildly to severely impaired intellectual development, delayed or slurred speech, and short stature. Dysmorphic features included a large bulbous nose and variable microretrognathia. Some patients show joint hyperlaxity and dislocations. {ECO:0000269|PubMed:30481285}. Note=The disease is caused by variants affecting the gene represented in this entry.
Without disease ID
- An autosomal recessive disorder characterized by global developmental delay, mildly to severely impaired intellectual development, delayed or slurred speech, and short stature. Dysmorphic features included a large bulbous nose and variable microretrognathia. Some patients show joint hyperlaxity and dislocations. {ECO:0000269|PubMed:30481285}. Note=The disease is caused by variants affecting the gene represented in this entry.
1 regional properties for Q9UKT7
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | F-box domain | 39 - 79 | IPR001810 |
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nuclear body | Extra-nucleolar nuclear domains usually visualized by confocal microscopy and fluorescent antibodies to specific proteins. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| SCF ubiquitin ligase complex | A ubiquitin ligase complex in which a cullin from the Cul1 subfamily and a RING domain protein form the catalytic core; substrate specificity is conferred by a Skp1 adaptor and an F-box protein. SCF complexes are involved in targeting proteins for degradation by the proteasome. The best characterized complexes are those from yeast and mammals (with core subunits named Cdc53/Cul1, Rbx1/Hrt1/Roc1). |
| ubiquitin ligase complex | A protein complex that includes a ubiquitin-protein ligase and enables ubiquitin protein ligase activity. The complex also contains other proteins that may confer substrate specificity on the complex. |
1 GO annotations of molecular function
| Name | Definition |
|---|---|
| ubiquitin-protein transferase activity | Catalysis of the transfer of ubiquitin from one protein to another via the reaction X-Ub + Y --> Y-Ub + X, where both X-Ub and Y-Ub are covalent linkages. |
8 GO annotations of biological process
| Name | Definition |
|---|---|
| entrainment of circadian clock by photoperiod | The synchronization of a circadian rhythm to photoperiod, the intermittent cycle of light (day) and dark (night). |
| G2/M transition of mitotic cell cycle | The mitotic cell cycle transition by which a cell in G2 commits to M phase. The process begins when the kinase activity of M cyclin/CDK complex reaches a threshold high enough for the cell cycle to proceed. This is accomplished by activating a positive feedback loop that results in the accumulation of unphosphorylated and active M cyclin/CDK complex. |
| protein destabilization | Any process that decreases the stability of a protein, making it more vulnerable to degradative processes or aggregation. |
| protein ubiquitination | The process in which one or more ubiquitin groups are added to a protein. |
| regulation of cell cycle | Any process that modulates the rate or extent of progression through the cell cycle. |
| regulation of circadian rhythm | Any process that modulates the frequency, rate or extent of a circadian rhythm. A circadian rhythm is a biological process in an organism that recurs with a regularity of approximately 24 hours. |
| rhythmic process | Any process pertinent to the generation and maintenance of rhythms in the physiology of an organism. |
| SCF-dependent proteasomal ubiquitin-dependent protein catabolic process | The chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of ubiquitin, with ubiquitin-protein ligation catalyzed by an SCF (Skp1/Cul1/F-box protein) complex, and mediated by the proteasome. |
6 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q8N4B4 | FBXO39 | F-box only protein 39 | Homo sapiens (Human) | PR |
| Q8N461 | FBXL16 | F-box/LRR-repeat protein 16 | Homo sapiens (Human) | PR |
| Q8BH70 | Fbxl4 | F-box/LRR-repeat protein 4 | Mus musculus (Mouse) | PR |
| Q8C4V4 | Fbxl3 | F-box/LRR-repeat protein 3 | Mus musculus (Mouse) | PR |
| Q9LTX2 | At5g49980 | Transport inhibitor response 1-like protein | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9ZR12 | GRH1 | GRR1-like protein 1 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MKRGGRDSDR | NSSEEGTAEK | SKKLRTTNEH | SQTCDWGNLL | QDIILQVFKY | LPLLDRAHAS |
| 70 | 80 | 90 | 100 | 110 | 120 |
| QVCRNWNQVF | HMPDLWRCFE | FELNQPATSY | LKATHPELIK | QIIKRHSNHL | QYVSFKVDSS |
| 130 | 140 | 150 | 160 | 170 | 180 |
| KESAEAACDI | LSQLVNCSLK | TLGLISTARP | SFMDLPKSHF | ISALTVVFVN | SKSLSSLKID |
| 190 | 200 | 210 | 220 | 230 | 240 |
| DTPVDDPSLK | VLVANNSDTL | KLLKMSSCPH | VSPAGILCVA | DQCHGLRELA | LNYHLLSDEL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| LLALSSEKHV | RLEHLRIDVV | SENPGQTHFH | TIQKSSWDAF | IRHSPKVNLV | MYFFLYEEEF |
| 310 | 320 | 330 | 340 | 350 | 360 |
| DPFFRYEIPA | THLYFGRSVS | KDVLGRVGMT | CPRLVELVVC | ANGLRPLDEE | LIRIAERCKN |
| 370 | 380 | 390 | 400 | 410 | 420 |
| LSAIGLGECE | VSCSAFVEFV | KMCGGRLSQL | SIMEEVLIPD | QKYSLEQIHW | EVSKHLGRVW |
| FPDMMPTW |