Q9UBV8
Gene name |
PEF1 |
Protein name |
Peflin |
Names |
PEF protein with a long N-terminal hydrophobic domain, Penta-EF hand domain-containing protein 1 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:553115 |
EC number |
|
Protein Class |
|
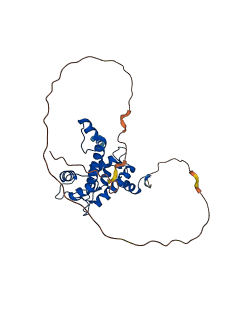
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9UBV8
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9UBV8-F1 | Predicted | AlphaFoldDB |
246 variants for Q9UBV8
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA339592541 rs1262928168 |
2 | A>T | No |
ClinGen gnomAD |
|
|
CA20192578 rs764113135 |
3 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs764113135 CA732460 |
3 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339592532 rs760759780 |
3 | S>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs764113135 CA732459 |
3 | S>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs767723197 CA339592529 |
4 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs140479455 CA732456 |
4 | Y>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs140479455 CA339592530 |
4 | Y>N | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA732455 rs767723197 |
4 | Y>S | No |
ClinGen ExAC gnomAD |
|
|
rs141265870 CA732453 |
5 | P>S | No |
ClinGen ESP ExAC gnomAD |
|
|
rs771358083 CA732452 |
6 | Y>* | No |
ClinGen ExAC gnomAD |
|
|
CA339592513 rs1454103643 |
7 | R>G | No |
ClinGen gnomAD |
|
|
CA732451 rs540821693 |
7 | R>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339592511 rs540821693 |
7 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339592512 rs1454103643 |
7 | R>W | No |
ClinGen gnomAD |
|
| TCGA novel | 8 | Q>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA732450 rs773868133 |
8 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
rs1306837647 CA339591914 |
11 | P>Q | No |
ClinGen gnomAD |
|
|
rs949458541 CA339591918 |
11 | P>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs949458541 CA20185570 |
11 | P>T | No |
ClinGen gnomAD |
|
|
rs867319495 CA20185562 |
12 | G>R | No |
ClinGen gnomAD |
|
|
rs1234874661 CA339591901 |
14 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
CA339591877 rs1295374474 |
17 | A>V | No |
ClinGen gnomAD |
|
|
CA339591871 rs1356394145 |
18 | P>L | No |
ClinGen gnomAD |
|
|
CA732428 rs768248106 |
19 | G>A | No |
ClinGen ExAC gnomAD |
|
|
rs1398738320 CA339591865 |
20 | A>T | No |
ClinGen gnomAD |
|
|
CA732425 rs202217061 COSM1341733 |
22 | P>L | large_intestine [Cosmic] | No |
ClinGen cosmic curated 1000Genomes ExAC TOPMed gnomAD |
|
rs771699009 CA732424 |
25 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs1475753291 CA339591826 |
26 | Y>H | No |
ClinGen gnomAD |
|
|
rs1417544737 CA339591819 |
27 | P>T | No |
ClinGen gnomAD |
|
|
rs1440283860 CA339591805 |
29 | P>S | No |
ClinGen gnomAD |
|
|
CA339591799 rs1398540135 |
30 | P>R | No |
ClinGen gnomAD |
|
|
rs142951278 CA339591800 |
30 | P>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs142951278 CA732421 |
30 | P>T | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA732419 rs781083110 |
31 | N>H | No |
ClinGen ExAC gnomAD |
|
|
rs368906197 CA732418 |
31 | N>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs763321866 CA732415 |
36 | Y>* | No |
ClinGen ExAC gnomAD |
|
|
CA339591759 rs1242953431 |
36 | Y>C | No |
ClinGen TOPMed gnomAD |
|
|
CA339591754 rs1192027286 |
37 | G>R | No |
ClinGen TOPMed |
|
|
rs1307845734 CA339591746 |
38 | S>N | No |
ClinGen gnomAD |
|
|
rs201449486 CA732413 |
40 | L>P | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA339591724 rs1475319446 |
42 | P>A | No |
ClinGen TOPMed gnomAD |
|
|
rs777221074 CA732411 |
42 | P>L | No |
ClinGen ExAC gnomAD |
|
|
rs375817960 CA732410 |
43 | G>A | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1223053516 CA339591720 |
43 | G>S | No |
ClinGen TOPMed |
|
|
CA732409 rs149013148 |
46 | Y>F | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA339591696 rs1365153595 |
47 | G>R | No |
ClinGen gnomAD |
|
|
rs1181970670 CA339591688 |
48 | G>C | No |
ClinGen gnomAD |
|
|
rs1438567452 CA339591687 |
48 | G>D | No |
ClinGen gnomAD |
|
| TCGA novel | 50 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA732404 COSM1341732 rs745569188 |
53 | G>R | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA |
|
CA20185429 rs952375748 |
54 | P>T | No |
ClinGen Ensembl |
|
|
rs369188697 CA732400 |
57 | P>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1239645955 CA339591633 |
57 | P>L | No |
ClinGen gnomAD |
|
|
CA732401 rs369188697 |
57 | P>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA20185416 rs11551772 |
58 | P>L | No |
ClinGen Ensembl |
|
|
rs1374773204 CA339591630 |
58 | P>S | No |
ClinGen gnomAD |
|
|
CA339591615 rs1305647778 |
61 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1402785884 CA339591591 |
64 | Y>* | No |
ClinGen gnomAD |
|
|
CA732398 rs756072857 |
64 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA20185380 rs965120879 |
66 | H>D | No |
ClinGen TOPMed |
|
| TCGA novel | 68 | N>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1386072034 CA339591569 |
68 | N>H | No |
ClinGen gnomAD |
|
|
CA732397 rs540510395 |
68 | N>S | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA339591563 rs1418651930 |
69 | P>A | No |
ClinGen gnomAD |
|
|
rs780044590 CA732396 |
73 | P>H | No |
ClinGen ExAC gnomAD |
|
|
rs780044590 CA20185357 |
73 | P>R | No |
ClinGen ExAC gnomAD |
|
|
rs141771149 CA732394 |
79 | G>E | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs757713580 CA732392 |
81 | Y>H | No |
ClinGen ExAC gnomAD |
|
|
CA339591483 rs1409767499 |
82 | G>S | No |
ClinGen TOPMed |
|
| TCGA novel | 82 | G>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA732389 COSM908165 rs761145394 |
83 | G>S | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs1344988932 CA339591472 |
84 | A>T | No |
ClinGen gnomAD |
|
|
CA20185262 rs201448518 |
84 | A>V | No |
ClinGen gnomAD |
|
|
rs767054971 CA339591464 |
85 | A>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs767054971 CA732387 |
85 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs149304800 CA339591462 |
86 | P>A | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs149304800 CA20185253 COSM3711316 |
86 | P>S | upper_aerodigestive_tract [Cosmic] | No |
ClinGen cosmic curated ESP TOPMed gnomAD |
|
CA732385 rs774005967 |
87 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs1000901823 CA20185226 |
88 | G>D | No |
ClinGen Ensembl |
|
|
CA732384 rs145077126 |
90 | Y>C | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs749103112 CA20185218 |
92 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1203493522 CA339591425 |
92 | Q>P | No |
ClinGen TOPMed |
|
|
rs772934269 CA732382 |
93 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA20185212 rs200144237 |
94 | P>S | No |
ClinGen 1000Genomes TOPMed |
|
|
rs200144237 CA339591415 |
94 | P>T | No |
ClinGen 1000Genomes TOPMed |
|
|
rs1014100052 CA20185194 |
96 | S>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1302766166 CA339591401 |
96 | S>N | No |
ClinGen TOPMed |
|
|
CA339591398 rs1447617728 |
97 | S>T | No |
ClinGen TOPMed |
|
|
rs748072690 CA732380 |
98 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
CA339591391 rs1307641250 |
98 | Y>H | No |
ClinGen gnomAD |
|
|
rs1487455960 CA339591385 |
99 | G>S | No |
ClinGen gnomAD |
|
|
rs746034322 CA732377 |
102 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
CA732376 rs779283966 |
104 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs374031460 CA732375 |
105 | L>F | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA339591328 rs374031460 |
105 | L>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs370676228 CA20185153 |
105 | L>R | No |
ClinGen ESP TOPMed |
|
|
rs779582221 CA732348 |
109 | G>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs557572685 CA732347 |
110 | G>S | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1379827108 CA339591103 |
110 | G>V | No |
ClinGen gnomAD |
|
|
CA339591102 rs140595911 |
111 | A>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA732346 rs140595911 |
111 | A>T | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA732345 rs750063064 |
112 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs765028173 CA732343 |
114 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs761519578 CA732342 |
115 | V>A | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 116 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA732340 rs749930655 |
120 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA732339 rs760744671 |
121 | S>P | No |
ClinGen ExAC gnomAD |
|
|
CA732337 rs774542516 |
122 | W>C | No |
ClinGen ExAC gnomAD |
|
|
rs770948880 CA732336 |
124 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339590967 rs1365240115 |
124 | Q>K | No |
ClinGen gnomAD |
|
|
CA339590949 rs1400913518 |
125 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
CA339590948 rs1296477248 |
126 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
CA20183872 rs1031650486 |
127 | D>N | No |
ClinGen TOPMed |
|
|
CA732334 rs777861045 |
131 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs770119323 CA732333 |
132 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA339590858 rs1422171269 |
133 | Y>* | No |
ClinGen gnomAD |
|
|
CA732331 rs781584359 |
133 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
CA20183830 rs998800886 |
136 | M>I | No |
ClinGen TOPMed |
|
|
rs752087793 CA732329 |
136 | M>T | No |
ClinGen ExAC gnomAD |
|
|
rs1488439627 CA339590831 |
136 | M>V | No |
ClinGen gnomAD |
|
|
rs757856977 CA732327 |
138 | E>D | No |
ClinGen ExAC gnomAD |
|
|
CA20183804 rs1043312412 |
140 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
CA339590777 rs1245303517 |
142 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
rs750028128 CA732326 |
145 | N>D | No |
ClinGen ExAC gnomAD |
|
|
rs1310364579 CA339590755 |
146 | C>R | No |
ClinGen gnomAD |
|
|
rs1047852178 CA20183787 |
147 | N>H | No |
ClinGen Ensembl |
|
|
rs143340788 CA732325 |
147 | N>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA339590736 rs1218990837 |
148 | W>* | No |
ClinGen TOPMed gnomAD |
|
|
CA20183774 rs757232708 |
148 | W>S | No |
ClinGen Ensembl |
|
|
rs1339544502 CA339590717 |
151 | F>S | No |
ClinGen gnomAD |
|
|
CA339590707 CA339590708 rs1416786604 |
152 | N>K | No |
ClinGen gnomAD |
|
|
CA20183773 rs373796290 |
152 | N>S | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs756996122 CA339590699 |
153 | D>E | No |
ClinGen ExAC gnomAD |
|
|
rs1302324356 CA339590687 |
155 | T>N | No |
ClinGen gnomAD |
|
|
rs1570270271 CA339590689 |
155 | T>P | No |
ClinGen Ensembl |
|
|
CA339590674 rs1356760970 |
157 | L>F | No |
ClinGen gnomAD |
|
|
CA339590671 rs1215298204 |
157 | L>R | No |
ClinGen TOPMed |
|
|
CA732322 rs753666924 |
158 | M>T | No |
ClinGen ExAC |
|
|
CA339590649 rs1477715410 |
160 | I>T | No |
ClinGen gnomAD |
|
| TCGA novel | 161 | N>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA339590620 rs1265113837 |
162 | M>I | No |
ClinGen gnomAD |
|
|
CA339590622 rs1557584621 |
162 | M>T | No |
ClinGen Ensembl |
|
|
CA339590626 rs1234886671 |
162 | M>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1242793392 CA339590605 |
164 | D>G | No |
ClinGen TOPMed gnomAD |
|
|
CA339590600 rs1487926990 |
165 | K>E | No |
ClinGen TOPMed |
|
|
rs763935107 CA339590570 |
169 | G>A | No |
ClinGen ExAC gnomAD |
|
|
CA732304 rs763935107 |
169 | G>D | No |
ClinGen ExAC gnomAD |
|
|
rs1375287373 CA339590566 |
170 | R>C | No |
ClinGen gnomAD |
|
|
rs147722531 CA732303 COSM314085 |
170 | R>H | lung [Cosmic] | No |
ClinGen cosmic curated 1000Genomes ESP ExAC TOPMed gnomAD |
|
rs752605388 CA732302 |
171 | I>F | No |
ClinGen ExAC gnomAD |
|
|
rs752605388 CA339590562 |
171 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA732299 rs773134257 |
172 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA732300 rs759567297 COSM3419112 |
172 | D>N | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs765386131 CA732298 |
174 | Y>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA732296 rs776849452 |
175 | G>S | No |
ClinGen ExAC |
|
|
rs1570268797 CA339590511 |
179 | L>P | No |
ClinGen Ensembl |
|
|
rs1266334678 CA339590499 |
181 | K>E | No |
ClinGen gnomAD |
|
|
CA732292 rs772440392 |
181 | K>N | No |
ClinGen ExAC gnomAD |
|
|
CA732291 rs146809023 |
182 | F>C | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs369403984 CA20183268 |
183 | I>V | No |
ClinGen ESP TOPMed |
|
|
CA339590478 rs1557584492 |
184 | Q>E | No |
ClinGen Ensembl |
|
|
CA732290 rs778246626 |
184 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
rs1277153576 CA339590466 |
185 | Q>H | No |
ClinGen gnomAD |
|
|
rs1351537862 CA339590467 |
185 | Q>L | No |
ClinGen gnomAD |
|
|
rs756851161 CA732289 |
186 | W>R | No |
ClinGen ExAC gnomAD |
|
|
rs1330901786 CA339590444 |
188 | N>S | No |
ClinGen gnomAD |
|
|
CA339590424 rs1384790829 |
191 | Q>* | No |
ClinGen gnomAD |
|
|
rs755887392 CA732286 |
192 | Q>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs781079521 CA732285 |
195 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA732283 rs140422275 |
195 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA732284 rs781079521 |
195 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA732282 rs751533337 |
197 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1196441365 CA339590382 |
197 | R>H | No |
ClinGen TOPMed gnomAD |
|
|
CA732281 rs765240041 |
198 | S>L | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 200 | S>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA732280 rs144874149 |
201 | I>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA20183139 rs887273963 |
208 | Q>E | No |
ClinGen TOPMed |
|
|
CA339589909 rs201297417 |
211 | S>C | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA732227 rs201297417 |
211 | S>F | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ExAC NCI-TCGA TOPMed gnomAD |
|
CA339589902 rs985013441 |
212 | Q>H | No |
ClinGen TOPMed |
|
|
rs374586693 CA339589905 |
212 | Q>P | No |
ClinGen gnomAD |
|
|
rs374586693 CA20182155 |
212 | Q>R | No |
ClinGen gnomAD |
|
|
CA339589889 rs1199000368 |
214 | G>A | No |
ClinGen TOPMed |
|
|
rs1426398480 CA339589886 |
215 | Y>H | No |
ClinGen gnomAD |
|
|
rs778826617 CA732226 |
216 | N>K | No |
ClinGen ExAC gnomAD |
|
|
rs1190948123 CA339589874 |
216 | N>S | No |
ClinGen gnomAD |
|
|
rs953350614 CA20182143 |
218 | S>G | No |
ClinGen Ensembl |
|
| TCGA novel | 222 | T>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1488337185 CA339589829 |
222 | T>I | No |
ClinGen gnomAD |
|
|
CA339589836 rs1570264867 |
222 | T>P | No |
ClinGen Ensembl |
|
|
rs1203030784 CA339589811 |
224 | L>V | No |
ClinGen TOPMed |
|
|
CA339589777 rs1213633075 |
227 | S>F | No |
ClinGen gnomAD |
|
|
rs1313849281 CA339589771 |
228 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs139896724 CA732223 |
228 | R>H | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1221334939 CA339589758 |
229 | Y>S | No |
ClinGen TOPMed |
|
|
rs1218449835 CA339589750 |
230 | C>S | No |
ClinGen gnomAD |
|
|
CA20182115 rs547542586 |
230 | C>Y | No |
ClinGen gnomAD |
|
|
rs1280341427 CA339589735 |
231 | P>A | No |
ClinGen gnomAD |
|
|
rs1280341427 CA339589733 |
231 | P>S | No |
ClinGen gnomAD |
|
|
rs755186565 CA732222 |
232 | R>C | No |
ClinGen ExAC gnomAD |
|
|
rs371830019 CA732221 |
232 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1287186849 CA339589708 |
233 | S>F | No |
ClinGen gnomAD |
|
|
rs1228639770 CA339589717 |
233 | S>P | No |
ClinGen TOPMed |
|
|
rs866571271 CA20182098 |
234 | A>T | No |
ClinGen Ensembl |
|
|
rs758834965 CA732219 |
235 | N>S | No |
ClinGen ExAC gnomAD |
|
|
rs569702331 CA20182085 |
237 | A>P | No |
ClinGen 1000Genomes |
|
|
rs1468602435 CA339589662 |
238 | M>T | No |
ClinGen gnomAD |
|
|
CA732218 rs549808725 |
238 | M>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA732217 rs765758652 |
240 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs780909453 CA732216 |
241 | D>H | No |
ClinGen ExAC gnomAD |
|
|
CA732215 rs776178785 |
242 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs763547860 CA732214 |
242 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs1019932391 CA20182059 |
243 | F>L | No |
ClinGen TOPMed gnomAD |
|
|
CA339589593 rs1557583019 |
245 | Q>R | No |
ClinGen Ensembl |
|
|
CA339589567 rs1256547111 |
247 | C>* | No |
ClinGen TOPMed gnomAD |
|
|
rs1209253535 CA339589555 |
248 | T>I | No |
ClinGen gnomAD |
|
|
CA339589558 rs1209253535 |
248 | T>N | No |
ClinGen gnomAD |
|
|
CA339589546 rs1227258375 |
249 | Q>P | No |
ClinGen gnomAD |
|
|
CA339589517 rs1321169406 |
252 | V>L | No |
ClinGen gnomAD |
|
|
rs760275627 CA732212 |
254 | T>R | No |
ClinGen ExAC gnomAD |
|
|
rs1570264402 CA339589474 |
256 | A>S | No |
ClinGen Ensembl |
|
|
rs146006007 CA339589453 |
258 | R>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs146006007 CA732210 |
258 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs775137790 CA732211 |
258 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA732209 rs745659069 |
259 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA732208 rs774191997 |
260 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs1175892699 CA339589408 |
262 | T>A | No |
ClinGen TOPMed |
|
|
CA20181981 rs539499336 |
263 | A>S | No |
ClinGen 1000Genomes |
|
|
CA732206 rs749213335 |
264 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA732207 rs749213335 |
264 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs781284157 CA732205 |
265 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
CA339589365 rs1443527794 |
266 | G>D | No |
ClinGen gnomAD |
|
|
CA732204 rs768631094 |
267 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339589333 rs1238516900 |
269 | R>Q | No |
ClinGen TOPMed |
|
|
CA339589335 rs1465872048 |
269 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA20181956 rs922785030 |
273 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA339589268 rs1182964415 |
276 | V>A | No |
ClinGen gnomAD |
|
|
CA732199 rs779189008 |
276 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs757745336 CA732198 |
277 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339589255 CA732196 rs763606589 |
278 | M>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs754327994 CA732197 |
278 | M>V | No |
ClinGen ExAC gnomAD |
|
|
CA732195 rs760183446 |
279 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339589247 rs760183446 |
279 | T>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1247207063 CA339589220 |
282 | R>Q | No |
ClinGen gnomAD |
|
|
rs937496556 COSM908160 CA20181929 |
282 | R>W | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
No associated diseases with Q9UBV8
Functions
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| COPII vesicle coat | One of two multimeric complexes that forms a membrane vesicle coat. COPII is best characterized in S. cerevisiae, where the subunits are called Sar1p, Sec13p, Sec31p, Sec23p, and Sec24p. Vesicles with COPII coats are found associated with endoplasmic reticulum (ER) membranes at steady state. |
| Cul3-RING ubiquitin ligase complex | A ubiquitin ligase complex in which a cullin from the Cul3 subfamily and a RING domain protein form the catalytic core; substrate specificity is conferred by a BTB-domain-containing protein. |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| endoplasmic reticulum | The irregular network of unit membranes, visible only by electron microscopy, that occurs in the cytoplasm of many eukaryotic cells. The membranes form a complex meshwork of tubular channels, which are often expanded into slitlike cavities called cisternae. The ER takes two forms, rough (or granular), with ribosomes adhering to the outer surface, and smooth (with no ribosomes attached). |
| extracellular exosome | A vesicle that is released into the extracellular region by fusion of the limiting endosomal membrane of a multivesicular body with the plasma membrane. Extracellular exosomes, also simply called exosomes, have a diameter of about 40-100 nm. |
7 GO annotations of molecular function
| Name | Definition |
|---|---|
| calcium ion binding | Binding to a calcium ion (Ca2+). |
| calcium-dependent protein binding | Binding to a protein or protein complex in the presence of calcium. |
| identical protein binding | Binding to an identical protein or proteins. |
| protein dimerization activity | The formation of a protein dimer, a macromolecular structure consists of two noncovalently associated identical or nonidentical subunits. |
| protein heterodimerization activity | Binding to a nonidentical protein to form a heterodimer. |
| RNA binding | Binding to an RNA molecule or a portion thereof. |
| ubiquitin ligase-substrate adaptor activity | The binding activity of a molecule that brings together a ubiquitin ligase and its substrate. Usually mediated by F-box BTB/POZ domain proteins. |
6 GO annotations of biological process
| Name | Definition |
|---|---|
| COPII vesicle coating | The addition of COPII proteins and adaptor proteins to ER membranes during the formation of transport vesicles, forming a vesicle coat. |
| endoplasmic reticulum to Golgi vesicle-mediated transport | The directed movement of substances from the endoplasmic reticulum (ER) to the Golgi, mediated by COP II vesicles. Small COP II coated vesicles form from the ER and then fuse directly with the cis-Golgi. Larger structures are transported along microtubules to the cis-Golgi. |
| neural crest cell development | The process aimed at the progression of a neural crest cell over time, from initial commitment of the cell to its specific fate, to the fully functional differentiated cell. |
| neural crest formation | The formation of the specialized region of ectoderm between the neural ectoderm (neural plate) and non-neural ectoderm. The neural crest gives rise to the neural crest cells that migrate away from this region as neural tube formation procedes. |
| positive regulation of protein monoubiquitination | Any process that activates or increases the frequency, rate or extent of protein monoubiquitination. |
| response to calcium ion | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a calcium ion stimulus. |
6 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q6MZZ7 | CAPN13 | Calpain-13 | Homo sapiens (Human) | PR |
| P28676 | GCA | Grancalcin | Homo sapiens (Human) | PR |
| Q3UW68 | Capn13 | Calpain-13 | Mus musculus (Mouse) | PR |
| Q8BFY6 | Pef1 | Peflin | Mus musculus (Mouse) | PR |
| Q5BK10 | Capn13 | Calpain-13 | Rattus norvegicus (Rat) | PR |
| Q641Z8 | Pef1 | Peflin | Rattus norvegicus (Rat) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MASYPYRQGC | PGAAGQAPGA | PPGSYYPGPP | NSGGQYGSGL | PPGGGYGGPA | PGGPYGPPAG |
| 70 | 80 | 90 | 100 | 110 | 120 |
| GGPYGHPNPG | MFPSGTPGGP | YGGAAPGGPY | GQPPPSSYGA | QQPGLYGQGG | APPNVDPEAY |
| 130 | 140 | 150 | 160 | 170 | 180 |
| SWFQSVDSDH | SGYISMKELK | QALVNCNWSS | FNDETCLMMI | NMFDKTKSGR | IDVYGFSALW |
| 190 | 200 | 210 | 220 | 230 | 240 |
| KFIQQWKNLF | QQYDRDRSGS | ISYTELQQAL | SQMGYNLSPQ | FTQLLVSRYC | PRSANPAMQL |
| 250 | 260 | 270 | 280 | ||
| DRFIQVCTQL | QVLTEAFREK | DTAVQGNIRL | SFEDFVTMTA | SRML |