Q9LVP1
Gene name |
TOP3A (At5g63920, MGI19.16) |
Protein name |
DNA topoisomerase 3-alpha |
Names |
|
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT5G63920 |
EC number |
5.6.2.1: Enzymes altering nucleic acid conformation |
Protein Class |
|
Descriptions
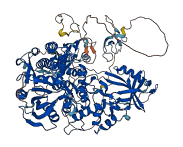
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9LVP1
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9LVP1-F1 | Predicted | AlphaFoldDB |
56 variants for Q9LVP1
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH03471727 | 30 | R>C | No | 1000Genomes | |
| tmp_5_25574632_C_T | 34 | R>W | No | 1000Genomes | |
| tmp_5_25574677_G_C | 49 | D>H | No | 1000Genomes | |
| tmp_5_25574713_A_G | 61 | M>V | No | 1000Genomes | |
| ENSVATH07475119 | 69 | M>L | No | 1000Genomes | |
| ENSVATH07475120 | 69 | M>T | No | 1000Genomes | |
| tmp_5_25574756_A_G | 75 | D>G | No | 1000Genomes | |
| ENSVATH12922261 | 79 | K>N | No | 1000Genomes | |
| ENSVATH03471736 | 114 | K>E | No | 1000Genomes | |
| ENSVATH07475135 | 210 | T>M | No | 1000Genomes | |
| tmp_5_25575602_G_T | 213 | E>D | No | 1000Genomes | |
| tmp_5_25575607_G_C | 215 | S>T | No | 1000Genomes | |
| ENSVATH07475138 | 234 | R>Q | No | 1000Genomes | |
| ENSVATH00750163 | 268 | H>N | No | 1000Genomes | |
| ENSVATH07475144 | 284 | E>K | No | 1000Genomes | |
| ENSVATH07475145 | 287 | T>A | No | 1000Genomes | |
| tmp_5_25576154_A_C | 305 | Y>S | No | 1000Genomes | |
| tmp_5_25576455_C_T | 343 | P>S | No | 1000Genomes | |
| ENSVATH14647317 | 355 | D>Y | No | 1000Genomes | |
| ENSVATH07475154 | 367 | P>S | No | 1000Genomes | |
| tmp_5_25576672_G_A | 385 | R>K | No | 1000Genomes | |
| tmp_5_25576757_C_A | 413 | S>R | No | 1000Genomes | |
| ENSVATH12922296 | 480 | Y>F | No | 1000Genomes | |
| ENSVATH00750181 | 495 | A>E | No | 1000Genomes | |
| tmp_5_25578025_A_G | 533 | D>G | No | 1000Genomes | |
| ENSVATH00750183 | 546 | S>C | No | 1000Genomes | |
| ENSVATH07475186 | 632 | S>N | No | 1000Genomes | |
| tmp_5_25579433_A_T | 650 | M>L | No | 1000Genomes | |
| ENSVATH07475192 | 683 | A>T | No | 1000Genomes | |
| ENSVATH00750193 | 685 | V>I | No | 1000Genomes | |
| ENSVATH00750194 | 692 | S>P | No | 1000Genomes | |
| tmp_5_25580040_C_G | 718 | H>Q | No | 1000Genomes | |
| ENSVATH07475206 | 760 | N>D | No | 1000Genomes | |
| tmp_5_25580477_G_A | 762 | R>K | No | 1000Genomes | |
| tmp_5_25580497_C_G | 769 | H>D | No | 1000Genomes | |
| tmp_5_25580510_G_A | 773 | R>Q | No | 1000Genomes | |
| ENSVATH07475207 | 776 | A>V | No | 1000Genomes | |
| ENSVATH03471824 | 778 | T>A | No | 1000Genomes | |
| ENSVATH00750197 | 786 | A>T | No | 1000Genomes | |
| ENSVATH03471826 | 788 | R>Q | No | 1000Genomes | |
| tmp_5_25580563_C_T | 791 | R>C | No | 1000Genomes | |
| ENSVATH03471827 | 795 | T>S | No | 1000Genomes | |
| tmp_5_25580755_A_T | 803 | T>S | No | 1000Genomes | |
| ENSVATH07475209 | 808 | T>I | No | 1000Genomes | |
| ENSVATH07475209 | 808 | T>S | No | 1000Genomes | |
| ENSVATH14647323 | 832 | P>S | No | 1000Genomes | |
| tmp_5_25580866_G_T | 840 | A>S | No | 1000Genomes | |
| tmp_5_25580997_G_T | 850 | G>W | No | 1000Genomes | |
| ENSVATH03471837 | 859 | G>S | No | 1000Genomes | |
| ENSVATH03471838 | 863 | R>G | No | 1000Genomes | |
| ENSVATH00750198 | 875 | G>S | No | 1000Genomes | |
| ENSVATH07475211 | 882 | R>Q | No | 1000Genomes | |
| tmp_5_25581188_C_A | 913 | N>K | No | 1000Genomes | |
| tmp_5_25581193_G_C | 915 | C>S | No | 1000Genomes | |
| ENSVATH12922360 | 918 | R>C | No | 1000Genomes | |
| ENSVATH03471839 | 920 | N>T | No | 1000Genomes |
No associated diseases with Q9LVP1
1 regional properties for Q9LVP1
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Sugar phosphate transporter domain | 25 - 299 | IPR004853 |
Functions
| Description | ||
|---|---|---|
| EC Number | 5.6.2.1 | Enzymes altering nucleic acid conformation |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
2 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromosome | A structure composed of a very long molecule of DNA and associated proteins (e.g. histones) that carries hereditary information. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
4 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| DNA topoisomerase activity | Catalysis of the transient cleavage and passage of individual DNA strands or double helices through one another, resulting a topological transformation in double-stranded DNA. |
| DNA topoisomerase type I (single strand cut, ATP-independent) activity | Catalysis of a DNA topological transformation by transiently cleaving one DNA strand at a time to allow passage of another strand; changes the linking number by +1 per catalytic cycle. |
| zinc ion binding | Binding to a zinc ion (Zn). |
6 GO annotations of biological process
| Name | Definition |
|---|---|
| chromosome segregation | The process in which genetic material, in the form of chromosomes, is organized into specific structures and then physically separated and apportioned to two or more sets. In eukaryotes, chromosome segregation begins with the condensation of chromosomes, includes chromosome separation, and ends when chromosomes have completed movement to the spindle poles. |
| DNA repair | The process of restoring DNA after damage. Genomes are subject to damage by chemical and physical agents in the environment (e.g. UV and ionizing radiations, chemical mutagens, fungal and bacterial toxins, etc.) and by free radicals or alkylating agents endogenously generated in metabolism. DNA is also damaged because of errors during its replication. A variety of different DNA repair pathways have been reported that include direct reversal, base excision repair, nucleotide excision repair, photoreactivation, bypass, double-strand break repair pathway, and mismatch repair pathway. |
| DNA topological change | The process in which a transformation is induced in the topological structure of a double-stranded DNA helix, resulting in a change in linking number. |
| meiotic cell cycle | Progression through the phases of the meiotic cell cycle, in which canonically a cell replicates to produce four offspring with half the chromosomal content of the progenitor cell via two nuclear divisions. |
| mitotic cell cycle | Progression through the phases of the mitotic cell cycle, the most common eukaryotic cell cycle, which canonically comprises four successive phases called G1, S, G2, and M and includes replication of the genome and the subsequent segregation of chromosomes into daughter cells. In some variant cell cycles nuclear replication or nuclear division may not be followed by cell division, or G1 and G2 phases may be absent. |
| resolution of meiotic recombination intermediates | The cleavage and rejoining of intermediates, such as Holliday junctions, formed during meiotic recombination to produce two intact molecules in which genetic material has been exchanged. |
5 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P13099 | TOP3 | DNA topoisomerase 3 | Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) | PR |
| Q13472 | TOP3A | DNA topoisomerase 3-alpha | Homo sapiens (Human) | PR |
| O70157 | Top3a | DNA topoisomerase 3-alpha | Mus musculus (Mouse) | PR |
| C7J0A2 | TOP3A | DNA topoisomerase 3-alpha | Oryza sativa subsp japonica (Rice) | PR |
| F4ISQ7 | At2g32000 | DNA topoisomerase 3-beta | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSRRGGGPVT | VLNVAEKPSV | AKSVAGILSR | GTFRTREGRS | RYNKIFEFDY | AINGQPCRML |
| 70 | 80 | 90 | 100 | 110 | 120 |
| MTSVIGHLME | LEFADRYRKW | HSCDPADLYQ | APVMKHVPED | KKDIKKTLEE | EARKSDWLVL |
| 130 | 140 | 150 | 160 | 170 | 180 |
| WLDCDREGEN | IAFEVVDVCR | AVKHNLFIRR | AHFSALIDRD | IHEAVQNLRD | PNQLFAEAVD |
| 190 | 200 | 210 | 220 | 230 | 240 |
| ARQEIDLRIG | ASFTRFQTML | LRDRFAIDST | GEERSRVISY | GPCQFPTLGF | IVERYWEIQA |
| 250 | 260 | 270 | 280 | 290 | 300 |
| HEPEEFWTIN | CSHQSEEGLA | TFNWMRGHLF | DYASAVILYE | MCVEEPTATV | MNVPHPRERF |
| 310 | 320 | 330 | 340 | 350 | 360 |
| KYPPYPLNTI | ELEKRASRYF | RLSSEHTMKV | AEELYQAGFI | SYPRTETDSF | SSRTDLRAMV |
| 370 | 380 | 390 | 400 | 410 | 420 |
| EEQTRHPAWG | SYAQRLLEPE | GGLWRNPANG | GHDDKAHPPI | HPTKFSSGES | NWSRDHLNVY |
| 430 | 440 | 450 | 460 | 470 | 480 |
| ELVVRHYLAC | VSQPAVAAET | TVEIDIAGER | FSASGRAILA | KNYLEVYRFE | SWGGSVIPVY |
| 490 | 500 | 510 | 520 | 530 | 540 |
| EKGQQFIPTT | LTLDAAVTRP | PPLLCEADLL | SCMDKAGIGT | DATMHDHIKK | LLDRGYATKD |
| 550 | 560 | 570 | 580 | 590 | 600 |
| ANTRFSPTNL | GEALVMGYDD | MGYELWKPNL | RALMEHDMNE | VSVGRKTKAE | VLETCLQQMK |
| 610 | 620 | 630 | 640 | 650 | 660 |
| ACFLDARVKK | SKLLEAMTIF | FERSNNTDES | ESQTAGEVVR | RCNLCNESDM | ALRKNRDGNF |
| 670 | 680 | 690 | 700 | 710 | 720 |
| MVGCMNYPQC | RNAVWLPGPT | LEASVTTNVC | QSCGPGPVYK | ILFKFRQIGI | PPGFDVNHLG |
| 730 | 740 | 750 | 760 | 770 | 780 |
| CVGGCDDILK | QLIDICGTGS | RSQARRTPGT | APSNNIQGSN | TRQSNVCIHC | QQRGHASTNC |
| 790 | 800 | 810 | 820 | 830 | 840 |
| PSRVPASRNS | RPTATNPRND | ESTVSCNTCG | SQCVLRTANT | EANRGRQFFS | CPTQGCSFFA |
| 850 | 860 | 870 | 880 | 890 | 900 |
| WEDSINNSSG | NATTGSNSGG | SGRRGSRGRG | RGGRGGQSSG | GRRGSGTSFV | SATGEPVSGI |
| 910 | 920 | ||||
| RCFSCGDPSH | FANACPNRNN | SNGNYF |