Q9H5X1
Gene name |
CIAO2A |
Protein name |
Cytosolic iron-sulfur assembly component 2A |
Names |
MIP18 family protein FAM96A |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:84191 |
EC number |
|
Protein Class |
|
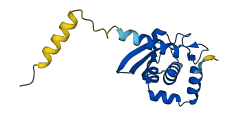
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
4 structures for Q9H5X1
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 2M5H | NMR | - | A | 28-160 | PDB |
| 3UX2 | X-ray | 180 A | A | 31-157 | PDB |
| 3UX3 | X-ray | 180 A | A/B | 31-157 | PDB |
| AF-Q9H5X1-F1 | Predicted | AlphaFoldDB |
136 variants for Q9H5X1
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs200860299 CA7607512 |
2 | Q>* | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA7607511 rs767557369 |
2 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
rs200860299 CA392813735 |
2 | Q>K | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1465166470 CA392813727 |
2 | Q>R | No |
ClinGen TOPMed |
|
|
rs969052158 CA272159612 |
3 | R>P | No |
ClinGen TOPMed gnomAD |
|
|
rs1200894779 CA392813694 |
5 | S>F | No |
ClinGen gnomAD |
|
|
rs1426842855 CA392813689 |
6 | G>R | No |
ClinGen TOPMed |
|
|
rs1322707426 CA392813683 |
6 | G>V | No |
ClinGen gnomAD |
|
|
rs1348967480 CA392813677 |
7 | L>R | No |
ClinGen gnomAD |
|
|
rs1053384259 CA272159594 |
7 | L>V | No |
ClinGen TOPMed gnomAD |
|
|
rs763370623 CA7607507 |
8 | L>P | No |
ClinGen ExAC gnomAD |
|
|
rs1311786888 CA392813656 |
9 | S>F | No |
ClinGen gnomAD |
|
|
rs527305764 CA7607505 |
10 | W>G | No |
ClinGen ExAC TOPMed |
|
|
rs527305764 CA7607504 |
10 | W>R | No |
ClinGen ExAC TOPMed |
|
|
CA272159568 rs148627319 |
11 | T>M | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs143270896 CA7607502 |
11 | T>S | No |
ClinGen ESP ExAC gnomAD |
|
|
CA7607500 rs745787463 |
12 | L>P | No |
ClinGen ExAC gnomAD |
|
|
rs774316860 CA7607499 |
13 | S>N | No |
ClinGen ExAC gnomAD |
|
|
CA7607498 rs770872832 |
14 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7607496 rs373353175 |
16 | L>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs373353175 CA7607497 |
16 | L>R | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1030800323 CA272159495 |
17 | W>* | No |
ClinGen TOPMed |
|
|
rs748375266 CA7607494 |
17 | W>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs748375266 CA7607495 |
17 | W>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA392813561 rs1262092239 |
20 | G>D | No |
ClinGen TOPMed |
|
|
rs1329648887 CA392813553 |
21 | L>R | No |
ClinGen TOPMed |
|
|
rs149870193 CA7607492 |
22 | S>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7607491 rs751720680 |
23 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs1268202557 CA392813512 |
26 | A>V | No |
ClinGen TOPMed |
|
|
rs1483150540 CA392813495 |
27 | A>V | No |
ClinGen gnomAD |
|
|
CA392813493 rs1174584365 |
28 | R>G | No |
ClinGen TOPMed |
|
|
CA272159469 rs758987507 |
28 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs758987507 CA7607489 |
28 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7607487 rs765589024 |
30 | P>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7607488 rs765589024 |
30 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA392813465 rs1324364725 |
30 | P>S | No |
ClinGen gnomAD |
|
|
rs1328091704 CA392813416 |
34 | E>Q | No |
ClinGen gnomAD |
|
|
rs1343801507 CA392813391 |
35 | E>G | No |
ClinGen TOPMed |
|
|
rs1296260087 CA392813379 |
36 | K>E | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 36 | K>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA392813362 rs1395218698 |
37 | A>V | No |
ClinGen gnomAD |
|
|
rs1567310873 CA392813353 |
38 | L>P | No |
ClinGen Ensembl |
|
|
CA392813333 CA392813334 rs332259 |
39 | E>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs960443007 CA272159446 |
40 | V>I | No |
ClinGen Ensembl |
|
|
CA392812186 rs1567308602 |
43 | L>S | No |
ClinGen Ensembl |
|
|
rs761466140 CA7607458 |
46 | T>S | No |
ClinGen ExAC gnomAD |
|
|
rs776499715 CA7607457 |
47 | I>L | No |
ClinGen ExAC gnomAD |
|
|
rs747303027 CA7607455 |
48 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs147426625 CA7607456 |
48 | R>W | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs772329697 CA7607453 |
54 | N>H | No |
ClinGen ExAC gnomAD |
|
|
CA392811940 rs1264277587 |
54 | N>S | No |
ClinGen TOPMed gnomAD |
|
|
rs142829471 CA7607452 |
55 | T>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7607451 rs779252477 |
56 | L>S | No |
ClinGen ExAC gnomAD |
|
|
rs1487739917 CA392811912 |
56 | L>V | No |
ClinGen TOPMed gnomAD |
|
|
rs757810258 CA7607450 |
61 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA7607448 rs778174210 |
63 | S>L | No |
ClinGen ExAC gnomAD |
|
|
rs1408947075 CA392811782 |
64 | E>K | No |
ClinGen gnomAD |
|
|
CA392811762 rs751259047 |
65 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7607446 rs751259047 |
65 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7607445 rs765841610 |
65 | S>I | No |
ClinGen ExAC gnomAD |
|
|
rs757805784 CA7607444 |
67 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs749970749 CA392811696 |
69 | V>F | No |
ClinGen ExAC gnomAD |
|
|
rs749970749 CA7607443 |
69 | V>I | No |
ClinGen ExAC gnomAD |
|
|
rs1377606064 CA392811677 |
70 | Q>R | No |
ClinGen TOPMed |
|
|
rs765026006 CA7607442 |
71 | E>V | No |
ClinGen ExAC gnomAD |
|
|
rs761815245 CA7607441 |
72 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs1027228149 CA272155050 |
73 | N>S | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 79 | V>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1292787403 CA392811475 |
80 | I>T | No |
ClinGen TOPMed |
|
|
CA7607435 rs745890561 |
80 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs369101440 CA7607433 |
81 | I>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs749860603 CA7607432 |
84 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs756509353 CA7607430 |
85 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7607429 rs748542366 |
86 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA392811355 rs1177177067 |
88 | P>S | No |
ClinGen gnomAD |
|
|
CA392811359 rs1177177067 |
88 | P>T | No |
ClinGen gnomAD |
|
|
rs953817117 CA272154942 |
89 | H>P | No |
ClinGen Ensembl |
|
|
rs1242699131 CA392811252 |
93 | A>G | No |
ClinGen TOPMed |
|
|
CA7607426 rs1242699131 |
93 | A>V | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
CA7607425 rs758082475 |
94 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA392811240 rs758082475 |
94 | T>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs770318592 CA7607410 |
100 | L>* | No |
ClinGen ExAC gnomAD |
|
|
rs1461536331 CA392810415 |
104 | L>R | No |
ClinGen gnomAD |
|
|
rs1174593273 CA392810410 |
105 | Q>R | No |
ClinGen gnomAD |
|
|
CA272148702 COSM193588 rs1056284662 |
106 | R>* | Variant assessed as Somatic; 0.0 impact. large_intestine endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
CA7607408 rs756598125 |
106 | R>P | No |
ClinGen ExAC gnomAD |
|
|
CA272148696 rs756598125 |
106 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs1384559130 CA392810403 |
107 | C>R | No |
ClinGen gnomAD |
|
|
CA7607407 rs371297121 |
109 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA272148692 rs1002970833 |
109 | P>S | No |
ClinGen TOPMed |
|
|
CA392810365 rs778254377 |
112 | H>L | No |
ClinGen ExAC gnomAD |
|
|
rs778254377 CA7607405 |
112 | H>P | No |
ClinGen ExAC gnomAD |
|
|
rs778254377 CA392810366 |
112 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs1424826207 CA392810358 |
113 | K>T | No |
ClinGen gnomAD |
|
|
rs1400474503 CA392809733 |
114 | L>V | No |
ClinGen TOPMed |
|
|
rs1238811900 CA392809662 |
117 | Y>C | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 117 | Y>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 121 | G>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1278664348 CA392809602 |
121 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1309475651 CA392809596 |
122 | T>A | No |
ClinGen gnomAD |
|
|
rs777431269 CA7607377 |
123 | H>D | No |
ClinGen ExAC gnomAD |
|
|
CA392809587 rs1301211022 |
123 | H>R | No |
ClinGen gnomAD |
|
|
rs1406620922 CA392809571 |
124 | S>* | No |
ClinGen gnomAD |
|
|
CA392809557 rs1595951130 |
126 | E>Q | No |
ClinGen Ensembl |
|
|
rs1391377809 CA392809513 |
128 | D>N | No |
ClinGen gnomAD |
|
|
CA392809089 rs1461001144 |
135 | D>E | No |
ClinGen gnomAD |
|
|
rs1388869569 CA392809088 |
136 | K>Q | No |
ClinGen TOPMed |
|
|
CA392809057 rs1467688371 |
138 | R>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs1261529584 CA392809051 |
138 | R>L | No |
ClinGen gnomAD |
|
|
CA392809010 rs1205603830 |
140 | A>V | No |
ClinGen gnomAD |
|
|
CA392809000 rs578112615 |
141 | A>G | No |
ClinGen gnomAD |
|
|
CA272141727 rs578112615 |
141 | A>V | No |
ClinGen gnomAD |
|
| TCGA novel | 142 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1250675289 CA392808954 |
143 | M>I | No |
ClinGen gnomAD |
|
|
CA7607358 rs747635711 |
144 | E>G | No |
ClinGen ExAC gnomAD |
|
|
rs1328146104 CA392808910 |
145 | N>H | No |
ClinGen gnomAD |
|
|
rs1298005509 CA392808891 |
146 | P>A | No |
ClinGen gnomAD |
|
|
rs781146659 CA7607357 |
147 | N>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs781146659 CA392808871 |
147 | N>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA272141715 rs1033438183 |
147 | N>S | No |
ClinGen TOPMed gnomAD |
|
|
COSM1323896 rs746761595 CA392808828 |
149 | R>G | ovary Variant assessed as Somatic; 0.0 impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA7607353 rs779770789 |
149 | R>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA272141671 rs779770789 |
149 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs746761595 CA7607354 |
149 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA392808809 rs1595949519 |
150 | E>G | No |
ClinGen Ensembl |
|
|
CA392808782 rs1567303259 |
151 | I>M | No |
ClinGen Ensembl |
|
|
CA392808784 rs1392591067 |
151 | I>T | No |
ClinGen gnomAD |
|
| TCGA novel | 152 | V>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7607351 rs750682279 |
152 | V>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA272141652 rs970431544 |
153 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA392808691 rs1443066552 |
155 | C>* | No |
ClinGen gnomAD |
|
|
CA392808701 rs1185718778 |
155 | C>Y | No |
ClinGen TOPMed gnomAD |
|
|
rs148274950 CA7607349 |
159 | P>A | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs199691769 CA7607348 |
160 | D>E | No |
ClinGen 1000Genomes ExAC gnomAD |
|
| TCGA novel | 160 | D>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1414219175 CA392808571 |
161 | D>C | No |
ClinGen TOPMed |
No associated diseases with Q9H5X1
1 regional properties for Q9H5X1
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | MIP18 family-like | 39 - 109 | IPR002744 |
3 GO annotations of cellular component
| Name | Definition |
|---|---|
| CIA complex | The cytosolic iron-sulfur protein assembly (CIA) complex mediates the incorporation of iron-sulfur clusters into apoproteins involved in DNA metabolism and genomic integrity. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
1 GO annotations of molecular function
| Name | Definition |
|---|---|
| metal ion binding | Binding to a metal ion. |
4 GO annotations of biological process
| Name | Definition |
|---|---|
| chromosome segregation | The process in which genetic material, in the form of chromosomes, is organized into specific structures and then physically separated and apportioned to two or more sets. In eukaryotes, chromosome segregation begins with the condensation of chromosomes, includes chromosome separation, and ends when chromosomes have completed movement to the spindle poles. |
| iron-sulfur cluster assembly | The incorporation of iron and exogenous sulfur into a metallo-sulfur cluster. |
| protein maturation by [4Fe-4S] cluster transfer | The transfer of an assembled 4Fe-4S] cluster from a scaffold protein to an acceptor protein that contributes to the attainment of the full functional capacity of a protein. |
| protein maturation by iron-sulfur cluster transfer | The transfer of an assembled iron-sulfur cluster from a scaffold protein to an acceptor protein that contributes to the attainment of the full functional capacity of a protein. |
4 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q3T0U7 | CIAO2A | Cytosolic iron-sulfur assembly component 2A | Bos taurus (Bovine) | PR |
| Q9D187 | Ciao2b | Cytosolic iron-sulfur assembly component 2B | Mus musculus (Mouse) | PR |
| Q9DCL2 | Ciao2a | Cytosolic iron-sulfur assembly component 2A | Mus musculus (Mouse) | PR |
| Q9SR25 | AEL2 | Protein AE7-like 2 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MQRVSGLLSW | TLSRVLWLSG | LSEPGAARQP | RIMEEKALEV | YDLIRTIRDP | EKPNTLEELE |
| 70 | 80 | 90 | 100 | 110 | 120 |
| VVSESCVEVQ | EINEEEYLVI | IRFTPTVPHC | SLATLIGLCL | RVKLQRCLPF | KHKLEIYISE |
| 130 | 140 | 150 | |||
| GTHSTEEDIN | KQINDKERVA | AAMENPNLRE | IVEQCVLEPD |