Q14696
Gene name |
MESD |
Protein name |
LRP chaperone MESD |
Names |
LDLR chaperone MESD, Mesoderm development LRP chaperone MESD, Mesoderm development candidate 2, Mesoderm development protein, Renal carcinoma antigen NY-REN-61 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:23184 |
EC number |
|
Protein Class |
|
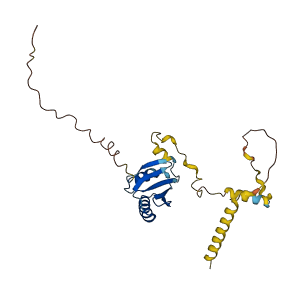
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q14696
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q14696-F1 | Predicted | AlphaFoldDB |
213 variants for Q14696
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs780491808 RCV000853613 |
203 | T>missing | Osteogenesis imperfecta, type 20 [ClinVar] | Yes |
ClinVar dbSNP |
|
rs745891632 RCV000853612 |
211 | K>missing | Osteogenesis imperfecta, type 20 [ClinVar] | Yes |
ClinVar dbSNP |
|
rs745891632 RCV000853610 |
212 | K>missing | Osteogenesis imperfecta, type 20 [ClinVar] | Yes |
ClinVar dbSNP |
|
CA393251488 RCV000853611 rs1021282486 |
226 | R>* | Osteogenesis imperfecta, type 20 [ClinVar] | Yes |
ClinGen ClinVar dbSNP gnomAD |
| VAR_083534 | 226 | R>del | OI20 [UniProt] | Yes | UniProt |
|
rs771591040 CA7694056 |
2 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs771591040 CA7694057 |
2 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs747563841 CA7694055 |
2 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA393258598 rs1300723498 |
3 | A>V | No |
ClinGen gnomAD |
|
|
CA7694052 rs61999333 |
4 | S>C | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA7694051 rs61999333 |
4 | S>F | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA393258594 rs1366109799 |
4 | S>P | No |
ClinGen gnomAD |
|
|
CA393258573 rs1468421394 |
5 | R>G | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA393258566 rs1333829041 |
5 | R>K | No |
ClinGen TOPMed |
|
|
CA393258527 rs1240321364 |
6 | W>G | No |
ClinGen gnomAD |
|
|
CA273381946 rs1013839844 |
6 | W>L | No |
ClinGen TOPMed |
|
|
CA393258530 rs1240321364 |
6 | W>R | No |
ClinGen gnomAD |
|
|
CA7694047 COSM3794455 rs758532744 |
8 | R>C | Variant assessed as Somatic; 0.0 impact. urinary_tract [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs758532744 CA7694048 |
8 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA393258468 rs752656906 |
8 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs752656906 CA7694046 |
8 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1201683569 CA393258455 |
9 | K>E | No |
ClinGen gnomAD |
|
|
CA393258439 rs1287064698 |
10 | A>S | No |
ClinGen TOPMed |
|
|
CA7694045 rs765791324 |
10 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA273381914 rs895071087 |
11 | V>L | No |
ClinGen TOPMed gnomAD |
|
|
CA393258415 rs895071087 |
11 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
rs766820623 CA7694042 |
13 | L>R | No |
ClinGen ExAC gnomAD |
|
|
rs773021525 CA7694040 |
16 | A>S | No |
ClinGen ExAC gnomAD |
|
|
CA7694039 rs771584647 |
16 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA7694037 rs773719701 |
17 | S>F | No |
ClinGen ExAC gnomAD |
|
|
rs779869446 CA7694034 |
19 | L>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs749191367 CA7694035 |
19 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs769595927 CA7694033 |
23 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA393258080 rs1400245496 |
26 | L>P | No |
ClinGen TOPMed gnomAD |
|
|
CA7694027 rs778056925 |
27 | P>A | No |
ClinGen ExAC gnomAD |
|
|
rs1262519950 CA393258048 |
28 | P>S | No |
ClinGen gnomAD |
|
|
CA7694024 rs146772302 |
29 | P>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7694025 rs375284217 |
29 | P>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7694023 rs755585515 |
31 | S>A | No |
ClinGen ExAC gnomAD |
|
|
CA393257988 rs1173030043 |
31 | S>F | No |
ClinGen TOPMed |
|
|
CA393257954 rs1398617919 |
33 | A>T | No |
ClinGen TOPMed |
|
|
CA393257943 rs1260878509 |
33 | A>V | No |
ClinGen gnomAD |
|
|
rs143990493 CA7694021 |
36 | G>A | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA393257890 rs1042594042 |
36 | G>C | No |
ClinGen gnomAD |
|
|
CA273381817 rs1042594042 |
36 | G>R | No |
ClinGen gnomAD |
|
|
CA7694022 rs143990493 |
36 | G>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1197724243 CA393257861 |
37 | S>L | No |
ClinGen gnomAD |
|
|
rs750695248 CA7694018 |
39 | G>E | No |
ClinGen ExAC gnomAD |
|
|
CA393257828 rs1428605286 |
39 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
CA393257763 rs1354983173 |
41 | P>L | No |
ClinGen TOPMed |
|
|
rs761365881 CA7694016 |
41 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA7694014 rs763486733 |
42 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7694012 rs201646678 |
43 | E>G | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA393257690 rs1596241080 |
44 | S>A | No |
ClinGen Ensembl |
|
|
rs536255319 CA7694010 |
45 | T>A | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs745679493 CA7694009 |
45 | T>I | No |
ClinGen ExAC TOPMed |
|
|
rs536255319 CA393257670 |
45 | T>P | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA7694011 rs536255319 |
45 | T>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs776280664 CA7694007 |
47 | P>L | No |
ClinGen ExAC gnomAD |
|
|
rs768816243 CA7694005 |
48 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs768816243 CA7694006 |
48 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA393257499 rs1460263321 |
51 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
CA273381706 rs932599029 |
52 | K>E | No |
ClinGen TOPMed gnomAD |
|
|
rs1256911593 CA393257337 |
57 | D>N | No |
ClinGen gnomAD |
|
|
COSM1678622 CA7694002 rs755132914 |
62 | D>A | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs1270705890 CA393257111 |
65 | R>H | No |
ClinGen gnomAD |
|
|
rs1270705890 CA393257109 |
65 | R>P | No |
ClinGen gnomAD |
|
|
rs756675505 CA7693999 |
69 | Q>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs866446988 CA273381631 |
71 | E>G | No |
ClinGen Ensembl |
|
|
rs143490497 CA7693998 |
71 | E>K | No |
ClinGen ESP ExAC gnomAD |
|
|
CA7693969 rs370334066 |
72 | K>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7693968 rs374050071 |
73 | D>G | No |
ClinGen ESP ExAC gnomAD |
|
|
CA393254924 rs374050071 |
73 | D>V | No |
ClinGen ESP ExAC gnomAD |
|
|
rs769066554 CA7693966 |
76 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs763235508 CA7693965 |
77 | E>G | No |
ClinGen ExAC gnomAD |
|
|
rs1408250589 CA393254854 |
78 | E>G | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 78 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1408250589 CA393254853 |
78 | E>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1247356012 CA393254841 |
79 | G>E | No |
ClinGen TOPMed |
|
|
CA393254817 rs1596237048 |
80 | D>E | No |
ClinGen Ensembl |
|
|
CA7693964 rs775761382 |
81 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA393254790 rs1270361287 |
82 | P>S | No |
ClinGen gnomAD |
|
|
CA7693963 rs770014867 |
84 | H>Y | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs1240178765 CA393254725 |
85 | K>R | No |
ClinGen gnomAD |
|
|
CA7693962 rs745917376 |
87 | P>H | No |
ClinGen ExAC gnomAD |
|
|
rs1555442592 CA7693960 |
89 | A>V | No |
ClinGen Ensembl |
|
|
CA7693958 rs771409126 |
90 | P>L | No |
ClinGen ExAC gnomAD |
|
|
rs781550236 CA7693959 |
90 | P>S | No |
ClinGen ExAC |
|
|
rs1221874594 CA393254573 |
92 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs1325788593 CA393254536 |
93 | F>L | No |
ClinGen gnomAD |
|
|
rs1283982246 CA393254505 |
95 | K>E | No |
ClinGen gnomAD |
|
|
CA393254495 rs1360484581 |
95 | K>N | No |
ClinGen gnomAD |
|
|
CA7693957 rs370672520 |
95 | K>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1291059655 CA393254449 |
97 | D>G | No |
ClinGen gnomAD |
|
|
CA393254368 rs1324708747 |
100 | K>Q | No |
ClinGen TOPMed |
|
|
rs1431951848 CA393254360 |
100 | K>R | No |
ClinGen gnomAD |
|
|
CA393254336 rs1349975011 |
101 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs1358881873 CA393254230 |
104 | I>M | No |
ClinGen gnomAD |
|
|
rs778109096 CA7693955 |
107 | M>I | No |
ClinGen ExAC gnomAD |
|
|
CA7693954 rs758089005 |
108 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs148831547 CA393254095 |
109 | K>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs766243377 CA7693949 |
111 | G>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs145472737 CA7693951 CA7693950 |
111 | G>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs760649884 CA7693948 |
112 | K>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs750281158 CA7693947 |
113 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA393253989 rs376822687 |
114 | L>F | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs1226768262 CA393253974 |
114 | L>R | No |
ClinGen gnomAD |
|
|
rs376822687 CA273373863 |
114 | L>V | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs1279700209 CA393253951 |
115 | M>I | No |
ClinGen Ensembl |
|
|
CA393253914 rs1305783075 |
116 | M>I | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 119 | T>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs761650773 CA7693945 |
119 | T>S | No |
ClinGen ExAC gnomAD |
|
|
CA393253837 rs1313338724 |
120 | V>L | No |
ClinGen gnomAD |
|
|
CA393253803 rs1461485763 |
122 | G>R | No |
ClinGen gnomAD |
|
|
rs759545458 CA7693942 |
124 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA7693943 rs759545458 |
124 | P>T | No |
ClinGen ExAC gnomAD |
|
|
rs776756284 COSM290754 CA7693941 |
125 | T>A | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs776756284 CA393253742 |
125 | T>P | No |
ClinGen ExAC gnomAD |
|
|
CA7693940 rs771410960 |
126 | E>A | No |
ClinGen ExAC gnomAD |
|
|
rs1336884171 CA393253722 |
126 | E>K | No |
ClinGen gnomAD |
|
|
rs1596236903 CA393253699 |
127 | K>E | No |
ClinGen Ensembl |
|
|
rs1172475380 CA393253649 |
129 | T>A | No |
ClinGen gnomAD |
|
| TCGA novel | 130 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 130 | E>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA393253625 rs1181520926 |
131 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA393253601 rs1446737360 |
132 | I>M | No |
ClinGen gnomAD |
|
|
CA7693939 rs778164192 |
133 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7693938 rs778164192 |
133 | T>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7693936 rs748473089 |
135 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA273373783 rs1000904744 |
137 | Q>R | No |
ClinGen TOPMed |
|
|
rs369992727 CA7693933 |
140 | L>F | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs369992727 CA7693934 |
140 | L>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs534456533 CA7693932 |
142 | N>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1290120888 CA393253435 |
144 | N>T | No |
ClinGen gnomAD |
|
|
CA7693931 rs368285022 |
145 | Y>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7693929 rs571856723 |
147 | V>I | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1008082002 CA273373764 |
148 | Q>* | No |
ClinGen TOPMed gnomAD |
|
|
rs551918262 CA7693928 |
149 | R>W | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs751463073 CA7693904 |
151 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA7693903 rs763920725 |
153 | G>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA7693902 rs146044786 |
155 | D>G | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA7693901 rs754116910 |
156 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs185628590 CA7693900 |
156 | R>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1203741833 CA393252658 |
157 | A>T | No |
ClinGen gnomAD |
|
|
rs773219081 CA7693898 |
158 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 159 | F>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7693897 rs768071584 |
160 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs1203648080 CA393252619 |
160 | M>V | No |
ClinGen gnomAD |
|
|
CA7693896 rs762303952 |
162 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA273370789 rs1036378913 |
162 | R>H | No |
ClinGen TOPMed |
|
|
rs763187582 CA7693893 |
163 | D>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
COSM3387086 CA7693894 rs769085988 |
163 | D>N | pancreas [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
CA273370769 rs748803320 |
165 | S>R | No |
ClinGen TOPMed gnomAD |
|
|
CA7693892 rs775212077 |
165 | S>T | No |
ClinGen ExAC gnomAD |
|
|
CA273370752 rs1049372369 |
169 | E>K | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 170 | I>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs779640639 CA273370740 |
173 | F>L | No |
ClinGen Ensembl |
|
| TCGA novel | 174 | L>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1427338905 CA393252422 |
175 | V>F | No |
ClinGen gnomAD |
|
|
CA393252394 rs777525821 |
176 | G>C | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 176 | G>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7693886 rs777525821 |
176 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1191586938 CA393252240 |
181 | A>S | No |
ClinGen gnomAD |
|
|
rs1481765687 CA393252190 |
183 | V>L | No |
ClinGen TOPMed |
|
|
rs755846651 CA7693884 |
184 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA273370688 rs780337539 |
185 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA393252141 rs1358762917 |
186 | E>* | No |
ClinGen TOPMed gnomAD |
|
|
rs554192447 CA7693882 |
187 | G>D | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1397658721 CA393252110 |
188 | Q>R | No |
ClinGen TOPMed |
|
|
rs1328002658 CA393252048 |
190 | Y>* | No |
ClinGen gnomAD |
|
|
rs767555701 CA7693880 COSM3741691 |
190 | Y>C | liver [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
CA7693878 rs752136549 |
192 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs763385906 CA7693875 |
194 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA393251952 rs1415115698 |
194 | G>V | No |
ClinGen gnomAD |
|
|
CA7693874 rs775699712 |
195 | G>E | No |
ClinGen ExAC gnomAD |
|
|
CA7693871 rs1555442302 |
197 | S>G | No |
ClinGen Ensembl |
|
|
CA273370587 rs111349315 CA273370574 |
197 | S>R | No |
ClinGen Ensembl |
|
|
CA393251872 rs1476663916 |
199 | E>Q | No |
ClinGen gnomAD |
|
|
rs759229590 CA7693870 |
200 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs1313781182 CA393251786 |
202 | K>E | No |
ClinGen TOPMed |
|
|
CA273370522 rs565976654 |
204 | K>E | No |
ClinGen 1000Genomes |
|
|
rs1189111257 CA393251677 |
206 | D>E | No |
ClinGen gnomAD |
|
|
rs1240894931 CA393251692 |
206 | D>N | No |
ClinGen gnomAD |
|
|
rs200800639 CA393251666 |
207 | K>N | No |
ClinGen 1000Genomes |
|
|
CA7693866 rs146515688 |
207 | K>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA393251671 rs1297959457 |
207 | K>R | No |
ClinGen gnomAD |
|
|
CA393251653 rs144118294 |
208 | G>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1271618365 CA393251664 |
208 | G>S | No |
ClinGen gnomAD |
|
|
rs144118294 CA7693865 |
208 | G>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs777773938 CA7693863 |
209 | K>Q | No |
ClinGen ExAC |
|
|
CA7693862 rs188746307 |
210 | K>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs183241539 CA7693861 |
210 | K>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1273065577 CA393251582 |
211 | K>N | No |
ClinGen TOPMed |
|
| rs745891632 | 211 | K>R | Variant assessed as Somatic; 9.565e-05 impact. [NCI-TCGA] | No | NCI-TCGA |
| rs745891632 | 212 | K>E | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1335302727 CA393251549 |
216 | L>V | No |
ClinGen gnomAD |
|
| TCGA novel | 218 | S>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA7693855 COSM3377676 rs750663890 |
219 | R>Q | pancreas [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs756370348 CA7693856 |
219 | R>W | No |
ClinGen ExAC gnomAD |
|
|
CA7693854 rs781351101 |
221 | S>F | No |
ClinGen ExAC gnomAD |
|
|
rs751535827 CA7693852 |
222 | K>Q | No |
ClinGen ExAC gnomAD |
|
|
rs763361869 CA273370373 |
223 | E>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1231850905 CA393251509 |
223 | E>G | No |
ClinGen gnomAD |
|
|
rs763361869 CA7693850 |
223 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1483718244 CA393251495 |
225 | N>D | No |
ClinGen gnomAD |
|
|
rs1596234849 CA393251492 |
225 | N>S | No |
ClinGen Ensembl |
|
|
CA273370370 rs1021282486 |
226 | R>G | No |
ClinGen gnomAD |
|
|
rs753142107 CA7693849 |
226 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA393251475 rs1293650238 |
228 | G>A | No |
ClinGen gnomAD |
|
|
CA273370359 rs960104401 |
230 | K>E | No |
ClinGen TOPMed gnomAD |
|
|
CA7693847 rs759933191 |
231 | R>I | No |
ClinGen ExAC |
|
|
rs1190488816 CA393251441 |
233 | D>A | No |
ClinGen TOPMed |
|
|
rs1277912578 CA393251425 |
235 | L>W | No |
ClinGen gnomAD |
1 associated diseases with Q14696
[MIM: 618644]: Osteogenesis imperfecta 20 (OI20)
An autosomal recessive form of osteogenesis imperfecta, a connective tissue disorder characterized by low bone mass, bone fragility and susceptibility to fractures after minimal trauma. Disease severity ranges from very mild forms without fractures to intrauterine fractures and perinatal lethality. Extraskeletal manifestations, which affect a variable number of patients, are dentinogenesis imperfecta, hearing loss, and blue sclerae. OI20 is a progressive deforming form characterized by osteopenia, skeletal deformity, healed fractures, and newly-acquired fractures. Death due to respiratory failure can occur in some patients. {ECO:0000269|PubMed:31564437}. Note=The disease is caused by variants affecting the gene represented in this entry.
Without disease ID
- An autosomal recessive form of osteogenesis imperfecta, a connective tissue disorder characterized by low bone mass, bone fragility and susceptibility to fractures after minimal trauma. Disease severity ranges from very mild forms without fractures to intrauterine fractures and perinatal lethality. Extraskeletal manifestations, which affect a variable number of patients, are dentinogenesis imperfecta, hearing loss, and blue sclerae. OI20 is a progressive deforming form characterized by osteopenia, skeletal deformity, healed fractures, and newly-acquired fractures. Death due to respiratory failure can occur in some patients. {ECO:0000269|PubMed:31564437}. Note=The disease is caused by variants affecting the gene represented in this entry.
No regional properties for Q14696
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for Q14696 | |||
2 GO annotations of cellular component
| Name | Definition |
|---|---|
| endoplasmic reticulum | The irregular network of unit membranes, visible only by electron microscopy, that occurs in the cytoplasm of many eukaryotic cells. The membranes form a complex meshwork of tubular channels, which are often expanded into slitlike cavities called cisternae. The ER takes two forms, rough (or granular), with ribosomes adhering to the outer surface, and smooth (with no ribosomes attached). |
| plasma membrane | The membrane surrounding a cell that separates the cell from its external environment. It consists of a phospholipid bilayer and associated proteins. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| identical protein binding | Binding to an identical protein or proteins. |
| low-density lipoprotein particle receptor binding | Binding to a low-density lipoprotein receptor. |
7 GO annotations of biological process
| Name | Definition |
|---|---|
| mesoderm development | The process whose specific outcome is the progression of the mesoderm over time, from its formation to the mature structure. The mesoderm is the middle germ layer that develops into muscle, bone, cartilage, blood and connective tissue. |
| ossification | The formation of bone or of a bony substance, or the conversion of fibrous tissue or of cartilage into bone or a bony substance. |
| phagocytosis | A vesicle-mediated transport process that results in the engulfment of external particulate material by phagocytes and their delivery to the lysosome. The particles are initially contained within phagocytic vacuoles (phagosomes), which then fuse with primary lysosomes to effect digestion of the particles. |
| positive regulation of skeletal muscle acetylcholine-gated channel clustering | Any process that activates or increases the frequency, rate or extent of skeletal muscle acetylcholine-gated channel clustering. |
| protein folding | The process of assisting in the covalent and noncovalent assembly of single chain polypeptides or multisubunit complexes into the correct tertiary structure. |
| protein localization to cell surface | A process in which a protein is transported to, or maintained in, a location within the external part of the cell wall and/or plasma membrane. |
| Wnt signaling pathway | The series of molecular signals initiated by binding of a Wnt protein to a frizzled family receptor on the surface of the target cell and ending with a change in cell state. |
4 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q3T0U1 | MESD | LRP chaperone MESD | Bos taurus (Bovine) | PR |
| Q5ZKK4 | mesd | LRP chaperone MESD | Gallus gallus (Chicken) | PR |
| Q5U2R7 | Mesd | LRP chaperone MESD | Rattus norvegicus (Rat) | PR |
| A1L243 | mesd | LRP chaperone MESD | Danio rerio (Zebrafish) (Brachydanio rerio) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAASRWARKA | VVLLCASDLL | LLLLLLPPPG | SCAAEGSPGT | PDESTPPPRK | KKKDIRDYND |
| 70 | 80 | 90 | 100 | 110 | 120 |
| ADMARLLEQW | EKDDDIEEGD | LPEHKRPSAP | VDFSKIDPSK | PESILKMTKK | GKTLMMFVTV |
| 130 | 140 | 150 | 160 | 170 | 180 |
| SGSPTEKETE | EITSLWQGSL | FNANYDVQRF | IVGSDRAIFM | LRDGSYAWEI | KDFLVGQDRC |
| 190 | 200 | 210 | 220 | 230 | |
| ADVTLEGQVY | PGKGGGSKEK | NKTKQDKGKK | KKEGDLKSRS | SKEENRAGNK | REDL |