P62333
Gene name |
PSMC6 (SUG2) |
Protein name |
26S proteasome regulatory subunit 10B |
Names |
26S proteasome AAA-ATPase subunit RPT4, Proteasome 26S subunit ATPase 6, Proteasome subunit p42 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:5706 |
EC number |
|
Protein Class |
|
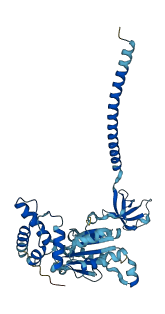
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
39 structures for P62333
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 5GJQ | EM | 450 A | L | 1-389 | PDB |
| 5GJR | EM | 350 A | L/z | 1-389 | PDB |
| 5L4G | EM | 402 A | L | 1-389 | PDB |
| 5LN3 | EM | 680 A | L | 1-389 | PDB |
| 5M32 | EM | 380 A | f | 1-379 | PDB |
| 5T0C | EM | 380 A | AE/BE | 1-389 | PDB |
| 5T0G | EM | 440 A | E | 1-389 | PDB |
| 5T0H | EM | 680 A | E | 1-389 | PDB |
| 5T0I | EM | 800 A | E | 1-389 | PDB |
| 5T0J | EM | 800 A | E | 1-389 | PDB |
| 5VFP | EM | 420 A | E | 15-389 | PDB |
| 5VFQ | EM | 420 A | E | 15-389 | PDB |
| 5VFR | EM | 490 A | E | 15-389 | PDB |
| 5VFS | EM | 360 A | E | 1-389 | PDB |
| 5VFT | EM | 700 A | E | 37-389 | PDB |
| 5VFU | EM | 580 A | E | 37-389 | PDB |
| 5VGZ | EM | 370 A | E | 11-114 | PDB |
| 5VHF | EM | 570 A | E | 11-389 | PDB |
| 5VHH | EM | 610 A | E | 11-389 | PDB |
| 5VHI | EM | 680 A | E | 11-389 | PDB |
| 5VHJ | EM | 850 A | E | 128-389 | PDB |
| 5VHM | EM | 830 A | E | 128-389 | PDB |
| 5VHN | EM | 730 A | E | 115-389 | PDB |
| 5VHO | EM | 830 A | E | 128-389 | PDB |
| 5VHP | EM | 790 A | E | 128-389 | PDB |
| 5VHQ | EM | 890 A | E | 128-389 | PDB |
| 5VHR | EM | 770 A | E | 128-389 | PDB |
| 5VHS | EM | 880 A | E | 11-389 | PDB |
| 6MSB | EM | 300 A | E | 1-389 | PDB |
| 6MSD | EM | 320 A | E | 1-389 | PDB |
| 6MSE | EM | 330 A | E | 1-389 | PDB |
| 6MSG | EM | 350 A | E | 1-389 | PDB |
| 6MSH | EM | 360 A | E | 1-389 | PDB |
| 6MSJ | EM | 330 A | E | 1-389 | PDB |
| 6MSK | EM | 320 A | E | 1-389 | PDB |
| 6WJN | EM | 570 A | E | 15-389 | PDB |
| 7QY7 | EM | 470 A | E | 1-389 | PDB |
| 8CVT | EM | 300 A | E | 1-389 | PDB |
| AF-P62333-F1 | Predicted | AlphaFoldDB |
141 variants for P62333
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA7189581 rs142367793 |
4 | P>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1489346771 CA389724314 |
4 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
CA389724313 rs1489346771 |
4 | P>R | No |
ClinGen TOPMed gnomAD |
|
|
CA7189580 rs142367793 |
4 | P>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA7189583 rs753009195 |
5 | R>K | No |
ClinGen ExAC |
|
|
rs777973212 CA389724324 |
6 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA7189584 rs542227590 |
6 | D>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA389724321 rs542227590 |
6 | D>N | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs777973212 CA7189585 |
6 | D>V | No |
ClinGen ExAC gnomAD |
|
|
CA7189586 rs749384722 |
7 | K>E | No |
ClinGen ExAC gnomAD |
|
|
CA7189587 rs771076814 |
8 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA260933969 rs999793856 |
10 | Q>E | No |
ClinGen gnomAD |
|
|
rs779585393 CA7189588 |
10 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
CA389724358 rs1436451444 |
11 | D>E | No |
ClinGen gnomAD |
|
|
rs1394464421 CA389724351 |
11 | D>N | No |
ClinGen gnomAD |
|
|
CA389724360 rs1290570124 |
12 | Y>H | No |
ClinGen TOPMed |
|
|
CA7189589 rs151244912 |
13 | R>C | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs772535111 CA7189591 |
14 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs1594845503 CA389724406 |
18 | E>D | No |
ClinGen Ensembl |
|
|
rs1415690800 CA389724420 |
20 | K>R | No |
ClinGen TOPMed |
|
|
rs745763726 CA389724433 |
22 | I>F | No |
ClinGen gnomAD |
|
|
rs745763726 CA260934002 |
22 | I>L | No |
ClinGen gnomAD |
|
|
CA260934009 rs922789384 |
23 | D>A | No |
ClinGen TOPMed |
|
|
CA389724481 rs1594845522 |
29 | L>V | No |
ClinGen Ensembl |
|
|
rs1255526988 CA389724516 |
32 | Q>E | No |
ClinGen TOPMed |
|
|
rs956227504 CA260934888 |
37 | T>A | No |
ClinGen TOPMed gnomAD |
|
|
CA389724554 rs1309950808 |
37 | T>N | No |
ClinGen TOPMed gnomAD |
|
|
CA389724581 rs1228178955 |
41 | E>K | No |
ClinGen TOPMed |
|
|
rs1252120720 CA389724589 |
42 | K>Q | No |
ClinGen gnomAD |
|
|
rs747859403 CA7189631 |
52 | S>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs769435277 CA7189632 |
55 | Q>P | No |
ClinGen ExAC gnomAD |
|
|
rs1286744683 CA389724729 |
60 | V>G | No |
ClinGen TOPMed |
|
|
CA389724737 rs1451339304 |
62 | K>E | No |
ClinGen gnomAD |
|
|
CA389724748 rs1166387708 |
63 | Q>R | No |
ClinGen gnomAD |
|
|
CA389724763 rs766447066 |
65 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA7189645 rs766447066 |
65 | T>S | No |
ClinGen ExAC gnomAD |
|
|
CA389724817 rs1316992233 |
71 | V>F | No |
ClinGen gnomAD |
|
|
CA389724829 rs1340761664 |
73 | A>T | No |
ClinGen gnomAD |
|
|
rs773343252 CA7189663 |
75 | N>S | No |
ClinGen ExAC TOPMed |
|
|
CA389724911 rs1290989286 |
85 | R>Q | No |
ClinGen gnomAD |
|
|
rs1479550485 CA389724998 |
88 | D>H | No |
ClinGen gnomAD |
|
|
rs1478092160 CA389725066 |
92 | L>P | No |
ClinGen gnomAD |
|
|
rs761150165 CA7189689 |
95 | G>E | No |
ClinGen ExAC gnomAD |
|
|
rs1379647559 CA389725108 |
96 | T>K | No |
ClinGen TOPMed |
|
|
CA260937045 rs541834964 |
107 | I>V | No |
ClinGen Ensembl |
|
|
rs781214722 CA7189717 |
112 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs11545962 CA260937294 |
114 | E>G | No |
ClinGen Ensembl |
|
|
CA7189719 rs755978557 |
116 | D>H | No |
ClinGen ExAC gnomAD |
|
|
rs1336685592 CA389725491 |
126 | D>E | No |
ClinGen gnomAD |
|
|
CA389725552 rs1456317179 |
130 | V>A | No |
ClinGen TOPMed |
|
|
CA389725568 rs1231171751 |
131 | S>C | No |
ClinGen gnomAD |
|
|
rs1351487758 CA389725584 |
132 | Y>F | No |
ClinGen TOPMed |
|
|
rs1803069 CA260937317 |
133 | S>F | No |
ClinGen Ensembl |
|
|
CA7189720 rs777523457 |
135 | I>S | No |
ClinGen ExAC gnomAD |
|
|
CA389725645 rs1165217588 |
137 | G>R | No |
ClinGen TOPMed |
|
|
rs1239858090 CA389725686 |
140 | E>G | No |
ClinGen gnomAD |
|
|
CA260937331 rs899785613 |
142 | I>M | No |
ClinGen Ensembl |
|
|
rs775631269 CA7189723 |
143 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs747132261 CA7189724 |
143 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs775631269 CA389725720 |
143 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1259121416 CA389725728 |
144 | E>K | No |
ClinGen gnomAD |
|
|
CA389726034 rs1282074078 |
153 | L>F | No |
ClinGen gnomAD |
|
|
CA389726042 rs753642513 |
154 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA7189739 rs753642513 |
154 | T>R | No |
ClinGen ExAC gnomAD |
|
|
rs1335408835 CA389726054 |
156 | P>Q | No |
ClinGen TOPMed |
|
|
rs747167339 CA7189742 |
157 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs1383242307 CA389726076 |
159 | F>L | No |
ClinGen TOPMed |
|
|
rs779580328 CA260938991 |
159 | F>L | No |
ClinGen TOPMed gnomAD |
|
|
CA7189743 rs768826722 |
160 | Q>R | No |
ClinGen ExAC |
|
|
rs1400222509 CA389726088 |
161 | R>H | No |
ClinGen gnomAD |
|
|
CA389726104 rs1457445565 |
164 | I>V | No |
ClinGen TOPMed |
|
|
CA7189747 rs773800840 |
173 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs1162198807 CA389726166 |
173 | Y>H | No |
ClinGen TOPMed |
|
|
CA389726207 rs1435670828 |
177 | G>A | No |
ClinGen TOPMed |
|
|
CA7189763 rs756217809 |
178 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA389726228 rs1594851579 |
181 | T>P | No |
ClinGen Ensembl |
|
|
rs771473061 CA7189766 |
185 | R>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs771473061 CA389726253 |
185 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1220814053 CA389726254 |
185 | R>Q | No |
ClinGen TOPMed |
|
|
CA389726265 rs1156992215 |
187 | V>I | No |
ClinGen gnomAD |
|
|
CA389726299 rs1278687625 |
192 | D>Y | No |
ClinGen TOPMed |
|
|
CA260941740 rs866595005 |
193 | C>Y | No |
ClinGen Ensembl |
|
|
CA389726317 rs1368171298 |
194 | N>S | No |
ClinGen gnomAD |
|
|
rs967216694 CA260941795 |
203 | I>V | No |
ClinGen gnomAD |
|
|
CA389726407 rs1294461109 |
205 | D>E | No |
ClinGen TOPMed gnomAD |
|
|
rs977361462 CA260941814 |
213 | R>H | No |
ClinGen Ensembl |
|
|
CA260941819 rs377094174 |
220 | N>S | No |
ClinGen ESP gnomAD |
|
|
rs1283345320 CA389726522 |
221 | Y>F | No |
ClinGen TOPMed |
|
|
rs1275641635 CA389726531 |
223 | R>G | No |
ClinGen gnomAD |
|
|
CA7189787 rs775045062 |
227 | P>L | No |
ClinGen ExAC gnomAD |
|
|
rs746641590 CA7189788 |
229 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs1241698659 CA389726644 |
238 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
rs780762950 CA7189809 |
247 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA260942247 rs749681528 |
251 | R>G | No |
ClinGen Ensembl |
|
|
CA260943315 rs1042135398 |
264 | M>V | No |
ClinGen TOPMed |
|
|
CA389726885 rs1594853263 |
269 | T>N | No |
ClinGen Ensembl |
|
|
rs1384005369 CA389726895 |
271 | H>Y | No |
ClinGen TOPMed |
|
|
CA389726955 rs1362691659 |
279 | T>A | No |
ClinGen TOPMed |
|
|
rs1331187743 CA389726956 |
279 | T>K | No |
ClinGen gnomAD |
|
|
CA7189831 rs369082655 |
284 | T>I | No |
ClinGen ESP ExAC gnomAD |
|
|
rs143101806 CA7189833 |
287 | P>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA260943360 rs61734473 |
290 | L>V | No |
ClinGen Ensembl |
|
|
rs1191175608 CA389727056 |
295 | L>S | No |
ClinGen TOPMed gnomAD |
|
|
CA389727089 rs1266296760 |
299 | I>M | No |
ClinGen gnomAD |
|
|
rs1394008432 CA389727107 |
300 | H>L | No |
ClinGen TOPMed |
|
|
rs1370989311 CA389727091 |
300 | H>Y | No |
ClinGen TOPMed |
|
|
rs779026305 CA7189855 |
301 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs756781602 CA7189854 |
301 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs745777005 CA7189856 |
302 | D>N | No |
ClinGen ExAC gnomAD |
|
|
rs772049323 CA7189857 |
303 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs1454329535 CA389727124 |
303 | L>W | No |
ClinGen gnomAD |
|
|
CA389727142 rs1171191828 |
306 | E>K | No |
ClinGen TOPMed |
|
|
rs1360092477 CA389727161 |
308 | A>E | No |
ClinGen gnomAD |
|
|
CA7189860 rs770064263 |
318 | G>D | No |
ClinGen ExAC gnomAD |
|
|
rs770064263 CA389727230 |
318 | G>V | No |
ClinGen ExAC gnomAD |
|
|
CA260943487 rs141153483 |
321 | T>R | No |
ClinGen ESP |
|
|
rs1234585672 CA389727327 |
330 | A>E | No |
ClinGen gnomAD |
|
|
rs1234585672 CA389727328 |
330 | A>G | No |
ClinGen gnomAD |
|
|
rs150366196 CA7189874 |
331 | I>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1486874597 CA389727338 |
332 | V>L | No |
ClinGen gnomAD |
|
|
rs556787109 CA7189875 |
333 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA389727358 rs1438582072 |
335 | S>L | No |
ClinGen gnomAD |
|
|
CA260945121 rs369530713 |
342 | D>E | No |
ClinGen ESP |
|
|
CA389727410 rs1481240614 |
343 | L>M | No |
ClinGen gnomAD |
|
|
CA260945126 rs1035876368 |
344 | R>S | No |
ClinGen Ensembl |
|
|
rs1179096966 CA389727429 |
346 | V>I | No |
ClinGen gnomAD |
|
|
CA7189877 rs768293547 |
351 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA7189890 rs753582556 |
352 | M>V | No |
ClinGen ExAC gnomAD |
|
|
rs1400637963 CA389727497 |
354 | A>T | No |
ClinGen gnomAD |
|
|
CA389727510 rs1411400060 |
356 | R>G | No |
ClinGen TOPMed gnomAD |
|
|
CA7189892 rs764914580 |
356 | R>H | No |
ClinGen ExAC gnomAD |
|
|
CA389727512 rs1411400060 |
356 | R>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1441066205 CA389727529 |
359 | H>N | No |
ClinGen gnomAD |
|
|
rs757929903 CA7189894 |
360 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
rs560603755 CA260946582 |
365 | E>G | No |
ClinGen Ensembl |
|
|
rs1435316510 CA389727594 |
367 | F>L | No |
ClinGen gnomAD |
|
|
rs1309623315 CA389727635 |
373 | K>R | No |
ClinGen TOPMed |
|
|
rs368977300 CA260946587 |
375 | A>D | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs368977300 CA260946589 |
375 | A>G | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA389727659 rs1363122948 |
377 | S>A | No |
ClinGen gnomAD |
|
|
CA389727733 rs1275129779 |
387 | K>R | No |
ClinGen gnomAD |
No associated diseases with P62333
5 regional properties for P62333
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | AAA+ ATPase domain | 166 - 305 | IPR003593 |
| domain | ATPase, AAA-type, core | 171 - 302 | IPR003959 |
| conserved_site | ATPase, AAA-type, conserved site | 273 - 291 | IPR003960 |
| domain | Proteasomal ATPase OB C-terminal domain | 57 - 112 | IPR032501 |
| domain | AAA ATPase, AAA+ lid domain | 326 - 368 | IPR041569 |
10 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| cytosolic proteasome complex | A proteasome complex found in the cytosol of a cell. |
| extracellular exosome | A vesicle that is released into the extracellular region by fusion of the limiting endosomal membrane of a multivesicular body with the plasma membrane. Extracellular exosomes, also simply called exosomes, have a diameter of about 40-100 nm. |
| inclusion body | A discrete intracellular part formed of aggregated molecules such as proteins or other biopolymers. |
| membrane | A lipid bilayer along with all the proteins and protein complexes embedded in it an attached to it. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| proteasome accessory complex | A protein complex, that caps one or both ends of the proteasome core complex and regulates entry into, or exit from, the proteasome core complex. |
| proteasome complex | A large multisubunit complex which catalyzes protein degradation, found in eukaryotes, archaea and some bacteria. In eukaryotes, this complex consists of the barrel shaped proteasome core complex and one or two associated proteins or complexes that act in regulating entry into or exit from the core. |
| proteasome regulatory particle, base subcomplex | The subcomplex of the proteasome regulatory particle that directly associates with the proteasome core complex. |
5 GO annotations of molecular function
| Name | Definition |
|---|---|
| ATP binding | Binding to ATP, adenosine 5'-triphosphate, a universally important coenzyme and enzyme regulator. |
| ATP hydrolysis activity | Catalysis of the reaction: ATP + H2O = ADP + H+ phosphate. ATP hydrolysis is used in some reactions as an energy source, for example to catalyze a reaction or drive transport against a concentration gradient. |
| identical protein binding | Binding to an identical protein or proteins. |
| proteasome-activating activity | Catalysis of the reaction: ATP + H2O = ADP + phosphate, which promotes unfolding of protein substrates, and channel opening of the core proteasome. |
| protein-macromolecule adaptor activity | The binding activity of a protein that brings together two or more macromolecules in contact, permitting those molecules to function in a coordinated way. The adaptor can bring together two proteins, or a protein and another macromolecule such as a lipid or a nucleic acid. |
5 GO annotations of biological process
| Name | Definition |
|---|---|
| positive regulation of inclusion body assembly | Any process that increases the rate, frequency, or extent of inclusion body assembly. Inclusion body assembly is the aggregation, arrangement and bonding together of a set of components to form an inclusion body. |
| positive regulation of proteasomal protein catabolic process | Any process that activates or increases the frequency, rate or extent of proteasomal protein catabolic process. |
| positive regulation of RNA polymerase II transcription preinitiation complex assembly | Any process that activates or increases the frequency, rate or extent of RNA polymerase II transcriptional preinitiation complex assembly. |
| proteasome-mediated ubiquitin-dependent protein catabolic process | The chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of ubiquitin, and mediated by the proteasome. |
| ubiquitin-dependent ERAD pathway | The series of steps necessary to target endoplasmic reticulum (ER)-resident proteins for degradation by the cytoplasmic proteasome. Begins with recognition of the ER-resident protein, includes retrotranslocation (dislocation) of the protein from the ER to the cytosol, protein ubiquitination necessary for correct substrate transfer, transport of the protein to the proteasome, and ends with degradation of the protein by the cytoplasmic proteasome. |
5 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P17980 | PSMC3 | 26S proteasome regulatory subunit 6A | Homo sapiens (Human) | PR |
| P43686 | PSMC4 | 26S proteasome regulatory subunit 6B | Homo sapiens (Human) | PR |
| P35998 | PSMC2 | 26S proteasome regulatory subunit 7 | Homo sapiens (Human) | PR |
| P62195 | PSMC5 | 26S proteasome regulatory subunit 8 | Homo sapiens (Human) | PR |
| O17071 | rpt-4 | Probable 26S proteasome regulatory subunit 10B | Caenorhabditis elegans | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MADPRDKALQ | DYRKKLLEHK | EIDGRLKELR | EQLKELTKQY | EKSENDLKAL | QSVGQIVGEV |
| 70 | 80 | 90 | 100 | 110 | 120 |
| LKQLTEEKFI | VKATNGPRYV | VGCRRQLDKS | KLKPGTRVAL | DMTTLTIMRY | LPREVDPLVY |
| 130 | 140 | 150 | 160 | 170 | 180 |
| NMSHEDPGNV | SYSEIGGLSE | QIRELREVIE | LPLTNPELFQ | RVGIIPPKGC | LLYGPPGTGK |
| 190 | 200 | 210 | 220 | 230 | 240 |
| TLLARAVASQ | LDCNFLKVVS | SSIVDKYIGE | SARLIREMFN | YARDHQPCII | FMDEIDAIGG |
| 250 | 260 | 270 | 280 | 290 | 300 |
| RRFSEGTSAD | REIQRTLMEL | LNQMDGFDTL | HRVKMIMATN | RPDTLDPALL | RPGRLDRKIH |
| 310 | 320 | 330 | 340 | 350 | 360 |
| IDLPNEQARL | DILKIHAGPI | TKHGEIDYEA | IVKLSDGFNG | ADLRNVCTEA | GMFAIRADHD |
| 370 | 380 | ||||
| FVVQEDFMKA | VRKVADSKKL | ESKLDYKPV |