P30304
Gene name |
CDC25A |
Protein name |
M-phase inducer phosphatase 1 |
Names |
Dual specificity phosphatase Cdc25A |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:993 |
EC number |
3.1.3.48: Phosphoric monoester hydrolases |
Protein Class |
|
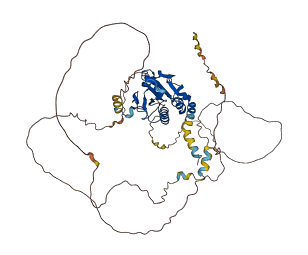
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
2 structures for P30304
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1C25 | X-ray | 230 A | A | 337-496 | PDB |
| AF-P30304-F1 | Predicted | AlphaFoldDB |
309 variants for P30304
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA352997806 rs914324994 |
4 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
CA74106363 rs914324994 |
4 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
CA352997804 rs1378352193 |
4 | G>V | No |
ClinGen gnomAD |
|
|
rs1434843977 CA352997796 |
5 | P>L | No |
ClinGen gnomAD |
|
|
CA2372247 rs761234931 |
7 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA74106361 rs994319712 |
9 | H>P | No |
ClinGen TOPMed |
|
|
rs994319712 CA352997773 |
9 | H>R | No |
ClinGen TOPMed |
|
|
rs1158177901 CA352997766 |
10 | R>H | No |
ClinGen gnomAD |
|
|
rs1408715616 CA352997756 |
12 | R>G | No |
ClinGen gnomAD |
|
|
CA352997752 rs1178871220 |
12 | R>L | No |
ClinGen gnomAD |
|
|
rs1199738200 CA352997746 |
14 | L>V | No |
ClinGen gnomAD |
|
|
rs775789345 CA2372246 |
16 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA352997732 rs775789345 |
16 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA352997731 rs775789345 |
16 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2372245 rs772493975 |
19 | P>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA352997708 rs772493975 |
19 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs937463969 CA74106355 |
19 | P>S | No |
ClinGen Ensembl |
|
|
rs1275767970 CA352997703 |
20 | P>L | No |
ClinGen gnomAD |
|
|
rs1275767970 CA352997704 |
20 | P>R | No |
ClinGen gnomAD |
|
|
CA2372244 rs746164227 |
20 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1425015047 CA352997697 |
21 | P>L | No |
ClinGen TOPMed |
|
|
RCV000950103 rs146179438 CA2372241 |
24 | Q>H | No |
ClinGen ClinVar 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA352997671 rs1472675189 |
26 | V>I | No |
ClinGen TOPMed |
|
|
CA74106328 rs970012640 |
28 | K>N | No |
ClinGen TOPMed |
|
|
rs972974061 CA74106324 |
29 | A>V | No |
ClinGen gnomAD |
|
|
rs1465385924 CA352997644 |
30 | L>P | No |
ClinGen TOPMed |
|
|
CA74106315 rs962870955 |
31 | F>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA352997625 rs1176948569 |
33 | A>V | No |
ClinGen gnomAD |
|
|
rs1404341101 CA352997621 |
34 | S>A | No |
ClinGen TOPMed |
|
|
rs1481276059 CA352997612 |
35 | A>V | No |
ClinGen gnomAD |
|
|
rs1485915985 COSM1423700 CA352997601 |
37 | G>V | large_intestine [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs1017557847 CA16040295 COSM48276 |
37 | G>W | lung [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
rs754974662 CA352997594 |
39 | L>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs754974662 CA352997593 |
39 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA352997561 rs1442401020 |
44 | N>S | No |
ClinGen gnomAD |
|
|
CA74106283 rs867954944 |
47 | V>F | No |
ClinGen Ensembl |
|
|
rs1277824616 CA352997536 |
48 | T>I | No |
ClinGen gnomAD |
|
|
CA74106277 rs578041713 |
49 | M>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1308568476 CA352997518 |
51 | Q>E | No |
ClinGen gnomAD |
|
|
rs1428867403 CA352997513 |
51 | Q>H | No |
ClinGen gnomAD |
|
|
rs1479981301 CA352997501 |
53 | Q>H | No |
ClinGen TOPMed |
|
|
rs746970478 CA2372237 |
53 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
CA352997497 rs1358542494 |
54 | G>S | No |
ClinGen gnomAD |
|
| TCGA novel | 55 | L>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs779797154 CA2372236 |
56 | G>D | No |
ClinGen ExAC gnomAD |
|
|
rs1221030472 CA352997455 |
59 | Y>D | No |
ClinGen gnomAD |
|
|
CA352997430 rs1293991664 |
62 | P>S | No |
ClinGen gnomAD |
|
|
rs149296597 CA2372224 |
64 | E>Q | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs997089589 CA74105487 |
65 | V>M | No |
ClinGen Ensembl |
|
|
CA352997400 rs1375182423 |
67 | N>D | No |
ClinGen gnomAD |
|
|
rs1202488744 CA352997383 |
69 | S>C | No |
ClinGen TOPMed |
|
|
rs1202488744 CA352997384 |
69 | S>G | No |
ClinGen TOPMed |
|
|
rs1423565683 CA352997374 |
70 | N>T | No |
ClinGen gnomAD |
|
|
rs1164990312 CA352997368 |
71 | L>V | No |
ClinGen gnomAD |
|
|
rs1409184968 CA352997360 |
72 | Q>R | No |
ClinGen gnomAD |
|
|
CA352997353 rs1380293119 |
73 | R>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA352997348 rs1183145054 |
74 | M>V | No |
ClinGen gnomAD |
|
|
rs746453844 CA2372220 |
75 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs780074569 CA2372219 |
76 | S>F | No |
ClinGen ExAC gnomAD |
|
|
rs372589757 CA74105461 |
77 | S>A | No |
ClinGen Ensembl |
|
|
CA16040297 rs1432423624 |
77 | S>C | No |
ClinGen TOPMed |
|
|
CA352997325 rs1396873792 |
78 | E>Q | No |
ClinGen TOPMed |
|
|
rs1271289307 CA352997308 |
80 | T>I | No |
ClinGen gnomAD |
|
| TCGA novel | 81 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1414846913 CA352997293 |
82 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
CA74104104 rs759966798 |
83 | G>D | No |
ClinGen ExAC gnomAD |
|
|
CA2372195 rs759966798 |
83 | G>V | No |
ClinGen ExAC gnomAD |
|
|
CA2372193 rs749046270 |
87 | D>E | No |
ClinGen ExAC gnomAD |
|
|
CA2372192 VAR_020932 rs3731499 |
88 | S>F | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen UniProt ESP ExAC NCI-TCGA TOPMed dbSNP gnomAD |
|
rs1216333941 CA352997240 |
89 | P>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs939641591 CA74104054 |
89 | P>S | No |
ClinGen Ensembl |
|
|
CA352997242 rs939641591 |
89 | P>T | No |
ClinGen Ensembl |
|
|
rs1318350979 CA352997233 |
90 | G>E | No |
ClinGen TOPMed gnomAD |
|
|
rs756265772 CA2372191 |
91 | P>Q | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 91 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs781124013 CA2372189 |
93 | D>G | No |
ClinGen ExAC gnomAD |
|
|
rs1168839398 CA352997211 |
94 | S>G | No |
ClinGen gnomAD |
|
|
CA2372188 rs755018719 |
96 | E>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs747049751 CA2372165 |
99 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs199758768 CA74103582 |
100 | N>K | No |
ClinGen Ensembl |
|
|
CA352997148 rs1353686764 |
101 | P>A | No |
ClinGen gnomAD |
|
|
rs1290337332 CA352997142 |
102 | M>V | No |
ClinGen gnomAD |
|
|
rs1186742351 CA16040296 |
105 | I>T | No |
ClinGen TOPMed |
|
|
rs750847449 CA2372162 |
107 | S>C | No |
ClinGen ExAC gnomAD |
|
|
rs148317132 CA2372163 |
107 | S>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs765515421 CA2372161 |
109 | P>T | No |
ClinGen ExAC gnomAD |
|
|
rs371158913 CA74103050 |
110 | Q>R | No |
ClinGen ESP TOPMed |
|
|
rs747141888 CA2372148 |
115 | C>Y | No |
ClinGen ExAC gnomAD |
|
|
rs1316172013 CA352997023 |
118 | A>S | No |
ClinGen gnomAD |
|
|
rs758971374 CA2372146 |
118 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA352997017 rs1379153510 |
119 | L>P | No |
ClinGen TOPMed |
|
|
CA352996966 rs746366227 |
126 | S>C | No |
ClinGen ExAC gnomAD |
|
|
CA2372145 rs746366227 |
126 | S>F | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 127 | L>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs963371313 CA74103017 |
127 | L>R | No |
ClinGen Ensembl |
|
|
rs143367735 CA2372144 |
128 | D>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA352996951 rs1400207543 |
129 | H>Y | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 130 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs149186214 CA2372142 |
131 | I>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs923345015 CA74102974 |
132 | F>C | No |
ClinGen TOPMed gnomAD |
|
|
CA74102970 rs770406262 |
133 | Q>K | No |
ClinGen Ensembl |
|
|
rs1559964260 CA352996907 |
135 | I>T | No |
ClinGen Ensembl |
|
|
rs142011702 CA2372139 |
136 | D>N | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1317881336 CA352996885 |
138 | D>E | No |
ClinGen TOPMed |
|
|
rs765988410 CA2372138 |
138 | D>H | No |
ClinGen ExAC gnomAD |
|
|
CA74102939 rs375655166 |
140 | N>D | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA352996876 rs375655166 |
140 | N>H | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs762490889 CA2372137 |
140 | N>K | No |
ClinGen ExAC gnomAD |
|
|
CA2372120 rs757877366 |
144 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs375690864 CA2372119 |
145 | A>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA2372118 rs375690864 |
145 | A>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA352996809 rs1381790980 |
147 | E>D | No |
ClinGen gnomAD |
|
|
rs761798691 CA2372117 |
148 | F>L | No |
ClinGen ExAC gnomAD |
|
|
CA352996763 rs1367549377 |
154 | P>R | No |
ClinGen gnomAD |
|
|
CA2372115 rs763881238 |
154 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA352996761 rs1321477720 |
155 | V>I | No |
ClinGen gnomAD |
|
|
CA2372114 rs760406123 |
157 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2372113 rs372655408 |
157 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs372655408 CA2372112 |
157 | R>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA74101647 rs770572616 |
158 | G>V | No |
ClinGen Ensembl |
|
|
CA352996734 rs1182313958 |
159 | C>W | No |
ClinGen gnomAD |
|
|
CA352996736 rs1308116667 |
159 | C>Y | No |
ClinGen TOPMed |
|
|
rs774470623 CA352996730 |
160 | L>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs774470623 CA2372110 |
160 | L>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2372109 rs771404791 |
161 | H>R | No |
ClinGen ExAC gnomAD |
|
|
CA2372107 rs778364050 |
163 | H>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2372108 rs778364050 |
163 | H>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2372106 rs749272262 |
164 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 167 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1250986434 CA352996679 |
168 | G>D | No |
ClinGen gnomAD |
|
|
CA352996676 rs1460429462 |
169 | K>E | No |
ClinGen TOPMed |
|
|
CA2372104 rs779890422 |
169 | K>N | No |
ClinGen ExAC gnomAD |
|
|
rs748482211 CA2372105 |
169 | K>R | No |
ClinGen ExAC gnomAD |
|
|
CA2372103 rs758047372 |
171 | L>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2372100 rs756655625 |
173 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs778482044 CA2372101 |
173 | T>P | No |
ClinGen ExAC gnomAD |
|
|
CA2372098 rs753788423 |
174 | Q>K | No |
ClinGen ExAC |
|
|
CA74101597 rs553480894 |
175 | R>S | No |
ClinGen TOPMed |
|
|
rs1397621878 CA352996629 |
176 | Q>R | No |
ClinGen gnomAD |
|
|
CA352996621 rs1370833186 |
177 | N>S | No |
ClinGen TOPMed gnomAD |
|
|
rs760496535 CA352996611 |
179 | A>S | No |
ClinGen ExAC gnomAD |
|
|
CA2372096 rs760496535 |
179 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA2372095 rs752459968 |
179 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA74101588 rs1046395415 |
180 | P>S | No |
ClinGen Ensembl |
|
|
rs774367168 CA2372092 |
181 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs6771386 CA74101577 VAR_023532 |
182 | R>G | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA352996596 rs762890600 |
182 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs762890600 CA352996597 |
182 | R>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs762890600 CA2372090 |
182 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs6771386 VAR_023533 CA2372091 |
182 | R>W | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs773402032 CA2372071 |
184 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA352996558 rs1235253089 |
186 | S>L | No |
ClinGen TOPMed |
|
|
CA352996541 rs1286482102 |
189 | R>G | No |
ClinGen TOPMed |
|
|
CA352996530 rs1379992426 |
190 | D>G | No |
ClinGen gnomAD |
|
|
rs1289950255 CA352996513 |
192 | S>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs975405163 CA74099806 |
194 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1209816456 CA352996486 |
196 | N>I | No |
ClinGen TOPMed |
|
|
rs371829889 CA2372065 |
202 | T>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1230259689 CA352996440 |
203 | P>H | No |
ClinGen gnomAD |
|
|
rs748848895 CA2372063 |
205 | S>L | No |
ClinGen ExAC gnomAD |
|
|
CA2372061 rs756114919 |
206 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs1260973619 CA352996419 |
207 | V>M | No |
ClinGen gnomAD |
|
|
rs780939908 CA2372060 |
208 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA352996410 rs1323858064 |
208 | T>I | No |
ClinGen gnomAD |
|
|
rs780939908 CA2372059 |
208 | T>P | No |
ClinGen ExAC gnomAD |
|
|
rs1471973544 CA352996389 |
212 | S>P | No |
ClinGen TOPMed |
|
|
rs368466847 CA74099774 |
216 | D>G | No |
ClinGen ESP TOPMed |
|
|
CA352996349 rs1437849797 |
217 | G>A | No |
ClinGen gnomAD |
|
|
rs758679809 CA2372055 |
219 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs1166313990 CA352996312 |
223 | D>G | No |
ClinGen gnomAD |
|
|
COSM1692730 CA2372053 rs374368943 |
223 | D>N | Variant assessed as Somatic; 0.0 impact. skin [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1416482643 CA352996307 |
224 | G>R | No |
ClinGen TOPMed |
|
|
rs1020851978 CA352996285 |
227 | L>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs1575269246 CA352996228 |
233 | T>P | No |
ClinGen Ensembl |
|
|
rs368546115 CA2372030 |
235 | S>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs757446929 CA2372027 |
236 | C>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs753832415 CA2372026 |
238 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA2372025 rs764713762 |
243 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2372023 rs572329670 |
247 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA352996101 rs1278190917 |
252 | L>F | No |
ClinGen gnomAD |
|
|
rs1453872017 CA352996078 |
253 | D>E | No |
ClinGen gnomAD |
|
|
rs1282758196 CA352996067 |
255 | R>* | No |
ClinGen TOPMed gnomAD |
|
|
rs757533603 CA2372007 |
255 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs1426856754 CA352996057 |
256 | C>W | No |
ClinGen gnomAD |
|
|
rs777714148 CA2372005 |
259 | F>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA352996023 rs1221874604 |
261 | S>F | No |
ClinGen gnomAD |
|
|
rs1344994486 CA352996017 |
262 | P>H | No |
ClinGen gnomAD |
|
|
rs1344994486 CA352996019 |
262 | P>R | No |
ClinGen gnomAD |
|
|
rs1284058954 CA352996012 |
263 | S>C | No |
ClinGen gnomAD |
|
|
rs753163764 CA2372003 |
265 | C>Y | No |
ClinGen ExAC gnomAD |
|
|
CA352995989 rs1316064498 |
267 | S>P | No |
ClinGen TOPMed gnomAD |
|
|
rs1316064498 CA352995990 |
267 | S>T | No |
ClinGen TOPMed gnomAD |
|
|
CA2372002 rs370021624 |
268 | S>G | No |
ClinGen ESP ExAC gnomAD |
|
|
rs759930362 CA2372001 |
268 | S>T | No |
ClinGen ExAC gnomAD |
|
|
CA74097399 rs892713120 |
270 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1160952995 CA352995971 |
270 | R>W | No |
ClinGen gnomAD |
|
|
CA352995965 rs1457691309 |
271 | S>L | No |
ClinGen TOPMed |
|
|
CA352995962 rs1575267185 |
272 | V>M | No |
ClinGen Ensembl |
|
|
CA2372000 rs751897112 |
273 | L>W | No |
ClinGen ExAC gnomAD |
|
|
CA352995924 rs1478719805 |
277 | E>G | No |
ClinGen TOPMed gnomAD |
|
|
CA352995918 rs764925971 |
278 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs764925971 CA352995919 |
278 | R>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs764925971 CA2371999 |
278 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs139580687 CA2371998 |
279 | S>P | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs200256458 CA2371996 |
287 | S>N | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1202146674 CA352995855 |
288 | T>A | No |
ClinGen gnomAD |
|
|
rs760183973 CA2371995 |
290 | R>K | No |
ClinGen ExAC gnomAD |
|
|
CA74097334 rs937509845 |
294 | M>L | No |
ClinGen gnomAD |
|
|
rs1268373128 CA352995783 |
298 | S>I | No |
ClinGen gnomAD |
|
|
rs1429877608 CA352995781 |
298 | S>R | No |
ClinGen gnomAD |
|
|
CA2371993 rs772104840 |
299 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs1322341488 CA352995774 |
300 | K>E | No |
ClinGen gnomAD |
|
|
rs745707698 CA2371992 |
300 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs201170431 CA352995765 |
301 | E>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA2371991 rs201170431 |
301 | E>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs771254010 CA2371990 |
303 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs373341230 CA2371989 |
306 | E>D | No |
ClinGen ESP ExAC |
|
|
CA2371986 rs748224977 |
309 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs1392631890 CA352995457 |
311 | T>S | No |
ClinGen TOPMed gnomAD |
|
|
rs748282795 CA2371967 |
311 | T>S | No |
ClinGen ExAC gnomAD |
|
|
rs1444437184 CA352995449 |
312 | L>F | No |
ClinGen gnomAD |
|
|
CA352995416 rs1414911698 |
314 | Q>R | No |
ClinGen gnomAD |
|
|
rs1002042589 CA74093629 |
315 | S>C | No |
ClinGen Ensembl |
|
|
rs1183940647 CA352995377 |
317 | S>A | No |
ClinGen gnomAD |
|
|
CA2371966 rs141219026 |
317 | S>Y | No |
ClinGen 1000Genomes ExAC |
|
|
CA2371963 rs551768306 |
318 | L>P | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA2371961 rs750770255 |
320 | S>P | No |
ClinGen ExAC gnomAD |
|
|
CA352995339 rs1575262569 |
320 | S>Y | No |
ClinGen Ensembl |
|
|
rs150267735 CA2371960 |
321 | S>F | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs138476071 CA2371959 |
322 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs138476071 CA352995312 |
322 | P>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs202026442 CA2371956 |
323 | K>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1025516505 CA74093570 |
329 | I>V | No |
ClinGen Ensembl |
|
|
rs766305671 CA2371954 |
331 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
rs373510424 CA2371953 |
332 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA352995137 rs1371823897 |
335 | R>M | No |
ClinGen gnomAD |
|
| TCGA novel | 337 | L>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA74092644 rs1023788242 |
344 | G>R | No |
ClinGen Ensembl |
|
|
CA2371931 rs201430835 |
349 | T>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs776869712 CA2371930 |
350 | V>F | No |
ClinGen ExAC gnomAD |
|
|
rs1433833507 CA352994920 |
351 | A>S | No |
ClinGen gnomAD |
|
|
rs1267989083 CA352994919 |
351 | A>V | No |
ClinGen gnomAD |
|
|
rs1192783624 CA352994862 |
359 | Y>D | No |
ClinGen gnomAD |
|
|
rs1184223304 CA352994840 |
362 | P>A | No |
ClinGen gnomAD |
|
|
CA2371928 rs142106531 |
362 | P>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA gnomAD |
|
CA352994826 rs1249755586 |
364 | I>V | No |
ClinGen gnomAD |
|
|
rs1257301594 CA352994808 |
365 | M>V | No |
ClinGen gnomAD |
|
|
CA352994800 rs1224575878 |
366 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs529680138 CA2371910 |
373 | F>L | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA2371909 rs565583599 |
375 | N>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs767652640 CA2371907 |
378 | K>E | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 380 | F>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1404579098 CA352994696 |
381 | V>I | No |
ClinGen TOPMed gnomAD |
|
|
rs1404579098 CA352994697 |
381 | V>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1303046794 CA352994683 |
383 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
CA2371901 rs532141329 |
392 | E>D | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs773575919 CA2371902 |
392 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1366445708 CA352994603 |
394 | G>D | No |
ClinGen gnomAD |
|
|
rs1490552698 CA352994558 |
398 | G>A | No |
ClinGen TOPMed |
|
|
rs1289775548 CA352994519 |
404 | M>L | No |
ClinGen gnomAD |
|
|
CA2371877 rs376412421 |
406 | E>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1259212402 CA352994485 |
408 | V>A | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs745760078 CA2371876 |
411 | F>Y | No |
ClinGen ExAC gnomAD |
|
|
CA74091455 rs749638499 |
418 | V>E | No |
ClinGen TOPMed gnomAD |
|
|
rs879655966 CA352994417 |
418 | V>I | No |
ClinGen gnomAD |
|
|
rs879655966 CA74091460 |
418 | V>L | No |
ClinGen gnomAD |
|
|
rs144093017 CA2371873 |
420 | T>I | No |
ClinGen ESP ExAC gnomAD |
|
|
CA352994339 rs1183786591 |
430 | H>Y | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 440 | R>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA352994130 rs1208232296 |
441 | M>I | No |
ClinGen gnomAD |
|
|
CA352994122 rs1346670060 |
442 | C>Y | No |
ClinGen Ensembl |
|
|
CA74088864 rs867146912 |
443 | R>L | No |
ClinGen Ensembl |
|
|
CA352994118 COSM190122 rs1441940642 |
443 | R>W | large_intestine haematopoietic_and_lymphoid_tissue [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA2371853 rs747774747 |
452 | G>D | No |
ClinGen ExAC gnomAD |
|
|
CA2371852 rs148722197 |
457 | K>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA74088847 rs1054030001 |
459 | H>Y | No |
ClinGen TOPMed |
|
| TCGA novel | 461 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 469 | G>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 470 | Y>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 472 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1358182558 CA352993896 |
475 | M>K | No |
ClinGen gnomAD |
|
|
rs1169800358 CA352993841 |
480 | Y>F | No |
ClinGen TOPMed |
|
|
CA2371828 rs746309630 |
482 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA2371829 rs746309630 |
482 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA352993811 rs1463555771 |
485 | S>G | No |
ClinGen TOPMed |
|
|
rs925063767 CA74088629 |
485 | S>N | No |
ClinGen TOPMed |
|
|
CA2371826 rs376309884 |
487 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs149642245 CA2371827 |
487 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA gnomAD |
|
CA352993777 rs1219130230 |
490 | H>Y | No |
ClinGen gnomAD |
|
| TCGA novel | 491 | H>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs753838385 CA2371825 COSM1045727 |
492 | E>K | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs753838385 CA74088614 |
492 | E>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2371824 rs764271295 |
493 | D>G | No |
ClinGen ExAC |
|
|
rs878906222 CA74088610 |
494 | F>V | No |
ClinGen Ensembl |
|
|
CA2371823 rs756286568 |
497 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA352993707 rs1348217909 |
500 | K>E | No |
ClinGen gnomAD |
|
|
rs766101355 CA2371821 |
502 | R>C | Variant assessed as Somatic; 4.619e-05 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs762736214 CA2371820 |
502 | R>H | No |
ClinGen ExAC gnomAD |
|
|
rs1457746097 CA352993677 |
504 | K>R | No |
ClinGen gnomAD |
|
|
CA352993661 rs1167314662 COSM48275 |
506 | R>Q | lung Variant assessed as Somatic; 0.0 impact. large_intestine [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
| TCGA novel | 506 | R>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA74088548 rs530558773 |
509 | A>G | No |
ClinGen Ensembl |
|
|
CA352993633 rs1024619739 |
511 | E>K | No |
ClinGen TOPMed |
|
|
CA74088545 rs1024619739 |
511 | E>Q | No |
ClinGen TOPMed |
|
|
rs1222752213 CA352993574 |
518 | Y>C | No |
ClinGen TOPMed |
|
|
CA74088530 rs1023272838 |
519 | S>R | No |
ClinGen TOPMed gnomAD |
|
|
rs768305047 CA2371815 |
519 | S>T | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 520 | R>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA2371814 rs746603686 |
520 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
No associated diseases with P30304
1 regional properties for P30304
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Rhodanese-like domain | 366 - 482 | IPR001763 |
Functions
| Description | ||
|---|---|---|
| EC Number | 3.1.3.48 | Phosphoric monoester hydrolases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
4 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
4 GO annotations of molecular function
| Name | Definition |
|---|---|
| chaperone binding | Binding to a chaperone protein, a class of proteins that bind to nascent or unfolded polypeptides and ensure correct folding or transport. |
| phosphoprotein phosphatase activity | Catalysis of the reaction: a phosphoprotein + H2O = a protein + phosphate. Together with protein kinases, these enzymes control the state of phosphorylation of cellular proteins and thereby provide an important mechanism for regulating cellular activity. |
| protein kinase binding | Binding to a protein kinase, any enzyme that catalyzes the transfer of a phosphate group, usually from ATP, to a protein substrate. |
| protein tyrosine phosphatase activity | Catalysis of the reaction: protein tyrosine phosphate + H2O = protein tyrosine + phosphate. |
10 GO annotations of biological process
| Name | Definition |
|---|---|
| cell division | The process resulting in division and partitioning of components of a cell to form more cells; may or may not be accompanied by the physical separation of a cell into distinct, individually membrane-bounded daughter cells. |
| cell population proliferation | The multiplication or reproduction of cells, resulting in the expansion of a cell population. |
| cellular response to UV | Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of an ultraviolet radiation (UV light) stimulus. Ultraviolet radiation is electromagnetic radiation with a wavelength in the range of 10 to 380 nanometers. |
| G1/S transition of mitotic cell cycle | The mitotic cell cycle transition by which a cell in G1 commits to S phase. The process begins with the build up of G1 cyclin-dependent kinase (G1 CDK), resulting in the activation of transcription of G1 cyclins. The process ends with the positive feedback of the G1 cyclins on the G1 CDK which commits the cell to S phase, in which DNA replication is initiated. |
| G2/M transition of mitotic cell cycle | The mitotic cell cycle transition by which a cell in G2 commits to M phase. The process begins when the kinase activity of M cyclin/CDK complex reaches a threshold high enough for the cell cycle to proceed. This is accomplished by activating a positive feedback loop that results in the accumulation of unphosphorylated and active M cyclin/CDK complex. |
| positive regulation of G2/M transition of mitotic cell cycle | Any signalling pathway that activates or increases the activity of a cell cycle cyclin-dependent protein kinase to modulate the switch from G2 phase to M phase of the mitotic cell cycle. |
| positive regulation of G2/MI transition of meiotic cell cycle | Any signalling pathway that activates or increases the activity of a cell cycle cyclin-dependent protein kinase to modulate the switch from G2 phase to MI phase of the meiotic cell cycle. |
| protein dephosphorylation | The process of removing one or more phosphoric residues from a protein. |
| regulation of cyclin-dependent protein serine/threonine kinase activity | Any process that modulates the frequency, rate or extent of cyclin-dependent protein serine/threonine kinase activity. |
| response to radiation | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of an electromagnetic radiation stimulus. Electromagnetic radiation is a propagating wave in space with electric and magnetic components. These components oscillate at right angles to each other and to the direction of propagation. |
4 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P20483 | stg | M-phase inducer phosphatase | Drosophila melanogaster (Fruit fly) | PR |
| P30305 | CDC25B | M-phase inducer phosphatase 2 | Homo sapiens (Human) | PR |
| P30306 | Cdc25b | M-phase inducer phosphatase 2 | Mus musculus (Mouse) | PR |
| Q336V5 | ACR2.1 | Arsenate reductase 2.1 | Oryza sativa subsp japonica (Rice) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MELGPEPPHR | RRLLFACSPP | PASQPVVKAL | FGASAAGGLS | PVTNLTVTMD | QLQGLGSDYE |
| 70 | 80 | 90 | 100 | 110 | 120 |
| QPLEVKNNSN | LQRMGSSEST | DSGFCLDSPG | PLDSKENLEN | PMRRIHSLPQ | KLLGCSPALK |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RSHSDSLDHD | IFQLIDPDEN | KENEAFEFKK | PVRPVSRGCL | HSHGLQEGKD | LFTQRQNSAP |
| 190 | 200 | 210 | 220 | 230 | 240 |
| ARMLSSNERD | SSEPGNFIPL | FTPQSPVTAT | LSDEDDGFVD | LLDGENLKNE | EETPSCMASL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| WTAPLVMRTT | NLDNRCKLFD | SPSLCSSSTR | SVLKRPERSQ | EESPPGSTKR | RKSMSGASPK |
| 310 | 320 | 330 | 340 | 350 | 360 |
| ESTNPEKAHE | TLHQSLSLAS | SPKGTIENIL | DNDPRDLIGD | FSKGYLFHTV | AGKHQDLKYI |
| 370 | 380 | 390 | 400 | 410 | 420 |
| SPEIMASVLN | GKFANLIKEF | VIIDCRYPYE | YEGGHIKGAV | NLHMEEEVED | FLLKKPIVPT |
| 430 | 440 | 450 | 460 | 470 | 480 |
| DGKRVIVVFH | CEFSSERGPR | MCRYVRERDR | LGNEYPKLHY | PELYVLKGGY | KEFFMKCQSY |
| 490 | 500 | 510 | 520 | ||
| CEPPSYRPMH | HEDFKEDLKK | FRTKSRTWAG | EKSKREMYSR | LKKL |