P05455
Gene name |
SSB |
Protein name |
Lupus La protein |
Names |
La autoantigen, La ribonucleoprotein, Sjoegren syndrome type B antigen, SS-B |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:6741 |
EC number |
|
Protein Class |
|
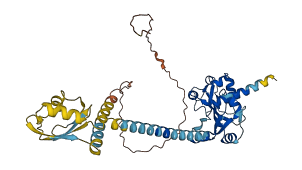
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
10 structures for P05455
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1OWX | NMR | - | A | 225-334 | PDB |
| 1S79 | NMR | - | A | 105-202 | PDB |
| 1S7A | NMR | - | A | 1-103 | PDB |
| 1YTY | X-ray | 229 A | A/B | 1-194 | PDB |
| 1ZH5 | X-ray | 185 A | A/B | 1-194 | PDB |
| 2VOD | X-ray | 210 A | A/B | 4-194 | PDB |
| 2VON | X-ray | 210 A | A/B | 4-194 | PDB |
| 2VOO | X-ray | 180 A | A/B | 4-194 | PDB |
| 2VOP | X-ray | 280 A | A | 4-194 | PDB |
| AF-P05455-F1 | Predicted | AlphaFoldDB |
224 variants for P05455
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA1959089 rs546772759 |
2 | A>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA1959091 rs747161057 |
4 | N>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs776632185 CA1959093 |
6 | D>G | No |
ClinGen ExAC gnomAD |
|
|
rs1438499171 CA348875637 |
7 | N>D | No |
ClinGen gnomAD |
|
|
CA348875716 rs1273050684 |
10 | M>V | No |
ClinGen gnomAD |
|
|
rs146485470 CA1959094 |
12 | A>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA1959095 rs367922508 |
13 | L>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1297190319 CA348875831 |
15 | A>S | No |
ClinGen gnomAD |
|
|
rs1352326179 CA348875962 |
19 | H>Y | No |
ClinGen TOPMed |
|
|
rs1318082149 CA348879025 |
26 | G>S | No |
ClinGen gnomAD |
|
|
CA348879052 rs1318117371 |
27 | D>N | No |
ClinGen TOPMed |
|
|
CA348879113 rs1252719505 |
29 | N>D | No |
ClinGen TOPMed |
|
|
CA1959115 rs769907654 COSM3787890 |
29 | N>S | pancreas [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs566356422 CA1959117 |
32 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1959118 rs771484976 |
33 | D>N | No |
ClinGen ExAC gnomAD |
|
|
rs905545381 CA59566712 |
34 | K>R | No |
ClinGen TOPMed |
|
|
CA59566715 rs267599002 |
39 | Q>H | No |
ClinGen Ensembl |
|
|
rs1374635098 CA348879470 |
39 | Q>R | No |
ClinGen TOPMed |
|
|
CA1959119 rs774515446 |
41 | K>T | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 41 | K>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA348879641 rs1290474636 |
45 | G>A | No |
ClinGen TOPMed gnomAD |
|
|
CA59566730 rs3191574 |
48 | P>S | No |
ClinGen Ensembl |
|
|
CA59566746 rs911514709 |
53 | I>T | No |
ClinGen gnomAD |
|
|
CA1959122 rs532347388 |
53 | I>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1358069216 CA348879934 |
56 | N>K | No |
ClinGen gnomAD |
|
|
rs918728303 CA59566801 |
60 | R>C | No |
ClinGen TOPMed gnomAD |
|
|
CA59566802 rs891627030 COSM1009367 |
60 | R>H | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
CA348880133 rs1333146440 |
63 | T>A | No |
ClinGen gnomAD |
|
|
rs1336724784 CA348880156 |
64 | D>E | No |
ClinGen gnomAD |
|
|
rs774983377 CA348880199 CA1959137 |
66 | N>K | No |
ClinGen ExAC gnomAD |
|
|
rs772605830 CA1959138 |
68 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA59566821 rs1009985222 |
71 | A>V | No |
ClinGen TOPMed |
|
|
rs1343007959 CA348880301 |
73 | S>G | No |
ClinGen gnomAD |
|
|
rs548069992 CA1959141 |
77 | A>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA1959142 rs753217349 |
78 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA1959143 rs761453238 |
79 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA348880437 rs761453238 |
79 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs141623414 CA1959146 |
80 | M>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs765070949 CA1959145 |
80 | M>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs765070949 CA1959144 |
80 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA348880614 rs1439034558 |
84 | E>D | No |
ClinGen gnomAD |
|
|
rs568279000 CA1959148 |
93 | P>S | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA348880964 rs751375349 |
94 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs751375349 CA1959149 |
94 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA348881048 rs1396770481 |
96 | P>L | No |
ClinGen gnomAD |
|
|
rs1159787253 CA348881030 |
96 | P>S | No |
ClinGen TOPMed |
|
|
CA1959150 rs756264443 |
103 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1400085380 CA348881411 |
107 | D>Y | No |
ClinGen gnomAD |
|
|
rs749319622 CA1959152 |
108 | V>L | No |
ClinGen ExAC gnomAD |
|
|
CA1959153 rs537120356 |
110 | N>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA59566906 rs879196529 |
113 | V>I | No |
ClinGen Ensembl |
|
|
CA1959156 rs377101371 |
114 | Y>F | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA348881804 rs1220189594 |
115 | I>M | No |
ClinGen gnomAD |
|
|
CA1959157 rs557065020 |
115 | I>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs757444172 CA1959193 |
120 | T>A | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs1183288270 CA348882409 |
121 | D>G | No |
ClinGen gnomAD |
|
|
rs887376306 CA59567510 |
121 | D>Y | No |
ClinGen Ensembl |
|
|
rs1236503677 CA348882458 |
122 | A>G | No |
ClinGen TOPMed |
|
|
CA348882555 rs1254474557 |
125 | D>N | No |
ClinGen gnomAD |
|
|
CA1959194 rs372066287 |
127 | I>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA348882660 rs1558971269 |
127 | I>R | No |
ClinGen Ensembl |
|
| TCGA novel | 129 | E>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA1959195 rs200789540 |
131 | L>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1392147580 CA348882897 |
133 | D>E | No |
ClinGen TOPMed |
|
|
rs1558971287 CA348882877 |
133 | D>N | No |
ClinGen Ensembl |
|
|
rs1573960351 CA348882931 |
135 | G>C | No |
ClinGen Ensembl |
|
|
rs147074057 CA1959196 |
136 | Q>* | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1359864396 CA348882972 |
137 | V>I | No |
ClinGen gnomAD |
|
|
rs747558417 CA1959198 |
140 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs376401398 CA1959199 |
147 | H>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA1959200 rs376401398 |
147 | H>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs546270676 CA1959201 |
149 | A>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA348883335 rs546270676 |
149 | A>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA1959202 rs769419286 |
150 | F>S | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 151 | K>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 152 | G>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1311333446 CA348883600 |
153 | S>T | No |
ClinGen gnomAD |
|
|
CA348883630 rs1558971367 |
154 | I>T | No |
ClinGen Ensembl |
|
|
CA348883619 rs1469063925 |
154 | I>V | No |
ClinGen gnomAD |
|
|
CA348883680 rs1278992679 |
155 | F>L | No |
ClinGen TOPMed |
|
| TCGA novel | 162 | E>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs12467132 CA59567675 |
164 | A>D | No |
ClinGen Ensembl |
|
|
rs1402256361 CA348883903 |
164 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
rs760452732 CA1959214 |
166 | K>E | No |
ClinGen ExAC gnomAD |
|
|
CA348884055 rs1330673910 |
168 | V>I | No |
ClinGen gnomAD |
|
|
CA1959217 rs186344908 |
171 | P>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA59567693 rs369947209 |
178 | T>A | No |
ClinGen ESP gnomAD |
|
|
CA1959219 rs751610012 |
179 | D>E | No |
ClinGen ExAC gnomAD |
|
|
rs753095047 CA1959222 |
182 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA348884436 rs1253703360 |
183 | L>F | No |
ClinGen TOPMed gnomAD |
|
|
CA1959223 rs756488413 |
184 | F>L | No |
ClinGen ExAC gnomAD |
|
|
CA348885640 rs1162673929 |
187 | D>N | No |
ClinGen TOPMed gnomAD |
|
|
rs1364389649 CA348885714 |
188 | Y>C | No |
ClinGen gnomAD |
|
|
CA348885814 COSM1009370 rs1419788745 |
191 | K>N | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
| rs753297385 | 193 | N>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
| rs753297385 | 193 | N>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA348885924 rs1573961460 |
194 | E>G | No |
ClinGen Ensembl |
|
|
rs1338004524 CA348885947 |
195 | E>G | No |
ClinGen gnomAD |
|
|
CA1959249 rs745368217 |
196 | R>G | No |
ClinGen ExAC gnomAD |
|
|
CA59568691 rs143377617 COSM106601 |
196 | R>K | skin [Cosmic] | No |
ClinGen cosmic curated Ensembl |
|
COSM108293 CA59568705 rs146255324 |
198 | Q>K | skin [Cosmic] | No |
ClinGen cosmic curated Ensembl |
|
rs139396181 COSM109894 CA59568713 |
199 | N>K | skin [Cosmic] | No |
ClinGen cosmic curated Ensembl |
| TCGA novel | 201 | V>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1170235931 CA348886246 |
207 | A>G | No |
ClinGen gnomAD |
|
|
rs779383125 CA1959271 |
209 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1227101487 CA348886295 |
209 | Q>K | No |
ClinGen gnomAD |
|
|
CA59568967 rs940739370 |
210 | E>Q | No |
ClinGen TOPMed |
|
|
rs139144686 CA1959272 |
210 | E>V | No |
ClinGen ESP ExAC gnomAD |
|
|
CA1959273 rs754892743 |
211 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
CA59568990 rs866315535 |
213 | A>T | No |
ClinGen Ensembl |
|
|
CA1959276 rs747940610 |
215 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
CA1959277 rs76002866 |
217 | L>S | No |
ClinGen 1000Genomes ESP TOPMed gnomAD |
|
|
rs1377932338 CA348886702 |
218 | E>Q | No |
ClinGen gnomAD |
|
|
CA1959279 rs145573186 |
219 | E>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs142716482 CA1959280 |
220 | D>A | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs368954177 CA1959281 |
221 | A>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs772353316 CA1959282 |
222 | E>D | No |
ClinGen ExAC gnomAD |
|
|
CA348886836 rs1336518068 |
223 | M>T | No |
ClinGen gnomAD |
|
|
CA1959324 rs768885266 |
226 | L>Q | No |
ClinGen ExAC gnomAD |
|
|
rs201142063 CA1959323 |
226 | L>V | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA1959325 rs781186776 |
227 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA1959326 rs748264074 |
229 | K>R | No |
ClinGen ExAC gnomAD |
|
|
CA59570378 rs374153062 |
232 | C>Y | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs773826217 CA1959328 |
237 | S>L | No |
ClinGen ExAC TOPMed |
|
|
CA348888639 rs1444030710 |
241 | D>G | No |
ClinGen gnomAD |
|
|
CA348888622 rs1291798115 |
241 | D>N | No |
ClinGen TOPMed |
|
|
rs771385009 CA1959330 |
244 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs1247538983 CA348888741 |
246 | R>G | No |
ClinGen TOPMed |
|
|
rs4813 CA59570413 |
247 | E>G | No |
ClinGen ESP TOPMed |
|
|
rs4813 CA59570414 |
247 | E>V | No |
ClinGen ESP TOPMed |
|
|
CA1959331 rs774879990 |
248 | D>N | No |
ClinGen ExAC gnomAD |
|
|
rs1296401220 CA348888824 |
250 | H>Y | No |
ClinGen TOPMed |
|
|
CA1959333 rs767282588 |
251 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA348889091 rs571911479 |
258 | E>* | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs763919441 CA1959336 |
258 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs571911479 CA1959335 |
258 | E>K | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1309326051 CA348889293 |
265 | V>I | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 269 | K>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1028236877 CA348889406 |
270 | E>* | No |
ClinGen gnomAD |
|
|
rs1028236877 CA59570469 |
270 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
| TCGA novel | 271 | G>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1323344081 CA348889703 |
274 | L>V | No |
ClinGen gnomAD |
|
|
CA1959349 rs746301438 |
276 | K>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1029985868 CA59570906 |
282 | A>T | No |
ClinGen TOPMed |
|
|
CA348890182 rs1176724563 |
283 | L>F | No |
ClinGen gnomAD |
|
|
CA348890246 rs1268198088 |
284 | G>V | No |
ClinGen gnomAD |
|
|
CA1959351 rs775265757 |
287 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs763617054 CA1959353 |
289 | A>E | No |
ClinGen ExAC gnomAD |
|
|
rs776024514 CA348890550 |
292 | G>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1959354 rs776024514 |
292 | G>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs761677581 CA348890755 |
297 | R>S | No |
ClinGen ExAC gnomAD |
|
|
rs143840972 CA1959356 |
298 | N>K | No |
ClinGen ESP ExAC gnomAD |
|
|
rs750214755 CA1959357 |
300 | E>V | No |
ClinGen ExAC gnomAD |
|
|
rs989775196 CA59571013 |
305 | V>I | No |
ClinGen Ensembl |
|
|
CA1959359 rs767702957 |
306 | L>I | No |
ClinGen ExAC gnomAD |
|
|
CA1959360 rs533896111 |
307 | E>G | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1260510662 CA348891031 |
310 | V>M | No |
ClinGen gnomAD |
|
|
CA348891047 rs1268095950 |
311 | E>G | No |
ClinGen TOPMed |
|
|
rs777720784 CA1959361 |
312 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs777853278 CA1959362 |
313 | E>A | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA348891078 rs1204501885 |
313 | E>K | No |
ClinGen gnomAD |
|
|
CA1959364 rs757835858 |
314 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA348891145 rs1197455395 |
316 | K>R | No |
ClinGen gnomAD |
|
|
CA348891277 rs1268463610 |
319 | I>M | No |
ClinGen gnomAD |
|
|
rs1194154895 CA348891348 |
320 | E>D | No |
ClinGen gnomAD |
|
|
rs1421436926 CA348891359 |
321 | D>Y | No |
ClinGen gnomAD |
|
| TCGA novel | 326 | L>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA348891563 rs1308312482 |
327 | N>K | No |
ClinGen TOPMed |
|
|
rs1573963390 CA348891628 |
329 | W>R | No |
ClinGen Ensembl |
|
|
CA1959381 rs760886261 |
334 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA348891958 rs760886261 |
334 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1959382 rs761080670 |
334 | R>H | No |
ClinGen ExAC gnomAD |
|
|
rs753941499 CA1959383 |
335 | R>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA348891993 rs1573963543 |
335 | R>T | No |
ClinGen Ensembl |
|
|
CA1959386 rs757465425 |
337 | K>T | No |
ClinGen ExAC gnomAD |
|
|
rs1244472114 CA348892237 |
341 | K>R | No |
ClinGen gnomAD |
|
|
rs1314437256 CA348892248 |
342 | G>D | No |
ClinGen gnomAD |
|
|
CA348892244 rs1284349421 |
342 | G>S | No |
ClinGen TOPMed |
|
| TCGA novel | 343 | N>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA348892356 rs1304156691 |
344 | K>N | No |
ClinGen TOPMed |
|
|
CA348892347 rs1349178116 |
344 | K>T | No |
ClinGen TOPMed |
|
| TCGA novel | 346 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA348892413 rs1558973597 |
346 | A>V | No |
ClinGen Ensembl |
|
|
CA348892439 rs1558973605 |
347 | Q>H | No |
ClinGen Ensembl |
|
|
CA1959387 rs370543439 |
347 | Q>P | No |
ClinGen ESP ExAC gnomAD |
|
|
rs370543439 CA1959388 |
347 | Q>R | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1390297049 CA348892461 |
349 | G>R | No |
ClinGen TOPMed |
|
|
rs374202019 CA59571188 |
349 | G>V | No |
ClinGen ESP TOPMed |
|
|
CA1959389 rs758993474 |
352 | K>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1959390 rs780405113 |
354 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1237885774 CA348892704 |
356 | Q>H | No |
ClinGen gnomAD |
|
|
CA348892691 rs1255649253 |
356 | Q>P | No |
ClinGen gnomAD |
|
|
CA1959393 rs747335133 |
359 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs780764356 CA1959396 |
362 | T>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1959395 rs780764356 |
362 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 366 | S>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1177202454 CA348892950 |
366 | S>T | No |
ClinGen gnomAD |
|
|
rs762821643 CA1959400 |
367 | D>E | No |
ClinGen ExAC gnomAD |
|
|
CA1959399 rs772739645 |
367 | D>G | No |
ClinGen ExAC gnomAD |
|
|
rs1558973669 CA348892963 |
367 | D>H | No |
ClinGen Ensembl |
|
|
CA1959401 rs377472931 |
368 | D>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1377650498 CA348893027 |
369 | E>K | No |
ClinGen gnomAD |
|
|
rs1053269262 CA59571245 |
370 | H>N | No |
ClinGen TOPMed |
|
|
CA59571253 rs901363673 |
370 | H>R | No |
ClinGen TOPMed |
|
|
rs1350265055 CA348893094 |
371 | D>G | No |
ClinGen gnomAD |
|
|
rs575866793 CA1959403 |
372 | E>Q | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA1959404 rs759308232 |
373 | H>Y | No |
ClinGen ExAC gnomAD |
|
|
CA59571268 rs934249542 |
374 | D>N | No |
ClinGen TOPMed |
|
|
rs1201618687 CA348893170 |
375 | E>A | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA1959405 rs139847090 |
375 | E>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1201618687 CA348893175 |
375 | E>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1308557439 CA348893281 |
379 | T>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs762159811 CA1959407 |
380 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA348894333 rs1358250965 |
381 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA1959430 rs150765079 |
387 | E>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA1959431 rs773416649 |
389 | T>K | No |
ClinGen ExAC gnomAD |
|
|
CA348894476 rs1338105682 |
391 | K>R | No |
ClinGen gnomAD |
|
|
CA1959435 rs766886435 |
395 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs752046045 CA1959436 |
399 | Q>K | No |
ClinGen ExAC gnomAD |
|
|
CA59571641 rs758688051 |
401 | T>I | No |
ClinGen gnomAD |
|
|
CA1959439 rs753066667 |
407 | D>H | No |
ClinGen ExAC gnomAD |
|
|
rs957310075 CA348894788 |
408 | Q>* | No |
ClinGen gnomAD |
|
|
rs957310075 CA59571648 |
408 | Q>K | No |
ClinGen gnomAD |
|
|
CA1959441 rs777460087 |
408 | Q>P | No |
ClinGen ExAC gnomAD |
No associated diseases with P05455
4 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromosome, telomeric region | The end of a linear chromosome, required for the integrity and maintenance of the end. A chromosome telomere usually includes a region of telomerase-encoded repeats the length of which rarely exceeds 20 bp each and that permits the formation of a telomeric loop (T-loop). The telomeric repeat region is usually preceded by a sub-telomeric region that is gene-poor but rich in repetitive elements. Some telomeres only consist of the latter part (for eg. D. melanogaster telomeres). |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| ribonucleoprotein complex | A macromolecular complex that contains both RNA and protein molecules. |
6 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| mRNA binding | Binding to messenger RNA (mRNA), an intermediate molecule between DNA and protein. mRNA includes UTR and coding sequences, but does not contain introns. |
| poly(U) RNA binding | Binding to a sequence of uracil residues in an RNA molecule. |
| RNA binding | Binding to an RNA molecule or a portion thereof. |
| sequence-specific mRNA binding | Binding to messenger RNA (mRNA) of a specific nucleotide composition or a specific sequence motif. |
| tRNA binding | Binding to a transfer RNA. |
9 GO annotations of biological process
| Name | Definition |
|---|---|
| histone mRNA metabolic process | The chemical reactions and pathways involving an mRNA encoding a histone. |
| IRES-dependent viral translational initiation | Process by which viral mRNA translation is initiated, where a domain in the 5' untranslated region (UTR) of the viral mRNA called an internal ribosome entry site (IRES) binds the host 43S preinitiation complex, circumventing regular cap-dependent translation initiation. |
| nuclear histone mRNA catabolic process | The chemical reactions and pathways resulting in the breakdown of histone messenger RNA (mRNA) within the nucleus. |
| protein localization to cytoplasmic stress granule | A process in which a protein is transported to, or maintained in, a location within a cytoplasmic stress granule. |
| tRNA 3'-end processing | The process in which the 3' end of a pre-tRNA molecule is converted to that of a mature tRNA. |
| tRNA 5'-leader removal | Generation of the mature 5'-end of the tRNA, usually via an endonucleolytic cleavage by RNase P. |
| tRNA export from nucleus | The directed movement of tRNA from the nucleus to the cytoplasm. |
| tRNA modification | The covalent alteration of one or more nucleotides within a tRNA molecule to produce a tRNA molecule with a sequence that differs from that coded genetically. |
| tRNA processing | The process in which a pre-tRNA molecule is converted to a mature tRNA, ready for addition of an aminoacyl group. |
6 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q4G0J3 | LARP7 | La-related protein 7 | Homo sapiens (Human) | PR |
| Q71RC2 | LARP4 | La-related protein 4 | Homo sapiens (Human) | PR |
| Q6PKG0 | LARP1 | La-related protein 1 | Homo sapiens (Human) | PR |
| Q659C4 | LARP1B | La-related protein 1B | Homo sapiens (Human) | PR |
| Q05CL8 | Larp7 | La-related protein 7 | Mus musculus (Mouse) | PR |
| Q93ZV7 | LA1 | La protein 1 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAENGDNEKM | AALEAKICHQ | IEYYFGDFNL | PRDKFLKEQI | KLDEGWVPLE | IMIKFNRLNR |
| 70 | 80 | 90 | 100 | 110 | 120 |
| LTTDFNVIVE | ALSKSKAELM | EISEDKTKIR | RSPSKPLPEV | TDEYKNDVKN | RSVYIKGFPT |
| 130 | 140 | 150 | 160 | 170 | 180 |
| DATLDDIKEW | LEDKGQVLNI | QMRRTLHKAF | KGSIFVVFDS | IESAKKFVET | PGQKYKETDL |
| 190 | 200 | 210 | 220 | 230 | 240 |
| LILFKDDYFA | KKNEERKQNK | VEAKLRAKQE | QEAKQKLEED | AEMKSLEEKI | GCLLKFSGDL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| DDQTCREDLH | ILFSNHGEIK | WIDFVRGAKE | GIILFKEKAK | EALGKAKDAN | NGNLQLRNKE |
| 310 | 320 | 330 | 340 | 350 | 360 |
| VTWEVLEGEV | EKEALKKIIE | DQQESLNKWK | SKGRRFKGKG | KGNKAAQPGS | GKGKVQFQGK |
| 370 | 380 | 390 | 400 | ||
| KTKFASDDEH | DEHDENGATG | PVKRAREETD | KEEPASKQQK | TENGAGDQ |