Q9Y5K5
Gene name |
UCHL5 (UCH37, AD-019, CGI-70) |
Protein name |
Ubiquitin carboxyl-terminal hydrolase isozyme L5 |
Names |
UCH-L5, Ubiquitin C-terminal hydrolase UCH37, Ubiquitin thioesterase L5 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:51377 |
EC number |
3.4.19.12: Omega peptidases |
Protein Class |
|
Descriptions
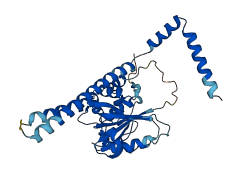
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
11 structures for Q9Y5K5
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 3A7S | X-ray | 220 A | A | 1-228 | PDB |
| 3IHR | X-ray | 295 A | A | 1-329 | PDB |
| 3RII | X-ray | 200 A | A/B | 1-228 | PDB |
| 3RIS | X-ray | 240 A | A/B/C/D | 1-240 | PDB |
| 3TB3 | X-ray | 230 A | A/B | 1-227 | PDB |
| 4UEL | X-ray | 230 A | A | 1-329 | PDB |
| 4UEM | X-ray | 282 A | A | 1-329 | PDB |
| 4UF5 | X-ray | 370 A | A | 1-329 | PDB |
| 4UF6 | X-ray | 369 A | A/D/G/J | 1-329 | PDB |
| 4WLP | X-ray | 310 A | A | 5-322 | PDB |
| AF-Q9Y5K5-F1 | Predicted | AlphaFoldDB |
210 variants for Q9Y5K5
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs1421640856 CA344076372 |
2 | T>M | No |
ClinGen TOPMed |
|
|
rs144390300 CA1302320 |
4 | N>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1572022946 CA344076336 |
8 | W>G | No |
ClinGen Ensembl |
|
|
rs1474300215 CA344076312 |
11 | M>R | No |
ClinGen gnomAD |
|
|
CA1302318 rs751924395 |
13 | S>G | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 16 | G>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1558210404 CA344076252 |
19 | T>I | No |
ClinGen Ensembl |
|
|
rs1188660418 CA344076220 |
24 | G>* | No |
ClinGen gnomAD |
|
|
CA344076222 rs1188660418 |
24 | G>R | No |
ClinGen gnomAD |
|
|
rs1476325898 CA344076218 |
24 | G>V | No |
ClinGen gnomAD |
|
|
CA344076050 rs1215076306 |
28 | R>* | No |
ClinGen TOPMed gnomAD |
|
|
rs770894191 CA1302309 COSM901362 |
28 | R>Q | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA344076039 rs1259842003 |
30 | A>T | No |
ClinGen gnomAD |
|
|
CA1302308 rs760569217 |
30 | A>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 34 | E>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA35095658 rs201468959 |
35 | I>M | No |
ClinGen Ensembl |
|
|
rs771715311 CA1302306 |
36 | W>* | No |
ClinGen ExAC gnomAD |
|
|
CA1302307 rs773036600 |
36 | W>R | No |
ClinGen ExAC gnomAD |
|
|
rs965461972 CA35095657 |
37 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
CA344075988 rs1370967170 |
37 | S>R | No |
ClinGen gnomAD |
|
|
rs867696559 CA344075970 |
40 | P>A | No |
ClinGen TOPMed |
|
|
rs867696559 CA35095656 |
40 | P>T | No |
ClinGen TOPMed |
|
|
CA344075966 rs1443286529 |
41 | E>K | No |
ClinGen gnomAD |
|
|
rs780193187 CA1302304 |
45 | K>E | No |
ClinGen ExAC gnomAD |
|
|
CA1302303 rs770059388 |
46 | L>S | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 47 | K>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1379254977 CA344075897 |
48 | P>S | No |
ClinGen TOPMed |
|
|
rs746140815 CA1302281 |
50 | H>L | No |
ClinGen ExAC gnomAD |
|
|
rs746140815 CA1302280 |
50 | H>R | No |
ClinGen ExAC gnomAD |
|
|
CA35095479 rs949826349 |
50 | H>Y | No |
ClinGen Ensembl |
|
| TCGA novel | 51 | G>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA344075854 rs1193339729 |
55 | L>I | No |
ClinGen gnomAD |
|
| TCGA novel | 55 | L>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs866279561 CA35095478 |
56 | F>L | No |
ClinGen Ensembl |
|
|
rs1558156791 CA344075789 |
63 | E>D | No |
ClinGen Ensembl |
|
|
rs1420609149 CA344075787 |
64 | P>S | No |
ClinGen TOPMed |
|
|
rs1420609149 CA344075786 |
64 | P>T | No |
ClinGen TOPMed |
|
|
rs747120010 CA1302276 |
67 | S>C | No |
ClinGen ExAC gnomAD |
|
|
rs747120010 CA344075767 |
67 | S>F | No |
ClinGen ExAC gnomAD |
|
|
CA1302277 rs770879529 |
67 | S>P | No |
ClinGen ExAC gnomAD |
|
|
CA344075755 rs1571890173 |
69 | V>G | No |
ClinGen Ensembl |
|
|
CA344075749 rs1365594464 |
70 | Q>L | No |
ClinGen TOPMed |
|
|
COSM1337363 CA35095475 rs930538472 |
73 | R>* | large_intestine [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
COSM1337362 CA35095474 rs920511079 |
73 | R>Q | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
rs1270108114 CA344075727 |
74 | L>F | No |
ClinGen gnomAD |
|
|
rs1342449791 CA344075721 COSM1337361 |
75 | D>G | large_intestine [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA1302275 rs778080751 COSM73192 |
75 | D>H | ovary Variant assessed as Somatic; 0.0 impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs759028109 CA1302274 |
76 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1335960005 CA344075705 |
77 | I>M | No |
ClinGen gnomAD |
|
|
rs1376245770 CA344075710 |
77 | I>V | No |
ClinGen gnomAD |
|
|
CA1302271 rs140990934 |
78 | F>Y | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA35095473 rs79965312 |
79 | F>L | No |
ClinGen Ensembl |
|
| TCGA novel | 85 | N>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA344075616 rs1232666387 |
88 | C>Y | No |
ClinGen gnomAD |
|
|
rs748711153 CA1302253 |
90 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA1302251 rs78945752 |
91 | Q>K | No |
ClinGen ExAC gnomAD |
|
|
CA344075589 rs1558051571 |
92 | A>G | No |
ClinGen Ensembl |
|
|
CA1302250 rs749668609 |
94 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs1558051278 CA344075523 |
102 | H>L | No |
ClinGen Ensembl |
|
|
CA344075518 rs1571600194 |
103 | Q>E | No |
ClinGen Ensembl |
|
|
rs767106872 CA1302246 |
103 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
CA35093359 rs904558279 |
103 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA344075509 rs1368765689 |
104 | D>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1448658923 CA344075511 |
104 | D>H | No |
ClinGen gnomAD |
|
|
CA344075505 rs1325106270 |
105 | V>I | No |
ClinGen gnomAD |
|
|
rs756784986 CA1302245 |
106 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1302243 rs375196985 |
109 | E>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 109 | E>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs370635844 CA1302242 |
110 | T>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1159675234 CA344075452 |
113 | E>* | No |
ClinGen gnomAD |
|
|
CA1302241 rs775409012 |
113 | E>A | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 113 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA344075436 rs1304349083 |
115 | K>R | No |
ClinGen TOPMed |
|
|
rs1404672046 CA344075406 |
119 | Q>R | No |
ClinGen TOPMed |
|
| TCGA novel | 120 | S>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA344075374 rs1193542022 |
123 | A>V | No |
ClinGen gnomAD |
|
|
CA344075371 rs1571598991 |
124 | A>T | No |
ClinGen Ensembl |
|
|
rs1297036136 CA344075366 |
124 | A>V | No |
ClinGen TOPMed |
|
|
CA1302228 rs745477602 |
125 | M>V | No |
ClinGen ExAC TOPMed |
|
|
CA344075324 rs1286632171 |
129 | A>T | No |
ClinGen gnomAD |
|
| TCGA novel | 132 | N>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1421965148 CA344075280 |
135 | V>E | No |
ClinGen gnomAD |
|
|
CA344075264 rs1178049411 |
138 | Q>E | No |
ClinGen TOPMed |
|
|
CA344075253 rs1211721310 |
139 | V>A | No |
ClinGen gnomAD |
|
|
rs1434286375 CA344075257 |
139 | V>I | No |
ClinGen gnomAD |
|
|
CA344075232 rs1313956355 |
142 | S>N | No |
ClinGen gnomAD |
|
|
CA35093354 rs375167412 |
143 | F>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs2275445 CA35093353 |
144 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs2275445 CA1302223 |
144 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs2275445 CA1302224 |
144 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1484109138 CA344075196 |
146 | Q>* | No |
ClinGen gnomAD |
|
| TCGA novel | 146 | Q>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA35093350 rs941683161 |
147 | Q>K | No |
ClinGen TOPMed gnomAD |
|
|
CA344075182 rs1553247236 |
148 | M>V | No |
ClinGen Ensembl |
|
|
rs746514604 CA1302205 |
149 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs865934027 CA35093349 |
150 | E>Q | No |
ClinGen Ensembl |
|
|
rs35505005 CA1302203 |
153 | T>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 154 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA344075131 rs1293496055 |
155 | T>P | No |
ClinGen gnomAD |
|
|
CA344075125 rs1413037512 |
156 | S>T | No |
ClinGen TOPMed |
|
|
CA1302201 rs778745204 |
157 | A>P | No |
ClinGen ExAC gnomAD |
|
|
rs754733947 CA1302200 |
160 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs767838915 CA344075083 |
162 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs767838915 CA1302198 |
162 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA344075047 rs773702442 |
167 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1302197 rs773702442 |
167 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs139595729 CA1302196 |
169 | V>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA1302195 rs764221741 |
171 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs1188491342 CA344075001 |
174 | R>K | No |
ClinGen gnomAD |
|
|
rs770352804 CA35093348 |
179 | D>G | No |
ClinGen Ensembl |
|
| TCGA novel | 184 | G>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA344074931 rs1458177690 |
184 | G>R | No |
ClinGen gnomAD |
|
|
rs910453913 CA35093347 |
186 | I>T | No |
ClinGen TOPMed gnomAD |
|
|
CA1302175 rs752781635 |
190 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA35093251 rs111500245 |
190 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs890591356 CA35093250 |
192 | N>D | No |
ClinGen Ensembl |
|
|
rs140645938 CA1302174 |
192 | N>S | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1311843534 CA344074862 |
193 | Q>* | No |
ClinGen gnomAD |
|
|
CA1302173 rs760071291 |
195 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
rs867951836 CA35093249 |
196 | W>L | No |
ClinGen Ensembl |
|
| VAR_011613 | 197 | I>F | No | UniProt | |
|
rs993773906 CA35093248 |
198 | S>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1270520382 CA344074817 |
199 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
CA344074798 rs1285545680 |
202 | P>S | No |
ClinGen TOPMed |
|
|
rs201071799 CA1302172 |
203 | V>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 207 | R>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs761056431 CA1302170 |
207 | R>S | No |
ClinGen ExAC gnomAD |
|
|
rs1010174152 CA35093247 |
208 | I>V | No |
ClinGen Ensembl |
|
| TCGA novel | 209 | Q>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1420141414 CA344074741 |
210 | K>R | No |
ClinGen gnomAD |
|
|
CA344074532 rs1571508171 |
211 | Y>H | No |
ClinGen Ensembl |
|
|
CA1302126 rs762268546 |
212 | S>R | No |
ClinGen ExAC gnomAD |
|
|
rs775430311 CA35092790 |
212 | S>T | No |
ClinGen Ensembl |
|
|
CA344074519 rs1409102370 |
213 | E>K | No |
ClinGen TOPMed |
|
|
CA1302125 rs751104681 |
214 | G>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA35092787 rs375856662 |
217 | R>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA35092788 rs375856662 |
217 | R>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1292950928 CA344074490 |
217 | R>P | No |
ClinGen gnomAD |
|
| TCGA novel | 217 | R>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 222 | A>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1457950788 CA344074454 |
222 | A>T | No |
ClinGen TOPMed |
|
|
rs1360290648 CA344074449 |
223 | I>V | No |
ClinGen gnomAD |
|
| TCGA novel | 224 | V>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1159584163 CA344074405 |
229 | M>K | No |
ClinGen TOPMed gnomAD |
|
|
CA344074404 rs1159584163 |
229 | M>T | No |
ClinGen TOPMed gnomAD |
|
|
CA1302123 rs762535915 |
230 | I>M | No |
ClinGen ExAC gnomAD |
|
|
rs967509934 CA35092785 |
232 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
rs1248734076 CA344074361 |
235 | I>V | No |
ClinGen gnomAD |
|
|
rs1213930637 CA344074355 |
236 | A>T | No |
ClinGen gnomAD |
|
| rs1488048601 | 236 | A>missing | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA1302120 rs759436892 |
242 | L>F | No |
ClinGen ExAC gnomAD |
|
|
CA344074310 rs759436892 |
242 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs200881380 CA1302119 |
243 | A>E | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1558012682 CA344074264 |
247 | P>T | No |
ClinGen Ensembl |
|
|
CA1302102 rs185520390 |
248 | M>L | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA344074254 rs1279694709 |
248 | M>R | No |
ClinGen gnomAD |
|
|
CA1302101 rs776369356 |
250 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA344074233 rs1377451362 |
251 | D>G | No |
ClinGen gnomAD |
|
|
COSM3803245 COSM3803244 COSM3803243 rs1302564487 CA344074227 COSM3803246 |
252 | Q>E | Variant assessed as Somatic; 0.0 impact. breast [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
rs760377013 CA1302099 |
253 | G>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1302100 rs766355155 |
253 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs1281270229 CA344074208 |
254 | N>D | No |
ClinGen TOPMed |
|
|
rs773059734 CA1302098 |
255 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA1302097 rs768836329 |
255 | S>N | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 255 | S>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA35092708 rs368049598 |
256 | M>I | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs749561076 CA1302096 |
256 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 257 | L>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA344074151 rs1173082318 |
259 | A>T | No |
ClinGen gnomAD |
|
|
rs1027291966 CA35092707 |
260 | I>V | No |
ClinGen Ensembl |
|
| TCGA novel | 261 | Q>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs775721003 CA1302095 |
266 | K>T | No |
ClinGen ExAC TOPMed gnomAD |
|
| rs1558011697 | 267 | N>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1376309370 CA344074038 |
269 | M>T | No |
ClinGen TOPMed |
|
|
rs769696158 CA35092706 |
271 | I>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA344074016 rs1268610155 COSM901354 |
271 | I>T | Variant assessed as Somatic; impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
rs769696158 CA1302094 |
271 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1193317807 CA344074010 |
272 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA35092705 rs938353590 |
281 | Y>F | No |
ClinGen TOPMed |
|
|
rs1197531329 CA344073904 |
281 | Y>N | No |
ClinGen gnomAD |
|
|
rs766225024 CA1302083 |
283 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs1571462464 CA344073793 |
284 | E>G | No |
ClinGen Ensembl |
|
|
rs760708096 CA1302082 |
285 | N>D | No |
ClinGen ExAC gnomAD |
|
|
rs1378466262 CA344073783 |
285 | N>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1228983394 CA344073697 |
292 | Y>S | No |
ClinGen TOPMed |
|
|
rs770111232 CA1302077 |
296 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA35092515 rs1007767123 |
298 | E>K | No |
ClinGen Ensembl |
|
|
rs1226750299 CA344073635 |
298 | E>V | No |
ClinGen Ensembl |
|
|
rs745929302 CA344073621 |
299 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1246077586 CA344073616 |
300 | L>* | No |
ClinGen TOPMed gnomAD |
|
|
rs1330468927 CA344073601 |
301 | K>R | No |
ClinGen gnomAD |
|
|
CA35092514 rs953770729 |
302 | T>S | No |
ClinGen gnomAD |
|
|
CA344073579 rs1452428046 |
303 | L>V | No |
ClinGen TOPMed |
|
|
CA35092513 rs868716595 |
306 | H>Y | No |
ClinGen Ensembl |
|
|
rs776809591 CA1302075 |
307 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
CA1302074 rs771316883 |
308 | Q>K | No |
ClinGen ExAC |
|
| TCGA novel | 310 | I>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs371022300 CA1302072 |
311 | P>A | No |
ClinGen ESP ExAC gnomAD |
|
|
rs371022300 CA1302073 |
311 | P>T | No |
ClinGen ESP ExAC gnomAD |
|
|
rs367543822 CA35092511 |
314 | E>K | No |
ClinGen ESP TOPMed gnomAD |
|
| TCGA novel | 318 | E>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA1302030 rs769500827 |
320 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
CA1302031 rs775195550 |
320 | Q>K | No |
ClinGen ExAC gnomAD |
|
|
CA1302029 rs75981031 |
321 | N>I | No |
ClinGen ExAC gnomAD |
|
|
CA35092049 rs75981031 |
321 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA1302027 rs146351256 COSM173824 |
322 | A>T | large_intestine [Cosmic] | No |
ClinGen cosmic curated 1000Genomes ESP ExAC TOPMed gnomAD |
| TCGA novel | 323 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 324 | K>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs200139872 CA1302025 |
327 | E>A | No |
ClinGen 1000Genomes ExAC TOPMed |
|
|
rs200139872 CA35092048 |
327 | E>G | No |
ClinGen 1000Genomes ExAC TOPMed |
No associated diseases with Q9Y5K5
Functions
| Description | ||
|---|---|---|
| EC Number | 3.4.19.12 | Omega peptidases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
7 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| cytosolic proteasome complex | A proteasome complex found in the cytosol of a cell. |
| Ino80 complex | A multisubunit protein complex that contains the Ino80p ATPase; exhibits chromatin remodeling activity. |
| nucleolus | A small, dense body one or more of which are present in the nucleus of eukaryotic cells. It is rich in RNA and protein, is not bounded by a limiting membrane, and is not seen during mitosis. Its prime function is the transcription of the nucleolar DNA into 45S ribosomal-precursor RNA, the processing of this RNA into 5.8S, 18S, and 28S components of ribosomal RNA, and the association of these components with 5S RNA and proteins synthesized outside the nucleolus. This association results in the formation of ribonucleoprotein precursors; these pass into the cytoplasm and mature into the 40S and 60S subunits of the ribosome. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
4 GO annotations of molecular function
| Name | Definition |
|---|---|
| cysteine-type deubiquitinase activity | An thiol-dependent isopeptidase activity that cleaves ubiquitin from a target protein to which it is conjugated. |
| endopeptidase inhibitor activity | Binds to and stops, prevents or reduces the activity of an endopeptidase, any enzyme that hydrolyzes nonterminal peptide bonds in polypeptides. |
| proteasome binding | Binding to a proteasome, a large multisubunit protein complex that catalyzes protein degradation. |
| RNA binding | Binding to an RNA molecule or a portion thereof. |
20 GO annotations of biological process
| Name | Definition |
|---|---|
| chromatin remodeling | A dynamic process of chromatin reorganization resulting in changes to chromatin structure. These changes allow DNA metabolic processes such as transcriptional regulation, DNA recombination, DNA repair, and DNA replication. |
| DNA recombination | Any process in which a new genotype is formed by reassortment of genes resulting in gene combinations different from those that were present in the parents. In eukaryotes genetic recombination can occur by chromosome assortment, intrachromosomal recombination, or nonreciprocal interchromosomal recombination. Interchromosomal recombination occurs by crossing over. In bacteria it may occur by genetic transformation, conjugation, transduction, or F-duction. |
| DNA repair | The process of restoring DNA after damage. Genomes are subject to damage by chemical and physical agents in the environment (e.g. UV and ionizing radiations, chemical mutagens, fungal and bacterial toxins, etc.) and by free radicals or alkylating agents endogenously generated in metabolism. DNA is also damaged because of errors during its replication. A variety of different DNA repair pathways have been reported that include direct reversal, base excision repair, nucleotide excision repair, photoreactivation, bypass, double-strand break repair pathway, and mismatch repair pathway. |
| forebrain morphogenesis | The process in which the anatomical structures of the forebrain are generated and organized. The forebrain is the anterior of the three primary divisions of the developing chordate brain or the corresponding part of the adult brain (in vertebrates, includes especially the cerebral hemispheres, the thalamus, and the hypothalamus and especially in higher vertebrates is the main control center for sensory and associative information processing, visceral functions, and voluntary motor functions). |
| lateral ventricle development | The process whose specific outcome is the progression of the lateral ventricles over time, from the formation to the mature structure. The two lateral ventricles are a cavity in each of the cerebral hemispheres derived from the cavity of the embryonic neural tube. They are separated from each other by the septum pellucidum, and each communicates with the third ventricle by the foramen of Monro, through which also the choroid plexuses of the lateral ventricles become continuous with that of the third ventricle. |
| midbrain development | The process whose specific outcome is the progression of the midbrain over time, from its formation to the mature structure. The midbrain is the middle division of the three primary divisions of the developing chordate brain or the corresponding part of the adult brain (in vertebrates, includes a ventral part containing the cerebral peduncles and a dorsal tectum containing the corpora quadrigemina and that surrounds the aqueduct of Sylvius connecting the third and fourth ventricles). |
| negative regulation of proteasomal ubiquitin-dependent protein catabolic process | Any process that stops, prevents, or reduces the frequency, rate or extent of the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of ubiquitin, and mediated by the proteasome. |
| positive regulation of DNA repair | Any process that activates or increases the frequency, rate or extent of DNA repair. |
| positive regulation of DNA-templated transcription | Any process that activates or increases the frequency, rate or extent of cellular DNA-templated transcription. |
| positive regulation of smoothened signaling pathway | Any process that activates or increases the frequency, rate or extent of smoothened signaling. |
| positive regulation of telomere maintenance in response to DNA damage | Any process that activates or increases the frequency, rate or extent of telomere maintenance in response to DNA damage. |
| protein deubiquitination | The removal of one or more ubiquitin groups from a protein. |
| regulation of cell cycle | Any process that modulates the rate or extent of progression through the cell cycle. |
| regulation of chromosome organization | Any process that modulates the frequency, rate or extent of a process involved in the formation, arrangement of constituent parts, or disassembly of a chromosome. |
| regulation of DNA replication | Any process that modulates the frequency, rate or extent of DNA replication. |
| regulation of DNA strand elongation | Any process that modulates the rate, frequency or extent of DNA strand elongation. DNA strand elongation is the DNA metabolic process in which an existing DNA strand is extended by activities including the addition of nucleotides to the 3' end of the strand. |
| regulation of embryonic development | Any process that modulates the frequency, rate or extent of embryonic development. |
| regulation of proteasomal protein catabolic process | Any process that modulates the rate, frequency, or extent of the chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds that is mediated by the proteasome. |
| telomere maintenance | Any process that contributes to the maintenance of proper telomeric length and structure by affecting and monitoring the activity of telomeric proteins, the length of telomeric DNA and the replication and repair of the DNA. These processes includes those that shorten, lengthen, replicate and repair the telomeric DNA sequences. |
| ubiquitin-dependent protein catabolic process | The chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of a ubiquitin group, or multiple ubiquitin groups, to the protein. |
4 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q9XSJ0 | UCHL5 | Ubiquitin carboxyl-terminal hydrolase isozyme L5 | Bos taurus (Bovine) | PR |
| Q7K5N4 | calypso | Ubiquitin carboxyl-terminal hydrolase calypso | Drosophila melanogaster (Fruit fly) | PR |
| Q9WUP7 | Uchl5 | Ubiquitin carboxyl-terminal hydrolase isozyme L5 | Mus musculus (Mouse) | PR |
| Q06AT3 | UCHL5 | Ubiquitin carboxyl-terminal hydrolase isozyme L5 | Sus scrofa (Pig) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MTGNAGEWCL | MESDPGVFTE | LIKGFGCRGA | QVEEIWSLEP | ENFEKLKPVH | GLIFLFKWQP |
| 70 | 80 | 90 | 100 | 110 | 120 |
| GEEPAGSVVQ | DSRLDTIFFA | KQVINNACAT | QAIVSVLLNC | THQDVHLGET | LSEFKEFSQS |
| 130 | 140 | 150 | 160 | 170 | 180 |
| FDAAMKGLAL | SNSDVIRQVH | NSFARQQMFE | FDTKTSAKEE | DAFHFVSYVP | VNGRLYELDG |
| 190 | 200 | 210 | 220 | 230 | 240 |
| LREGPIDLGA | CNQDDWISAV | RPVIEKRIQK | YSEGEIRFNL | MAIVSDRKMI | YEQKIAELQR |
| 250 | 260 | 270 | 280 | 290 | 300 |
| QLAEEEPMDT | DQGNSMLSAI | QSEVAKNQML | IEEEVQKLKR | YKIENIRRKH | NYLPFIMELL |
| 310 | 320 | ||||
| KTLAEHQQLI | PLVEKAKEKQ | NAKKAQETK |