Q9SKI4
Gene name |
RPA1A (RPA70A, At2g06510, T12H3.6) |
Protein name |
Replication protein A 70 kDa DNA-binding subunit A |
Names |
AtRPA70A, AtRPA1-3, Replication factor A protein 1A, Replication protein A 1A, AtRPA1A |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT2G06510 |
EC number |
|
Protein Class |
|
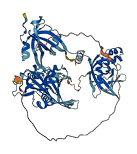
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9SKI4
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9SKI4-F1 | Predicted | AlphaFoldDB |
67 variants for Q9SKI4
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH00212978 | 14 | H>N | No | 1000Genomes | |
| ENSVATH01673374 | 26 | V>I | No | 1000Genomes | |
| tmp_2_2585336_A_C | 41 | E>A | No | 1000Genomes | |
| ENSVATH00212979 | 58 | V>I | No | 1000Genomes | |
| tmp_2_2585422_C_A | 70 | Q>K | No | 1000Genomes | |
| ENSVATH05295711 | 103 | Q>P | No | 1000Genomes | |
| tmp_2_2586007_A_G | 110 | N>S | No | 1000Genomes | |
| ENSVATH05295712 | 112 | T>A | No | 1000Genomes | |
| tmp_2_2586018_T_G | 114 | F>V | No | 1000Genomes | |
| ENSVATH11685432 | 115 | G>E | No | 1000Genomes | |
| tmp_2_2586026_A_C | 116 | E>D | No | 1000Genomes | |
| ENSVATH14069200 | 119 | T>K | No | 1000Genomes | |
| tmp_2_2586039_G_T | 121 | A>S | No | 1000Genomes | |
| tmp_2_2586044_G_T | 122 | Q>H | No | 1000Genomes | |
| ENSVATH14069201 | 124 | T>R | No | 1000Genomes | |
| tmp_2_2586061_C_T | 128 | T>M | No | 1000Genomes | |
| ENSVATH14069202 | 129 | G>A | No | 1000Genomes | |
| tmp_2_2586073_C_T | 132 | P>L | No | 1000Genomes | |
| tmp_2_2586079_C_T | 134 | P>L | No | 1000Genomes | |
| tmp_2_2586090_G_A | 138 | V>I | No | 1000Genomes | |
| ENSVATH05295713 | 143 | M>V | No | 1000Genomes | |
| ENSVATH11685433 | 146 | H>L | No | 1000Genomes | |
| ENSVATH05295714 | 148 | V>F | No | 1000Genomes | |
| ENSVATH11685434 | 153 | P>S | No | 1000Genomes | |
| tmp_2_2586166_A_G | 163 | N>S | No | 1000Genomes | |
| ENSVATH05295716 | 164 | N>S | No | 1000Genomes | |
| tmp_2_2586183_A_G | 169 | R>G | No | 1000Genomes | |
| tmp_2_2586211_C_T | 178 | P>L | No | 1000Genomes | |
| ENSVATH11685505 | 194 | P>S | No | 1000Genomes | |
| tmp_2_2586341_T_A | 221 | D>E | No | 1000Genomes | |
| tmp_2_2586450_C_T | 258 | R>C | No | 1000Genomes | |
| ENSVATH05295719 | 282 | N>I | No | 1000Genomes | |
| tmp_2_2586565_C_T | 296 | S>L | No | 1000Genomes | |
| tmp_2_2586564_T_A | 296 | S>T | No | 1000Genomes | |
| tmp_2_2586582_C_G | 302 | L>V | No | 1000Genomes | |
| ENSVATH05295721 | 318 | R>H | No | 1000Genomes | |
| ENSVATH14069204 | 326 | A>T | No | 1000Genomes | |
| ENSVATH00212983 | 339 | T>N | No | 1000Genomes | |
| tmp_2_2586708_T_A | 344 | S>T | No | 1000Genomes | |
| tmp_2_2586773_A_T | 365 | E>D | No | 1000Genomes | |
| tmp_2_2586829_G_A | 384 | R>Q | No | 1000Genomes | |
| tmp_2_2586845_G_A | 389 | M>I | No | 1000Genomes | |
| tmp_2_2586846_G_A | 390 | V>I | No | 1000Genomes | |
| ENSVATH05295725 | 391 | D>E | No | 1000Genomes | |
| tmp_2_2586870_T_G | 398 | L>V | No | 1000Genomes | |
| ENSVATH05295726 | 400 | I>L | No | 1000Genomes | |
| ENSVATH05295730 | 431 | H>Q | No | 1000Genomes | |
| tmp_2_2586979_G_A | 434 | R>Q | No | 1000Genomes | |
| ENSVATH05295731 | 439 | Y>H | No | 1000Genomes | |
| ENSVATH14069237 | 509 | D>E | No | 1000Genomes | |
| ENSVATH14069238 | 510 | K>Q | No | 1000Genomes | |
| tmp_2_2587231_G_A | 518 | R>Q | No | 1000Genomes | |
| tmp_2_2587257_G_C | 527 | D>H | No | 1000Genomes | |
| ENSVATH05295737 | 549 | H>Y | No | 1000Genomes | |
| ENSVATH11685507 | 550 | T>S | No | 1000Genomes | |
| ENSVATH05295738 | 561 | T>S | No | 1000Genomes | |
| ENSVATH05295739 | 564 | E>D | No | 1000Genomes | |
| tmp_2_2587374_A_G | 566 | M>V | No | 1000Genomes | |
| ENSVATH11685509 | 569 | P>Q | No | 1000Genomes | |
| ENSVATH05295741 | 576 | M>L | No | 1000Genomes | |
| ENSVATH05295744 | 589 | I>M | No | 1000Genomes | |
| tmp_2_2587452_G_A | 592 | D>N | No | 1000Genomes | |
| tmp_2_2587521_G_T | 615 | V>L | No | 1000Genomes | |
| ENSVATH05295746 | 628 | T>I | No | 1000Genomes | |
| ENSVATH05295745 | 628 | T>S | No | 1000Genomes | |
| ENSVATH11685510 | 629 | S>A | No | 1000Genomes | |
| ENSVATH01673380 | 634 | M>I | No | 1000Genomes |
No associated diseases with Q9SKI4
5 regional properties for Q9SKI4
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | OB-fold nucleic acid binding domain, AA-tRNA synthetase-type | 211 - 294 | IPR004365 |
| domain | Replication factor-A protein 1, N-terminal | 5 - 103 | IPR007199 |
| domain | Replication factor A, C-terminal | 483 - 634 | IPR013955 |
| domain | Replication protein A, OB domain | 320 - 424 | IPR031657 |
| domain | Replication factor A, C-terminal, eukaryotes | 467 - 638 | IPR047192 |
2 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromatin | The ordered and organized complex of DNA, protein, and sometimes RNA, that forms the chromosome. |
| DNA replication factor A complex | A conserved heterotrimeric complex that binds nonspecifically to single-stranded DNA and is required for multiple processes in eukaryotic DNA metabolism, including DNA replication, DNA repair, and recombination. In all eukaryotic organisms examined the complex is composed of subunits of approximately 70, 30, and 14 kDa. |
3 GO annotations of molecular function
| Name | Definition |
|---|---|
| damaged DNA binding | Binding to damaged DNA. |
| metal ion binding | Binding to a metal ion. |
| single-stranded telomeric DNA binding | Binding to single-stranded telomere-associated DNA. |
10 GO annotations of biological process
| Name | Definition |
|---|---|
| chiasma assembly | The cell cycle process in which a connection between chromatids assembles, indicating where an exchange of homologous segments has taken place by the crossing-over of non-sister chromatids. |
| DNA unwinding involved in DNA replication | The process in which interchain hydrogen bonds between two strands of DNA are broken or 'melted', generating unpaired template strands for DNA replication. |
| double-strand break repair via homologous recombination | The error-free repair of a double-strand break in DNA in which the broken DNA molecule is repaired using homologous sequences. A strand in the broken DNA searches for a homologous region in an intact chromosome to serve as the template for DNA synthesis. The restoration of two intact DNA molecules results in the exchange, reciprocal or nonreciprocal, of genetic material between the intact DNA molecule and the broken DNA molecule. |
| male gamete generation | Generation of the male gamete; specialised haploid cells produced by meiosis and along with a female gamete takes part in sexual reproduction. |
| male meiosis I | A cell cycle process comprising the steps by which a cell progresses through male meiosis I, the first meiotic division in the male germline. |
| meiotic cell cycle | Progression through the phases of the meiotic cell cycle, in which canonically a cell replicates to produce four offspring with half the chromosomal content of the progenitor cell via two nuclear divisions. |
| nucleotide-excision repair | A DNA repair process in which a small region of the strand surrounding the damage is removed from the DNA helix as an oligonucleotide. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. Nucleotide excision repair recognizes a wide range of substrates, including damage caused by UV irradiation (pyrimidine dimers and 6-4 photoproducts) and chemicals (intrastrand cross-links and bulky adducts). |
| pollen development | The process whose specific outcome is the progression of the pollen grain over time, from its formation to the mature structure. The process begins with the meiosis of the microsporocyte to form four haploid microspores. The nucleus of each microspore then divides by mitosis to form a two-celled organism, the pollen grain, that contains a tube cell as well as a smaller generative cell. The pollen grain is surrounded by an elaborate cell wall. In some species, the generative cell immediately divides again to give a pair of sperm cells. In most flowering plants, however this division takes place later, in the tube that develops when a pollen grain germinates. |
| reciprocal meiotic recombination | The cell cycle process in which double strand breaks are formed and repaired through a single or double Holliday junction intermediate. This results in the equal exchange of genetic material between non-sister chromatids in a pair of homologous chromosomes. These reciprocal recombinant products ensure the proper segregation of homologous chromosomes during meiosis I and create genetic diversity. |
| telomere maintenance via telomerase | The maintenance of proper telomeric length by the addition of telomeric repeats by telomerase. |
8 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q5ZJJ2 | RPA1 | Replication protein A 70 kDa DNA-binding subunit | Gallus gallus (Chicken) | PR |
| Q24492 | RpA-70 | Replication protein A 70 kDa DNA-binding subunit | Drosophila melanogaster (Fruit fly) | PR |
| P27694 | RPA1 | Replication protein A 70 kDa DNA-binding subunit | Homo sapiens (Human) | PR |
| Q8VEE4 | Rpa1 | Replication protein A 70 kDa DNA-binding subunit | Mus musculus (Mouse) | PR |
| Q10Q08 | RPA1B | Replication protein A 70 kDa DNA-binding subunit B | Oryza sativa subsp japonica (Rice) | PR |
| Q19537 | rpa-1 | Probable replication factor A 73 kDa subunit | Caenorhabditis elegans | PR |
| F4JSG3 | RPA1E | Replication protein A 70 kDa DNA-binding subunit E | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q5FW17 | rpa1 | Replication protein A 70 kDa DNA-binding subunit | Xenopus tropicalis (Western clawed frog) (Silurana tropicalis) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MPVSLTPNAI | TAIHDGDVNL | KPLLQVLEIK | MIGRSQERSQ | ERYRFLISDG | VSAQHAMVAV |
| 70 | 80 | 90 | 100 | 110 | 120 |
| QLNDRVKSGQ | FEKGSIVQLI | DYICSDVKGR | KLIVVLNMET | IVQQSETIGN | PTIFGETDTE |
| 130 | 140 | 150 | 160 | 170 | 180 |
| AQKTFSGTGN | IPPPNRVVFN | EPMVQHSVNR | APPRGVNIQN | QANNTPSFRP | SVQPSYQPPA |
| 190 | 200 | 210 | 220 | 230 | 240 |
| SYRNHGPIMK | NEAPARVIPI | AALNPYQGRW | AIKARVTAKG | DIRRYNNAKG | DGKVFSFDLL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| DYDGGEIRVT | CFNALVDRFY | DVTEVGKVYL | ISKGSLKPAQ | KNFNHLKNEW | EIFLESTSTV |
| 310 | 320 | 330 | 340 | 350 | 360 |
| ELCPDEDGSI | PKQQFSFRPI | SDIENAENNT | ILDVIGVVTS | VNPSVPILRK | NGMETHRRIL |
| 370 | 380 | 390 | 400 | 410 | 420 |
| NLKDESGKAV | EVTLWGEFCN | RDGRQLEEMV | DSAFHPVLAI | KAGKVSDFSG | KSVGTISSTQ |
| 430 | 440 | 450 | 460 | 470 | 480 |
| LFINPDFPEA | HKLRTWFDYG | GKDTASFSIS | RDTMPGGVSR | NEIRKNVSQI | KEEGLGRSDK |
| 490 | 500 | 510 | 520 | 530 | 540 |
| PDWITVKATI | SFIKTDSFCY | TACPLMIGDK | QCNKKVTRSG | TNRWLCDRCN | QESDECDYRY |
| 550 | 560 | 570 | 580 | 590 | 600 |
| LLQVQIQDHT | GLTWITAFQE | TGEEIMGCPA | KKLYAMKYEL | EKEEEFAEIV | RDRLFHQYML |
| 610 | 620 | 630 | |||
| KLKIKEESYG | DEQRVKMTVV | KVDKVNYTSE | SKYMLDLLVR |