F4JSG3
Gene name |
RPA1E (RPA70E, At4g19130, T18B16.100) |
Protein name |
Replication protein A 70 kDa DNA-binding subunit E |
Names |
AtRPA70E, AtRPA1-1, Replication factor A protein 1E, Replication protein A 1E, AtRPA1E |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT4G19130 |
EC number |
|
Protein Class |
|
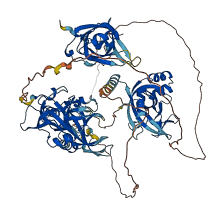
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for F4JSG3
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-F4JSG3-F1 | Predicted | AlphaFoldDB |
165 variants for F4JSG3
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| tmp_4_10469089_C_G | 2 | E>Q | No | 1000Genomes | |
| ENSVATH06722633 | 3 | V>A | No | 1000Genomes | |
| ENSVATH12007487 | 8 | G>R | No | 1000Genomes | |
| tmp_4_10469058_T_C | 12 | K>R | No | 1000Genomes | |
| ENSVATH06722632 | 13 | I>M | No | 1000Genomes | |
| ENSVATH00522317 | 15 | N>S | No | 1000Genomes | |
| ENSVATH02880255 | 20 | T>I | No | 1000Genomes | |
| ENSVATH02880255 | 20 | T>S | No | 1000Genomes | |
| tmp_4_10469028_G_T | 22 | A>E | No | 1000Genomes | |
| ENSVATH12007485 | 48 | R>K | No | 1000Genomes | |
| ENSVATH06722631 | 49 | M>L | No | 1000Genomes | |
| ENSVATH12007434 | 51 | L>* | No | 1000Genomes | |
| ENSVATH12007433 | 58 | H>D | No | 1000Genomes | |
| ENSVATH08354286 | 66 | L>I | No | 1000Genomes | |
| ENSVATH00522314 | 77 | P>S | No | 1000Genomes | |
| tmp_4_10468861_C_A | 78 | G>C | No | 1000Genomes | |
| ENSVATH12007432 | 80 | I>T | No | 1000Genomes | |
| tmp_4_10468846_G_C | 83 | L>V | No | 1000Genomes | |
| tmp_4_10468666_C_T | 103 | E>K | No | 1000Genomes | |
| ENSVATH02880252 | 107 | Q>K | No | 1000Genomes | |
| ENSVATH02880251 | 107 | Q>P | No | 1000Genomes | |
| ENSVATH02880250 | 108 | I>T | No | 1000Genomes | |
| ENSVATH06722624 | 110 | D>V | No | 1000Genomes | |
| ENSVATH06722623 | 114 | H>N | No | 1000Genomes | |
| tmp_4_10468630_G_A | 115 | P>S | No | 1000Genomes | |
| tmp_4_10468618_C_T | 119 | G>R | No | 1000Genomes | |
| ENSVATH00522310 | 127 | A>S | No | 1000Genomes | |
| tmp_4_10468577_C_A | 132 | K>N | No | 1000Genomes | |
| ENSVATH00522309 | 139 | Q>H | No | 1000Genomes | |
| ENSVATH00522308 | 143 | I>V | No | 1000Genomes | |
| ENSVATH00522306 | 147 | N>I | No | 1000Genomes | |
| ENSVATH14252313 | 168 | S>N | No | 1000Genomes | |
| ENSVATH00522305 | 168 | S>R | No | 1000Genomes | |
| tmp_4_10468440_C_G | 178 | R>P | No | 1000Genomes | |
| ENSVATH00522304 | 181 | S>R | No | 1000Genomes | |
| ENSVATH12007427 | 183 | P>L | No | 1000Genomes | |
| tmp_4_10468422_G_T | 184 | S>Y | No | 1000Genomes | |
| ENSVATH12007426 | 188 | G>R | No | 1000Genomes | |
| ENSVATH00522303 | 192 | Q>P | No | 1000Genomes | |
| tmp_4_10468394_G_T | 193 | D>E | No | 1000Genomes | |
| tmp_4_10468380_G_A | 198 | P>L | No | 1000Genomes | |
| tmp_4_10468367_A_T | 202 | Y>* | No | 1000Genomes | |
| ENSVATH02880248 | 214 | A>P | No | 1000Genomes | |
| tmp_4_10468317_A_C | 219 | V>G | No | 1000Genomes | |
| ENSVATH06722620 | 219 | V>L | No | 1000Genomes | |
| ENSVATH12007425 | 224 | A>P | No | 1000Genomes | |
| ENSVATH02880247 | 224 | A>V | No | 1000Genomes | |
| tmp_4_10468290_A_T | 228 | I>K | No | 1000Genomes | |
| tmp_4_10468288_T_C | 229 | I>V | No | 1000Genomes | |
| tmp_4_10468282_C_T | 231 | V>I | No | 1000Genomes | |
| tmp_4_10468276_C_A | 233 | A>S | No | 1000Genomes | |
| tmp_4_10468222_C_T | 251 | A>T | No | 1000Genomes | |
| tmp_4_10468219_C_T | 252 | A>T | No | 1000Genomes | |
| ENSVATH06722619 | 265 | V>M | No | 1000Genomes | |
| ENSVATH00522302 | 274 | D>E | No | 1000Genomes | |
| ENSVATH06722618 | 279 | R>C | No | 1000Genomes | |
| ENSVATH06722617 | 282 | C>R | No | 1000Genomes | |
| ENSVATH00522301 | 284 | N>S | No | 1000Genomes | |
| tmp_4_10468107_T_C | 289 | Q>R | No | 1000Genomes | |
| tmp_4_10468090_C_A | 295 | V>F | No | 1000Genomes | |
| tmp_4_10468073_A_T | 300 | Y>* | No | 1000Genomes | |
| tmp_4_10468069_T_A | 302 | I>F | No | 1000Genomes | |
| ENSVATH14252312 | 308 | R>W | No | 1000Genomes | |
| tmp_4_10468045_C_T | 310 | A>T | No | 1000Genomes | |
| ENSVATH12007362 | 320 | D>N | No | 1000Genomes | |
| ENSVATH06722615 | 324 | M>V | No | 1000Genomes | |
| tmp_4_10467997_C_T | 326 | D>N | No | 1000Genomes | |
| ENSVATH12007361 | 339 | A>V | No | 1000Genomes | |
| tmp_4_10467952_T_A | 341 | I>F | No | 1000Genomes | |
| ENSVATH06722614 | 347 | H>Y | No | 1000Genomes | |
| tmp_4_10467927_C_T | 349 | R>H | No | 1000Genomes | |
| ENSVATH14252311 | 359 | N>K | No | 1000Genomes | |
| ENSVATH00522300 | 361 | C>S | No | 1000Genomes | |
| ENSVATH02880245 | 363 | V>I | No | 1000Genomes | |
| tmp_4_10467861_G_A | 371 | S>F | No | 1000Genomes | |
| ENSVATH12007358 | 384 | T>S | No | 1000Genomes | |
| ENSVATH06722612 | 389 | R>I | No | 1000Genomes | |
| ENSVATH06722611 | 391 | L>F | No | 1000Genomes | |
| tmp_4_10467799_G_T | 392 | Q>K | No | 1000Genomes | |
| ENSVATH06722610 | 400 | S>T | No | 1000Genomes | |
| ENSVATH02880238 | 412 | A>G | No | 1000Genomes | |
| ENSVATH02880239 | 412 | A>S | No | 1000Genomes | |
| ENSVATH02880239 | 412 | A>T | No | 1000Genomes | |
| tmp_4_10467734_T_G | 413 | E>D | No | 1000Genomes | |
| ENSVATH02880237 | 414 | G>A | No | 1000Genomes | |
| ENSVATH02880237 | 414 | G>E | No | 1000Genomes | |
| tmp_4_10467726_C_A | 416 | R>M | No | 1000Genomes | |
| ENSVATH02880236 | 419 | S>N | No | 1000Genomes | |
| tmp_4_10467712_A_C | 421 | C>G | No | 1000Genomes | |
| tmp_4_10467702_C_T | 424 | G>D | No | 1000Genomes | |
| tmp_4_10467685_C_A | 430 | A>S | No | 1000Genomes | |
| ENSVATH02880233 | 462 | E>Q | No | 1000Genomes | |
| ENSVATH02880232 | 466 | N>D | No | 1000Genomes | |
| tmp_4_10467565_T_C | 470 | R>G | No | 1000Genomes | |
| ENSVATH12007356 | 470 | R>K | No | 1000Genomes | |
| ENSVATH02880231 | 470 | R>S | No | 1000Genomes | |
| ENSVATH06722608 | 482 | R>Q | No | 1000Genomes | |
| tmp_4_10467500_A_T | 491 | D>E | No | 1000Genomes | |
| tmp_4_10467456_G_A | 506 | T>I | No | 1000Genomes | |
| ENSVATH00522299 | 510 | P>L | No | 1000Genomes | |
| tmp_4_10467426_C_T | 516 | S>N | No | 1000Genomes | |
| tmp_4_10467381_G_T | 531 | A>D | No | 1000Genomes | |
| tmp_4_10467382_C_A | 531 | A>S | No | 1000Genomes | |
| tmp_4_10467360_T_C | 538 | D>G | No | 1000Genomes | |
| tmp_4_10467337_T_A | 546 | T>S | No | 1000Genomes | |
| tmp_4_10467331_T_A | 548 | N>Y | No | 1000Genomes | |
| tmp_4_10467327_CCAT_GCAT,C | 549 | G>A | No | 1000Genomes | |
| ENSVATH12007355 | 550 | D>N | No | 1000Genomes | |
| tmp_4_10467315_C_T | 553 | W>* | No | 1000Genomes | |
| tmp_4_10467235_C_T | 580 | D>N | No | 1000Genomes | |
| ENSVATH00522296 | 583 | C>W | No | 1000Genomes | |
| ENSVATH12007344 | 590 | A>T | No | 1000Genomes | |
| ENSVATH06722599 | 599 | A>S | No | 1000Genomes | |
| tmp_4_10467166_A_T | 603 | Y>N | No | 1000Genomes | |
| ENSVATH06722598 | 607 | N>Y | No | 1000Genomes | |
| ENSVATH06722597 | 609 | H>D | No | 1000Genomes | |
| ENSVATH06722596 | 609 | H>Q | No | 1000Genomes | |
| ENSVATH06722594 | 612 | E>D | No | 1000Genomes | |
| ENSVATH06722595 | 612 | E>V | No | 1000Genomes | |
| tmp_4_10467111_T_A | 621 | K>M | No | 1000Genomes | |
| tmp_4_10467090_T_A | 628 | N>I | No | 1000Genomes | |
| ENSVATH14252310 | 629 | F>I | No | 1000Genomes | |
| ENSVATH12007343 | 634 | K>N | No | 1000Genomes | |
| tmp_4_10467050_T_A,C | 641 | E>D | No | 1000Genomes | |
| tmp_4_10467046_G_T,C | 643 | R>G | No | 1000Genomes | |
| tmp_4_10467045_C_A | 643 | R>L | No | 1000Genomes | |
| tmp_4_10467046_G_T,C | 643 | R>S | No | 1000Genomes | |
| tmp_4_10467043_C_T | 644 | V>M | No | 1000Genomes | |
| tmp_4_10467031_C_T | 648 | V>I | No | 1000Genomes | |
| ENSVATH00522294 | 650 | K>E | No | 1000Genomes | |
| tmp_4_10467023_T_A | 650 | K>N | No | 1000Genomes | |
| tmp_4_10467000_G_A | 658 | A>V | No | 1000Genomes | |
| tmp_4_10466998_C_T | 659 | D>N | No | 1000Genomes | |
| tmp_4_10466991_C_A | 661 | R>M | No | 1000Genomes | |
| tmp_4_10466979_C_T | 665 | G>D | No | 1000Genomes | |
| ENSVATH06722592 | 676 | N>S | No | 1000Genomes | |
| tmp_4_10466937_G_A | 679 | P>L | No | 1000Genomes | |
| ENSVATH00522292 | 679 | P>S | No | 1000Genomes | |
| tmp_4_10466928_G_C | 682 | P>R | No | 1000Genomes | |
| ENSVATH12007342 | 682 | P>S | No | 1000Genomes | |
| ENSVATH06722591 | 686 | D>H | No | 1000Genomes | |
| ENSVATH06722590 | 687 | Y>D | No | 1000Genomes | |
| ENSVATH06722589 | 688 | N>S | No | 1000Genomes | |
| tmp_4_10466895_T_C | 693 | N>S | No | 1000Genomes | |
| tmp_4_10466893_T_G | 694 | T>P | No | 1000Genomes | |
| ENSVATH02880227 | 697 | G>E | No | 1000Genomes | |
| tmp_4_10466866_C_A | 703 | D>Y | No | 1000Genomes | |
| tmp_4_10466831_T_A | 714 | L>F | No | 1000Genomes | |
| tmp_4_10466815_C_G | 720 | G>R | No | 1000Genomes | |
| tmp_4_10466798_G_T | 725 | H>Q | No | 1000Genomes | |
| ENSVATH06722583 | 730 | G>S | No | 1000Genomes | |
| tmp_4_10466775_G_T | 733 | T>N | No | 1000Genomes | |
| tmp_4_10466772_C_G | 734 | S>T | No | 1000Genomes | |
| tmp_4_10466760_C_A | 738 | C>F | No | 1000Genomes | |
| ENSVATH06722582 | 747 | K>N | No | 1000Genomes | |
| tmp_4_10466718_G_A | 752 | T>I | No | 1000Genomes | |
| tmp_4_10466716_T_C | 753 | K>E | No | 1000Genomes | |
| ENSVATH12007341 | 755 | Q>H | No | 1000Genomes | |
| tmp_4_10466706_T_G | 756 | E>A | No | 1000Genomes | |
| ENSVATH06722580 | 760 | Y>D | No | 1000Genomes | |
| ENSVATH06722579 | 765 | Y>F | No | 1000Genomes | |
| tmp_4_10466668_T_A | 769 | T>S | No | 1000Genomes | |
| tmp_4_10466665_C_T | 770 | G>R | No | 1000Genomes | |
| ENSVATH02880226 | 774 | G>E | No | 1000Genomes | |
| tmp_4_10466632_C_G | 781 | V>L | No | 1000Genomes |
No associated diseases with F4JSG3
6 regional properties for F4JSG3
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Zinc finger, CCHC-type | 735 - 749 | IPR001878 |
| domain | OB-fold nucleic acid binding domain, AA-tRNA synthetase-type | 241 - 326 | IPR004365 |
| domain | Replication factor-A protein 1, N-terminal | 5 - 107 | IPR007199 |
| domain | Replication factor A, C-terminal | 512 - 662 | IPR013955 |
| domain | Replication protein A, OB domain | 351 - 455 | IPR031657 |
| domain | Replication factor A, C-terminal, eukaryotes | 496 - 669 | IPR047192 |
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| DNA replication factor A complex | A conserved heterotrimeric complex that binds nonspecifically to single-stranded DNA and is required for multiple processes in eukaryotic DNA metabolism, including DNA replication, DNA repair, and recombination. In all eukaryotic organisms examined the complex is composed of subunits of approximately 70, 30, and 14 kDa. |
3 GO annotations of molecular function
| Name | Definition |
|---|---|
| damaged DNA binding | Binding to damaged DNA. |
| single-stranded telomeric DNA binding | Binding to single-stranded telomere-associated DNA. |
| zinc ion binding | Binding to a zinc ion (Zn). |
5 GO annotations of biological process
| Name | Definition |
|---|---|
| DNA unwinding involved in DNA replication | The process in which interchain hydrogen bonds between two strands of DNA are broken or 'melted', generating unpaired template strands for DNA replication. |
| double-strand break repair via homologous recombination | The error-free repair of a double-strand break in DNA in which the broken DNA molecule is repaired using homologous sequences. A strand in the broken DNA searches for a homologous region in an intact chromosome to serve as the template for DNA synthesis. The restoration of two intact DNA molecules results in the exchange, reciprocal or nonreciprocal, of genetic material between the intact DNA molecule and the broken DNA molecule. |
| meiotic cell cycle | Progression through the phases of the meiotic cell cycle, in which canonically a cell replicates to produce four offspring with half the chromosomal content of the progenitor cell via two nuclear divisions. |
| nucleotide-excision repair | A DNA repair process in which a small region of the strand surrounding the damage is removed from the DNA helix as an oligonucleotide. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. Nucleotide excision repair recognizes a wide range of substrates, including damage caused by UV irradiation (pyrimidine dimers and 6-4 photoproducts) and chemicals (intrastrand cross-links and bulky adducts). |
| telomere maintenance via telomerase | The maintenance of proper telomeric length by the addition of telomeric repeats by telomerase. |
8 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q5ZJJ2 | RPA1 | Replication protein A 70 kDa DNA-binding subunit | Gallus gallus (Chicken) | PR |
| Q24492 | RpA-70 | Replication protein A 70 kDa DNA-binding subunit | Drosophila melanogaster (Fruit fly) | PR |
| P27694 | RPA1 | Replication protein A 70 kDa DNA-binding subunit | Homo sapiens (Human) | PR |
| Q8VEE4 | Rpa1 | Replication protein A 70 kDa DNA-binding subunit | Mus musculus (Mouse) | PR |
| Q10Q08 | RPA1B | Replication protein A 70 kDa DNA-binding subunit B | Oryza sativa subsp japonica (Rice) | PR |
| Q19537 | rpa-1 | Probable replication factor A 73 kDa subunit | Caenorhabditis elegans | PR |
| Q9SKI4 | RPA1A | Replication protein A 70 kDa DNA-binding subunit A | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q5FW17 | rpa1 | Replication protein A 70 kDa DNA-binding subunit | Xenopus tropicalis (Western clawed frog) (Silurana tropicalis) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MEVSLTAGAI | GKIMNGEVTT | EADMIPVLQV | TDLKQIMAQQ | DPTRERFRMV | LSDGTYLHQG |
| 70 | 80 | 90 | 100 | 110 | 120 |
| MLGTDLNNLV | KEGTLQPGSI | VRLTRFVGDV | IKGRRIVIVP | QLEVLKQISD | IIGHPVPGGK |
| 130 | 140 | 150 | 160 | 170 | 180 |
| HNDQRGADSG | IKFNTTEQQG | SGIRQVNNIE | PGRSNAAISP | QVGGTGSSVP | ASTTPSTRAY |
| 190 | 200 | 210 | 220 | 230 | 240 |
| SNPSSGNGVT | RQDYARDPPT | SYPHQPQPPP | PMYANRGPVA | RNEAPPKIIP | VNALSPYSGR |
| 250 | 260 | 270 | 280 | 290 | 300 |
| WTIKARVTNK | AALKQYSNPR | GEGKVFNFDL | LDADGGEIRV | TCFNAVADQF | YDQIVVGNLY |
| 310 | 320 | 330 | 340 | 350 | 360 |
| LISRGSLRPA | QKNFNHLRND | YEIMLDNAST | IKQCYEEDAA | IPRHQFHFRT | IGDIESMENN |
| 370 | 380 | 390 | 400 | 410 | 420 |
| CIVDVIGIVS | SISPTVTITR | KNGTATPKRS | LQLKDMSGRS | VEVTMWGDFC | NAEGQRLQSL |
| 430 | 440 | 450 | 460 | 470 | 480 |
| CDSGVFPVLA | VKAGRISEFN | GKTVSTIGSS | QLFIDPDFVE | AEKLKNWFER | EGKSVPCISL |
| 490 | 500 | 510 | 520 | 530 | 540 |
| SREFSGSGKV | DVRKTISQIK | DEKLGTSEKP | DWITVSATIL | YLKFDNFCYT | ACPIMNGDRP |
| 550 | 560 | 570 | 580 | 590 | 600 |
| CSKKVTDNGD | GTWRCEKCDK | SVDECDYRYI | LQLQIQDHTD | LTCVTAFQEA | GEEIMGISAK |
| 610 | 620 | 630 | 640 | 650 | 660 |
| DLYYVKNEHK | DEEKFEDIIR | KVAFTKYNFK | LKVKEETFSD | EQRVKATVVK | VDKLNYSADT |
| 670 | 680 | 690 | 700 | 710 | 720 |
| RTMLGAMDKL | RTRDANSLPI | NPEGSDYNAD | VVNTGIGSSG | TRDPSSVQRR | DFGLHAHQSG |
| 730 | 740 | 750 | 760 | 770 | 780 |
| QSGNHYSGGG | ATTSCNVCGN | SGHVSAKCPG | ATKPQEQGQY | MGGSYRGTTG | SYGGGLPRQH |
| VGSY |