Q86VN1
Gene name |
VPS36 (C13orf9, EAP45, CGI-145) |
Protein name |
Vacuolar protein-sorting-associated protein 36 |
Names |
ELL-associated protein of 45 kDa, ESCRT-II complex subunit VPS36 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:51028 |
EC number |
|
Protein Class |
|
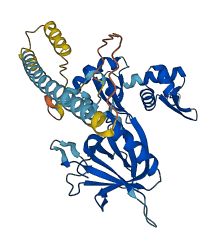
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
4 structures for Q86VN1
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 2HTH | X-ray | 270 A | B | 1-138 | PDB |
| 2ZME | X-ray | 290 A | B | 149-386 | PDB |
| 3CUQ | X-ray | 261 A | B | 169-386 | PDB |
| AF-Q86VN1-F1 | Predicted | AlphaFoldDB |
237 variants for Q86VN1
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs1263446947 CA388047106 |
2 | D>G | No |
ClinGen gnomAD |
|
|
CA6992677 rs577147750 |
3 | R>C | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA6992676 rs577147750 |
3 | R>G | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA6992675 rs761266589 |
6 | W>R | No |
ClinGen ExAC gnomAD |
|
|
rs1273724103 CA388047072 |
7 | T>S | No |
ClinGen gnomAD |
|
|
CA6992674 rs773815112 |
8 | S>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA6992672 rs373489248 |
10 | L>F | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA6992670 rs769324003 |
11 | L>Q | No |
ClinGen ExAC gnomAD |
|
|
CA6992669 rs745439453 |
14 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA6992668 rs780687417 |
16 | T>S | No |
ClinGen ExAC gnomAD |
|
|
CA250077887 rs986422035 |
18 | V>E | No |
ClinGen TOPMed |
|
|
rs953628242 CA250077882 |
19 | I>F | No |
ClinGen TOPMed |
|
| TCGA novel | 19 | I>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs11545440 CA250077881 |
20 | Q>K | No |
ClinGen Ensembl |
|
|
CA388046972 rs1167635526 |
21 | Q>L | No |
ClinGen gnomAD |
|
|
CA388046956 rs1364480857 |
22 | R>L | No |
ClinGen TOPMed |
|
|
rs913841674 CA250077864 |
22 | R>S | No |
ClinGen Ensembl |
|
|
CA388046954 rs1391579919 CA388046953 |
23 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1053525221 CA250077861 |
23 | G>V | No |
ClinGen Ensembl |
|
|
rs1566093053 CA388046944 |
24 | V>M | No |
ClinGen Ensembl |
|
|
CA388046925 rs1566093047 |
25 | R>P | No |
ClinGen Ensembl |
|
|
rs1566093047 CA388046927 |
25 | R>Q | No |
ClinGen Ensembl |
|
|
CA388046912 rs1453233117 |
26 | I>S | No |
ClinGen gnomAD |
|
|
CA388046897 rs1195410170 |
27 | Y>C | No |
ClinGen gnomAD |
|
|
rs1249733810 CA388046865 |
29 | G>D | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA388046874 rs1435945921 |
29 | G>S | No |
ClinGen gnomAD |
|
|
CA6992663 rs752432200 |
30 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388046862 rs1248178739 |
30 | E>K | No |
ClinGen TOPMed |
|
|
CA6992662 rs568175027 |
31 | E>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
| TCGA novel | 31 | E>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA388046828 rs1161272051 |
32 | K>R | No |
ClinGen gnomAD |
|
|
CA6992633 rs763285959 |
33 | I>M | No |
ClinGen ExAC gnomAD |
|
|
CA6992634 rs764392240 |
33 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs764636096 CA250072993 |
35 | F>V | No |
ClinGen Ensembl |
|
|
CA388046448 rs1594123821 |
36 | D>V | No |
ClinGen Ensembl |
|
|
CA388046428 rs1238247404 |
39 | T>I | No |
ClinGen gnomAD |
|
| TCGA novel | 40 | L>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1465760486 CA388046421 |
41 | L>F | No |
ClinGen TOPMed |
|
| rs763216059 | 42 | L>missing | Variant assessed as Somatic; 4.625e-05 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA250072973 rs949189663 |
44 | T>I | No |
ClinGen Ensembl |
|
|
rs772613576 CA6992629 |
45 | H>Q | No |
ClinGen ExAC gnomAD |
|
|
rs1056739271 CA250072953 |
46 | R>* | No |
ClinGen TOPMed |
|
|
CA6992628 rs567352617 |
46 | R>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA388046377 rs1233000698 |
48 | I>T | No |
ClinGen gnomAD |
|
|
CA388046344 rs1356552755 |
52 | Q>H | No |
ClinGen gnomAD |
|
|
CA388046328 rs1236090178 |
54 | N>K | No |
ClinGen TOPMed |
|
|
rs1211602507 CA388046304 |
56 | E>G | No |
ClinGen TOPMed |
|
|
rs1325133741 CA388046306 |
56 | E>Q | No |
ClinGen gnomAD |
|
|
CA388046274 rs1594122071 |
60 | A>S | No |
ClinGen Ensembl |
|
|
CA6992609 rs760326692 |
61 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs1167973976 CA388046257 |
62 | L>P | No |
ClinGen gnomAD |
|
|
rs1268936974 CA388046254 |
63 | L>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs1409185275 CA388046248 |
64 | S>A | No |
ClinGen gnomAD |
|
|
rs1419009084 CA388046228 |
67 | V>M | No |
ClinGen gnomAD |
|
|
CA6992607 rs771502892 |
69 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1028369384 CA250068439 |
69 | I>V | No |
ClinGen gnomAD |
|
|
CA388046204 rs1566088985 |
70 | E>D | No |
ClinGen Ensembl |
|
|
CA388046210 rs1193104384 |
70 | E>Q | No |
ClinGen gnomAD |
|
|
rs564047614 CA6992606 |
71 | E>K | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs768575745 CA388046191 |
72 | Q>L | No |
ClinGen gnomAD |
|
|
rs768575745 CA250068431 |
72 | Q>R | No |
ClinGen gnomAD |
|
|
CA388046185 rs185573531 |
73 | A>E | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs185573531 CA6992605 |
73 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA6992603 rs749149596 |
74 | A>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 75 | G>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA6992602 rs201611503 |
75 | G>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA388046164 rs1173441150 |
77 | G>W | No |
ClinGen TOPMed |
|
|
CA6992582 rs762986715 |
80 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1037480527 CA388046124 |
81 | K>I | No |
ClinGen TOPMed gnomAD |
|
|
rs1037480527 CA250066979 |
81 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
CA388046108 rs1413345451 |
84 | V>F | No |
ClinGen gnomAD |
|
|
rs1184734095 CA388046098 |
85 | H>R | No |
ClinGen gnomAD |
|
|
rs1256335544 CA388046078 |
88 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
CA388046077 rs1256335544 |
88 | P>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs865991502 CA250066974 |
88 | P>S | No |
ClinGen Ensembl |
|
|
CA388046056 rs1483942214 |
92 | N>D | No |
ClinGen gnomAD |
|
|
CA250066963 rs926534991 |
92 | N>K | No |
ClinGen Ensembl |
|
|
CA250066960 rs940562696 |
95 | P>H | No |
ClinGen TOPMed |
|
|
rs776789902 CA6992577 |
99 | Q>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs371106659 CA6992576 |
100 | S>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 101 | S>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA388045986 rs747142932 |
102 | K>* | No |
ClinGen ExAC gnomAD |
|
|
rs747142932 CA6992575 |
102 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs758434923 CA6992573 |
104 | S>A | No |
ClinGen ExAC gnomAD |
|
|
rs748675244 CA6992572 |
105 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs779368783 CA6992571 |
106 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA388045943 rs1381632972 COSM1232380 |
108 | L>P | large_intestine [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA388045936 rs1324803332 |
109 | S>C | No |
ClinGen TOPMed |
|
|
rs755336970 CA6992570 |
111 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs767129941 CA6992568 |
113 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA6992569 rs377668244 |
113 | H>Y | No |
ClinGen ESP ExAC gnomAD |
|
|
CA6992566 rs751102773 |
114 | G>C | No |
ClinGen ExAC |
|
|
CA6992540 rs751307637 |
118 | F>V | No |
ClinGen ExAC gnomAD |
|
|
rs752241758 CA388045842 |
121 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs140039960 CA6992536 |
121 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA6992537 rs752241758 |
121 | R>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388045838 rs1373077735 |
122 | L>V | No |
ClinGen gnomAD |
|
|
rs759526314 CA6992535 |
126 | M>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 128 | Q>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA388045779 rs1444501222 |
130 | R>K | No |
ClinGen TOPMed gnomAD |
|
|
rs778764463 CA6992533 |
131 | W>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388045757 rs1388857874 |
133 | N>D | No |
ClinGen gnomAD |
|
|
rs1271665869 CA388045746 |
134 | M>T | No |
ClinGen TOPMed |
|
|
rs1429931246 CA388045723 |
138 | Q>K | No |
ClinGen gnomAD |
|
|
rs150589000 CA6992531 |
138 | Q>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs772273059 CA6992530 |
141 | Q>K | No |
ClinGen ExAC gnomAD |
|
|
rs1378110757 CA388045686 |
143 | N>S | No |
ClinGen gnomAD |
|
|
CA388045667 rs1417073429 |
146 | P>T | No |
ClinGen gnomAD |
|
|
rs1203707334 CA388045642 |
148 | P>S | No |
ClinGen TOPMed |
|
|
rs767241247 CA6992508 |
150 | R>G | No |
ClinGen ExAC gnomAD |
|
|
CA6992507 rs762027049 |
151 | I>L | No |
ClinGen ExAC gnomAD |
|
|
rs933736917 CA388045617 |
152 | R>K | No |
ClinGen TOPMed gnomAD |
|
|
rs933736917 CA250065809 |
152 | R>M | No |
ClinGen TOPMed gnomAD |
|
|
CA388045608 rs1340708870 |
154 | V>I | No |
ClinGen gnomAD |
|
|
rs1277140565 CA388045595 |
156 | I>V | No |
ClinGen TOPMed |
|
|
CA388045587 rs1221058057 |
157 | V>L | No |
ClinGen TOPMed |
|
|
CA388045555 rs764254757 |
162 | K>E | No |
ClinGen ExAC gnomAD |
|
|
CA6992505 rs764254757 |
162 | K>Q | No |
ClinGen ExAC gnomAD |
|
|
rs762913176 CA6992504 |
167 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
| rs777713470 | 167 | R>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA6992502 rs531572536 |
168 | K>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs144817587 COSM108425 CA250065800 |
169 | E>K | skin [Cosmic] | No |
ClinGen cosmic curated Ensembl |
|
CA388045494 rs1162446592 |
170 | T>I | No |
ClinGen gnomAD |
|
|
CA6992501 rs201878072 |
172 | K>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1189648968 CA388045471 |
173 | N>K | No |
ClinGen gnomAD |
|
|
CA388045475 rs1238301507 |
173 | N>T | No |
ClinGen gnomAD |
|
|
CA388045196 rs1221269957 |
177 | A>S | No |
ClinGen gnomAD |
|
|
CA6992477 rs774117351 |
181 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs889215243 CA250064000 |
183 | K>N | No |
ClinGen TOPMed gnomAD |
|
|
rs1178981124 CA388045130 |
183 | K>Q | No |
ClinGen TOPMed |
|
|
CA388045096 CA6992475 rs748909695 |
185 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs1341038841 CA388045105 |
185 | M>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1341038841 CA388045107 |
185 | M>V | No |
ClinGen TOPMed gnomAD |
|
|
CA6992474 rs779434828 |
186 | I>F | No |
ClinGen ExAC gnomAD |
|
|
CA388044985 rs1369651793 |
192 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
CA6992459 rs773458066 |
195 | S>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1409019088 CA388044914 |
198 | I>V | No |
ClinGen gnomAD |
|
|
rs772410580 CA6992458 |
204 | D>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA250063961 rs976576823 |
205 | K>Q | No |
ClinGen TOPMed |
|
|
CA388044800 rs1431704845 |
207 | G>D | No |
ClinGen gnomAD |
|
| TCGA novel | 211 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs563700906 CA250063956 |
212 | D>E | No |
ClinGen Ensembl |
|
|
rs1427906865 CA388044738 |
212 | D>G | No |
ClinGen gnomAD |
|
|
rs1415478424 CA388044745 |
212 | D>Y | No |
ClinGen gnomAD |
|
|
rs769341330 CA6992454 |
213 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs1228902577 CA388044646 |
214 | T>N | No |
ClinGen TOPMed |
|
|
rs1012947506 CA250063664 |
217 | F>I | No |
ClinGen TOPMed |
|
|
rs1246112588 CA388044596 |
218 | K>N | No |
ClinGen gnomAD |
|
|
CA388044589 rs1208096691 |
219 | S>Y | No |
ClinGen gnomAD |
|
|
rs759133031 CA6992432 |
222 | L>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs759133031 CA6992431 |
222 | L>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs894811249 CA250063661 |
222 | L>V | No |
ClinGen Ensembl |
|
|
rs1269718136 CA388044551 |
223 | S>C | No |
ClinGen gnomAD |
|
|
CA388044467 rs1256158607 |
230 | V>A | No |
ClinGen TOPMed |
|
|
rs1480115640 CA388044454 |
232 | R>G | No |
ClinGen TOPMed |
|
|
rs1320092151 CA388044447 |
232 | R>K | No |
ClinGen gnomAD |
|
|
CA388044435 rs1193528513 |
233 | E>G | No |
ClinGen TOPMed |
|
|
CA6992429 rs770436208 |
235 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA6992426 rs771805336 |
236 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA6992427 rs771805336 |
236 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs747955028 COSM948087 CA6992425 |
239 | T>A | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs1393005925 CA388044371 |
239 | T>I | No |
ClinGen gnomAD |
|
|
rs1390024952 CA388044362 |
240 | Q>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1390024952 CA388044363 |
240 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA6992424 rs779332765 |
241 | Y>H | No |
ClinGen ExAC |
|
|
rs1023958760 CA250063632 |
242 | H>R | No |
ClinGen TOPMed |
|
|
CA250063629 rs148021124 |
243 | M>I | No |
ClinGen ESP |
|
|
CA6992421 rs780307997 |
246 | A>G | No |
ClinGen ExAC gnomAD |
|
|
rs750941087 CA6992419 |
247 | K>I | No |
ClinGen ExAC gnomAD |
|
|
rs1387727498 CA388044252 |
250 | A>T | No |
ClinGen gnomAD |
|
|
rs768035586 CA6992418 |
252 | I>M | No |
ClinGen ExAC gnomAD |
|
|
rs1490889314 CA388043585 |
260 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA250062989 rs937872451 |
261 | G>A | No |
ClinGen TOPMed |
|
|
rs979318014 CA250062985 |
263 | I>M | No |
ClinGen TOPMed |
|
|
rs144558806 CA6992394 |
263 | I>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs758744494 CA6992393 |
265 | S>P | No |
ClinGen ExAC gnomAD |
|
|
CA6992391 rs138713397 |
267 | T>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs867642870 CA388043493 |
268 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
rs766868664 CA6992388 |
275 | R>* | No |
ClinGen ExAC TOPMed |
|
|
rs1330972941 COSM297920 CA388043404 |
277 | R>* | large_intestine Variant assessed as Somatic; impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
CA6992387 rs761869362 |
277 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388043380 rs1348220905 |
279 | M>I | No |
ClinGen gnomAD |
|
|
CA388042667 rs753095007 |
282 | L>I | No |
ClinGen ExAC gnomAD |
|
|
rs753095007 CA6992372 |
282 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs1303208194 CA388042656 |
283 | S>P | No |
ClinGen TOPMed |
|
|
CA388042643 rs1372427100 |
284 | P>S | No |
ClinGen TOPMed |
|
|
CA388042638 rs1337164881 |
285 | E>Q | No |
ClinGen gnomAD |
|
|
CA388042551 rs1331574053 |
289 | N>K | No |
ClinGen gnomAD |
|
|
rs779092607 CA6992371 COSM300129 |
290 | A>V | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs750000143 CA6992369 |
293 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs767072520 CA6992368 |
295 | E>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388042442 rs1411030861 |
296 | A>V | No |
ClinGen gnomAD |
|
|
CA388042435 rs1325852589 |
297 | L>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs761384772 CA6992367 |
298 | K>T | No |
ClinGen ExAC gnomAD |
|
|
rs957856347 CA250061297 |
300 | P>R | No |
ClinGen gnomAD |
|
|
CA388042367 rs1234837327 |
301 | L>P | No |
ClinGen gnomAD |
|
|
CA388042245 rs1240260591 |
303 | L>F | No |
ClinGen gnomAD |
|
|
rs778313209 CA6992357 |
304 | R>C | No |
ClinGen ExAC gnomAD |
|
|
CA6992356 rs145896285 |
304 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs145896285 CA388042230 |
304 | R>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA388042222 rs1449138233 |
305 | V>L | No |
ClinGen gnomAD |
|
|
CA6992354 rs779363980 |
310 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA6992353 rs755244819 |
311 | M>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs750136185 CA6992352 |
313 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs756894284 CA6992350 |
316 | Q>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs943817245 CA250061108 |
317 | S>F | No |
ClinGen Ensembl |
|
|
rs1298293742 CA388042001 |
318 | H>Y | No |
ClinGen TOPMed gnomAD |
|
|
rs912383022 CA250061106 |
319 | K>E | No |
ClinGen TOPMed |
|
|
rs1040812952 CA250061104 |
319 | K>R | No |
ClinGen TOPMed |
|
|
rs868577151 CA250061102 |
321 | E>G | No |
ClinGen Ensembl |
|
|
rs763638585 CA6992348 |
322 | E>G | No |
ClinGen ExAC gnomAD |
|
|
rs763017466 COSM130171 CA6992347 |
326 | S>L | upper_aerodigestive_tract Variant assessed as Somatic; 0.0 impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
| TCGA novel | 327 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1367291453 CA388041002 |
329 | E>K | No |
ClinGen TOPMed |
|
|
CA6992345 rs765128734 |
330 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA388040771 rs1270589967 |
331 | V>L | No |
ClinGen gnomAD |
|
|
rs1179647843 CA388040691 |
334 | K>E | No |
ClinGen gnomAD |
|
|
rs757826427 CA6992328 |
336 | S>T | No |
ClinGen ExAC gnomAD |
|
|
CA250060895 rs369735041 |
343 | A>V | No |
ClinGen ESP |
|
|
CA6992324 rs753651402 |
345 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA6992323 rs766099499 |
348 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs1360048118 CA388040359 |
350 | V>A | No |
ClinGen gnomAD |
|
|
rs1594110507 CA388040227 |
356 | R>T | No |
ClinGen Ensembl |
|
|
rs574568412 CA250060877 |
358 | L>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA388040054 rs1295141591 |
359 | L>R | No |
ClinGen TOPMed |
|
|
rs747600868 CA6992301 |
365 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1227765659 CA388039913 |
366 | L>F | No |
ClinGen TOPMed |
|
|
rs778431031 CA6992300 |
368 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs368445598 CA6992299 |
368 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA388039794 rs1453931504 |
371 | S>* | No |
ClinGen gnomAD |
|
|
CA6992296 rs374745105 |
376 | R>C | No |
ClinGen ESP ExAC gnomAD |
|
|
CA388039699 rs750681798 COSM3376574 |
376 | R>H | pancreas [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs750681798 CA6992295 |
376 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs767628596 CA6992294 |
378 | Y>C | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 378 | Y>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs762009281 CA6992293 |
379 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs942861593 CA250060876 |
387 | S>L | No |
ClinGen Ensembl |
No associated diseases with Q86VN1
1 regional properties for Q86VN1
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Vacuolar protein sorting protein 36, GLUE domain | 1 - 138 | IPR021648 |
Functions
7 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| endosome | A vacuole to which materials ingested by endocytosis are delivered. |
| ESCRT II complex | An endosomal sorting complex required for transport and functions downstream of ESCRT I complex. It consists of the class E vacuolar protein sorting (Vps) proteins and is required for the membrane recruitment of ESCRT III complex and binds to ubiquitinated cargoes. |
| extracellular exosome | A vesicle that is released into the extracellular region by fusion of the limiting endosomal membrane of a multivesicular body with the plasma membrane. Extracellular exosomes, also simply called exosomes, have a diameter of about 40-100 nm. |
| late endosome membrane | The lipid bilayer surrounding a late endosome. |
| lysosome | A small lytic vacuole that has cell cycle-independent morphology found in most animal cells and that contains a variety of hydrolases, most of which have their maximal activities in the pH range 5-6. The contained enzymes display latency if properly isolated. About 40 different lysosomal hydrolases are known and lysosomes have a great variety of morphologies and functions. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
3 GO annotations of molecular function
| Name | Definition |
|---|---|
| phosphatidylinositol-3-phosphate binding | Binding to phosphatidylinositol-3-phosphate, a derivative of phosphatidylinositol in which the inositol ring is phosphorylated at the 3' position. |
| protein C-terminus binding | Binding to a protein C-terminus, the end of a peptide chain at which the 1-carboxyl function of a constituent amino acid is not attached in peptide linkage to another amino-acid residue. |
| ubiquitin binding | Binding to ubiquitin, a protein that when covalently bound to other cellular proteins marks them for proteolytic degradation. |
4 GO annotations of biological process
| Name | Definition |
|---|---|
| macroautophagy | The major inducible pathway for the general turnover of cytoplasmic constituents in eukaryotic cells, it is also responsible for the degradation of active cytoplasmic enzymes and organelles during nutrient starvation. Macroautophagy involves the formation of double-membrane-bounded autophagosomes which enclose the cytoplasmic constituent targeted for degradation in a membrane-bounded structure. Autophagosomes then fuse with a lysosome (or vacuole) releasing single-membrane-bounded autophagic bodies that are then degraded within the lysosome (or vacuole). Some types of macroautophagy, e.g. pexophagy, mitophagy, involve selective targeting of the targets to be degraded. |
| membrane fission | A process that is carried out at the cellular level which results in the separation of a single continuous membrane into two membranes. |
| multivesicular body assembly | The aggregation, arrangement and bonding together of a set of components to form a multivesicular body, a type of late endosome in which regions of the limiting endosomal membrane invaginate to form internal vesicles; membrane proteins that enter the internal vesicles are sequestered from the cytoplasm. |
| protein transport to vacuole involved in ubiquitin-dependent protein catabolic process via the multivesicular body sorting pathway | The process of directing proteins towards the vacuole that contributes to protein catabolism via the multivesicular body (MVB) pathway. |
3 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| A5PK00 | VPS36 | Vacuolar protein-sorting-associated protein 36 | Bos taurus (Bovine) | PR |
| Q9VU87 | Vps36 | Vacuolar protein-sorting-associated protein 36 | Drosophila melanogaster (Fruit fly) | PR |
| Q7ZVK4 | vps36 | Vacuolar protein-sorting-associated protein 36 | Danio rerio (Zebrafish) (Brachydanio rerio) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MDRFVWTSGL | LEINETLVIQ | QRGVRIYDGE | EKIKFDAGTL | LLSTHRLIWR | DQKNHECCMA |
| 70 | 80 | 90 | 100 | 110 | 120 |
| ILLSQIVFIE | EQAAGIGKSA | KIVVHLHPAP | PNKEPGPFQS | SKNSYIKLSF | KEHGQIEFYR |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RLSEEMTQRR | WENMPVSQSL | QTNRGPQPGR | IRAVGIVGIE | RKLEEKRKET | DKNISEAFED |
| 190 | 200 | 210 | 220 | 230 | 240 |
| LSKLMIKAKE | MVELSKSIAN | KIKDKQGDIT | EDETIRFKSY | LLSMGIANPV | TRETYGSGTQ |
| 250 | 260 | 270 | 280 | 290 | 300 |
| YHMQLAKQLA | GILQVPLEER | GGIMSLTEVY | CLVNRARGME | LLSPEDLVNA | CKMLEALKLP |
| 310 | 320 | 330 | 340 | 350 | 360 |
| LRLRVFDSGV | MVIELQSHKE | EEMVASALET | VSEKGSLTSE | EFAKLVGMSV | LLAKERLLLA |
| 370 | 380 | ||||
| EKMGHLCRDD | SVEGLRFYPN | LFMTQS |