Q7Z7C8
Gene name |
TAF8 (TAFII43, TBN) |
Protein name |
Transcription initiation factor TFIID subunit 8 |
Names |
Protein taube nuss, TBP-associated factor 43 kDa, TBP-associated factor 8, Transcription initiation factor TFIID 43 kDa subunit, TAFII-43, TAFII43, hTAFII43 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:129685 |
EC number |
|
Protein Class |
|
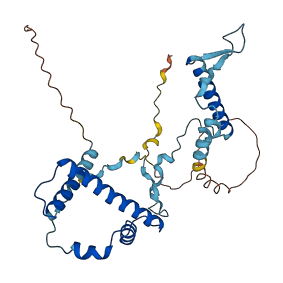
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
32 structures for Q7Z7C8
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 4WV4 | X-ray | 191 A | B | 25-120 | PDB |
| 4WV6 | X-ray | 175 A | B/C | 297-310 | PDB |
| 5FUR | EM | 850 A | L | 1-310 | PDB |
| 6MZC | EM | 450 A | K | 1-310 | PDB |
| 6MZL | EM | 2300 A | K | 1-310 | PDB |
| 6MZM | EM | 750 A | K | 1-310 | PDB |
| 7EDX | EM | 450 A | H | 1-310 | PDB |
| 7EG7 | EM | 620 A | H | 1-310 | PDB |
| 7EG8 | EM | 740 A | H | 1-310 | PDB |
| 7EG9 | EM | 370 A | H | 1-310 | PDB |
| 7EGA | EM | 410 A | H | 1-310 | PDB |
| 7EGB | EM | 330 A | H | 1-310 | PDB |
| 7EGC | EM | 390 A | H | 1-310 | PDB |
| 7EGD | EM | 675 A | H | 1-310 | PDB |
| 7EGE | EM | 900 A | H | 1-310 | PDB |
| 7EGG | EM | 277 A | H | 1-310 | PDB |
| 7EGH | EM | 304 A | H | 1-310 | PDB |
| 7EGI | EM | 982 A | H | 1-310 | PDB |
| 7EGJ | EM | 864 A | H | 1-310 | PDB |
| 7ENA | EM | 407 A | DH | 1-310 | PDB |
| 7ENC | EM | 413 A | DH | 1-310 | PDB |
| 8GXQ | EM | 504 A | DH | 1-310 | PDB |
| 8GXS | EM | 416 A | DH | 1-310 | PDB |
| 8WAK | EM | 547 A | H | 1-310 | PDB |
| 8WAL | EM | 852 A | H | 1-310 | PDB |
| 8WAN | EM | 607 A | H | 1-310 | PDB |
| 8WAO | EM | 640 A | H | 1-310 | PDB |
| 8WAP | EM | 585 A | H | 1-310 | PDB |
| 8WAQ | EM | 629 A | H | 1-310 | PDB |
| 8WAR | EM | 720 A | H | 1-310 | PDB |
| 8WAS | EM | 613 A | H | 1-310 | PDB |
| AF-Q7Z7C8-F1 | Predicted | AlphaFoldDB |
301 variants for Q7Z7C8
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA3804493 rs751006594 |
2 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804494 rs757004180 |
3 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA364087416 rs1178107080 |
3 | D>N | No |
ClinGen Ensembl |
|
|
rs573020143 CA138128506 |
4 | A>G | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
rs1050521943 CA138128503 |
4 | A>P | No |
ClinGen TOPMed gnomAD |
|
|
rs1050521943 CA364087481 |
4 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
CA364087494 rs573020143 |
4 | A>V | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
CA138128507 rs555280249 |
5 | A>T | No |
ClinGen 1000Genomes TOPMed |
|
|
CA364087532 rs1286689998 |
5 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA364087537 rs1287003435 |
6 | A>T | No |
ClinGen TOPMed |
|
|
rs1435531116 CA364087550 |
6 | A>V | No |
ClinGen gnomAD |
|
|
rs768929303 CA3804497 |
7 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA138128514 rs1005039057 |
7 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
rs748678333 CA3804499 |
8 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804498 rs779286517 |
8 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs779286517 CA364087620 |
8 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364087681 rs773491807 |
10 | A>S | No |
ClinGen ExAC TOPMed |
|
|
CA3804501 rs773491807 |
10 | A>T | No |
ClinGen ExAC TOPMed |
|
|
rs183028083 CA3804502 |
10 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA138128534 rs1015767224 |
11 | G>C | No |
ClinGen TOPMed gnomAD |
|
|
rs1015767224 CA364087696 |
11 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
rs868161378 CA364087762 |
13 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
rs759765030 CA3804505 |
13 | S>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA138128555 rs868161378 |
13 | S>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA364087786 rs1160970521 |
14 | G>E | No |
ClinGen gnomAD |
|
|
CA364087765 rs1457483099 CA364087769 |
14 | G>R | No |
ClinGen gnomAD |
|
|
CA3804507 rs752435360 |
15 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364087815 rs752435360 |
15 | T>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs755786579 CA3804536 |
17 | S>L | No |
ClinGen ExAC gnomAD |
|
|
CA3804538 rs531214257 |
18 | G>* | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA3804539 rs758806468 |
18 | G>A | No |
ClinGen ExAC gnomAD |
|
|
rs531214257 CA364089438 |
18 | G>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1028796330 CA138129020 |
19 | S>R | No |
ClinGen Ensembl |
|
|
CA3804541 rs373530647 |
21 | Q>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA3804540 rs551322668 |
21 | Q>P | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1226732787 CA364089544 |
22 | S>C | No |
ClinGen gnomAD |
|
|
rs1226732787 CA364089545 |
22 | S>F | No |
ClinGen gnomAD |
|
|
CA3804542 rs757728659 |
22 | S>P | No |
ClinGen ExAC |
|
|
CA3804544 rs745958022 |
23 | T>I | No |
ClinGen ExAC |
|
|
rs781140275 CA3804543 |
23 | T>P | No |
ClinGen ExAC |
|
|
CA3804547 rs74710424 |
24 | N>T | No |
ClinGen ExAC gnomAD |
|
|
CA3804548 rs768457784 |
25 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 25 | P>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA364089678 rs1229927241 |
26 | A>T | No |
ClinGen gnomAD |
|
|
rs1310581657 CA364089704 |
27 | D>N | No |
ClinGen TOPMed |
|
|
CA364089715 rs1441355382 |
28 | N>D | No |
ClinGen gnomAD |
|
| TCGA novel | 29 | Y>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs956006606 CA138129062 |
29 | Y>C | No |
ClinGen TOPMed gnomAD |
|
|
CA364089771 rs1463375464 |
30 | H>Y | No |
ClinGen TOPMed gnomAD |
|
|
rs915130570 CA138129068 |
31 | L>R | No |
ClinGen TOPMed gnomAD |
|
|
CA364089843 rs767483326 |
33 | R>L | No |
ClinGen ExAC gnomAD |
|
|
CA3804553 rs767483326 |
33 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs772654780 CA3804554 |
34 | R>K | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 37 | L>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1413992813 CA364089927 |
37 | L>Q | No |
ClinGen gnomAD |
|
|
CA3804555 rs760208849 |
38 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804557 rs753576013 |
39 | V>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804559 rs764568765 |
40 | V>G | No |
ClinGen ExAC gnomAD |
|
|
rs1452480418 CA364090061 |
41 | V>E | No |
ClinGen Ensembl |
|
|
rs376399735 CA3804561 |
41 | V>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1273593268 CA364090093 |
43 | S>P | No |
ClinGen gnomAD |
|
|
CA3804562 rs781717709 |
44 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs1554170019 CA3804564 |
47 | E>V | No |
ClinGen Ensembl |
|
|
rs1562007337 CA364090265 |
48 | A>V | No |
ClinGen Ensembl |
|
|
CA364090304 rs1326700344 |
49 | G>A | No |
ClinGen gnomAD |
|
|
rs756213236 CA3804567 |
49 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA364090310 rs1582208388 |
50 | F>V | No |
ClinGen Ensembl |
|
|
rs780055411 CA3804568 |
52 | S>I | No |
ClinGen ExAC gnomAD |
|
|
CA364090385 rs1582208405 |
52 | S>R | No |
ClinGen Ensembl |
|
|
CA3804570 rs749522287 |
53 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364090418 rs1248371235 |
53 | A>S | No |
ClinGen gnomAD |
|
|
CA3804569 rs749522287 |
53 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA138129184 rs942821006 |
54 | E>K | No |
ClinGen gnomAD |
|
|
CA364090453 rs942821006 |
54 | E>Q | No |
ClinGen gnomAD |
|
|
rs1431674783 CA364090511 |
56 | A>V | No |
ClinGen gnomAD |
|
|
CA3804573 rs747961595 |
57 | S>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs771952250 CA3804574 |
59 | E>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs771952250 CA138129205 |
59 | E>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs370822634 CA3804575 |
60 | T>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs999781686 CA138129213 |
60 | T>M | No |
ClinGen gnomAD |
|
|
rs1436547498 CA364090601 |
61 | L>P | No |
ClinGen gnomAD |
|
|
rs770589974 CA3804577 |
61 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs374257808 CA3804578 |
63 | E>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 63 | E>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA364090657 rs1348124652 |
64 | M>L | No |
ClinGen gnomAD |
|
|
CA364090659 rs1348124652 |
64 | M>V | No |
ClinGen gnomAD |
|
|
CA364090706 rs764979779 |
66 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
rs764979779 CA3804580 |
66 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
rs1457103305 CA364092429 |
68 | Y>C | No |
ClinGen TOPMed |
|
|
CA3804603 rs750684997 |
69 | I>F | No |
ClinGen ExAC gnomAD |
|
|
CA364092454 rs750684997 |
69 | I>L | No |
ClinGen ExAC gnomAD |
|
|
rs761234284 CA3804604 |
71 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs919633649 CA138131129 |
71 | E>K | No |
ClinGen TOPMed |
|
|
CA364092602 rs1160984516 |
72 | I>M | No |
ClinGen TOPMed |
|
|
CA364092609 CA364092604 rs1473339290 |
73 | G>R | No |
ClinGen gnomAD |
|
|
rs1376582656 CA364092634 |
74 | R>G | No |
ClinGen TOPMed |
|
|
rs749824663 CA138131137 |
75 | S>N | No |
ClinGen gnomAD |
|
|
CA3804605 rs766856727 |
76 | A>G | No |
ClinGen ExAC gnomAD |
|
|
rs1041925804 CA138131142 |
76 | A>T | No |
ClinGen Ensembl |
|
|
CA364092719 rs766856727 |
76 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs755019294 CA364092740 |
77 | K>E | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 77 | K>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA3804607 rs755019294 |
77 | K>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA138131164 rs1050049842 |
77 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
CA3804610 rs758493295 |
80 | C>G | No |
ClinGen ExAC gnomAD |
|
|
CA364092814 rs758493295 |
80 | C>R | No |
ClinGen ExAC gnomAD |
|
|
rs1341430106 CA364092877 |
82 | H>Y | No |
ClinGen gnomAD |
|
|
rs1246371188 CA364092932 |
83 | T>I | No |
ClinGen TOPMed |
|
|
rs777630505 CA3804611 |
84 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA138131178 rs928658205 |
85 | R>G | No |
ClinGen TOPMed |
|
|
rs1341590714 CA364092985 |
85 | R>S | No |
ClinGen gnomAD |
|
|
CA364092964 rs928658205 |
85 | R>W | No |
ClinGen TOPMed |
|
|
rs1198889856 CA364093004 |
86 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
rs757324476 CA3804613 |
87 | Q>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804615 rs745415464 |
90 | L>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364093096 rs1185876672 |
90 | L>V | No |
ClinGen gnomAD |
|
|
CA364093149 rs1374232301 |
92 | D>A | No |
ClinGen gnomAD |
|
|
rs368588507 CA3804617 |
92 | D>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA3804619 rs547928279 |
94 | V>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA364093263 rs1318340299 |
97 | L>P | No |
ClinGen gnomAD |
|
|
CA364093261 rs1318340299 |
97 | L>R | No |
ClinGen gnomAD |
|
|
rs1454357869 CA364093255 |
97 | L>V | No |
ClinGen gnomAD |
|
|
rs536405539 CA3804621 |
98 | V>I | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs536405539 CA3804622 |
98 | V>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA364093285 rs1170298007 |
99 | E>K | No |
ClinGen TOPMed |
|
|
rs1313353543 CA364093339 |
100 | M>I | No |
ClinGen gnomAD |
|
|
rs777153742 CA3804623 |
100 | M>T | No |
ClinGen ExAC gnomAD |
|
|
rs1582216245 CA364093479 |
101 | G>D | No |
ClinGen Ensembl |
|
|
CA364093508 rs1262993724 |
103 | N>K | No |
ClinGen TOPMed gnomAD |
|
|
rs760094311 CA3804641 |
103 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA138131390 rs957816690 |
104 | V>M | No |
ClinGen TOPMed |
|
|
rs765658996 CA3804642 |
105 | D>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804643 rs765658996 |
105 | D>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364093522 rs1441419714 |
105 | D>N | No |
ClinGen TOPMed |
|
|
CA364093555 rs1281658518 |
107 | L>F | No |
ClinGen TOPMed gnomAD |
|
|
CA364093574 rs762921654 |
108 | P>L | No |
ClinGen ExAC gnomAD |
|
|
rs762921654 CA3804646 |
108 | P>R | No |
ClinGen ExAC gnomAD |
|
|
rs758273833 CA364093630 |
110 | Y>* | No |
ClinGen TOPMed gnomAD |
|
|
CA364093602 rs1419442628 |
110 | Y>N | No |
ClinGen gnomAD |
|
| TCGA novel | 111 | A>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA3804648 rs751865496 |
111 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA364093697 rs1294055355 |
113 | R>W | No |
ClinGen gnomAD |
|
|
rs750235942 CA3804653 |
117 | M>V | No |
ClinGen ExAC gnomAD |
|
|
rs752200321 CA3804678 |
122 | P>L | No |
ClinGen ExAC gnomAD |
|
|
rs779832016 CA3804655 |
122 | P>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs201356964 CA138132152 |
123 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201356964 CA3804679 |
123 | P>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201356964 CA364095596 |
123 | P>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804681 rs746287434 |
124 | V>G | No |
ClinGen ExAC gnomAD |
|
|
rs777384806 CA3804680 |
124 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs1447537719 CA364095695 |
126 | N>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs770090308 CA3804682 |
128 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA3804683 rs780421286 |
130 | T>N | No |
ClinGen ExAC gnomAD |
|
|
CA364095789 rs1582218473 |
130 | T>P | No |
ClinGen Ensembl |
|
|
CA3804686 rs774628411 |
132 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1469595508 CA364095954 |
133 | A>V | No |
ClinGen gnomAD |
|
|
rs1582218548 CA364096145 |
139 | N>T | No |
ClinGen Ensembl |
|
|
rs773336996 CA3804689 |
140 | R>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs200166840 CA3804690 |
140 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1276039095 CA364096219 |
141 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1276039095 CA364096217 |
141 | P>R | No |
ClinGen TOPMed gnomAD |
|
|
CA3804693 rs766100611 |
142 | H>P | No |
ClinGen ExAC gnomAD |
|
|
rs373004161 CA3804694 |
143 | P>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs374681523 CA3804695 |
144 | P>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA364096357 rs374681523 |
144 | P>R | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA364096390 rs1242701273 |
145 | H>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA364096474 rs1354705952 |
146 | I>N | No |
ClinGen TOPMed |
|
|
CA364096479 rs1354705952 |
146 | I>T | No |
ClinGen TOPMed |
|
|
rs1475776722 CA364096457 |
146 | I>V | No |
ClinGen gnomAD |
|
|
CA3804697 rs752255358 |
147 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804698 rs757874607 |
149 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs200962020 CA3804699 |
150 | F>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs968089454 CA138132253 |
151 | P>A | No |
ClinGen TOPMed gnomAD |
|
|
CA3804700 rs201385171 |
151 | P>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs968089454 CA138132256 |
151 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA364096695 rs1408689099 |
152 | E>G | No |
ClinGen gnomAD |
|
|
CA3804702 rs369886097 |
155 | D>G | No |
ClinGen ESP ExAC gnomAD |
|
|
CA364096917 rs1178701501 |
159 | Y>F | No |
ClinGen TOPMed |
|
|
rs1432262852 CA364096908 |
159 | Y>H | No |
ClinGen TOPMed gnomAD |
|
| rs746487321 | 164 | T>= | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA364101153 rs1371060055 |
164 | T>A | No |
ClinGen TOPMed |
|
| TCGA novel | 166 | R>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1030879586 CA138142226 |
167 | E>D | No |
ClinGen TOPMed |
|
|
rs765700807 CA3804740 |
168 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA364101311 rs1445712107 |
169 | V>A | No |
ClinGen TOPMed gnomAD |
|
|
CA3804744 rs374915188 |
169 | V>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA3804743 COSM1228454 rs374915188 |
169 | V>M | large_intestine [Cosmic] | No |
ClinGen cosmic curated ESP ExAC TOPMed gnomAD |
|
rs1185996759 CA364101341 |
170 | S>L | No |
ClinGen gnomAD |
|
|
rs1165602006 CA364101367 |
171 | D>G | No |
ClinGen TOPMed |
|
|
rs1418630138 CA364101424 |
173 | Q>* | No |
ClinGen TOPMed |
|
|
rs371265065 CA3804750 |
176 | R>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs371265065 CA3804749 |
176 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA3804748 rs769940264 |
176 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs376100000 CA3804751 |
177 | E>V | No |
ClinGen ESP ExAC gnomAD |
|
|
CA364101662 rs1295333904 |
180 | A>T | No |
ClinGen gnomAD |
|
|
CA3804753 rs201089461 |
181 | S>F | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA138142280 rs766136389 |
182 | Q>* | No |
ClinGen gnomAD |
|
|
rs372388576 CA3804755 |
183 | R>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs760462541 CA3804756 |
184 | R>C | No |
ClinGen ExAC gnomAD |
|
|
CA138142292 rs968814710 COSM1079299 |
184 | R>H | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
rs368068958 CA3804758 |
185 | D>N | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA364101884 rs1185898798 |
186 | V>M | No |
ClinGen gnomAD |
|
|
CA138142300 rs532594187 |
187 | E>K | No |
ClinGen Ensembl |
|
|
CA3804759 rs371516491 |
188 | R>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA364101959 rs1374321126 |
188 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs371516491 CA364101956 |
188 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs928204960 CA138142310 |
189 | A>T | No |
ClinGen Ensembl |
|
|
rs752136318 CA3804762 |
191 | T>A | No |
ClinGen ExAC |
|
|
rs1406471536 CA364102089 |
191 | T>S | No |
ClinGen gnomAD |
|
|
rs770137667 CA138142329 |
192 | R>C | No |
ClinGen TOPMed |
|
|
CA3804763 rs374759131 |
192 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs368068359 CA138142347 |
194 | M>T | No |
ClinGen Ensembl |
|
|
rs781258446 CA3804764 |
194 | M>V | No |
ClinGen ExAC gnomAD |
|
|
rs1474866388 CA364102301 |
197 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
CA3804766 rs756372584 |
199 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs544595066 CA3804765 |
199 | E>K | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA3804768 rs780235922 |
202 | S>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364102562 rs1282895022 |
203 | L>F | No |
ClinGen gnomAD |
|
|
CA138142357 rs368936827 |
203 | L>P | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs1435317109 CA364102721 |
206 | D>G | No |
ClinGen TOPMed |
|
| TCGA novel | 206 | D>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA364102795 rs1206275063 |
208 | V>A | No |
ClinGen gnomAD |
|
|
CA3804771 rs778507860 |
208 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA3804772 rs748131198 |
209 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs886522375 CA138142384 |
210 | T>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1367999240 CA364104177 |
214 | I>V | No |
ClinGen TOPMed |
|
|
rs748725698 CA138143608 |
216 | A>P | No |
ClinGen TOPMed gnomAD |
|
|
rs748725698 CA364104266 |
216 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
CA138143613 rs934472680 |
217 | R>G | No |
ClinGen TOPMed |
|
|
CA364104381 rs1357988637 |
220 | T>A | No |
ClinGen gnomAD |
|
|
rs1291816869 CA364104449 |
222 | P>H | No |
ClinGen gnomAD |
|
|
CA364104477 rs1360975312 |
223 | Y>C | No |
ClinGen TOPMed gnomAD |
|
|
rs1360975312 CA364104480 |
223 | Y>F | No |
ClinGen TOPMed gnomAD |
|
|
rs745545223 CA3804797 |
225 | T>S | No |
ClinGen ExAC gnomAD |
|
|
rs1188943239 CA364104526 |
226 | A>T | No |
ClinGen TOPMed |
|
|
CA138143633 rs749869589 |
227 | L>R | No |
ClinGen Ensembl |
|
| rs746056203 | 228 | L>missing | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA3804800 rs769313819 |
229 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs769313819 CA364104586 |
229 | P>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3804799 rs769313819 |
229 | P>R | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 230 | S>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA3804802 rs767823791 |
230 | S>P | No |
ClinGen ExAC gnomAD |
|
|
CA3804803 rs773742959 |
231 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
rs761105655 CA3804804 |
232 | L>R | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 233 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs766461968 CA3804805 |
233 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
rs1168596606 CA364104681 |
234 | M>I | No |
ClinGen gnomAD |
|
|
CA364104735 rs1262290916 |
236 | Q>E | No |
ClinGen TOPMed |
|
|
rs753850736 CA3804807 |
237 | M>R | No |
ClinGen ExAC gnomAD |
|
|
rs753850736 CA3804806 |
237 | M>T | No |
ClinGen ExAC gnomAD |
|
|
CA3804808 rs765346730 |
242 | S>C | No |
ClinGen ExAC gnomAD |
|
|
rs752586050 CA3804809 |
243 | S>L | Variant assessed as Somatic; 4.677e-05 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA364105046 rs1452461216 |
246 | D>N | No |
ClinGen gnomAD |
|
|
CA138143677 rs983766535 |
247 | E>* | No |
ClinGen Ensembl |
|
|
rs1316365787 CA364105213 |
251 | T>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1384344244 CA364105319 |
254 | L>F | No |
ClinGen gnomAD |
|
|
CA138143679 rs1044000808 |
255 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
rs777669969 CA3804812 |
257 | H>L | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 257 | H>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs777669969 CA3804811 |
257 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1197007290 COSM334713 CA364105450 |
259 | S>G | lung [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
CA364105461 rs1383199019 |
259 | S>N | No |
ClinGen TOPMed |
|
|
rs1290965710 CA364105510 |
260 | M>I | No |
ClinGen TOPMed |
|
|
rs747344270 CA3804843 |
262 | D>H | No |
ClinGen ExAC gnomAD |
|
|
CA364110609 rs1438320300 |
263 | S>F | No |
ClinGen gnomAD |
|
|
CA3804844 rs189994370 |
264 | G>R | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs760047297 CA364110669 |
266 | E>* | No |
ClinGen ExAC gnomAD |
|
|
CA3804847 rs760047297 |
266 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs760047297 CA364110667 |
266 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA3804849 rs769766503 |
270 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs769766503 CA364110804 |
270 | T>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364110934 rs1318715318 |
274 | Q>* | No |
ClinGen gnomAD |
|
| TCGA novel | 274 | Q>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA364111021 rs1582248429 |
276 | N>T | No |
ClinGen Ensembl |
|
|
rs936629996 CA138147326 |
277 | P>T | No |
ClinGen Ensembl |
|
|
CA3804852 rs200995490 |
278 | S>A | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1245665601 CA364111078 |
278 | S>Y | No |
ClinGen gnomAD |
|
|
COSM1193755 rs372180909 CA3804853 |
280 | S>L | lung [Cosmic] | No |
ClinGen cosmic curated ESP ExAC TOPMed gnomAD |
|
rs767307596 CA3804855 |
282 | S>G | No |
ClinGen ExAC gnomAD |
|
|
CA3804856 rs376494787 |
282 | S>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs878886811 CA138147337 |
283 | R>Q | No |
ClinGen Ensembl |
|
|
rs1291669682 CA364111159 |
284 | N>D | No |
ClinGen TOPMed |
|
|
rs1243138301 CA364111178 |
285 | G>E | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA3804861 rs546610742 |
289 | I>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA3804863 rs778515780 |
291 | D>N | No |
ClinGen ExAC gnomAD |
|
|
rs1402184812 CA364111301 |
293 | P>R | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 293 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA364111318 rs1370764402 |
294 | Y>C | No |
ClinGen TOPMed |
|
|
CA138147370 rs966434982 |
296 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs1335967843 CA364111345 |
296 | R>W | No |
ClinGen gnomAD |
|
|
rs781551114 CA3804866 |
297 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 297 | P>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA364111374 rs1324766329 |
298 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
rs1418685539 CA364111446 |
303 | I>S | No |
ClinGen TOPMed |
|
|
CA3804869 rs775777569 |
304 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA3804870 rs749343718 |
304 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364111470 rs1263034193 |
305 | R>K | No |
ClinGen gnomAD |
|
|
CA3804871 rs769046111 |
306 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA364111560 rs1356664701 |
309 | L>F | No |
ClinGen gnomAD |
|
|
CA3804892 rs561846227 |
310 | S>P | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1265730693 CA364111581 |
311 | S>R | No |
ClinGen gnomAD |
No associated diseases with Q7Z7C8
4 GO annotations of cellular component
| Name | Definition |
|---|---|
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| perinuclear region of cytoplasm | Cytoplasm situated near, or occurring around, the nucleus. |
| transcription factor TFIID complex | A complex composed of TATA binding protein (TBP) and TBP associated factors (TAFs); the total mass is typically about 800 kDa. Most of the TAFs are conserved across species. In TATA-containing promoters for RNA polymerase II (Pol II), TFIID is believed to recognize at least two distinct elements, the TATA element and a downstream promoter element. TFIID is also involved in recognition of TATA-less Pol II promoters. Binding of TFIID to DNA is necessary but not sufficient for transcription initiation from most RNA polymerase II promoters. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| protein heterodimerization activity | Binding to a nonidentical protein to form a heterodimer. |
| RNA polymerase II general transcription initiation factor activity | A general transcription initiation factor activity that contributes to transcription start site selection and transcription initiation of genes transcribed by RNA polymerase II. The general transcription factors for RNA polymerase II include TFIIB, TFIID, TFIIE, TFIIF, TFIIH and TATA-binding protein (TBP). In most species, RNA polymerase II transcribes all messenger RNAs (mRNAs), most untranslated regulatory RNAs, the majority of the snoRNAs, four of the five snRNAs (U1, U2, U4, and U5), and other small noncoding RNAs. For some small RNAs there is variability between species as to whether it is transcribed by RNA polymerase II or RNA polymerase III. However there are also rare exceptions, such as Trypanosoma brucei, where RNA polymerase I transcribes certain mRNAs in addition to its normal role in rRNA transcription. |
10 GO annotations of biological process
| Name | Definition |
|---|---|
| cell differentiation | The process in which relatively unspecialized cells, e.g. embryonic or regenerative cells, acquire specialized structural and/or functional features that characterize the cells, tissues, or organs of the mature organism or some other relatively stable phase of the organism's life history. Differentiation includes the processes involved in commitment of a cell to a specific fate and its subsequent development to the mature state. |
| DNA-templated transcription open complex formation | Any process involved in the melting of the DNA hybrid of the core promoter region within the transcriptional closed complex of an RNA polymerase preinitiation complex (PIC) to produce an open complex where the DNA duplex around the transcription initiation site is unwound to form the transcription bubble. |
| inner cell mass cell proliferation | The proliferation of cells in the inner cell mass. |
| maintenance of protein location in nucleus | Any process in which a protein is maintained in the nucleus and prevented from moving elsewhere. These include sequestration within the nucleus, protein stabilization to prevent transport elsewhere and the active retrieval of proteins that escape the nucleus. |
| mRNA transcription by RNA polymerase II | The cellular synthesis of messenger RNA (mRNA) from a DNA template by RNA polymerase II, originating at an RNA polymerase II promoter. |
| positive regulation of transcription initiation by RNA polymerase II | Any process that increases the rate, frequency or extent of a process involved in starting transcription from an RNA polymerase II promoter. |
| protein phosphorylation | The process of introducing a phosphate group on to a protein. |
| regulation of fat cell differentiation | Any process that modulates the frequency, rate or extent of adipocyte differentiation. |
| RNA polymerase II preinitiation complex assembly | The aggregation, arrangement and bonding together of proteins on an RNA polymerase II promoter DNA to form the transcriptional preinitiation complex (PIC), the formation of which is a prerequisite for transcription by RNA polymerase. |
| transcription initiation at RNA polymerase II promoter | A transcription initiation process that takes place at a RNA polymerase II gene promoter. Messenger RNAs (mRNA) genes, as well as some non-coding RNAs, are transcribed by RNA polymerase II. |
5 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| A7MAZ4 | TAF8 | Transcription initiation factor TFIID subunit 8 | Bos taurus (Bovine) | PR |
| Q5ZMS1 | TAF8 | Transcription initiation factor TFIID subunit 8 | Gallus gallus (Chicken) | PR |
| Q9EQH4 | Taf8 | Transcription initiation factor TFIID subunit 8 | Mus musculus (Mouse) | PR |
| Q28J24 | taf8 | Transcription initiation factor TFIID subunit 8 | Xenopus tropicalis (Western clawed frog) (Silurana tropicalis) | PR |
| Q6P0T2 | taf8 | Transcription initiation factor TFIID subunit 8 | Danio rerio (Zebrafish) (Brachydanio rerio) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MADAAATAGA | GGSGTRSGSK | QSTNPADNYH | LARRRTLQVV | VSSLLTEAGF | ESAEKASVET |
| 70 | 80 | 90 | 100 | 110 | 120 |
| LTEMLQSYIS | EIGRSAKSYC | EHTARTQPTL | SDIVVTLVEM | GFNVDTLPAY | AKRSQRMVIT |
| 130 | 140 | 150 | 160 | 170 | 180 |
| APPVTNQPVT | PKALTAGQNR | PHPPHIPSHF | PEFPDPHTYI | KTPTYREPVS | DYQVLREKAA |
| 190 | 200 | 210 | 220 | 230 | 240 |
| SQRRDVERAL | TRFMAKTGET | QSLFKDDVST | FPLIAARPFT | IPYLTALLPS | ELEMQQMEET |
| 250 | 260 | 270 | 280 | 290 | 300 |
| DSSEQDEQTD | TENLALHISM | EDSGAEKENT | SVLQQNPSLS | GSRNGEENII | DNPYLRPVKK |
| PKIRRKKSLS |