Q13156
Gene name |
RPA4 |
Protein name |
Replication protein A 30 kDa subunit |
Names |
RP-A p30, Replication factor A protein 4, RF-A protein 4 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:29935 |
EC number |
|
Protein Class |
|
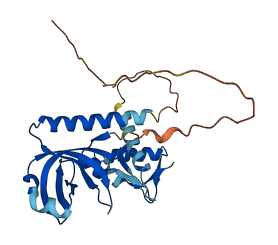
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q13156
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q13156-F1 | Predicted | AlphaFoldDB |
177 variants for Q13156
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs1569419839 CA413992542 |
2 | S>R | No |
ClinGen Ensembl |
|
|
CA413992593 rs1270882796 |
5 | G>A | No |
ClinGen TOPMed |
|
|
rs375731658 CA10467937 |
5 | G>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA10467938 rs142187288 |
9 | Y>C | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA10467939 rs777653217 |
15 | A>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs751261961 CA10467940 |
17 | G>* | No |
ClinGen ExAC gnomAD |
|
|
CA10467941 rs187652788 |
20 | G>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA413992836 rs1222812876 |
22 | S>R | No |
ClinGen gnomAD |
|
| TCGA novel | 25 | L>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs199993954 CA10467942 |
29 | D>N | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1474638734 CA413992890 |
30 | A>P | No |
ClinGen gnomAD |
|
|
CA10467943 rs746079672 |
31 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs746079672 CA10467944 |
31 | T>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413992907 rs1451925063 |
33 | A>G | No |
ClinGen TOPMed gnomAD |
|
|
CA10467945 VAR_019170 rs2642219 |
33 | A>T | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs749838488 CA10467946 |
34 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413992939 rs1197473040 COSM1636636 |
38 | R>K | liver [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA10467947 rs769007105 |
40 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs1284398168 COSM1126454 CA413992965 |
42 | R>Q | Variant assessed as Somatic; impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed |
|
CA10467948 rs774803428 |
43 | I>N | No |
ClinGen ExAC gnomAD |
|
|
CA333535925 rs202067524 |
44 | Q>H | No |
ClinGen 1000Genomes |
|
|
rs33970383 CA413993010 |
45 | D>E | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs779282598 CA333535932 |
48 | P>L | No |
ClinGen gnomAD |
|
|
rs779282598 CA413993050 |
48 | P>R | No |
ClinGen gnomAD |
|
|
rs192076302 CA333535935 |
50 | N>D | No |
ClinGen 1000Genomes |
|
|
rs2642218 CA413993082 |
50 | N>K | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA10467953 rs764853980 |
51 | V>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10467954 rs368340875 |
53 | Q>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA413993167 rs1444995303 |
57 | S>P | No |
ClinGen TOPMed gnomAD |
|
|
CA413993186 rs1215483768 |
59 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
rs762969824 CA10467955 |
65 | K>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1466602605 CA413993292 |
66 | V>A | No |
ClinGen gnomAD |
|
|
rs1182320949 CA413993298 |
67 | R>S | No |
ClinGen TOPMed gnomAD |
|
|
CA413993302 rs1367548002 |
68 | G>E | No |
ClinGen TOPMed gnomAD |
|
|
CA10467956 rs778666124 |
68 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs751403798 CA10467957 |
70 | I>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413993321 rs1165127957 |
71 | V>D | No |
ClinGen gnomAD |
|
| TCGA novel | 71 | V>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1480677030 CA413993326 |
72 | S>A | No |
ClinGen TOPMed |
|
|
CA413993347 rs1406056683 |
75 | S>F | No |
ClinGen gnomAD |
|
|
rs764459650 CA10467958 |
76 | I>L | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1437106087 CA413993368 |
79 | V>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs756371048 CA10467962 |
80 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA10467963 rs780210770 |
82 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs1325329868 CA413993394 |
83 | A>S | No |
ClinGen TOPMed |
|
|
rs1264114955 CA413993397 COSM1331655 |
83 | A>V | ovary Variant assessed as Somatic; impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated NCI-TCGA TOPMed |
| TCGA novel | 84 | E>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs769222965 CA10467965 |
86 | A>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413993415 rs749282673 |
86 | A>P | No |
ClinGen ExAC gnomAD |
|
|
CA10467964 rs749282673 |
86 | A>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs1222876130 CA413993425 |
88 | N>D | No |
ClinGen gnomAD |
|
|
rs779224198 CA10467966 |
88 | N>T | No |
ClinGen ExAC gnomAD |
|
|
CA413993438 rs1329811225 |
89 | H>Q | No |
ClinGen TOPMed |
|
| TCGA novel | 89 | H>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs748650794 CA10467967 |
90 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413993440 rs1331662626 |
90 | I>V | No |
ClinGen gnomAD |
|
|
CA10467968 rs772484141 |
96 | D>A | No |
ClinGen ExAC |
|
|
rs1236130250 CA413993496 |
97 | M>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1243052787 CA413993492 |
97 | M>V | No |
ClinGen gnomAD |
|
|
rs1569419977 CA413993505 |
98 | T>I | No |
ClinGen Ensembl |
|
|
rs745560952 CA10467971 |
99 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10467969 rs773544923 |
99 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs745560952 CA10467970 |
99 | A>V | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA413993513 rs1469773704 |
100 | K>R | No |
ClinGen gnomAD |
|
|
CA10467972 rs775077220 |
101 | P>Q | No |
ClinGen ExAC gnomAD |
|
|
CA10467973 rs762302359 |
102 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 103 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA10467976 rs774485213 |
104 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 105 | R>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 106 | Q>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA413993560 rs1328940634 |
107 | W>* | No |
ClinGen TOPMed gnomAD |
|
|
rs1338388374 CA413993556 |
107 | W>R | No |
ClinGen Ensembl |
|
|
rs761816138 CA10467977 |
109 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1161220237 CA413993615 |
115 | Q>E | No |
ClinGen TOPMed |
|
| TCGA novel | 115 | Q>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1249207536 CA413993623 |
116 | V>M | No |
ClinGen TOPMed |
|
|
CA413993651 rs1335565795 |
120 | S>L | No |
ClinGen gnomAD |
|
|
CA413993655 rs1440932728 |
121 | V>A | No |
ClinGen gnomAD |
|
|
rs372688483 CA10467978 |
121 | V>F | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs144423256 CA333535976 |
122 | G>R | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA333535982 rs201038766 |
124 | Y>F | No |
ClinGen Ensembl |
|
|
CA10467979 rs750200948 |
124 | Y>H | No |
ClinGen ExAC gnomAD |
|
|
rs756383923 CA10467981 |
129 | G>C | No |
ClinGen ExAC gnomAD |
|
|
CA10467982 rs766456237 |
130 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA333535987 rs1029496439 |
131 | L>P | No |
ClinGen TOPMed |
|
|
CA10467983 rs377302642 |
132 | K>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA413993721 rs377302642 |
132 | K>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1254240586 CA413993736 |
134 | P>R | No |
ClinGen gnomAD |
|
|
CA10467984 rs755083419 |
134 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA10467985 rs148408114 |
136 | G>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs183526208 CA10467986 |
137 | T>I | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA333535997 rs187756303 |
139 | S>I | No |
ClinGen 1000Genomes TOPMed |
|
|
rs778143589 CA10467988 |
142 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs865958206 CA333536001 |
142 | V>I | No |
ClinGen TOPMed |
|
|
rs150547120 CA10467989 |
146 | H>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1602595078 CA413993850 |
150 | D>Y | No |
ClinGen Ensembl |
|
|
CA10467993 rs201616178 |
152 | N>D | No |
ClinGen ExAC gnomAD |
|
|
CA10467994 rs773964117 |
152 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA413993894 rs1332071901 |
153 | E>* | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 153 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA413993892 rs1332071901 |
153 | E>Q | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 155 | T>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
COSM614042 rs139569203 CA10467996 |
156 | V>M | lung [Cosmic] | No |
ClinGen cosmic curated 1000Genomes ESP ExAC TOPMed gnomAD |
|
CA10467997 rs773158242 |
157 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs192760986 CA10467998 |
158 | I>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA10467999 rs766197285 COSM3406680 |
161 | T>M | Variant assessed as Somatic; 0.0001253 impact. central_nervous_system [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
rs184130356 CA10468001 |
163 | N>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1485798992 CA413994070 |
166 | M>V | No |
ClinGen TOPMed |
|
|
CA333536023 COSM614040 rs906667923 |
167 | M>I | lung [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
rs1293135795 CA413994086 |
167 | M>L | No |
ClinGen gnomAD |
|
| TCGA novel | 169 | D>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs938173282 CA333536026 |
172 | R>C | No |
ClinGen TOPMed |
|
|
CA10468003 COSM3845578 rs752735862 |
172 | R>H | Variant assessed as Somatic; 6.262e-05 impact. breast [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
CA10468005 rs758918264 |
181 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413994296 rs1242879250 |
182 | V>L | No |
ClinGen TOPMed |
|
|
CA413994292 rs1242879250 |
182 | V>M | No |
ClinGen TOPMed |
|
|
rs1475064302 CA413994315 |
183 | S>F | No |
ClinGen gnomAD |
|
|
CA413994317 rs1304304049 |
184 | P>A | No |
ClinGen gnomAD |
|
| TCGA novel | 184 | P>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA333536030 rs867176116 |
188 | N>D | No |
ClinGen TOPMed |
|
|
CA10468006 rs778184711 |
188 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA413994353 rs1391504895 |
189 | D>V | No |
ClinGen gnomAD |
|
|
rs61736055 CA10468008 |
190 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs200380831 CA10468007 |
190 | A>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs61736055 CA10468009 |
190 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs748929447 CA10468010 |
191 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs768311636 CA10468011 |
193 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA10468013 rs747607202 |
195 | E>V | No |
ClinGen ExAC gnomAD |
|
|
rs772143522 CA10468014 |
196 | S>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA333536031 rs1005836154 |
197 | H>L | No |
ClinGen TOPMed |
|
|
rs373048681 CA10468015 |
198 | R>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA10468016 COSM198858 rs199631132 |
198 | R>H | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs199631132 CA10468017 |
198 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413994492 rs1266246102 |
199 | N>S | No |
ClinGen gnomAD |
|
| TCGA novel | 199 | N>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs558028763 CA10468018 |
202 | Q>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA413994585 rs1259456879 |
203 | D>E | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA10468019 rs759709110 |
203 | D>V | No |
ClinGen ExAC gnomAD |
|
|
CA413994597 rs1477702291 |
204 | E>* | No |
ClinGen TOPMed |
|
|
rs765397140 CA413994606 |
205 | V>L | No |
ClinGen ExAC gnomAD |
|
|
CA10468020 rs765397140 |
205 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs866290728 CA333536032 |
210 | H>Y | No |
ClinGen TOPMed |
|
|
rs764145220 CA10468023 |
211 | E>D | No |
ClinGen ExAC gnomAD |
|
|
CA413994748 rs1489190469 |
212 | C>* | No |
ClinGen TOPMed gnomAD |
|
|
rs144363735 CA10468025 |
217 | G>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs781437665 CA10468026 |
218 | K>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10468027 rs199689421 |
223 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1384744713 CA413994972 |
224 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA10468028 rs530995109 |
225 | A>D | No |
ClinGen ExAC |
|
|
CA10468029 rs778644041 |
227 | L>P | No |
ClinGen ExAC gnomAD |
|
|
rs747801103 CA10468030 |
229 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413995077 rs1381292756 |
230 | L>F | No |
ClinGen gnomAD |
|
|
rs1184240746 CA413995097 |
231 | S>N | No |
ClinGen gnomAD |
|
| TCGA novel | 235 | I>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1276140117 CA413995183 |
235 | I>N | No |
ClinGen TOPMed |
|
| TCGA novel | 235 | I>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1029836959 CA333536034 |
237 | E>V | No |
ClinGen TOPMed |
|
|
CA413995272 rs1398104114 |
240 | D>G | No |
ClinGen TOPMed |
|
|
CA413995280 rs1237184707 |
241 | Y>C | No |
ClinGen gnomAD |
|
|
rs1237184707 CA413995281 |
241 | Y>F | No |
ClinGen gnomAD |
|
|
rs746960917 CA10468033 |
243 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs778673464 CA10468032 |
243 | T>P | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs770863451 CA10468034 COSM3783628 |
244 | V>I | prostate [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed |
|
CA333536035 rs748114324 |
246 | G>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
|
rs201295573 CA10468035 |
247 | H>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1202097059 CA413995318 |
248 | I>L | No |
ClinGen TOPMed |
|
| TCGA novel | 249 | Y>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1182419889 CA413995339 |
251 | T>S | No |
ClinGen gnomAD |
|
|
CA413995361 rs1425149634 |
254 | R>Q | No |
ClinGen gnomAD |
|
| TCGA novel | 255 | E>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs764194530 CA10468040 |
256 | H>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA413995372 rs764194530 |
256 | H>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1164385444 CA413995375 |
256 | H>R | No |
ClinGen gnomAD |
|
|
CA10468041 rs751615388 |
259 | S>F | No |
ClinGen ExAC gnomAD |
|
|
rs762246801 CA10468042 |
260 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA10468044 rs750760682 |
261 | D>G | No |
ClinGen ExAC |
|
|
CA10468043 rs200339720 |
261 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
No associated diseases with Q13156
1 regional properties for Q13156
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Replication protein A, C-terminal | 197 - 254 | IPR014892 |
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromosome, telomeric region | The end of a linear chromosome, required for the integrity and maintenance of the end. A chromosome telomere usually includes a region of telomerase-encoded repeats the length of which rarely exceeds 20 bp each and that permits the formation of a telomeric loop (T-loop). The telomeric repeat region is usually preceded by a sub-telomeric region that is gene-poor but rich in repetitive elements. Some telomeres only consist of the latter part (for eg. D. melanogaster telomeres). |
| DNA replication factor A complex | A conserved heterotrimeric complex that binds nonspecifically to single-stranded DNA and is required for multiple processes in eukaryotic DNA metabolism, including DNA replication, DNA repair, and recombination. In all eukaryotic organisms examined the complex is composed of subunits of approximately 70, 30, and 14 kDa. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| site of double-strand break | A region of a chromosome at which a DNA double-strand break has occurred. DNA damage signaling and repair proteins accumulate at the lesion to respond to the damage and repair the DNA to form a continuous DNA helix. |
1 GO annotations of molecular function
| Name | Definition |
|---|---|
| single-stranded DNA binding | Binding to single-stranded DNA. |
6 GO annotations of biological process
| Name | Definition |
|---|---|
| DNA damage checkpoint signaling | A signal transduction process that contributes to a DNA damage checkpoint. |
| DNA repair | The process of restoring DNA after damage. Genomes are subject to damage by chemical and physical agents in the environment (e.g. UV and ionizing radiations, chemical mutagens, fungal and bacterial toxins, etc.) and by free radicals or alkylating agents endogenously generated in metabolism. DNA is also damaged because of errors during its replication. A variety of different DNA repair pathways have been reported that include direct reversal, base excision repair, nucleotide excision repair, photoreactivation, bypass, double-strand break repair pathway, and mismatch repair pathway. |
| DNA replication | The cellular metabolic process in which a cell duplicates one or more molecules of DNA. DNA replication begins when specific sequences, known as origins of replication, are recognized and bound by initiation proteins, and ends when the original DNA molecule has been completely duplicated and the copies topologically separated. The unit of replication usually corresponds to the genome of the cell, an organelle, or a virus. The template for replication can either be an existing DNA molecule or RNA. |
| DNA replication initiation | The process in which DNA-dependent DNA replication is started; this begins with the ATP dependent loading of an initiator complex onto the DNA, this is followed by DNA melting and helicase activity. In bacteria, the gene products that enable the helicase activity are loaded after the initial melting and in archaea and eukaryotes, the gene products that enable the helicase activity are inactive when they are loaded and subsequently activate. |
| double-strand break repair via homologous recombination | The error-free repair of a double-strand break in DNA in which the broken DNA molecule is repaired using homologous sequences. A strand in the broken DNA searches for a homologous region in an intact chromosome to serve as the template for DNA synthesis. The restoration of two intact DNA molecules results in the exchange, reciprocal or nonreciprocal, of genetic material between the intact DNA molecule and the broken DNA molecule. |
| nucleotide-excision repair | A DNA repair process in which a small region of the strand surrounding the damage is removed from the DNA helix as an oligonucleotide. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. Nucleotide excision repair recognizes a wide range of substrates, including damage caused by UV irradiation (pyrimidine dimers and 6-4 photoproducts) and chemicals (intrastrand cross-links and bulky adducts). |
3 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P15927 | RPA2 | Replication protein A 32 kDa subunit | Homo sapiens (Human) | PR |
| Q9ZQ19 | RPA2A | Replication protein A 32 kDa subunit A | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q6DJ48 | stn1 | CST complex subunit STN1 | Xenopus tropicalis (Western clawed frog) (Silurana tropicalis) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSKSGFGSYG | SISAADGASG | GSDQLCERDA | TPAIKTQRPK | VRIQDVVPCN | VNQLLSSTVF |
| 70 | 80 | 90 | 100 | 110 | 120 |
| DPVFKVRGII | VSQVSIVGVI | RGAEKASNHI | CYKIDDMTAK | PIEARQWFGR | EKVKQVTPLS |
| 130 | 140 | 150 | 160 | 170 | 180 |
| VGVYVKVFGI | LKCPTGTKSL | EVLKIHVLED | MNEFTVHILE | TVNAHMMLDK | ARRDTTVESV |
| 190 | 200 | 210 | 220 | 230 | 240 |
| PVSPSEVNDA | GDNDESHRNF | IQDEVLRLIH | ECPHQEGKSI | HELRAQLCDL | SVKAIKEAID |
| 250 | 260 | ||||
| YLTVEGHIYP | TVDREHFKSA | D |