P15927
Gene name |
RPA2 (REPA2, RPA32, RPA34) |
Protein name |
Replication protein A 32 kDa subunit |
Names |
RP-A p32, Replication factor A protein 2, RF-A protein 2, Replication protein A 34 kDa subunit, RP-A p34 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:6118 |
EC number |
|
Protein Class |
|
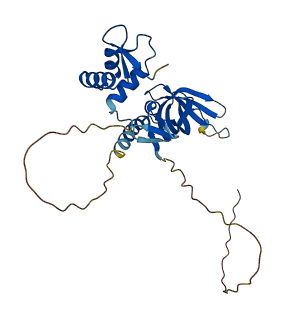
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
11 structures for P15927
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1DPU | NMR | - | A | 172-270 | PDB |
| 1L1O | X-ray | 280 A | B/E | 44-171 | PDB |
| 1QUQ | X-ray | 250 A | A/C | 43-171 | PDB |
| 1Z1D | NMR | - | A | 172-270 | PDB |
| 2PI2 | X-ray | 200 A | A/B/C/D | 1-270 | PDB |
| 2PQA | X-ray | 250 A | A/C | 42-172 | PDB |
| 2Z6K | X-ray | 300 A | A/B | 1-270 | PDB |
| 3KDF | X-ray | 198 A | B/D | 41-172 | PDB |
| 4MQV | X-ray | 195 A | A/C | 202-270 | PDB |
| 4OU0 | X-ray | 140 A | A | 202-270 | PDB |
| AF-P15927-F1 | Predicted | AlphaFoldDB |
202 variants for P15927
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs777779644 CA718358 |
3 | N>K | No |
ClinGen ExAC gnomAD |
|
|
rs765854928 CA718302 |
4 | S>I | No |
ClinGen ExAC gnomAD |
|
|
CA339477499 rs765854928 |
4 | S>N | No |
ClinGen ExAC gnomAD |
|
|
TCGA novel CA19944102 rs898160262 |
6 | F>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
NCI-TCGA ClinGen TOPMed |
|
CA718301 rs757873922 |
8 | S>N | No |
ClinGen ExAC gnomAD |
|
|
CA339477463 rs1201286242 |
9 | Y>C | No |
ClinGen TOPMed |
|
|
rs1273358149 CA339477458 |
10 | G>R | No |
ClinGen TOPMed |
|
|
rs761614333 CA718298 |
11 | S>R | No |
ClinGen ExAC gnomAD |
|
|
rs776471331 CA718297 |
12 | S>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs776471331 CA339477443 |
12 | S>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA718296 rs201492173 |
13 | S>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA19944074 rs28988896 VAR_023300 |
14 | Y>S | No |
ClinGen UniProt Ensembl dbSNP |
|
|
CA718292 VAR_023301 rs28988897 CA339477429 |
15 | G>R | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD UniProt dbSNP |
|
|
rs28988897 CA718293 |
15 | G>W | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA718291 rs148430221 |
16 | G>R | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1248396349 CA339477420 |
17 | A>T | No |
ClinGen gnomAD |
|
|
rs770197869 CA718289 |
18 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA339477395 rs748375829 |
21 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs781718215 CA718287 |
21 | T>M | No |
ClinGen ExAC gnomAD |
|
|
rs748375829 CA718288 |
21 | T>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
COSM184564 rs755345876 COSM184563 CA718286 |
23 | S>F | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs755345876 CA339477379 |
23 | S>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 26 | G>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA718284 rs780566579 |
26 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA339477362 rs1557477543 |
26 | G>V | No |
ClinGen Ensembl |
|
| rs771264048 | 27 | F>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs369007762 CA718282 |
27 | F>Y | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1167754276 CA339477344 |
29 | S>* | No |
ClinGen TOPMed |
|
|
CA339477343 rs1167754276 |
29 | S>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs199857202 CA19943973 |
30 | P>S | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs199857202 CA718281 |
30 | P>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA339477338 rs1571627682 |
31 | A>T | No |
ClinGen Ensembl |
|
|
CA718280 rs149249571 |
33 | S>F | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA339477320 rs1363445599 |
34 | Q>E | No |
ClinGen gnomAD |
|
|
CA339477318 rs1157119942 |
34 | Q>P | No |
ClinGen gnomAD |
|
|
CA718279 rs756974840 |
35 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs1193999593 CA339477299 |
37 | K>E | No |
ClinGen gnomAD |
|
|
CA339477281 rs1251048763 |
39 | S>L | No |
ClinGen gnomAD |
|
|
CA19938814 rs962234142 |
40 | R>G | No |
ClinGen TOPMed |
|
|
CA339252884 rs1277423591 |
41 | A>D | No |
ClinGen gnomAD |
|
|
rs1346102564 CA339252887 |
41 | A>S | No |
ClinGen gnomAD |
|
|
rs755866319 CA19938806 |
42 | R>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1225165257 CA339252877 |
43 | A>T | No |
ClinGen gnomAD |
|
|
CA718256 rs752479657 |
43 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs781090246 CA19938788 |
44 | Q>E | No |
ClinGen Ensembl |
|
|
CA718255 rs767211752 |
49 | C>S | No |
ClinGen ExAC gnomAD |
|
|
rs1225327354 CA339252827 |
50 | T>S | No |
ClinGen TOPMed |
|
|
CA718254 rs540849246 |
51 | I>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1317288814 CA339252816 |
52 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
CA19938767 rs1050563630 |
58 | T>S | No |
ClinGen TOPMed |
|
|
CA19938763 rs5030742 |
59 | L>V | No |
ClinGen Ensembl |
|
|
rs367965034 CA718253 |
59 | L>W | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA19938753 rs376928504 |
61 | D>E | No |
ClinGen ESP TOPMed |
|
|
CA339252737 rs1372414426 |
65 | R>G | No |
ClinGen gnomAD |
|
|
rs1190481788 CA339252734 |
65 | R>T | No |
ClinGen gnomAD |
|
|
rs776720485 CA718250 |
73 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
rs1382280006 CA339252677 |
73 | Q>H | No |
ClinGen gnomAD |
|
|
CA339252660 rs1280290919 |
74 | V>D | No |
ClinGen gnomAD |
|
|
rs1341377467 CA339252656 |
75 | T>A | No |
ClinGen TOPMed |
|
|
CA718218 rs146039555 |
76 | I>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA339252633 rs1443066950 |
79 | I>F | No |
ClinGen gnomAD |
|
|
CA19938573 rs5030750 |
79 | I>N | No |
ClinGen Ensembl |
|
|
CA718215 rs771369613 |
80 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs1324707342 CA339252612 |
82 | H>Y | No |
ClinGen gnomAD |
|
| TCGA novel | 84 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1419388190 CA339252599 |
84 | E>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA339252570 rs1316740579 |
88 | T>A | No |
ClinGen TOPMed |
|
|
rs1158735496 CA339252565 |
89 | N>D | No |
ClinGen gnomAD |
|
|
rs1469972602 CA339252557 |
90 | I>V | No |
ClinGen gnomAD |
|
|
rs1362459002 CA339252536 |
93 | K>E | No |
ClinGen gnomAD |
|
|
CA19938551 rs981230684 |
94 | I>T | No |
ClinGen TOPMed gnomAD |
|
|
rs371117106 CA718213 |
95 | D>N | No |
ClinGen ESP ExAC gnomAD |
|
| TCGA novel | 95 | D>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA718211 rs747856894 |
97 | M>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1448750353 CA339252508 |
97 | M>V | No |
ClinGen gnomAD |
|
|
rs558257017 CA718210 |
100 | A>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs148706559 CA19938528 COSM107725 COSM107726 |
102 | M>I | skin [Cosmic] | No |
ClinGen cosmic curated Ensembl |
|
rs1277607207 CA339252453 |
102 | M>V | No |
ClinGen gnomAD |
|
|
rs111497606 CA19938523 |
104 | V>A | No |
ClinGen Ensembl |
|
|
rs746740719 CA718208 |
104 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339252420 rs1371730662 |
105 | R>C | No |
ClinGen gnomAD |
|
|
rs779978159 CA718207 |
106 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339252409 rs1458496368 |
106 | Q>R | No |
ClinGen TOPMed |
|
|
rs1438098024 CA339252392 |
107 | W>C | No |
ClinGen gnomAD |
|
|
CA19938509 rs199748491 |
108 | V>A | No |
ClinGen 1000Genomes |
|
|
CA718206 rs758424316 |
108 | V>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339252388 rs758424316 |
108 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA718205 rs750300316 |
110 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA339251922 rs1299429108 |
112 | D>N | No |
ClinGen TOPMed |
|
|
rs768478609 CA718191 |
113 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA339251909 rs768478609 |
113 | T>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA19933596 rs866886354 |
114 | S>I | No |
ClinGen Ensembl |
|
|
rs1412180755 CA339251894 |
115 | S>R | No |
ClinGen TOPMed gnomAD |
|
|
CA718188 rs780031389 |
117 | N>H | No |
ClinGen ExAC |
|
|
rs1337899350 CA339251869 |
117 | N>I | No |
ClinGen TOPMed |
|
| TCGA novel | 118 | T>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA718187 rs758110434 |
118 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs1188866853 CA339251851 |
119 | V>E | No |
ClinGen gnomAD |
|
|
rs745842090 CA718186 |
119 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs1282586099 CA339251845 |
120 | V>I | No |
ClinGen gnomAD |
|
|
rs1241478711 CA339251819 |
122 | P>L | No |
ClinGen gnomAD |
|
|
rs1008120997 CA19933581 |
122 | P>S | No |
ClinGen TOPMed |
|
|
CA718184 rs756224339 |
124 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs977722946 CA19933578 |
125 | Y>C | No |
ClinGen TOPMed |
|
|
rs1273541282 CA339251736 |
129 | A>G | No |
ClinGen gnomAD |
|
|
rs1571607482 CA339251716 |
131 | H>P | No |
ClinGen Ensembl |
|
|
CA718180 rs751758104 |
132 | L>P | No |
ClinGen ExAC |
|
|
CA718181 rs755260671 |
132 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs1392219187 CA339251697 |
133 | R>K | No |
ClinGen TOPMed |
|
|
CA339251662 rs1571607441 |
136 | Q>* | No |
ClinGen Ensembl |
|
|
rs986952483 CA19933353 |
137 | N>S | No |
ClinGen Ensembl |
|
|
CA718168 rs778925354 |
138 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs770834134 CA718167 |
140 | S>G | No |
ClinGen ExAC gnomAD |
|
|
rs781289959 CA718165 |
142 | V>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA718166 rs749219918 |
142 | V>I | No |
ClinGen ExAC gnomAD |
|
|
rs556071176 CA718164 |
143 | A>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1420687764 CA339251535 |
143 | A>V | No |
ClinGen gnomAD |
|
|
rs751811246 CA718163 |
144 | F>S | No |
ClinGen ExAC gnomAD |
|
|
CA339251504 rs1176389757 |
146 | I>T | No |
ClinGen gnomAD |
|
|
CA339251491 rs1437815647 |
147 | M>I | No |
ClinGen gnomAD |
|
| TCGA novel | 150 | E>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA718162 rs758120826 |
151 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA718161 rs758802798 |
151 | D>V | No |
ClinGen ExAC gnomAD |
|
|
CA19933340 rs911286483 |
152 | M>I | No |
ClinGen TOPMed |
|
|
CA339251400 rs1394072256 |
156 | T>I | No |
ClinGen TOPMed |
|
|
CA339251397 rs1217448969 |
157 | T>A | No |
ClinGen gnomAD |
|
|
CA718159 rs765627839 |
157 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA718158 rs752598145 |
158 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs535763830 CA718156 |
159 | I>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs760225361 CA718155 |
161 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA718154 rs775289224 |
162 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA339251344 rs1454547834 |
163 | I>V | No |
ClinGen gnomAD |
|
|
rs374603144 CA718153 |
164 | N>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs759215567 CA718152 |
165 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA19933333 rs986856911 |
166 | H>D | No |
ClinGen TOPMed gnomAD |
|
|
CA339251299 rs1267803483 |
167 | M>I | No |
ClinGen gnomAD |
|
|
CA718151 rs370079410 |
167 | M>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1424890593 CA339251307 |
167 | M>L | No |
ClinGen TOPMed |
|
|
CA339251305 rs1424890593 |
167 | M>V | No |
ClinGen TOPMed |
|
|
rs1194133985 CA339251289 |
168 | V>E | No |
ClinGen gnomAD |
|
|
rs58894196 CA19933328 |
173 | N>D | No |
ClinGen Ensembl |
|
|
rs749244686 CA718149 |
174 | S>G | No |
ClinGen ExAC gnomAD |
|
|
CA339251248 rs1347777972 |
174 | S>N | No |
ClinGen gnomAD |
|
|
CA339251250 rs749244686 |
174 | S>R | No |
ClinGen ExAC gnomAD |
|
|
rs1486026460 CA339251237 |
175 | Q>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1284426941 CA339251240 |
175 | Q>P | No |
ClinGen TOPMed gnomAD |
|
|
rs766191837 CA718131 |
181 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs377253918 CA19932392 |
181 | A>V | No |
ClinGen ESP |
|
|
rs773145803 CA718129 |
182 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA718128 rs373117782 |
183 | I>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1476981638 CA339251154 |
187 | G>R | No |
ClinGen gnomAD |
|
|
rs1313325257 CA339251118 |
192 | G>R | No |
ClinGen gnomAD |
|
|
CA19932382 rs1017479000 |
193 | N>K | No |
ClinGen Ensembl |
|
|
rs748070130 CA718127 |
195 | G>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1006823696 CA19932371 |
196 | G>E | No |
ClinGen Ensembl |
|
|
rs775468537 CA718126 |
196 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs1462077347 CA339251083 |
197 | N>K | No |
ClinGen gnomAD |
|
|
CA718125 rs772167431 |
197 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1557462796 CA339251079 |
198 | S>G | No |
ClinGen Ensembl |
|
|
CA339251078 rs1422340426 |
198 | S>N | No |
ClinGen gnomAD |
|
|
CA718124 rs143220390 |
200 | M>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA718123 rs143220390 |
200 | M>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1476016273 CA339251057 |
201 | P>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs1275762533 CA339251051 |
202 | A>P | No |
ClinGen TOPMed |
|
|
rs757703165 CA718122 |
202 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs28904899 CA718121 VAR_023302 |
203 | N>S | No |
ClinGen UniProt 1000Genomes ExAC TOPMed dbSNP gnomAD |
|
|
CA718120 rs778270017 |
204 | G>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs753219520 CA718118 |
206 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA718117 rs766986933 |
207 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA339251010 rs1235204609 |
209 | Q>P | No |
ClinGen gnomAD |
|
|
CA339250996 rs1235350021 |
211 | Q>E | No |
ClinGen TOPMed |
|
|
CA718097 rs751138848 |
218 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs779533846 CA718096 |
220 | P>L | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 220 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA339250915 rs1322275693 |
221 | R>G | No |
ClinGen gnomAD |
|
|
CA339250911 rs1409510067 |
221 | R>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
CA718093 rs765037324 |
228 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
CA718092 rs761625313 |
228 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
rs1419416341 CA339250853 |
229 | D>E | No |
ClinGen TOPMed gnomAD |
|
|
rs1009900509 CA19932233 |
232 | N>T | No |
ClinGen TOPMed |
|
|
rs747655908 CA19932227 |
233 | Q>H | No |
ClinGen Ensembl |
|
|
rs371319377 CA718091 |
236 | H>Y | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs760520445 CA718090 CA718089 |
237 | M>I | No |
ClinGen ExAC |
|
|
rs1455059474 CA339250800 |
237 | M>K | No |
ClinGen gnomAD |
|
|
CA19932216 rs201582355 |
237 | M>V | No |
ClinGen 1000Genomes |
|
|
CA718088 rs774640706 |
238 | S>P | No |
ClinGen ExAC gnomAD |
|
|
rs1054090047 CA19932201 |
240 | S>F | No |
ClinGen TOPMed |
|
|
CA339250782 rs1054090047 |
240 | S>Y | No |
ClinGen TOPMed |
|
|
rs771103313 CA718087 |
242 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA339250768 rs1168426964 |
243 | K>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA339250747 rs1359154141 |
244 | Q>K | No |
ClinGen gnomAD |
|
|
rs986227010 CA19931421 |
245 | A>P | No |
ClinGen Ensembl |
|
|
CA718062 rs768876425 |
252 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA718061 rs747532813 |
254 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs1420353749 CA339250676 |
254 | H>Y | No |
ClinGen gnomAD |
|
|
COSM907934 CA19931409 rs769494381 |
255 | I>V | endometrium [Cosmic] | No |
ClinGen cosmic curated Ensembl |
| TCGA novel | 256 | Y>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs367687334 CA19931401 |
262 | D>E | No |
ClinGen Ensembl |
|
|
CA718057 rs771571842 |
264 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs1557461116 CA339250605 |
264 | F>S | No |
ClinGen Ensembl |
|
|
rs550898082 CA718056 |
265 | K>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA339250570 rs1439443744 |
269 | A>G | No |
ClinGen gnomAD |
No associated diseases with P15927
1 regional properties for P15927
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Replication protein A, C-terminal | 166 - 262 | IPR014892 |
7 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromatin | The ordered and organized complex of DNA, protein, and sometimes RNA, that forms the chromosome. |
| chromosome, telomeric region | The end of a linear chromosome, required for the integrity and maintenance of the end. A chromosome telomere usually includes a region of telomerase-encoded repeats the length of which rarely exceeds 20 bp each and that permits the formation of a telomeric loop (T-loop). The telomeric repeat region is usually preceded by a sub-telomeric region that is gene-poor but rich in repetitive elements. Some telomeres only consist of the latter part (for eg. D. melanogaster telomeres). |
| DNA replication factor A complex | A conserved heterotrimeric complex that binds nonspecifically to single-stranded DNA and is required for multiple processes in eukaryotic DNA metabolism, including DNA replication, DNA repair, and recombination. In all eukaryotic organisms examined the complex is composed of subunits of approximately 70, 30, and 14 kDa. |
| nuclear body | Extra-nucleolar nuclear domains usually visualized by confocal microscopy and fluorescent antibodies to specific proteins. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| PML body | A class of nuclear body; they react against SP100 auto-antibodies (PML, promyelocytic leukemia); cells typically contain 10-30 PML bodies per nucleus; alterations in the localization of PML bodies occurs after viral infection. |
7 GO annotations of molecular function
| Name | Definition |
|---|---|
| damaged DNA binding | Binding to damaged DNA. |
| enzyme binding | Binding to an enzyme, a protein with catalytic activity. |
| G-rich strand telomeric DNA binding | Binding to G-rich, single-stranded, telomere-associated DNA. |
| protein N-terminus binding | Binding to a protein N-terminus, the end of any peptide chain at which the 2-amino (or 2-imino) function of a constituent amino acid is not attached in peptide linkage to another amino-acid residue. |
| protein phosphatase binding | Binding to a protein phosphatase. |
| single-stranded DNA binding | Binding to single-stranded DNA. |
| ubiquitin protein ligase binding | Binding to a ubiquitin protein ligase enzyme, any of the E3 proteins. |
10 GO annotations of biological process
| Name | Definition |
|---|---|
| base-excision repair | In base excision repair, an altered base is removed by a DNA glycosylase enzyme, followed by excision of the resulting sugar phosphate. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. |
| DNA replication | The cellular metabolic process in which a cell duplicates one or more molecules of DNA. DNA replication begins when specific sequences, known as origins of replication, are recognized and bound by initiation proteins, and ends when the original DNA molecule has been completely duplicated and the copies topologically separated. The unit of replication usually corresponds to the genome of the cell, an organelle, or a virus. The template for replication can either be an existing DNA molecule or RNA. |
| double-strand break repair via homologous recombination | The error-free repair of a double-strand break in DNA in which the broken DNA molecule is repaired using homologous sequences. A strand in the broken DNA searches for a homologous region in an intact chromosome to serve as the template for DNA synthesis. The restoration of two intact DNA molecules results in the exchange, reciprocal or nonreciprocal, of genetic material between the intact DNA molecule and the broken DNA molecule. |
| mismatch repair | A system for the correction of errors in which an incorrect base, which cannot form hydrogen bonds with the corresponding base in the parent strand, is incorporated into the daughter strand. The mismatch repair system promotes genomic fidelity by repairing base-base mismatches, insertion-deletion loops and heterologies generated during DNA replication and recombination. |
| mitotic G1 DNA damage checkpoint signaling | A signal transduction process that contributes to a mitotic cell cycle G1/S transition DNA damage checkpoint. |
| nucleotide-excision repair | A DNA repair process in which a small region of the strand surrounding the damage is removed from the DNA helix as an oligonucleotide. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. Nucleotide excision repair recognizes a wide range of substrates, including damage caused by UV irradiation (pyrimidine dimers and 6-4 photoproducts) and chemicals (intrastrand cross-links and bulky adducts). |
| protein localization to chromosome | Any process in which a protein is transported to, or maintained at, a specific location on a chromosome. |
| regulation of DNA damage checkpoint | Any process that modulates the frequency, rate or extent of a DNA damage checkpoint. |
| regulation of double-strand break repair via homologous recombination | Any process that modulates the frequency, rate or extent of the error-free repair of a double-strand break in DNA in which the broken DNA molecule is repaired using homologous sequences. |
| telomere maintenance | Any process that contributes to the maintenance of proper telomeric length and structure by affecting and monitoring the activity of telomeric proteins, the length of telomeric DNA and the replication and repair of the DNA. These processes includes those that shorten, lengthen, replicate and repair the telomeric DNA sequences. |
3 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q13156 | RPA4 | Replication protein A 30 kDa subunit | Homo sapiens (Human) | PR |
| Q9ZQ19 | RPA2A | Replication protein A 32 kDa subunit A | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q6DJ48 | stn1 | CST complex subunit STN1 | Xenopus tropicalis (Western clawed frog) (Silurana tropicalis) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MWNSGFESYG | SSSYGGAGGY | TQSPGGFGSP | APSQAEKKSR | ARAQHIVPCT | ISQLLSATLV |
| 70 | 80 | 90 | 100 | 110 | 120 |
| DEVFRIGNVE | ISQVTIVGII | RHAEKAPTNI | VYKIDDMTAA | PMDVRQWVDT | DDTSSENTVV |
| 130 | 140 | 150 | 160 | 170 | 180 |
| PPETYVKVAG | HLRSFQNKKS | LVAFKIMPLE | DMNEFTTHIL | EVINAHMVLS | KANSQPSAGR |
| 190 | 200 | 210 | 220 | 230 | 240 |
| APISNPGMSE | AGNFGGNSFM | PANGLTVAQN | QVLNLIKACP | RPEGLNFQDL | KNQLKHMSVS |
| 250 | 260 | ||||
| SIKQAVDFLS | NEGHIYSTVD | DDHFKSTDAE |