P12956
Gene name |
XRCC6 (G22P1) |
Protein name |
X-ray repair cross-complementing protein 6 |
Names |
5'-deoxyribose-5-phosphate lyase Ku70, 5'-dRP lyase Ku70, 70 kDa subunit of Ku antigen, ATP-dependent DNA helicase 2 subunit 1, ATP-dependent DNA helicase II 70 kDa subunit, CTC box-binding factor 75 kDa subunit, CTC75, CTCBF, DNA repair protein XRCC6, Lupus Ku autoantigen protein p70, Ku70, Thyroid-lupus autoantigen, TLAA, X-ray repair complementing defective repair in Chinese hamster cells 6 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:2547 |
EC number |
|
Protein Class |
|
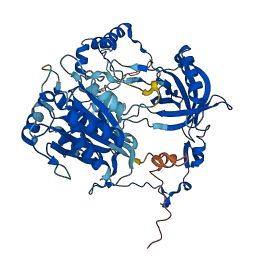
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
38 structures for P12956
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1JEQ | X-ray | 270 A | A | 1-609 | PDB |
| 1JEY | X-ray | 250 A | A | 1-609 | PDB |
| 1JJR | NMR | - | A | 556-609 | PDB |
| 3RZX | X-ray | 261 A | B | 537-558 | PDB |
| 5Y3R | EM | 660 A | A | 34-534 | PDB |
| 6ERF | X-ray | 301 A | A/C/E/G | 1-544 | PDB |
| 6ERG | X-ray | 290 A | A/D | 1-544 | PDB |
| 6ERH | X-ray | 280 A | A/C | 1-544 | PDB |
| 6ZHA | EM | 391 A | B | 1-609 | PDB |
| 6ZHE | EM | 724 A | B/G | 1-609 | PDB |
| 7AXZ | EM | 320 A | A | 1-609 | PDB |
| 7K0Y | EM | 370 A | B | 1-609 | PDB |
| 7K1J | EM | 390 A | B | 1-609 | PDB |
| 7K1K | EM | 410 A | B | 1-609 | PDB |
| 7K1N | EM | 390 A | B | 1-609 | PDB |
| 7LSY | EM | 840 A | A/J | 1-600 | PDB |
| 7LT3 | EM | 460 A | A/J | 1-609 | PDB |
| 7NFC | EM | 414 A | B/G | 1-609 | PDB |
| 7NFE | EM | 429 A | B | 1-609 | PDB |
| 7SGL | EM | 300 A | B | 1-609 | PDB |
| 7SU3 | EM | 330 A | B | 1-609 | PDB |
| 7Z6O | X-ray | 370 A | A | 1-609 | PDB |
| 7Z87 | EM | 291 A | B | 1-609 | PDB |
| 7Z88 | EM | 333 A | B | 1-609 | PDB |
| 7ZT6 | EM | 350 A | A | 1-609 | PDB |
| 7ZVT | EM | 274 A | A | 1-609 | PDB |
| 7ZWA | EM | 280 A | A | 1-609 | PDB |
| 7ZYG | EM | 268 A | A | 1-609 | PDB |
| 8AG4 | EM | 246 A | A | 1-609 | PDB |
| 8AG5 | EM | 347 A | A | 1-609 | PDB |
| 8ASC | X-ray | 295 A | A/E/K/O | 1-544 | PDB |
| 8BH3 | EM | 455 A | B/T | 1-609 | PDB |
| 8BHV | EM | 451 A | a/h | 1-609 | PDB |
| 8BHY | EM | 533 A | B/T | 1-609 | PDB |
| 8BOT | EM | 776 A | B/G/T | 1-609 | PDB |
| 8EZA | EM | 439 A | A/J | 1-609 | PDB |
| 8EZB | EM | 890 A | A/J | 1-609 | PDB |
| AF-P12956-F1 | Predicted | AlphaFoldDB |
307 variants for P12956
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA411734658 rs1601521436 |
4 | W>G | No |
ClinGen Ensembl |
|
|
CA411734674 rs1194159758 |
6 | S>P | No |
ClinGen TOPMed |
|
|
CA324609761 rs200736808 |
7 | Y>C | No |
ClinGen TOPMed gnomAD |
|
|
CA10259062 rs547529160 |
18 | E>G | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA411734778 rs1601521483 |
19 | E>G | No |
ClinGen Ensembl |
|
|
rs1601521493 CA411734792 |
21 | E>K | No |
ClinGen Ensembl |
|
|
rs769585677 CA10259064 |
22 | E>D | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 23 | N>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1569075524 CA411734817 |
24 | L>F | No |
ClinGen Ensembl |
|
|
CA411734846 rs1181240905 |
27 | S>G | No |
ClinGen gnomAD |
|
|
rs369186241 CA324609813 |
27 | S>N | No |
ClinGen ESP TOPMed gnomAD |
|
| TCGA novel | 27 | S>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs369186241 CA411734848 |
27 | S>T | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA639458668 rs1285050452 |
30 | Y>* | No |
ClinGen gnomAD |
|
|
CA10259090 rs774503375 |
30 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1218396338 CA411735649 |
36 | D>E | No |
ClinGen gnomAD |
|
|
CA324615160 rs920294126 |
36 | D>H | No |
ClinGen Ensembl |
|
|
CA324615164 rs577676183 |
38 | L>F | No |
ClinGen Ensembl |
|
|
CA411735670 rs1309062456 |
39 | I>M | No |
ClinGen TOPMed gnomAD |
|
|
rs1207517177 CA411735675 |
40 | F>C | No |
ClinGen gnomAD |
|
| rs1296088221 | 41 | L>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs950456250 CA324615169 |
44 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA324615173 rs746333795 |
45 | S>A | No |
ClinGen Ensembl |
|
|
rs983186249 CA324615177 |
46 | K>R | No |
ClinGen Ensembl |
|
|
rs745930113 CA10259091 |
47 | A>G | No |
ClinGen ExAC gnomAD |
|
|
rs538300003 CA10259092 |
50 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1420601304 CA411735757 |
52 | Q>H | No |
ClinGen gnomAD |
|
|
CA10259094 rs761297117 |
52 | Q>K | No |
ClinGen ExAC gnomAD |
|
|
CA411735776 rs1166254574 |
55 | D>H | No |
ClinGen gnomAD |
|
|
CA10259095 rs764318806 |
56 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA411735783 rs1359279263 |
56 | E>K | No |
ClinGen TOPMed |
|
|
CA411735802 rs1424742034 |
58 | T>I | No |
ClinGen gnomAD |
|
|
rs777034808 CA10259096 |
62 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1204123047 CA411736094 |
63 | S>G | No |
ClinGen gnomAD |
|
|
rs1175785361 CA411736105 |
64 | I>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs1270734225 CA411736109 |
65 | Q>E | No |
ClinGen gnomAD |
|
|
COSM479009 CA411736108 rs1270734225 |
65 | Q>K | kidney [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs1453586938 CA411737313 |
66 | C>F | No |
ClinGen gnomAD |
|
|
rs1286202577 CA411737316 |
67 | I>F | No |
ClinGen gnomAD |
|
|
CA411737334 rs1429698986 |
69 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
rs5758399 CA324620063 |
72 | I>F | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs5758399 CA10259113 |
72 | I>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs775736811 CA10259114 |
73 | S>R | No |
ClinGen ExAC gnomAD |
|
|
rs1311787643 CA411737381 |
76 | I>V | No |
ClinGen TOPMed |
|
|
rs769178314 CA10259116 |
77 | S>R | No |
ClinGen ExAC gnomAD |
|
|
CA411737411 rs1394023551 |
80 | R>* | No |
ClinGen TOPMed |
|
| TCGA novel | 80 | R>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA10259118 rs762229472 |
83 | L>F | No |
ClinGen ExAC |
|
|
CA324620086 CA411737442 rs370335839 |
85 | V>L | No |
ClinGen gnomAD |
|
|
CA411737441 rs370335839 |
85 | V>M | No |
ClinGen gnomAD |
|
|
CA10259119 rs765521252 |
86 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA411737457 rs1428549240 |
87 | F>L | No |
ClinGen TOPMed |
|
|
rs773949461 CA10259120 |
87 | F>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10259121 rs755007926 |
88 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10259123 rs373148769 |
91 | E>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs903145339 CA324620110 |
98 | N>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1406490157 CA411737541 |
99 | F>L | No |
ClinGen gnomAD |
|
|
CA324620111 rs999474140 |
101 | N>D | No |
ClinGen TOPMed gnomAD |
|
|
CA411737563 rs1569085375 |
102 | I>M | No |
ClinGen Ensembl |
|
|
rs764078149 CA10259125 |
102 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs757018461 CA10259127 |
104 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA411737588 rs1270879941 |
106 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA324620128 rs11557354 |
107 | E>K | No |
ClinGen Ensembl |
|
|
CA411737603 rs1294103123 |
108 | L>P | No |
ClinGen TOPMed |
|
|
CA324620132 rs960759558 |
109 | D>N | No |
ClinGen gnomAD |
|
|
CA411737606 rs960759558 |
109 | D>Y | No |
ClinGen gnomAD |
|
|
rs1227053698 CA411737621 |
111 | P>A | No |
ClinGen gnomAD |
|
| TCGA novel | 112 | G>= | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA10259147 rs761686722 |
114 | K>N | No |
ClinGen ExAC gnomAD |
|
|
CA324575568 rs931647183 |
115 | R>* | No |
ClinGen Ensembl |
|
|
rs765303000 CA10259148 |
115 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs1434877351 CA411731946 |
120 | D>H | No |
ClinGen gnomAD |
|
|
CA411732294 rs1376817859 |
122 | F>L | No |
ClinGen gnomAD |
|
|
CA411732279 rs1196696640 |
122 | F>L | No |
ClinGen gnomAD |
|
| TCGA novel | 124 | G>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1475621651 CA411732349 |
125 | Q>H | No |
ClinGen gnomAD |
|
|
rs914328332 CA324575581 |
127 | G>E | No |
ClinGen Ensembl |
|
|
CA411732379 rs1427902186 |
128 | Q>R | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 129 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA411732393 rs1207901999 |
130 | R>C | No |
ClinGen TOPMed |
|
|
CA10259151 rs780415976 |
130 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs751831387 CA10259152 |
131 | F>C | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 131 | F>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA324575628 rs11557351 |
132 | Q>R | No |
ClinGen Ensembl |
|
|
CA411732428 rs1322178456 |
133 | D>G | No |
ClinGen gnomAD |
|
|
CA324575661 rs11557348 |
134 | M>I | No |
ClinGen Ensembl |
|
|
CA411732441 rs748302771 |
134 | M>L | No |
ClinGen ExAC gnomAD |
|
|
CA10259155 rs748302771 |
134 | M>V | No |
ClinGen ExAC gnomAD |
|
|
CA411732457 rs1299342859 |
135 | M>V | No |
ClinGen gnomAD |
|
|
CA411732483 rs1339715918 |
136 | G>A | No |
ClinGen gnomAD |
|
|
rs368664677 CA10259158 |
138 | G>R | No |
ClinGen ESP ExAC gnomAD |
|
|
rs775066234 CA10259160 |
141 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10259161 rs201771953 |
142 | S>L | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs775971407 CA10259163 |
143 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs140162874 CA324575668 |
145 | E>G | No |
ClinGen ESP gnomAD |
|
|
rs1463325354 CA411732555 |
145 | E>K | No |
ClinGen TOPMed |
|
|
rs761432957 CA10259164 |
146 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs1369088289 CA411732573 |
148 | W>R | No |
ClinGen gnomAD |
|
|
rs903094529 CA324575687 |
150 | C>R | No |
ClinGen Ensembl |
|
|
rs1344187036 CA411732598 COSM1232990 |
151 | A>V | large_intestine [Cosmic] | No |
ClinGen cosmic curated TOPMed |
|
rs750448678 CA10259166 |
157 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA10259167 rs762766085 |
158 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
CA411732655 rs1436272185 |
159 | F>Y | No |
ClinGen gnomAD |
|
|
CA411732667 rs1404122751 |
161 | M>V | No |
ClinGen gnomAD |
|
|
CA10259168 rs766303484 |
162 | S>G | No |
ClinGen ExAC gnomAD |
|
|
CA324575705 rs986593782 |
162 | S>I | No |
ClinGen TOPMed |
|
|
CA411732677 rs986593782 |
162 | S>N | No |
ClinGen TOPMed |
|
|
rs751769011 CA10259169 |
163 | H>R | No |
ClinGen ExAC |
|
|
rs372965250 CA10259170 |
166 | I>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA411732706 rs1362550653 |
166 | I>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs755798578 CA324575713 |
166 | I>V | No |
ClinGen Ensembl |
|
|
CA411732713 rs1296338943 |
167 | M>T | No |
ClinGen TOPMed |
|
|
CA10259171 rs781528484 |
171 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10259172 rs752708099 |
172 | E>A | No |
ClinGen ExAC gnomAD |
|
|
CA411732779 rs1601536994 |
174 | N>T | No |
ClinGen Ensembl |
|
|
CA10259174 rs778186685 |
176 | H>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs577089846 CA10259176 |
177 | G>D | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs558810043 CA324575744 |
177 | G>S | No |
ClinGen 1000Genomes |
|
|
CA411732850 rs1414452382 |
178 | N>S | No |
ClinGen TOPMed |
|
|
rs377060517 CA10259177 |
179 | D>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1185595302 CA411732923 |
182 | K>R | No |
ClinGen gnomAD |
|
|
CA324575757 rs200942837 |
185 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs768169162 CA10259179 |
185 | R>W | No |
ClinGen ExAC gnomAD |
|
|
CA10259180 rs776401056 |
186 | A>G | No |
ClinGen ExAC gnomAD |
|
|
CA10259181 rs776401056 |
186 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA411733004 rs773221766 |
187 | R>G | No |
ClinGen ExAC gnomAD |
|
|
rs1303054561 CA411733023 |
188 | T>A | No |
ClinGen gnomAD |
|
|
CA10259185 rs61754573 |
191 | G>C | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs61754573 CA10259184 |
191 | G>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1350598621 CA411733111 |
193 | L>I | No |
ClinGen gnomAD |
|
|
CA411733131 rs1276355929 |
194 | R>* | No |
ClinGen TOPMed |
|
|
rs1266166982 CA411733135 |
194 | R>Q | No |
ClinGen gnomAD |
|
|
rs1483415743 CA411733211 |
203 | M>V | No |
ClinGen gnomAD |
|
|
rs1207467404 CA411733234 |
206 | K>E | No |
ClinGen gnomAD |
|
|
CA411733237 rs1250210587 |
206 | K>R | No |
ClinGen gnomAD |
|
|
rs1192312604 CA411733253 |
208 | P>H | No |
ClinGen gnomAD |
|
|
CA411733250 rs1404927101 |
208 | P>S | No |
ClinGen TOPMed |
|
|
rs780639260 CA10259201 |
209 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA411733258 rs1431804859 |
209 | G>V | No |
ClinGen TOPMed gnomAD |
|
|
rs747846355 CA10259202 |
210 | G>V | No |
ClinGen ExAC gnomAD |
|
|
CA411733292 COSM4004941 rs1390461982 |
214 | S>F | urinary_tract [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
rs1390461982 CA411733290 |
214 | S>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA10259203 rs769393588 |
215 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs897949939 CA324576519 |
218 | R>G | No |
ClinGen Ensembl |
|
|
CA10259205 rs748860086 |
219 | D>E | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 219 | D>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 220 | I>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA10259207 rs201075469 |
222 | S>G | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1365154504 COSM3939661 CA411733356 |
224 | A>T | oesophagus [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA10259208 rs759188998 |
225 | E>A | No |
ClinGen ExAC gnomAD |
|
|
rs1218488187 CA411733362 |
225 | E>K | No |
ClinGen gnomAD |
|
|
rs775525989 CA10259210 |
226 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10259209 rs767358697 |
226 | D>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10259212 rs764339481 |
228 | D>G | No |
ClinGen ExAC gnomAD |
|
|
rs11557355 CA324576534 |
228 | D>Y | No |
ClinGen gnomAD |
|
|
CA324576570 rs997675783 |
232 | H>R | No |
ClinGen TOPMed |
|
|
rs1253724582 CA411733419 |
233 | F>V | No |
ClinGen TOPMed |
|
| TCGA novel | 237 | S>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA411733487 rs1365430665 |
239 | L>P | No |
ClinGen TOPMed |
|
|
rs1193473163 CA411733567 |
244 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1342799546 CA411733599 |
246 | V>F | No |
ClinGen TOPMed |
|
|
rs757383465 CA10259214 |
247 | R>C | No |
ClinGen ExAC gnomAD |
|
|
rs758629534 CA10259217 |
248 | A>D | No |
ClinGen ExAC gnomAD |
|
|
rs750942031 CA10259216 |
248 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs750942031 CA324576624 |
248 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 263 | L>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA411735211 rs1331599994 |
264 | N>K | No |
ClinGen gnomAD |
|
|
CA10259240 rs777502377 |
264 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA411735209 rs777502377 |
264 | N>T | No |
ClinGen ExAC gnomAD |
|
|
CA10259241 rs753559698 |
266 | D>V | No |
ClinGen ExAC gnomAD |
|
|
CA10259243 rs778516859 |
267 | I>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
COSM726988 CA10259242 rs369020045 |
267 | I>T | lung Variant assessed as Somatic; 0.0 impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA411735229 COSM1632627 rs1283082601 |
267 | I>V | liver [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs1569091454 CA411735245 |
269 | I>M | No |
ClinGen Ensembl |
|
|
rs1162090714 CA411735258 |
272 | G>S | No |
ClinGen TOPMed |
|
|
rs1474598846 CA411735263 |
272 | G>V | No |
ClinGen gnomAD |
|
|
rs62621117 CA411735265 |
273 | I>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs62621117 CA10259246 |
273 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA411735271 rs1601546442 |
274 | Y>H | No |
ClinGen Ensembl |
|
|
CA10259247 rs746801065 |
283 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs776773263 COSM1308222 CA10259249 |
284 | P>S | Variant assessed as Somatic; impact. urinary_tract [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
rs1488422006 CA411735344 |
285 | P>A | No |
ClinGen TOPMed |
|
| TCGA novel | 287 | K>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs762113155 CA10259250 |
293 | N>S | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 294 | E>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA10259253 rs763005618 |
301 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs773323415 CA10259252 |
301 | R>W | No |
ClinGen ExAC gnomAD |
|
|
CA10259254 rs766906979 |
304 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA411735486 rs1220532835 |
306 | S>I | No |
ClinGen gnomAD |
|
|
CA324583191 rs920055919 |
307 | T>I | No |
ClinGen Ensembl |
|
|
rs576287152 CA10259255 |
309 | G>S | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA324583207 rs952979212 |
310 | L>F | No |
ClinGen Ensembl |
|
|
CA10259256 rs759924833 |
314 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10259259 rs756901999 |
317 | K>R | No |
ClinGen ExAC gnomAD |
|
|
CA10259281 rs750047356 |
321 | I>M | No |
ClinGen ExAC gnomAD |
|
|
rs1324351825 CA411736252 |
325 | R>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1370742072 CA411736275 |
327 | I>V | No |
ClinGen gnomAD |
|
|
CA10259283 rs369839566 |
334 | T>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs751455021 CA10259284 |
337 | L>V | No |
ClinGen ExAC |
|
|
CA10259285 rs754875330 |
339 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs943053443 CA324585261 |
341 | D>Y | No |
ClinGen Ensembl |
|
|
rs781168212 CA10259286 |
343 | P>T | No |
ClinGen ExAC gnomAD |
|
|
CA10259287 rs373568942 |
346 | M>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs144313964 CA10259290 CA411736730 |
348 | M>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs777997397 CA411736713 |
348 | M>L | No |
ClinGen ExAC gnomAD |
|
|
rs1451190945 CA411736721 |
348 | M>T | No |
ClinGen TOPMed |
|
|
CA10259289 rs777997397 |
348 | M>V | No |
ClinGen ExAC gnomAD |
|
|
CA10259291 rs771094973 |
352 | P>Q | No |
ClinGen ExAC gnomAD |
|
|
rs1302456390 CA411736881 |
358 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
CA324585282 rs148749706 |
359 | H>Y | No |
ClinGen ESP TOPMed gnomAD |
|
| TCGA novel | 361 | Y>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA411736968 rs1303560810 |
364 | P>S | No |
ClinGen gnomAD |
|
|
CA411737028 rs761413214 |
368 | V>L | No |
ClinGen TOPMed gnomAD |
|
|
CA324585305 rs761413214 |
368 | V>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
COSM1714429 CA10259297 rs562297881 |
373 | S>L | skin [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs764939773 CA324585308 |
373 | S>P | No |
ClinGen TOPMed |
|
|
rs1569094194 CA411737134 |
374 | L>P | No |
ClinGen Ensembl |
|
|
rs1163911254 CA411737659 |
380 | T>A | No |
ClinGen gnomAD |
|
|
rs571011219 CA10259328 |
383 | S>G | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1411546189 CA411737692 |
385 | L>V | No |
ClinGen TOPMed gnomAD |
|
|
COSM95548 rs1370772338 CA411737702 |
387 | I>L | lung [Cosmic] | No |
ClinGen cosmic curated TOPMed |
|
rs758500661 CA10259330 |
387 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs1330453852 CA411737724 |
390 | L>M | No |
ClinGen TOPMed gnomAD |
|
|
CA411737753 rs1350374829 |
394 | V>I | No |
ClinGen gnomAD |
|
|
CA324586692 rs61754571 |
395 | A>T | No |
ClinGen Ensembl |
|
|
CA10259334 rs781757979 |
402 | P>A | No |
ClinGen ExAC gnomAD |
|
|
rs937641717 CA411737819 |
404 | R>K | No |
ClinGen TOPMed gnomAD |
|
|
CA324586714 rs937641717 |
404 | R>M | No |
ClinGen TOPMed gnomAD |
|
|
CA10259335 rs748448265 |
406 | I>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs770840046 CA324586719 |
412 | A>G | No |
ClinGen Ensembl |
|
|
rs75407440 CA324586725 |
413 | L>F | No |
ClinGen Ensembl |
|
|
rs773947446 CA10259337 |
422 | D>E | No |
ClinGen ExAC gnomAD |
|
|
CA411737943 rs1192175214 |
422 | D>N | No |
ClinGen gnomAD |
|
|
rs745552492 CA10259338 |
425 | I>V | No |
ClinGen ExAC |
|
|
rs953734753 CA411737979 CA324586738 |
427 | V>L | No |
ClinGen TOPMed |
|
|
CA411737986 rs1390188802 |
428 | T>I | No |
ClinGen gnomAD |
|
|
CA411737996 COSM726986 rs1168219605 |
430 | P>A | lung Variant assessed as Somatic; impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
CA411737997 rs1168219605 |
430 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1213240826 COSM1751896 CA411738288 |
433 | Q>* | urinary_tract [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA10259365 rs761869477 |
441 | D>N | No |
ClinGen ExAC gnomAD |
|
|
rs988785854 CA324588568 |
447 | P>L | No |
ClinGen Ensembl |
|
|
CA10259367 rs773117386 |
447 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA411738423 rs1474738744 |
452 | I>F | No |
ClinGen TOPMed gnomAD |
|
|
CA411738422 rs1474738744 |
452 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
rs541350436 CA10259368 |
453 | M>I | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA411738430 rs1409912479 |
453 | M>L | No |
ClinGen TOPMed gnomAD |
|
|
CA411738429 rs1409912479 |
453 | M>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1449664540 CA411738450 |
456 | P>S | No |
ClinGen TOPMed |
|
|
CA411738468 rs1247848455 |
458 | Q>H | No |
ClinGen TOPMed |
|
|
rs1344628680 CA411738479 |
460 | G>D | No |
ClinGen gnomAD |
|
|
rs767619167 CA10259372 |
465 | I>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10259371 rs754968679 |
465 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs368079935 CA10259374 |
466 | V>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA10259375 rs759844857 |
470 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA |
|
CA10259376 COSM3694086 rs749612494 |
470 | R>H | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
CA411738571 rs1334035620 |
474 | R>G | No |
ClinGen gnomAD |
|
|
rs1236067253 CA411738604 |
476 | D>E | No |
ClinGen gnomAD |
|
|
rs1569098339 CA411738634 |
480 | N>S | No |
ClinGen Ensembl |
|
|
COSM1034663 rs1346522683 CA411738644 |
482 | V>M | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
| TCGA novel | 482 | V>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA324589328 rs4084339 |
486 | H>L | No |
ClinGen Ensembl |
|
|
rs754380678 CA10259394 |
491 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs1202005824 CA411738805 |
497 | L>F | No |
ClinGen gnomAD |
|
|
rs1180876831 CA411738810 |
498 | M>L | No |
ClinGen gnomAD |
|
|
rs757515014 CA10259395 |
498 | M>T | No |
ClinGen ExAC gnomAD |
|
|
rs1001294599 CA324589332 |
500 | P>A | No |
ClinGen TOPMed |
|
|
COSM385169 rs1454837878 CA411738849 |
500 | P>L | lung [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
CA10259396 rs553304643 |
501 | E>A | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs553304643 CA411738856 |
501 | E>G | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs750789414 CA10259397 |
502 | Q>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA411738870 rs750789414 |
502 | Q>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1168992420 CA411738891 |
504 | V>M | No |
ClinGen gnomAD |
|
|
rs754651274 CA10259399 |
507 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA324591140 rs911441935 |
513 | A>E | No |
ClinGen Ensembl |
|
|
CA10259423 rs61754572 |
513 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA10259424 rs369429364 |
514 | M>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA10259425 rs745597419 |
516 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs1336667146 CA411739436 |
518 | L>P | No |
ClinGen gnomAD |
|
| TCGA novel | 518 | L>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA411739434 rs1293845932 |
518 | L>V | No |
ClinGen gnomAD |
|
|
CA411739441 rs1601559857 |
519 | G>D | No |
ClinGen Ensembl |
|
|
rs1271482191 CA411739448 |
520 | S>F | No |
ClinGen gnomAD |
|
|
rs1231270659 CA411739446 |
520 | S>P | No |
ClinGen gnomAD |
|
|
rs1488250273 CA411739495 |
527 | E>K | No |
ClinGen gnomAD |
|
| TCGA novel | 528 | L>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs968329582 CA324591155 |
530 | Y>H | No |
ClinGen Ensembl |
|
|
rs775639157 CA10259427 |
531 | P>R | No |
ClinGen ExAC gnomAD |
|
|
CA411739534 rs1193885084 |
533 | D>N | No |
ClinGen TOPMed |
|
|
CA324591179 rs1803107 |
534 | Y>F | No |
ClinGen Ensembl |
|
| TCGA novel | 537 | E>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1163289632 CA411739585 |
540 | V>L | No |
ClinGen gnomAD |
|
|
CA10259431 rs761852720 |
541 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs773594748 CA10259433 |
545 | H>Y | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 550 | S>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA411739941 rs1429713148 |
551 | G>R | No |
ClinGen TOPMed |
|
|
rs1259056307 CA411739950 |
552 | S>N | No |
ClinGen gnomAD |
|
|
rs151012067 CA10259456 |
559 | Y>H | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1569101422 CA411740011 |
561 | E>K | No |
ClinGen Ensembl |
|
|
rs1234442646 CA411740116 |
571 | G>A | No |
ClinGen TOPMed |
|
|
CA324592494 rs3179615 |
583 | E>K | No |
ClinGen Ensembl |
|
|
CA10259460 rs753447958 |
586 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs999945015 CA324592497 |
587 | A>T | No |
ClinGen TOPMed |
|
|
rs538910971 CA411740421 CA10259462 |
589 | G>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA10259468 rs781415973 |
602 | A>S | No |
ClinGen ExAC gnomAD |
|
|
CA10259469 rs576808369 |
605 | K>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA324592526 rs1020933883 |
608 | Q>R | No |
ClinGen TOPMed |
|
|
rs777980914 CA10259471 |
609 | D>G | No |
ClinGen ExAC gnomAD |
No associated diseases with P12956
5 regional properties for P12956
16 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromosome, telomeric region | The end of a linear chromosome, required for the integrity and maintenance of the end. A chromosome telomere usually includes a region of telomerase-encoded repeats the length of which rarely exceeds 20 bp each and that permits the formation of a telomeric loop (T-loop). The telomeric repeat region is usually preceded by a sub-telomeric region that is gene-poor but rich in repetitive elements. Some telomeres only consist of the latter part (for eg. D. melanogaster telomeres). |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| DNA-dependent protein kinase complex | A protein complex that is involved in the repair of DNA double-strand breaks and, in mammals, V(D)J recombination events. It consists of the DNA-dependent protein kinase catalytic subunit (DNA-PKcs) and the DNA end-binding heterodimer Ku. |
| extracellular region | The space external to the outermost structure of a cell. For cells without external protective or external encapsulating structures this refers to space outside of the plasma membrane. This term covers the host cell environment outside an intracellular parasite. |
| ficolin-1-rich granule lumen | Any membrane-enclosed lumen that is part of a ficolin-1-rich granule. |
| Ku70:Ku80 complex | Heterodimeric protein complex composed of a 70 kDa and a 80 kDa subunit, binds DNA through a channel formed by the heterodimer. Functions in DNA double stranded break repair, chromosome maintenance, transcription regulation, V(D)J recombination, and activation of DNA-PK. |
| membrane | A lipid bilayer along with all the proteins and protein complexes embedded in it an attached to it. |
| nonhomologous end joining complex | A protein complex that plays a role in DNA double-strand break repair via nonhomologous end joining. Such complexes typically contain a specialized DNA ligase (e.g. Lig4 in eukaryotes) and one or more proteins that bind to DNA ends. |
| nuclear telomere cap complex | A complex of DNA and protein located at the end of a linear chromosome in the nucleus that protects and stabilizes a linear chromosome. |
| nucleolus | A small, dense body one or more of which are present in the nucleus of eukaryotic cells. It is rich in RNA and protein, is not bounded by a limiting membrane, and is not seen during mitosis. Its prime function is the transcription of the nucleolar DNA into 45S ribosomal-precursor RNA, the processing of this RNA into 5.8S, 18S, and 28S components of ribosomal RNA, and the association of these components with 5S RNA and proteins synthesized outside the nucleolus. This association results in the formation of ribonucleoprotein precursors; these pass into the cytoplasm and mature into the 40S and 60S subunits of the ribosome. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| protein-containing complex | A stable assembly of two or more macromolecules, i.e. proteins, nucleic acids, carbohydrates or lipids, in which at least one component is a protein and the constituent parts function together. |
| protein-DNA complex | A macromolecular complex containing both protein and DNA molecules. |
| secretory granule lumen | The volume enclosed by the membrane of a secretory granule. |
| transcription regulator complex | A protein complex that is capable of associating with DNA by direct binding, or via other DNA-binding proteins or complexes, and regulating transcription. |
15 GO annotations of molecular function
| Name | Definition |
|---|---|
| 5'-deoxyribose-5-phosphate lyase activity | Catalysis of the beta-elimination of the 5' deoxyribose-5-phosphate at an abasic site in DNA where a DNA-(apurinic or apyrimidinic site) lyase has already cleaved the C-O-P bond 3' to the apurinic or apyrimidinic site. |
| ATP binding | Binding to ATP, adenosine 5'-triphosphate, a universally important coenzyme and enzyme regulator. |
| ATP-dependent activity, acting on DNA | Catalytic activity that acts to modify DNA, driven by ATP hydrolysis. |
| cyclin binding | Binding to cyclins, proteins whose levels in a cell varies markedly during the cell cycle, rising steadily until mitosis, then falling abruptly to zero. As cyclins reach a threshold level, they are thought to drive cells into G2 phase and thus to mitosis. |
| damaged DNA binding | Binding to damaged DNA. |
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| DNA helicase activity | Unwinding of a DNA helix, driven by ATP hydrolysis. |
| double-stranded DNA binding | Binding to double-stranded DNA. |
| hydrolase activity | Catalysis of the hydrolysis of various bonds, e.g. C-O, C-N, C-C, phosphoric anhydride bonds, etc. |
| protein C-terminus binding | Binding to a protein C-terminus, the end of a peptide chain at which the 1-carboxyl function of a constituent amino acid is not attached in peptide linkage to another amino-acid residue. |
| protein-containing complex binding | Binding to a macromolecular complex. |
| RNA binding | Binding to an RNA molecule or a portion thereof. |
| scaffold protein binding | Binding to a scaffold protein. Scaffold proteins are crucial regulators of many key signaling pathways. Although not strictly defined in function, they are known to interact and/or bind with multiple members of a signaling pathway, tethering them into complexes. |
| telomeric DNA binding | Binding to a telomere, a specific structure at the end of a linear chromosome required for the integrity and maintenance of the end. |
| transcription cis-regulatory region binding | Binding to a specific sequence of DNA that is part of a regulatory region that controls transcription of that section of the DNA. The transcribed region might be described as a gene, cistron, or operon. |
15 GO annotations of biological process
| Name | Definition |
|---|---|
| activation of innate immune response | Any process that initiates an innate immune response. Innate immune responses are defense responses mediated by germline encoded components that directly recognize components of potential pathogens. Examples of this process include activation of the hypersensitive response of Arabidopsis thaliana and activation of any NOD or TLR signaling pathway in vertebrate species. |
| cellular response to gamma radiation | Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a gamma radiation stimulus. Gamma radiation is a form of electromagnetic radiation (EMR) or light emission of a specific frequency produced from sub-atomic particle interaction, such as electron-positron annihilation and radioactive decay. Gamma rays are generally characterized as EMR having the highest frequency and energy, and also the shortest wavelength, within the electromagnetic radiation spectrum. |
| cellular response to X-ray | Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of X-ray radiation. An X-ray is a form of electromagnetic radiation with a wavelength in the range of 10 nanometers to 100 picometers (corresponding to frequencies in the range 30 PHz to 3 EHz). |
| DNA ligation | The re-formation of a broken phosphodiester bond in the DNA backbone, carried out by DNA ligase. |
| double-strand break repair via classical nonhomologous end joining | An instance of double-strand break repair via nonhomologous end joining that requires a number of factors important for V(D)J recombination, including the KU70/80 heterodimer (KU), XRCC4, ligase IV, and DNA-PKcs in mammals. It does not produce translocations (as opposed to the alternative nonhomologous end joining). |
| double-strand break repair via nonhomologous end joining | The repair of a double-strand break in DNA in which the two broken ends are rejoined with little or no sequence complementarity. Information at the DNA ends may be lost due to the modification of broken DNA ends. This term covers instances of separate pathways, called classical (or canonical) and alternative nonhomologous end joining (C-NHEJ and A-NHEJ). These in turn may further branch into sub-pathways, but evidence is still unclear. |
| innate immune response | Innate immune responses are defense responses mediated by germline encoded components that directly recognize components of potential pathogens. |
| negative regulation of DNA-templated transcription | Any process that stops, prevents, or reduces the frequency, rate or extent of cellular DNA-templated transcription. |
| positive regulation of DNA-templated transcription | Any process that activates or increases the frequency, rate or extent of cellular DNA-templated transcription. |
| positive regulation of lymphocyte differentiation | Any process that activates or increases the frequency, rate or extent of lymphocyte differentiation. |
| positive regulation of protein kinase activity | Any process that activates or increases the frequency, rate or extent of protein kinase activity. |
| positive regulation of transcription by RNA polymerase II | Any process that activates or increases the frequency, rate or extent of transcription from an RNA polymerase II promoter. |
| recombinational repair | A DNA repair process that involves the exchange, reciprocal or nonreciprocal, of genetic material between the broken DNA molecule and a homologous DNA region. |
| regulation of smooth muscle cell proliferation | Any process that modulates the frequency, rate or extent of smooth muscle cell proliferation. |
| telomere maintenance | Any process that contributes to the maintenance of proper telomeric length and structure by affecting and monitoring the activity of telomeric proteins, the length of telomeric DNA and the replication and repair of the DNA. These processes includes those that shorten, lengthen, replicate and repair the telomeric DNA sequences. |
4 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| O93257 | XRCC6 | X-ray repair cross-complementing protein 5 | Gallus gallus (Chicken) | PR |
| P23475 | Xrcc6 | X-ray repair cross-complementing protein 6 | Mus musculus (Mouse) | PR |
| Q7F1M0 | KU70 | ATP-dependent DNA helicase 2 subunit KU70 | Oryza sativa subsp japonica (Rice) | PR |
| Q9FQ08 | KU70 | ATP-dependent DNA helicase 2 subunit KU70 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSGWESYYKT | EGDEEAEEEQ | EENLEASGDY | KYSGRDSLIF | LVDASKAMFE | SQSEDELTPF |
| 70 | 80 | 90 | 100 | 110 | 120 |
| DMSIQCIQSV | YISKIISSDR | DLLAVVFYGT | EKDKNSVNFK | NIYVLQELDN | PGAKRILELD |
| 130 | 140 | 150 | 160 | 170 | 180 |
| QFKGQQGQKR | FQDMMGHGSD | YSLSEVLWVC | ANLFSDVQFK | MSHKRIMLFT | NEDNPHGNDS |
| 190 | 200 | 210 | 220 | 230 | 240 |
| AKASRARTKA | GDLRDTGIFL | DLMHLKKPGG | FDISLFYRDI | ISIAEDEDLR | VHFEESSKLE |
| 250 | 260 | 270 | 280 | 290 | 300 |
| DLLRKVRAKE | TRKRALSRLK | LKLNKDIVIS | VGIYNLVQKA | LKPPPIKLYR | ETNEPVKTKT |
| 310 | 320 | 330 | 340 | 350 | 360 |
| RTFNTSTGGL | LLPSDTKRSQ | IYGSRQIILE | KEETEELKRF | DDPGLMLMGF | KPLVLLKKHH |
| 370 | 380 | 390 | 400 | 410 | 420 |
| YLRPSLFVYP | EESLVIGSST | LFSALLIKCL | EKEVAALCRY | TPRRNIPPYF | VALVPQEEEL |
| 430 | 440 | 450 | 460 | 470 | 480 |
| DDQKIQVTPP | GFQLVFLPFA | DDKRKMPFTE | KIMATPEQVG | KMKAIVEKLR | FTYRSDSFEN |
| 490 | 500 | 510 | 520 | 530 | 540 |
| PVLQQHFRNL | EALALDLMEP | EQAVDLTLPK | VEAMNKRLGS | LVDEFKELVY | PPDYNPEGKV |
| 550 | 560 | 570 | 580 | 590 | 600 |
| TKRKHDNEGS | GSKRPKVEYS | EEELKTHISK | GTLGKFTVPM | LKEACRAYGL | KSGLKKQELL |
| EALTKHFQD |