O82190
Gene name |
RDR3 (RDRP3, At2g19910, F6F22.6) |
Protein name |
Probable RNA-dependent RNA polymerase 3 |
Names |
AtRDRP3, RNA-directed RNA polymerase 3 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT2G19910 |
EC number |
2.7.7.48: Nucleotidyltransferases |
Protein Class |
|
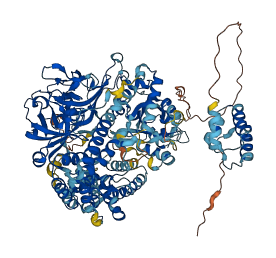
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for O82190
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-O82190-F1 | Predicted | AlphaFoldDB |
177 variants for O82190
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH13290736 | 4 | N>Y | No | 1000Genomes | |
| ENSVATH13290735 | 7 | D>N | No | 1000Genomes | |
| tmp_2_8600734_T_A | 8 | E>D | No | 1000Genomes | |
| tmp_2_8600727_G_A | 11 | P>S | No | 1000Genomes | |
| ENSVATH01848501 | 19 | G>V | No | 1000Genomes | |
| tmp_2_8600678_TTCTC_ATCTC,T | 27 | K>I | No | 1000Genomes | |
| ENSVATH01848499 | 30 | E>A | No | 1000Genomes | |
| tmp_2_8600654_C_T | 35 | R>H | No | 1000Genomes | |
| tmp_2_8600648_G_A | 37 | P>L | No | 1000Genomes | |
| ENSVATH13290734 | 41 | E>* | No | 1000Genomes | |
| tmp_2_8600628_G_A | 44 | R>* | No | 1000Genomes | |
| tmp_2_8600612_A_T | 49 | I>N | No | 1000Genomes | |
| ENSVATH00239582 | 70 | L>H | No | 1000Genomes | |
| tmp_2_8600501_C_T | 86 | G>D | No | 1000Genomes | |
| tmp_2_8600466_G_A | 98 | Q>* | No | 1000Genomes | |
| ENSVATH01848497 | 101 | R>* | No | 1000Genomes | |
| ENSVATH01848496 | 104 | A>G | No | 1000Genomes | |
| ENSVATH01848495 | 106 | K>I | No | 1000Genomes | |
| ENSVATH01848495 | 106 | K>T | No | 1000Genomes | |
| tmp_2_8600309_G_A | 123 | P>L | No | 1000Genomes | |
| ENSVATH01848488 | 125 | F>Y | No | 1000Genomes | |
| ENSVATH01848487 | 126 | M>L | No | 1000Genomes | |
| ENSVATH01848486 | 127 | K>R | No | 1000Genomes | |
| ENSVATH01848484 | 136 | Y>H | No | 1000Genomes | |
| ENSVATH01848482 | 143 | L>F | No | 1000Genomes | |
| tmp_2_8600241_G_C | 146 | L>V | No | 1000Genomes | |
| tmp_2_8600084_C_T | 171 | D>N | No | 1000Genomes | |
| tmp_2_8600081_GA_CA,G | 172 | Q>E | No | 1000Genomes | |
| tmp_2_8600072_TTCTGA_T,GTCTGA | 175 | K>Q | No | 1000Genomes | |
| ENSVATH01848473 | 183 | S>A | No | 1000Genomes | |
| ENSVATH01848472 | 186 | A>S | No | 1000Genomes | |
| ENSVATH01848471 | 190 | N>H | No | 1000Genomes | |
| ENSVATH01848470 | 190 | N>I | No | 1000Genomes | |
| tmp_2_8600019_C_A | 192 | L>F | No | 1000Genomes | |
| tmp_2_8600017_C_G | 193 | G>A | No | 1000Genomes | |
| ENSVATH01848469 | 194 | Q>H | No | 1000Genomes | |
| ENSVATH01848468 | 195 | R>C | No | 1000Genomes | |
| ENSVATH01848467 | 198 | S>P | No | 1000Genomes | |
| ENSVATH01848466 | 199 | P>H | No | 1000Genomes | |
| ENSVATH00239578 | 203 | R>K | No | 1000Genomes | |
| ENSVATH01848457 | 205 | P>S | No | 1000Genomes | |
| tmp_2_8599810_T_A | 210 | S>C | No | 1000Genomes | |
| ENSVATH01848456 | 212 | M>K | No | 1000Genomes | |
| ENSVATH01848454 | 222 | T>P | No | 1000Genomes | |
| tmp_2_8599490_A_C | 232 | L>R | No | 1000Genomes | |
| ENSVATH01848430 | 256 | K>E | No | 1000Genomes | |
| ENSVATH01848429 | 256 | K>N | No | 1000Genomes | |
| ENSVATH01848428 | 258 | L>S | No | 1000Genomes | |
| ENSVATH00239576 | 260 | V>E | No | 1000Genomes | |
| ENSVATH01848427 | 263 | Y>F | No | 1000Genomes | |
| tmp_2_8599388_T_C | 266 | D>G | No | 1000Genomes | |
| ENSVATH01848426 | 270 | T>I | No | 1000Genomes | |
| tmp_2_8599373_T_C | 271 | Y>C | No | 1000Genomes | |
| ENSVATH01848425 | 278 | G>D | No | 1000Genomes | |
| ENSVATH01848425 | 278 | G>V | No | 1000Genomes | |
| tmp_2_8599345_C_T | 280 | M>I | No | 1000Genomes | |
| ENSVATH01848423 | 284 | R>C | No | 1000Genomes | |
| ENSVATH01848421 | 287 | R>Q | No | 1000Genomes | |
| ENSVATH13290719 | 292 | K>* | No | 1000Genomes | |
| ENSVATH01848414 | 298 | E>G | No | 1000Genomes | |
| tmp_2_8599130_T_C | 301 | K>E | No | 1000Genomes | |
| ENSVATH01848413 | 303 | V>F | No | 1000Genomes | |
| ENSVATH01848411 | 316 | D>G | No | 1000Genomes | |
| ENSVATH05538059 | 331 | G>* | No | 1000Genomes | |
| ENSVATH00239572 | 334 | M>I | No | 1000Genomes | |
| ENSVATH07885307 | 340 | H>R | No | 1000Genomes | |
| tmp_2_8598969_C_G | 354 | M>I | No | 1000Genomes | |
| ENSVATH07885304 | 355 | S>A | No | 1000Genomes | |
| tmp_2_8598844_T_A | 363 | K>* | No | 1000Genomes | |
| ENSVATH01848403 | 366 | T>K | No | 1000Genomes | |
| tmp_2_8598826_C_T | 369 | V>I | No | 1000Genomes | |
| ENSVATH01848400 | 371 | M>T | No | 1000Genomes | |
| ENSVATH01848399 | 372 | T>I | No | 1000Genomes | |
| tmp_2_8598807_G_T | 375 | T>N | No | 1000Genomes | |
| ENSVATH01848396 | 378 | Q>K | No | 1000Genomes | |
| ENSVATH01848387 | 387 | Q>E | No | 1000Genomes | |
| ENSVATH01848386 | 389 | D>N | No | 1000Genomes | |
| ENSVATH01848385 | 390 | K>N | No | 1000Genomes | |
| tmp_2_8598605_C_T | 407 | G>S | No | 1000Genomes | |
| ENSVATH01848382 | 415 | R>Q | No | 1000Genomes | |
| ENSVATH01848380 | 419 | V>A | No | 1000Genomes | |
| ENSVATH01848381 | 419 | V>I | No | 1000Genomes | |
| ENSVATH01848379 | 422 | F>Y | No | 1000Genomes | |
| tmp_2_8598554_C_G | 424 | G>R | No | 1000Genomes | |
| ENSVATH01848377 | 427 | M>I | No | 1000Genomes | |
| ENSVATH14522810 | 433 | Q>* | No | 1000Genomes | |
| ENSVATH07885292 | 440 | E>* | No | 1000Genomes | |
| tmp_2_8598389_A_T | 445 | C>* | No | 1000Genomes | |
| ENSVATH07885290 | 447 | Q>K | No | 1000Genomes | |
| ENSVATH00239570 | 448 | E>D | No | 1000Genomes | |
| ENSVATH13290710 | 453 | I>V | No | 1000Genomes | |
| tmp_2_8598270_G_C | 456 | R>G | No | 1000Genomes | |
| ENSVATH00239569 | 457 | I>M | No | 1000Genomes | |
| ENSVATH13290709 | 458 | F>L | No | 1000Genomes | |
| ENSVATH01848355 | 460 | N>K | No | 1000Genomes | |
| tmp_2_8598236_G_A | 467 | T>I | No | 1000Genomes | |
| tmp_2_8598232_A_T | 468 | F>L | No | 1000Genomes | |
| tmp_2_8598231_G_A | 469 | L>F | No | 1000Genomes | |
| ENSVATH01848353 | 470 | T>I | No | 1000Genomes | |
| ENSVATH01848354 | 470 | T>S | No | 1000Genomes | |
| ENSVATH00239568 | 477 | R>Q | No | 1000Genomes | |
| tmp_2_8598114_G_A | 483 | P>L | No | 1000Genomes | |
| ENSVATH01848345 | 486 | I>M | No | 1000Genomes | |
| ENSVATH01848344 | 492 | R>Q | No | 1000Genomes | |
| tmp_2_8598079_A_G | 495 | S>P | No | 1000Genomes | |
| tmp_2_8598075_T_A | 496 | N>I | No | 1000Genomes | |
| ENSVATH14522808 | 511 | P>S | No | 1000Genomes | |
| ENSVATH05538049 | 513 | R>K | No | 1000Genomes | |
| ENSVATH09472445 | 514 | K>M | No | 1000Genomes | |
| ENSVATH09472444 | 515 | A>T | No | 1000Genomes | |
| ENSVATH05538048 | 516 | R>S | No | 1000Genomes | |
| ENSVATH07885280 | 531 | P>S | No | 1000Genomes | |
| ENSVATH01848338 | 536 | L>S | No | 1000Genomes | |
| ENSVATH05538042 | 538 | I>T | No | 1000Genomes | |
| ENSVATH01848337 | 540 | R>L | No | 1000Genomes | |
| ENSVATH07885279 | 541 | N>K | No | 1000Genomes | |
| ENSVATH01848336 | 544 | E>A | No | 1000Genomes | |
| ENSVATH01848336 | 544 | E>G | No | 1000Genomes | |
| ENSVATH01848335 | 547 | K>E | No | 1000Genomes | |
| ENSVATH01848334 | 552 | S>R | No | 1000Genomes | |
| ENSVATH01848325 | 583 | Y>D | No | 1000Genomes | |
| ENSVATH05538039 | 598 | A>V | No | 1000Genomes | |
| ENSVATH00239564 | 604 | F>Y | No | 1000Genomes | |
| ENSVATH01848320 | 626 | E>G | No | 1000Genomes | |
| ENSVATH01848314 | 632 | H>D | No | 1000Genomes | |
| ENSVATH00239563 | 632 | H>Q | No | 1000Genomes | |
| ENSVATH01848312 | 639 | D>N | No | 1000Genomes | |
| ENSVATH00239562 | 642 | V>G | No | 1000Genomes | |
| ENSVATH13290699 | 643 | Y>* | No | 1000Genomes | |
| tmp_2_8597229_A_T,C | 653 | I>K | No | 1000Genomes | |
| tmp_2_8597229_A_T,C | 653 | I>R | No | 1000Genomes | |
| ENSVATH01848304 | 662 | K>E | No | 1000Genomes | |
| ENSVATH01848303 | 671 | A>S | No | 1000Genomes | |
| ENSVATH01848302 | 673 | F>Y | No | 1000Genomes | |
| ENSVATH01848301 | 674 | A>V | No | 1000Genomes | |
| tmp_2_8597139_C_T | 683 | R>K | No | 1000Genomes | |
| ENSVATH13290697 | 686 | G>S | No | 1000Genomes | |
| tmp_2_8597125_C_T | 688 | E>K | No | 1000Genomes | |
| tmp_2_8597101_C_G | 696 | G>R | No | 1000Genomes | |
| ENSVATH01848297 | 701 | I>V | No | 1000Genomes | |
| tmp_2_8597069_C_G | 706 | K>N | No | 1000Genomes | |
| ENSVATH01848285 | 726 | I>V | No | 1000Genomes | |
| ENSVATH01848284 | 728 | C>S | No | 1000Genomes | |
| ENSVATH01848282 | 733 | S>N | No | 1000Genomes | |
| ENSVATH01848280 | 737 | E>Q | No | 1000Genomes | |
| ENSVATH01848278 | 747 | M>L | No | 1000Genomes | |
| ENSVATH01848277 | 750 | K>N | No | 1000Genomes | |
| ENSVATH05538030 | 754 | C>R | No | 1000Genomes | |
| ENSVATH07885238 | 755 | K>Q | No | 1000Genomes | |
| ENSVATH07885237 | 755 | K>T | No | 1000Genomes | |
| ENSVATH00239558 | 756 | R>S | No | 1000Genomes | |
| tmp_2_8596754_C_T | 757 | D>N | No | 1000Genomes | |
| ENSVATH00239557 | 765 | C>S | No | 1000Genomes | |
| ENSVATH01848266 | 765 | C>Y | No | 1000Genomes | |
| tmp_2_8596723_A_T | 767 | L>Q | No | 1000Genomes | |
| ENSVATH14522805 | 778 | D>N | No | 1000Genomes | |
| ENSVATH13290684 | 787 | R>S | No | 1000Genomes | |
| tmp_2_8596638_A_C | 795 | I>M | No | 1000Genomes | |
| ENSVATH14522784 | 798 | Y>N | No | 1000Genomes | |
| tmp_2_8596582_G_A | 814 | P>L | No | 1000Genomes | |
| tmp_2_8596573_A_T | 817 | L>Q | No | 1000Genomes | |
| ENSVATH00239555 | 832 | R>* | No | 1000Genomes | |
| ENSVATH05538027 | 853 | E>A | No | 1000Genomes | |
| ENSVATH05538020 | 864 | W>R | No | 1000Genomes | |
| ENSVATH05538019 | 864 | W>S | No | 1000Genomes | |
| ENSVATH05538018 | 865 | Y>C | No | 1000Genomes | |
| tmp_2_8596204_C_A | 909 | V>F | No | 1000Genomes | |
| ENSVATH01848238 | 927 | N>K | No | 1000Genomes | |
| ENSVATH09472383 | 949 | I>M | No | 1000Genomes | |
| ENSVATH00239553 | 957 | T>A | No | 1000Genomes | |
| tmp_2_8595924_C_T | 959 | A>T | No | 1000Genomes | |
| ENSVATH01848234 | 961 | N>K | No | 1000Genomes | |
| ENSVATH00239552 | 969 | K>R | No | 1000Genomes | |
| ENSVATH05538007 | 975 | T>A | No | 1000Genomes | |
| ENSVATH01848230 | 984 | T>M | No | 1000Genomes | |
| ENSVATH01848228 | 986 | V>M | No | 1000Genomes | |
| ENSVATH01848227 | 990 | L>F | No | 1000Genomes |
No associated diseases with O82190
Functions
| Description | ||
|---|---|---|
| EC Number | 2.7.7.48 | Nucleotidyltransferases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| nuclear RNA-directed RNA polymerase complex | A complex required for RNAi mediated heterochromatin assembly. In S. pombe this contains RNA-directed RNA polymerase, a putative helicase and a protein containing a pap25 associated domain. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| RNA binding | Binding to an RNA molecule or a portion thereof. |
| RNA-directed 5'-3' RNA polymerase activity | Catalysis of the reaction: nucleoside triphosphate + RNA(n) = diphosphate + RNA(n+1); uses an RNA template, i.e. the catalysis of RNA-template-directed extension of the 3'-end of an RNA strand by one nucleotide at a time. |
1 GO annotations of biological process
| Name | Definition |
|---|---|
| siRNA processing | A process leading to the generation of a functional small interfering RNA (siRNA). Includes the cleavage of double-stranded RNA to form small interfering RNA molecules (siRNAs) of 21-23 nucleotides. May also include amplification of the siRNA by RNA-directed RNA polymerase. |
3 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| O82188 | RDR5 | Probable RNA-dependent RNA polymerase 5 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| O82189 | RDR4 | Probable RNA-dependent RNA polymerase 4 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9SG02 | RDR6 | RNA-dependent RNA polymerase 6 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MMNNGCDEVS | PRSEIALLGS | VETMLEKIYE | KHNHRLPISV | ETRRKLSSIS | EELALETLRK |
| 70 | 80 | 90 | 100 | 110 | 120 |
| VFNKPYLKTL | DGLIMYFVKG | TVTVDGSPRL | SPGESPVQSP | RTPAKKSCRA | SQDVSLDLET |
| 130 | 140 | 150 | 160 | 170 | 180 |
| PSPKFMKREE | NGGSKYIPPL | LALGELEFKK | AFLLLSYIGG | ESLVEEVISG | DQIRKWKDLP |
| 190 | 200 | 210 | 220 | 230 | 240 |
| MVSYEAAVWN | RLGQRYCSPK | ERRRPLEGDS | GMTHYYQCHV | ATDGSYKFKG | HLLENTGTHL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| HKVLGDDNVL | TVKFDKVLGV | ETYCNDLYST | YKGIAKNGIM | VGLRRYRFFV | FKDGGKEEKK |
| 310 | 320 | 330 | 340 | 350 | 360 |
| KDVSTKGVKC | YFIRTDSTAS | IDMQNPYIFA | GKSMHEARMH | FMHVNTLSSL | PNYMSRFSLI |
| 370 | 380 | 390 | 400 | 410 | 420 |
| LSKTKTLEVD | MTGITFEQID | DIHCHDQDDK | DVLDKNGKPC | IHSDGTGYIS | EDLARMCPVN |
| 430 | 440 | 450 | 460 | 470 | 480 |
| IFKGKSMRSN | NIQSKNLNFE | GQGPCGQEPP | LLIQFRIFYN | GYAVKGTFLT | NKKLPPRTVQ |
| 490 | 500 | 510 | 520 | 530 | 540 |
| VRPSMIKVYE | DRTLSNLSTF | NSLEVVTTSN | PPRKARLSRN | LVALLSYGGV | PNDFFLNILR |
| 550 | 560 | 570 | 580 | 590 | 600 |
| NTLEESKTIF | YSERAAFKAA | INYGDDQYTA | DMILVGIPLD | EPYLKDRLSY | LLKTERNALK |
| 610 | 620 | 630 | 640 | 650 | 660 |
| AGRFPIDESY | YIMGTVDPTG | ELKENEICVI | LHSGQISGDV | LVYRNPGLHF | GDIHVLKATY |
| 670 | 680 | 690 | 700 | 710 | 720 |
| VKALEDYVGN | AKFAVFFPQK | GPRSLGDEIA | GGDFDGDMYF | ISRNPKLLEH | FKPSEPWVSS |
| 730 | 740 | 750 | 760 | 770 | 780 |
| SKPSKIYCGR | KPSELSEEEL | EEELFKMFLK | ARFCKRDVIG | MAADCWLGIM | DPFLTLGDES |
| 790 | 800 | 810 | 820 | 830 | 840 |
| AKEKYERKKN | ILKLIDIYYD | ALDAPKKGAK | VDLPPDLEIK | NFPHYMERDP | KRDFRSTSIL |
| 850 | 860 | 870 | 880 | 890 | 900 |
| GLIFDTVDSH | NAEEPPPSEI | SKLWYFEDEP | VPKSHMDKFT | SWYENYRSEM | SQAMMETDKV |
| 910 | 920 | 930 | 940 | 950 | 960 |
| KRNQLTNEVI | QRYKQDFYGA | AGFEDSNKSL | EELYPQALAL | YNVVYDYAIQ | EGVAKCTFAW |
| 970 | 980 | 990 | |||
| NVAGPVLCKF | YLKKTKDKSV | VASTSVLKKL | LG |