Q9NXR8
Gene name |
ING3 (HSPC301) |
Protein name |
Inhibitor of growth protein 3 |
Names |
p47ING3 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:54556 |
EC number |
|
Protein Class |
|
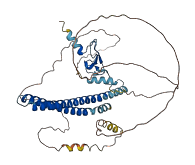
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
3 structures for Q9NXR8
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1X4I | NMR | - | A | 362-418 | PDB |
| 7ZMX | X-ray | 120 A | A/B | 358-411 | PDB |
| AF-Q9NXR8-F1 | Predicted | AlphaFoldDB |
206 variants for Q9NXR8
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| VAR_021263 | 20 | D>G | HNSCC [UniProt] | Yes | UniProt |
|
rs1461735101 CA369134798 |
3 | Y>H | No |
ClinGen TOPMed |
|
| TCGA novel | 4 | L>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs4440563 CA165851904 |
6 | D>N | No |
ClinGen Ensembl |
|
|
CA4454064 rs775974967 |
7 | Y>S | No |
ClinGen ExAC gnomAD |
|
|
CA4454066 rs764656224 |
9 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs1332996963 CA369134859 |
10 | M>K | No |
ClinGen gnomAD |
|
|
rs780962589 CA4454099 |
11 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4454102 CA4454103 rs780341286 |
16 | M>I | No |
ClinGen ExAC gnomAD |
|
|
CA369134899 rs756138808 |
16 | M>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs756138808 CA4454101 |
16 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4454104 rs769040781 |
17 | D>A | No |
ClinGen ExAC gnomAD |
|
|
CA4454107 rs772673743 |
23 | T>M | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 25 | M>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs201054245 CA4454108 |
25 | M>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
| TCGA novel | 27 | E>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4454109 rs759143530 |
28 | M>T | No |
ClinGen ExAC gnomAD |
|
|
CA4454110 COSM1312604 rs769127768 |
29 | D>N | Variant assessed as Somatic; 0.0 impact. urinary_tract [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs1220186021 CA369135048 |
36 | M>V | No |
ClinGen TOPMed gnomAD |
|
|
rs765499968 CA4454143 |
38 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
rs755044036 CA4454142 |
38 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
rs1408622289 CA369135084 |
41 | Q>K | No |
ClinGen TOPMed |
|
|
CA369135088 rs1348574955 |
41 | Q>L | No |
ClinGen TOPMed |
|
| TCGA novel | 42 | R>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs777955673 CA4454146 |
43 | V>L | No |
ClinGen ExAC gnomAD |
|
|
CA4454147 rs747570865 |
45 | E>Q | No |
ClinGen ExAC |
|
|
rs1213812067 CA369135140 |
48 | M>I | No |
ClinGen gnomAD |
|
|
CA165852168 rs867738371 |
51 | K>R | No |
ClinGen Ensembl |
|
|
CA4454148 rs757750682 |
53 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA369135184 rs1201234170 |
54 | K>I | No |
ClinGen gnomAD |
|
|
CA4454149 rs150115417 |
55 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1174278261 CA369135211 |
58 | R>K | No |
ClinGen TOPMed |
|
|
CA4454151 rs768225061 |
60 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs747714856 CA4454153 |
62 | M>I | No |
ClinGen ExAC gnomAD |
|
|
CA4454154 rs771928223 |
63 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA4454155 rs772933794 |
65 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 68 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4454166 rs769542101 |
70 | Y>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA369135624 rs1358425936 |
71 | K>R | No |
ClinGen TOPMed |
|
|
rs1005112662 CA165852417 |
78 | E>D | No |
ClinGen gnomAD |
|
|
rs867875232 CA165852418 |
83 | A>E | No |
ClinGen Ensembl |
|
|
rs1419837407 CA369137135 |
92 | R>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA4454204 rs775492387 |
99 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
CA369137185 rs1388103074 |
99 | Q>R | No |
ClinGen gnomAD |
|
|
CA4454205 rs749343034 |
101 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs768716282 CA4454206 |
103 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs1231806217 COSM4155386 CA369137221 |
104 | F>L | kidney [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs1316215369 CA369137227 |
105 | K>R | No |
ClinGen TOPMed |
|
|
rs1311451465 CA369137233 |
106 | M>V | No |
ClinGen gnomAD |
|
|
rs774468293 CA4454207 |
109 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs762077982 CA4454208 |
111 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA165853458 rs985386218 |
111 | D>N | No |
ClinGen Ensembl |
|
|
CA369137304 rs1260173898 COSM1662276 |
113 | A>S | kidney [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs767834668 CA4454209 |
114 | G>E | No |
ClinGen ExAC gnomAD |
|
|
CA4454210 rs773755720 |
115 | I>S | No |
ClinGen ExAC gnomAD |
|
|
rs1268273338 CA369137328 |
116 | T>A | No |
ClinGen gnomAD |
|
|
CA369137356 rs1192130261 |
118 | I>M | No |
ClinGen gnomAD |
|
|
CA4454226 rs772493489 |
125 | E>K | No |
ClinGen ExAC |
|
|
rs1416724046 CA369137778 |
126 | L>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1193501935 CA369137784 |
127 | D>H | No |
ClinGen TOPMed |
|
| TCGA novel | 127 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA369137795 rs1459514654 |
128 | T>I | No |
ClinGen gnomAD |
|
|
rs1584993136 CA369137790 |
128 | T>P | No |
ClinGen Ensembl |
|
|
rs200821423 CA165853637 |
130 | S>P | No |
ClinGen Ensembl |
|
|
CA4454229 rs766698072 |
131 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
rs1418157512 CA369137846 |
136 | H>R | No |
ClinGen gnomAD |
|
|
CA369137854 rs1381234660 |
137 | H>R | No |
ClinGen gnomAD |
|
|
rs760036711 CA4454231 |
138 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs1355096295 CA369137864 |
139 | H>D | No |
ClinGen gnomAD |
|
|
CA369137886 rs1231741074 |
142 | T>A | No |
ClinGen gnomAD |
|
|
rs1562976054 CA369137892 |
143 | P>A | No |
ClinGen Ensembl |
|
|
rs113738109 CA165853724 |
148 | K>R | No |
ClinGen Ensembl |
|
|
rs1280201982 CA369138009 |
151 | P>A | No |
ClinGen gnomAD |
|
| TCGA novel | 151 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs771218708 CA4454246 |
152 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA369138039 rs1263470015 |
153 | S>F | No |
ClinGen gnomAD |
|
|
CA4454247 rs201298392 |
154 | H>N | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA369138055 rs1184593183 |
155 | H>D | No |
ClinGen gnomAD |
|
|
rs759788131 CA4454248 |
155 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4454249 rs199888903 |
156 | T>M | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs761324262 CA4454251 |
158 | T>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA369138084 rs1584993567 |
158 | T>P | No |
ClinGen Ensembl |
|
|
rs766975352 CA369138102 |
159 | D>G | No |
ClinGen ExAC gnomAD |
|
|
rs766975352 CA4454252 |
159 | D>V | No |
ClinGen ExAC gnomAD |
|
|
CA4454253 rs750100465 |
160 | H>L | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 164 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA369138207 rs1372958359 |
170 | A>V | No |
ClinGen TOPMed |
|
|
rs1562976360 CA369138243 |
174 | T>A | No |
ClinGen Ensembl |
|
|
rs753736819 CA369138278 |
176 | T>M | No |
ClinGen ExAC gnomAD |
|
|
rs753736819 CA4454256 |
176 | T>R | No |
ClinGen ExAC gnomAD |
|
|
CA4454258 rs779009828 |
177 | S>L | No |
ClinGen ExAC gnomAD |
|
|
rs1346268711 CA369138283 |
177 | S>P | No |
ClinGen gnomAD |
|
|
CA4454259 rs752617786 |
180 | S>P | No |
ClinGen ExAC gnomAD |
|
|
rs3180313 CA165853725 |
182 | E>G | No |
ClinGen Ensembl |
|
|
rs200902834 CA165853726 |
184 | T>S | No |
ClinGen Ensembl |
|
|
rs1221560654 CA369138381 |
187 | C>F | No |
ClinGen gnomAD |
|
|
rs908317865 CA165853746 |
188 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA369138419 rs1458911813 |
193 | T>P | No |
ClinGen gnomAD |
|
|
rs772819242 CA4454273 |
194 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA369138441 rs1584993728 |
196 | S>C | No |
ClinGen Ensembl |
|
|
CA165853748 rs938680740 |
198 | N>D | No |
ClinGen TOPMed gnomAD |
|
|
rs1416234768 CA369138455 |
198 | N>K | No |
ClinGen TOPMed gnomAD |
|
|
CA4454275 rs766117424 COSM744879 |
198 | N>S | lung liver [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
CA369138467 rs1462125454 |
200 | Y>C | No |
ClinGen gnomAD |
|
|
rs972793610 CA165853749 |
201 | N>D | No |
ClinGen TOPMed |
|
|
CA4454277 rs759383329 |
201 | N>T | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 202 | V>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1467507318 CA369138484 |
203 | N>Y | No |
ClinGen gnomAD |
|
|
CA369138495 rs1330215639 |
204 | S>C | No |
ClinGen gnomAD |
|
|
CA369138500 rs1335629427 |
205 | S>F | No |
ClinGen gnomAD |
|
| TCGA novel | 206 | Q>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1285412842 CA369138513 |
207 | P>H | No |
ClinGen gnomAD |
|
|
rs201788608 CA165853751 |
208 | L>M | No |
ClinGen 1000Genomes ExAC |
|
|
rs201788608 CA4454279 |
208 | L>V | No |
ClinGen 1000Genomes ExAC |
|
|
CA369138529 rs1355725270 |
210 | S>F | No |
ClinGen gnomAD |
|
|
CA4454280 rs200304406 |
215 | S>L | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs919600444 CA165853754 |
215 | S>P | No |
ClinGen gnomAD |
|
|
CA369138563 rs200304406 |
215 | S>W | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA4454282 rs751727977 |
217 | S>P | No |
ClinGen ExAC gnomAD |
|
|
CA369138580 rs1272214995 |
218 | S>L | No |
ClinGen gnomAD |
|
|
rs201712063 CA165853755 |
218 | S>T | No |
ClinGen Ensembl |
|
|
CA369138595 rs1259644829 |
221 | G>C | No |
ClinGen gnomAD |
|
|
CA4454285 rs144315352 |
222 | A>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1415938665 CA369138616 |
225 | I>L | No |
ClinGen TOPMed gnomAD |
|
|
CA369138650 rs1185357794 |
230 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs369051259 CA165853758 |
232 | A>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs369051259 CA4454286 |
232 | A>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA4454288 rs544861013 |
237 | A>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs760410824 CA165853759 |
238 | Q>L | No |
ClinGen Ensembl |
|
|
rs1433571423 CA369138945 COSM1084549 |
243 | R>Q | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
CA4454307 rs749714240 |
245 | T>S | No |
ClinGen ExAC gnomAD |
|
|
rs1211143821 CA369139042 |
247 | S>N | No |
ClinGen TOPMed |
|
|
CA4454309 rs779481523 |
255 | F>C | No |
ClinGen ExAC gnomAD |
|
|
CA4454310 rs748565699 |
256 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs776051200 CA4454312 |
257 | N>K | No |
ClinGen ExAC gnomAD |
|
|
rs756187407 CA4454311 |
257 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4454313 rs745335917 |
258 | N>I | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 259 | D>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1338386869 CA369139373 |
261 | Q>K | No |
ClinGen TOPMed |
|
| TCGA novel | 261 | Q>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA369139407 rs1584994355 |
262 | L>F | No |
ClinGen Ensembl |
|
|
CA165853854 rs1018252472 |
264 | K>E | No |
ClinGen TOPMed |
|
|
rs763727104 CA4454317 |
268 | M>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs762854929 CA4454316 |
268 | M>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 270 | R>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs750568317 CA4454322 |
274 | G>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs750568317 CA4454321 |
274 | G>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA165853857 rs1006647546 |
278 | S>P | No |
ClinGen Ensembl |
|
|
rs753997717 CA4454324 |
279 | S>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA4454326 rs200011060 |
282 | M>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA165853858 rs956892697 |
283 | T>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1584994382 CA369139686 |
284 | T>A | No |
ClinGen Ensembl |
|
|
CA4454328 rs758866749 |
289 | A>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4454327 rs753080716 |
289 | A>S | No |
ClinGen ExAC gnomAD |
|
|
CA4454330 rs745425792 |
292 | S>L | No |
ClinGen ExAC gnomAD |
|
|
rs769371186 CA369139771 |
293 | A>P | No |
ClinGen ExAC gnomAD |
|
|
rs769371186 CA4454331 |
293 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA369139782 rs1246290036 |
294 | A>P | No |
ClinGen TOPMed |
|
| TCGA novel | 294 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 295 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs768333923 CA4454334 |
297 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA4454333 rs748907453 |
297 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs761664024 CA4454336 |
298 | S>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs866714436 CA165853862 |
300 | R>Q | No |
ClinGen gnomAD |
|
|
rs1305007588 CA369139871 |
302 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
CA369139881 rs1246272938 |
303 | K>R | No |
ClinGen TOPMed |
|
|
CA165854026 rs374432546 |
305 | N>K | No |
ClinGen ESP TOPMed |
|
|
CA4454357 rs760561603 |
306 | N>K | No |
ClinGen ExAC gnomAD |
|
|
rs1355077682 CA369140167 |
308 | S>A | No |
ClinGen gnomAD |
|
|
CA4454359 rs776728234 |
308 | S>C | No |
ClinGen ExAC gnomAD |
|
|
rs1016519986 CA165854029 |
315 | S>Y | No |
ClinGen TOPMed |
|
|
rs1429154500 CA369140255 |
317 | S>T | No |
ClinGen TOPMed |
|
|
rs1434392681 CA369140269 |
318 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
rs1416696277 CA369140296 |
320 | S>F | No |
ClinGen gnomAD |
|
|
CA369140324 rs1194191883 |
323 | S>P | No |
ClinGen TOPMed gnomAD |
|
|
CA369140322 rs1194191883 COSM1666235 |
323 | S>T | eye [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
CA4454364 rs367657969 |
324 | S>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA369140342 rs1450710206 |
325 | C>S | No |
ClinGen Ensembl |
|
|
CA4454366 rs372931331 |
326 | S>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA369140435 rs1484465223 |
333 | Q>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1484465223 CA369140433 |
333 | Q>P | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 334 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1188075254 CA369140441 |
334 | E>K | No |
ClinGen gnomAD |
|
|
CA4454371 rs547908706 |
335 | I>F | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA4454370 rs547908706 |
335 | I>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA4454372 rs201574570 |
337 | Q>H | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1396798395 CA369140503 |
339 | T>K | No |
ClinGen gnomAD |
|
|
CA4454374 rs747799457 |
342 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs139642346 CA4454375 |
348 | N>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1375093160 CA369140602 |
348 | N>S | No |
ClinGen gnomAD |
|
|
rs1290820242 CA369140654 |
354 | T>I | No |
ClinGen gnomAD |
|
| TCGA novel | 359 | E>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA165854249 rs773573180 |
368 | V>I | No |
ClinGen Ensembl |
|
| TCGA novel | 376 | C>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA369140849 rs1409021353 |
379 | Q>H | No |
ClinGen gnomAD |
|
| TCGA novel | 379 | Q>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4454409 rs761297921 |
383 | I>M | No |
ClinGen ExAC gnomAD |
|
|
rs201955164 CA4454410 |
390 | C>W | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs762432484 CA4454412 |
391 | V>G | No |
ClinGen ExAC gnomAD |
|
|
rs369549499 CA4454414 |
398 | K>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs267601248 CA165854405 |
401 | W>S | No |
ClinGen Ensembl |
|
|
CA369141036 rs1562978522 |
404 | P>A | No |
ClinGen Ensembl |
|
|
CA4454418 rs756116032 |
409 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs1584996863 CA369141107 |
414 | G>S | No |
ClinGen Ensembl |
|
|
rs749392825 CA4454420 |
415 | S>G | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 418 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
1 associated diseases with Q9NXR8
[MIM: 275355]: Squamous cell carcinoma of the head and neck (HNSCC)
A non-melanoma skin cancer affecting the head and neck. The hallmark of cutaneous SCC is malignant transformation of normal epidermal keratinocytes. {ECO:0000269|PubMed:12080476}. Note=The disease may be caused by variants affecting the gene represented in this entry.
Without disease ID
- A non-melanoma skin cancer affecting the head and neck. The hallmark of cutaneous SCC is malignant transformation of normal epidermal keratinocytes. {ECO:0000269|PubMed:12080476}. Note=The disease may be caused by variants affecting the gene represented in this entry.
5 regional properties for Q9NXR8
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Zinc finger, PHD-type | 362 - 407 | IPR001965 |
| conserved_site | Zinc finger, PHD-type, conserved site | 363 - 406 | IPR019786 |
| domain | Zinc finger, PHD-finger | 360 - 409 | IPR019787 |
| domain | Inhibitor of growth protein, N-terminal histone-binding | 3 - 104 | IPR024610 |
| domain | ING3, PHD domain | 362 - 406 | IPR042020 |
6 GO annotations of cellular component
| Name | Definition |
|---|---|
| NuA4 histone acetyltransferase complex | A complex having histone acetylase activity on chromatin, as well as ATPase, DNA helicase and structural DNA binding activities. The complex is thought to be involved in double-strand DNA break repair. Subunits of the human complex include HTATIP/TIP60, TRRAP, RUVBL1, BUVBL2, beta-actin and BAF53/ACTL6A. In yeast, the complex has 13 subunits, including the catalytic subunit Esa1 (homologous to human Tip60). |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleosome | A complex comprised of DNA wound around a multisubunit core and associated proteins, which forms the primary packing unit of DNA into higher order structures. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| Piccolo NuA4 histone acetyltransferase complex | A heterotrimeric H4/H2A histone acetyltransferase complex with a substrate preference of chromatin over free histones. It contains a subset of the proteins found in the larger NuA4 histone acetyltransferase complex; for example, the S. cerevisiae complex contains Esa1p, Yng2p, and Epl1p. |
| Swr1 complex | A multisubunit protein complex that is involved in chromatin remodeling. It is required for the incorporation of the histone variant H2AZ into chromatin. In S. cerevisiae, the complex contains Swr1p, a Swi2/Snf2-related ATPase, and 12 additional subunits. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| metal ion binding | Binding to a metal ion. |
| methylated histone binding | Binding to a histone in which a residue has been modified by methylation. |
11 GO annotations of biological process
| Name | Definition |
|---|---|
| chromatin organization | The assembly or remodeling of chromatin composed of DNA complexed with histones, other associated proteins, and sometimes RNA. |
| histone acetylation | The modification of a histone by the addition of an acetyl group. |
| histone H2A acetylation | The modification of histone H2A by the addition of an acetyl group. |
| histone H4 acetylation | The modification of histone H4 by the addition of an acetyl group. |
| positive regulation of apoptotic process | Any process that activates or increases the frequency, rate or extent of cell death by apoptotic process. |
| positive regulation of DNA-templated transcription | Any process that activates or increases the frequency, rate or extent of cellular DNA-templated transcription. |
| positive regulation of double-strand break repair via homologous recombination | Any process that activates or increases the frequency, rate or extent of double-strand break repair via homologous recombination. |
| regulation of apoptotic process | Any process that modulates the occurrence or rate of cell death by apoptotic process. |
| regulation of cell cycle | Any process that modulates the rate or extent of progression through the cell cycle. |
| regulation of DNA-templated transcription | Any process that modulates the frequency, rate or extent of cellular DNA-templated transcription. |
| regulation of double-strand break repair | Any process that modulates the frequency, rate or extent of double-strand break repair. |
3 homologous proteins in AiPD
| 10 | 20 | 30 | 40 | 50 | 60 |
| MLYLEDYLEM | IEQLPMDLRD | RFTEMREMDL | QVQNAMDQLE | QRVSEFFMNA | KKNKPEWREE |
| 70 | 80 | 90 | 100 | 110 | 120 |
| QMASIKKDYY | KALEDADEKV | QLANQIYDLV | DRHLRKLDQE | LAKFKMELEA | DNAGITEILE |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RRSLELDTPS | QPVNNHHAHS | HTPVEKRKYN | PTSHHTTTDH | IPEKKFKSEA | LLSTLTSDAS |
| 190 | 200 | 210 | 220 | 230 | 240 |
| KENTLGCRNN | NSTASSNNAY | NVNSSQPLGS | YNIGSLSSGT | GAGAITMAAA | QAVQATAQMK |
| 250 | 260 | 270 | 280 | 290 | 300 |
| EGRRTSSLKA | SYEAFKNNDF | QLGKEFSMAR | ETVGYSSSSA | LMTTLTQNAS | SSAADSRSGR |
| 310 | 320 | 330 | 340 | 350 | 360 |
| KSKNNNKSSS | QQSSSSSSSS | SLSSCSSSST | VVQEISQQTT | VVPESDSNSQ | VDWTYDPNEP |
| 370 | 380 | 390 | 400 | 410 | |
| RYCICNQVSY | GEMVGCDNQD | CPIEWFHYGC | VGLTEAPKGK | WYCPQCTAAM | KRRGSRHK |