Q8N2W9
Gene name |
PIAS4 |
Protein name |
E3 SUMO-protein ligase PIAS4 |
Names |
PIASy, Protein inhibitor of activated STAT protein 4, Protein inhibitor of activated STAT protein gamma, PIAS-gamma |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:51588 |
EC number |
2.3.2.27: Aminoacyltransferases |
Protein Class |
|
Descriptions
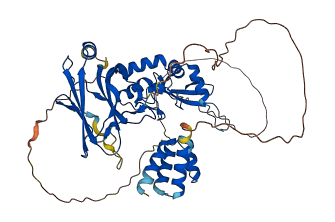
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q8N2W9
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q8N2W9-F1 | Predicted | AlphaFoldDB |
350 variants for Q8N2W9
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs1282649151 CA403358280 |
3 | A>T | No |
ClinGen gnomAD |
|
|
rs1329960249 CA403358365 |
8 | A>T | No |
ClinGen gnomAD |
|
| TCGA novel | 12 | V>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA403360550 rs1245443721 |
14 | S>N | No |
ClinGen gnomAD |
|
|
CA403360701 rs1250182612 |
22 | M>I | No |
ClinGen gnomAD |
|
|
rs1211879153 CA403360692 |
22 | M>K | No |
ClinGen gnomAD |
|
|
CA9089654 rs374253879 |
27 | V>M | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1295890139 CA403360780 |
29 | R>G | No |
ClinGen TOPMed |
|
|
rs760589223 CA9089655 |
29 | R>Q | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 30 | S>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA403360916 rs141222368 |
36 | H>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs778494339 CA9089659 |
37 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA9089661 rs758037993 |
39 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9089663 rs747350292 |
53 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA403361278 rs1396385714 |
53 | E>Q | No |
ClinGen gnomAD |
|
|
CA403361330 rs1435055319 |
55 | F>L | No |
ClinGen TOPMed |
|
|
CA403361421 rs1329882781 |
59 | K>R | No |
ClinGen gnomAD |
|
|
rs769704640 CA9089667 |
63 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA403361494 rs1599215220 |
64 | T>P | No |
ClinGen Ensembl |
|
|
CA9089670 rs553988056 |
67 | A>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9089669 rs553988056 |
67 | A>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9089671 rs774765388 |
68 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403361590 rs1599215244 |
70 | N>T | No |
ClinGen Ensembl |
|
|
CA9089672 rs758152481 |
71 | S>L | No |
ClinGen ExAC gnomAD |
|
|
CA403361626 rs1599215263 |
72 | E>D | No |
ClinGen Ensembl |
|
|
CA9089674 rs753654253 |
73 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA403361648 rs1158975672 |
74 | A>P | No |
ClinGen gnomAD |
|
| TCGA novel | 74 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA304431208 rs914947553 |
75 | P>S | No |
ClinGen TOPMed |
|
|
rs142623244 CA9089677 |
77 | P>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA403361740 rs1227290825 |
78 | H>Q | No |
ClinGen TOPMed |
|
|
CA9089679 rs369731508 |
78 | H>Y | No |
ClinGen ESP ExAC gnomAD |
|
|
rs755230248 CA9089681 |
79 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
CA9089680 rs751242393 |
79 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs977840261 CA304431220 |
80 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
CA403361756 rs1290203666 |
80 | P>T | No |
ClinGen TOPMed |
|
|
CA403361781 rs1305206223 |
82 | D>G | No |
ClinGen gnomAD |
|
|
rs778466049 CA9089685 |
83 | P>R | No |
ClinGen ExAC gnomAD |
|
|
rs756641652 CA9089684 |
83 | P>T | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 84 | L>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA304431229 rs955710543 |
84 | L>M | No |
ClinGen TOPMed |
|
|
CA403361804 rs955710543 |
84 | L>V | No |
ClinGen TOPMed |
|
|
rs771160224 CA9089687 |
85 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA403361825 rs1021533044 |
85 | T>N | No |
ClinGen TOPMed gnomAD |
|
|
CA304431234 rs1021533044 |
85 | T>S | No |
ClinGen TOPMed gnomAD |
|
|
rs146034709 CA9089689 |
86 | M>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA403361848 rs1415632114 |
86 | M>T | No |
ClinGen gnomAD |
|
|
rs1324632961 CA403361836 |
86 | M>V | No |
ClinGen Ensembl |
|
|
CA9089690 rs768281556 |
87 | H>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403361918 rs1174862710 |
89 | T>P | No |
ClinGen gnomAD |
|
|
CA304431240 rs889712236 |
90 | Y>F | No |
ClinGen TOPMed gnomAD |
|
|
rs1599215402 CA403361973 |
91 | D>A | No |
ClinGen Ensembl |
|
| TCGA novel | 91 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs370475096 CA9089694 |
91 | D>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs200574015 CA9089696 |
92 | R>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA9089695 rs754930081 |
92 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs754645720 CA9089698 |
94 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA403362053 rs577156557 |
95 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs577156557 CA9089700 |
95 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA403362068 rs1599215420 |
96 | V>L | No |
ClinGen Ensembl |
|
|
CA9089701 rs756486400 |
97 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA403362079 rs1346248232 |
97 | P>T | No |
ClinGen gnomAD |
|
|
rs1276032004 CA403362088 |
98 | R>G | No |
ClinGen gnomAD |
|
|
rs994819976 CA304431255 |
98 | R>S | No |
ClinGen TOPMed |
|
|
CA9089702 rs778378130 |
98 | R>T | No |
ClinGen ExAC gnomAD |
|
|
rs1194110100 CA403362110 |
99 | T>S | No |
ClinGen TOPMed gnomAD |
|
|
CA9089704 rs2289867 |
100 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA304431260 rs2289867 |
100 | P>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA304431269 rs943597496 |
102 | A>T | No |
ClinGen Ensembl |
|
|
rs1190280045 CA403362138 |
102 | A>V | No |
ClinGen gnomAD |
|
|
CA403362152 rs1250752212 |
103 | G>S | No |
ClinGen gnomAD |
|
|
rs1451165789 CA403362178 |
104 | P>T | No |
ClinGen gnomAD |
|
|
CA9089708 rs775620072 |
106 | I>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 107 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA403362275 rs1599215493 |
108 | Y>S | No |
ClinGen Ensembl |
|
|
rs773065787 CA9089711 |
110 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA403362310 rs769605924 CA9089710 |
110 | V>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs769605924 COSM996406 CA304431284 |
110 | V>M | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA9089712 rs762889908 |
111 | L>P | No |
ClinGen ExAC gnomAD |
|
|
rs773727077 CA304431299 |
115 | Y>C | No |
ClinGen Ensembl |
|
|
CA403362451 rs1213343758 |
116 | L>F | No |
ClinGen gnomAD |
|
|
rs759009184 CA9089715 CA403362475 |
118 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA9089717 rs752315957 |
121 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1270939479 CA403362521 |
121 | R>W | No |
ClinGen gnomAD |
|
|
rs1188758491 CA403362539 |
122 | L>F | No |
ClinGen TOPMed gnomAD |
|
|
rs1247209233 CA403362561 |
123 | P>R | No |
ClinGen TOPMed gnomAD |
|
|
rs111928159 CA9089719 |
124 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
COSM439483 rs111928159 CA304431317 |
124 | A>T | Variant assessed as Somatic; 0.0 impact. breast [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA9089720 rs754342767 |
125 | K>E | No |
ClinGen ExAC gnomAD |
|
|
CA304431324 rs905505157 |
126 | T>I | No |
ClinGen Ensembl |
|
|
CA9089722 rs148740518 |
128 | K>M | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs373529709 CA9089723 |
129 | P>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9089724 rs376431812 |
132 | R>C | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA9089725 rs370857173 |
132 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs777529629 CA9089728 |
134 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA403362776 rs1429059576 |
134 | V>L | No |
ClinGen gnomAD |
|
|
rs749121993 CA9089729 |
135 | K>N | No |
ClinGen ExAC gnomAD |
|
|
rs759027208 CA9089732 |
140 | N>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs150447524 CA9089733 |
141 | M>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA9089734 rs775165266 |
142 | L>M | No |
ClinGen ExAC gnomAD |
|
|
rs1445123107 CA403362929 |
143 | D>N | No |
ClinGen gnomAD |
|
|
CA403362960 rs1324101273 |
145 | L>V | No |
ClinGen TOPMed |
|
|
CA403363024 rs1165580590 |
149 | T>I | No |
ClinGen TOPMed |
|
|
CA403363018 rs1185642644 |
149 | T>S | No |
ClinGen gnomAD |
|
|
CA9089739 rs765784737 |
150 | E>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs1341045782 CA403367265 |
153 | P>S | No |
ClinGen TOPMed |
|
|
CA403367357 rs1208981777 |
156 | N>K | No |
ClinGen TOPMed gnomAD |
|
|
rs746464624 CA9089769 |
157 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs768290359 CA9089770 |
163 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs773419050 CA9089774 |
164 | C>F | No |
ClinGen ExAC gnomAD |
|
|
rs769537741 CA9089773 |
164 | C>R | No |
ClinGen ExAC gnomAD |
|
|
rs774851982 CA9089777 |
167 | A>E | No |
ClinGen ExAC gnomAD |
|
|
CA403367598 rs766783529 |
167 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs766783529 CA403367601 |
167 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9089776 rs766783529 |
167 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1393692484 COSM349585 CA403367760 |
174 | E>Q | lung [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA304439044 rs1040803145 |
177 | R>Q | No |
ClinGen TOPMed |
|
|
CA9089779 rs377305529 |
178 | N>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1452722630 CA403367880 |
180 | R>G | No |
ClinGen TOPMed |
|
|
rs1260314525 CA403369978 |
182 | L>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1189208747 CA403370064 |
183 | Q>H | No |
ClinGen gnomAD |
|
|
rs749000055 CA9089811 |
183 | Q>L | No |
ClinGen ExAC gnomAD |
|
|
rs771151053 CA403370070 |
184 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA9089812 rs771151053 |
184 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA9089813 rs779225437 |
185 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA9089815 rs571784826 |
189 | V>M | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1476361839 CA403370354 |
191 | V>A | No |
ClinGen TOPMed |
|
|
rs1396546893 CA403370365 |
192 | V>I | No |
ClinGen TOPMed gnomAD |
|
|
rs1354973324 CA403370440 |
193 | L>Q | No |
ClinGen gnomAD |
|
|
rs1313260537 CA403370736 |
195 | I>V | No |
ClinGen gnomAD |
|
|
rs1461541275 CA403370767 |
196 | C>Y | No |
ClinGen gnomAD |
|
|
CA403370779 rs1296727365 |
197 | Y>N | No |
ClinGen gnomAD |
|
|
rs1019470589 CA304441213 |
202 | C>F | No |
ClinGen Ensembl |
|
|
rs1231262052 CA403370909 |
202 | C>S | No |
ClinGen gnomAD |
|
|
rs750110815 CA9089850 |
203 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1599227663 CA403371115 |
208 | Y>S | No |
ClinGen Ensembl |
|
|
rs1247938019 CA403371140 |
210 | P>S | No |
ClinGen TOPMed |
|
|
rs528479610 CA9089853 |
211 | N>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9089855 rs200867700 |
212 | I>M | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA9089856 rs748181758 |
213 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs748181758 CA403371211 |
213 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs1451030811 CA403371261 |
215 | K>R | No |
ClinGen gnomAD |
|
|
rs1418692040 CA403371318 |
218 | H>R | No |
ClinGen gnomAD |
|
| TCGA novel | 219 | S>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA403371356 rs1428048271 |
220 | Y>C | No |
ClinGen gnomAD |
|
|
rs141113403 CA9089859 |
223 | V>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9089860 rs771106134 |
224 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9089861 rs775323057 |
224 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403371630 rs1599227882 |
227 | Y>S | No |
ClinGen Ensembl |
|
|
rs770378756 CA9089905 |
230 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9089909 rs753106051 |
233 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs761178452 CA403371835 |
235 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs764634633 CA9089911 |
238 | R>K | No |
ClinGen ExAC gnomAD |
|
|
CA9089913 rs757315532 |
241 | R>C | No |
ClinGen ExAC gnomAD |
|
|
rs977215281 CA304441392 |
241 | R>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
| TCGA novel | 242 | P>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs973316079 CA304441396 |
243 | I>V | No |
ClinGen Ensembl |
|
|
rs778839305 CA9089914 |
244 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs778839305 CA403372025 |
244 | N>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403372089 rs1451079873 |
246 | T>N | No |
ClinGen TOPMed |
|
|
CA403372125 rs145838130 |
247 | H>Q | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1195857562 CA403372145 |
248 | L>F | No |
ClinGen TOPMed gnomAD |
|
|
rs747881688 CA9089918 COSM996420 |
248 | L>P | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
rs931086465 CA304441406 |
249 | M>I | No |
ClinGen Ensembl |
|
|
rs910948410 CA304441411 |
253 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
rs777650005 CA9089920 |
253 | S>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9089922 rs770949260 |
254 | A>D | No |
ClinGen ExAC gnomAD |
|
|
rs200365509 CA9089921 |
254 | A>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA403372292 rs1369901709 |
255 | T>A | No |
ClinGen gnomAD |
|
|
CA403372302 rs1231999279 |
255 | T>I | No |
ClinGen gnomAD |
|
|
CA403372327 rs1341636831 |
257 | R>C | No |
ClinGen TOPMed gnomAD |
|
|
rs773701146 CA9089923 |
257 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1303082695 CA403372336 |
258 | I>F | No |
ClinGen TOPMed |
|
|
CA304441417 rs1040676979 |
259 | T>I | No |
ClinGen Ensembl |
|
|
CA9089924 rs745450084 |
260 | V>L | No |
ClinGen ExAC |
|
|
CA403372530 rs1395753806 |
266 | G>S | No |
ClinGen TOPMed |
|
|
rs1475476869 CA403372558 |
267 | K>Q | No |
ClinGen gnomAD |
|
|
rs1364169867 CA403372752 |
268 | S>N | No |
ClinGen gnomAD |
|
| TCGA novel | 270 | S>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA9089965 rs376010709 |
271 | V>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9089966 rs137864303 |
276 | V>M | No |
ClinGen ESP ExAC gnomAD |
|
|
rs531098682 CA9089968 |
277 | R>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs748398070 COSM1680525 CA9089967 |
277 | R>W | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
CA403372970 rs1238753773 |
280 | T>S | No |
ClinGen gnomAD |
|
|
rs1336786207 CA403372964 |
280 | T>S | No |
ClinGen gnomAD |
|
|
rs1350726446 CA403372978 |
281 | S>P | No |
ClinGen gnomAD |
|
|
CA9089972 rs774408856 |
282 | S>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1178634658 CA403373046 |
285 | L>M | No |
ClinGen gnomAD |
|
|
CA9089974 rs767577652 |
286 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
CA403373104 rs1418321960 |
288 | L>V | No |
ClinGen gnomAD |
|
|
rs142374202 CA403373150 |
291 | I>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs142374202 CA9089977 |
291 | I>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs761472167 CA9089976 |
291 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA304441509 rs954803175 |
293 | V>I | No |
ClinGen TOPMed |
|
|
rs758377090 CA403373213 |
295 | H>P | No |
ClinGen ExAC gnomAD |
|
|
rs758377090 CA9089979 |
295 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs751060174 CA9089981 COSM1239835 |
296 | P>L | oesophagus [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
| TCGA novel | 299 | C>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 301 | A>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 303 | V>= | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA9090019 rs755590949 |
304 | K>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9090020 rs763668743 |
304 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs753520939 CA9090021 |
308 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1241436975 CA403374966 |
308 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs779223440 CA403375054 |
313 | S>R | No |
ClinGen ExAC gnomAD |
|
|
CA403375074 rs1375709575 |
315 | I>V | No |
ClinGen TOPMed |
|
|
CA403375086 rs1383574890 |
316 | A>T | No |
ClinGen TOPMed |
|
|
CA403375102 rs1599231734 |
317 | T>P | No |
ClinGen Ensembl |
|
| TCGA novel | 318 | T>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA403375132 rs1455270610 |
319 | G>R | No |
ClinGen TOPMed |
|
|
CA403375161 rs1366586665 |
321 | R>P | No |
ClinGen TOPMed |
|
|
rs748359367 CA9090030 |
324 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403375217 rs1314199880 |
325 | I>M | No |
ClinGen gnomAD |
|
|
CA403375376 rs1219553427 |
335 | V>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1219553427 CA403375372 |
335 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
CA9090070 rs749494347 |
338 | R>L | No |
ClinGen ExAC |
|
|
CA9090069 rs778015695 |
338 | R>W | No |
ClinGen ExAC TOPMed |
|
|
rs913349262 CA304442494 |
339 | A>V | No |
ClinGen Ensembl |
|
|
CA9090072 rs779678732 |
340 | E>D | No |
ClinGen ExAC |
|
|
rs7255988 CA403375507 |
342 | C>* | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs7255988 CA304442495 |
342 | C>W | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1279387361 CA403375515 |
343 | A>S | No |
ClinGen gnomAD |
|
|
rs761275153 CA9090076 |
345 | L>Q | No |
ClinGen ExAC |
|
| TCGA novel | 349 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA304442497 rs905850256 |
350 | A>G | No |
ClinGen TOPMed |
|
|
CA9090078 rs368054611 |
350 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs573290406 CA9090080 |
351 | V>I | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs141381662 CA304442499 |
353 | Y>F | No |
ClinGen ESP TOPMed gnomAD |
|
| TCGA novel | 355 | Q>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 356 | M>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1328340293 CA403375861 |
361 | P>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1328340293 CA403375855 |
361 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA403375887 rs1400673059 |
362 | T>S | No |
ClinGen gnomAD |
|
|
rs182911350 CA9090084 |
364 | M>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9090086 rs764058396 |
367 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA304442502 rs1017950383 |
369 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA403376075 rs1365130113 |
371 | P>L | No |
ClinGen gnomAD |
|
|
rs865800775 CA304442503 |
371 | P>S | No |
ClinGen Ensembl |
|
| TCGA novel | 372 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs139150317 CA9090091 |
373 | P>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1169284272 CA403376130 |
375 | D>E | No |
ClinGen TOPMed |
|
|
CA9090093 rs748059852 |
375 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
| rs375800297 | 380 | D>= | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs757251659 CA9090151 |
382 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403377177 rs1364935195 |
384 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
CA403377175 rs1364935195 |
384 | S>W | No |
ClinGen TOPMed gnomAD |
|
|
rs930106526 CA304443905 |
386 | I>T | No |
ClinGen Ensembl |
|
|
rs1274817667 CA403377258 |
389 | E>G | No |
ClinGen gnomAD |
|
|
rs200749383 CA9090155 |
389 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403377266 rs1322098706 |
390 | C>G | No |
ClinGen gnomAD |
|
|
CA403377296 rs1347481240 |
391 | E>V | No |
ClinGen TOPMed gnomAD |
|
|
CA9090157 rs768234393 |
393 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1568223334 CA403377337 |
394 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
|
rs1190040933 CA403377384 |
396 | I>T | No |
ClinGen TOPMed |
|
|
rs1477628381 CA403377391 |
397 | E>K | No |
ClinGen gnomAD |
|
|
CA403377403 rs1191698563 |
397 | E>V | No |
ClinGen gnomAD |
|
|
CA403377430 rs1416478316 |
399 | L>M | No |
ClinGen gnomAD |
|
|
rs1035852737 CA304443906 |
400 | V>M | No |
ClinGen TOPMed |
|
|
CA9090164 rs774340944 |
402 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA403377572 rs1397822945 |
406 | P>L | No |
ClinGen gnomAD |
|
|
CA9090167 rs776468867 |
408 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9090168 rs761714054 |
408 | R>H | No |
ClinGen ExAC gnomAD |
|
|
rs776468867 CA304443907 |
408 | R>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403377598 rs201898018 |
409 | A>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9090170 COSM1740575 rs201898018 |
409 | A>T | haematopoietic_and_lymphoid_tissue [Cosmic] | No |
ClinGen cosmic curated ESP ExAC TOPMed gnomAD |
|
rs1190929754 CA403377604 |
409 | A>V | No |
ClinGen gnomAD |
|
|
rs765883460 CA9090172 |
410 | E>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA403377616 rs1487993769 |
410 | E>V | No |
ClinGen gnomAD |
|
|
CA9090174 rs368259481 |
413 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA9090175 rs145338811 |
413 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs145338811 CA403377673 |
413 | R>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs756505500 CA9090177 |
416 | S>I | No |
ClinGen ExAC |
|
|
rs1442089986 CA403377745 COSM3692757 |
417 | P>L | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
rs771465294 CA403377790 |
420 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs771465294 CA9090180 |
420 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA304443911 rs968786696 |
423 | V>L | No |
ClinGen TOPMed gnomAD |
|
|
CA304443909 rs968786696 |
423 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
CA9090185 rs761658845 |
425 | G>C | No |
ClinGen ExAC gnomAD |
|
|
CA403377865 rs761658845 |
425 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA304443942 rs1035336855 |
426 | P>S | No |
ClinGen TOPMed |
|
|
CA9090219 rs148794749 |
427 | S>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs758992349 CA9090218 |
427 | S>P | No |
ClinGen ExAC gnomAD |
|
|
rs565166694 CA403378018 |
429 | A>D | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs749075247 CA9090223 |
429 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9090224 rs565166694 |
429 | A>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA304443948 rs112334040 |
430 | N>I | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs112334040 CA9090225 |
430 | N>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs112334040 CA403378030 |
430 | N>T | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA403378035 rs1196675695 |
431 | G>R | No |
ClinGen gnomAD |
|
|
CA9090227 rs772112206 |
431 | G>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1568223543 CA403378053 |
432 | L>R | No |
ClinGen Ensembl |
|
|
CA9090231 rs151289664 |
434 | P>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs763666380 CA9090230 |
434 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA9090233 rs765494888 |
435 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs750838012 CA9090234 |
435 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1362468408 CA403378084 |
436 | P>L | No |
ClinGen gnomAD |
|
| TCGA novel | 437 | S>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1400915626 CA403378093 |
437 | S>N | No |
ClinGen gnomAD |
|
|
rs868752033 CA304443960 |
438 | V>A | No |
ClinGen Ensembl |
|
|
rs199991663 CA9090236 |
438 | V>I | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1247480057 CA403378110 |
439 | N>Y | No |
ClinGen TOPMed gnomAD |
|
|
rs1185241431 CA403378125 |
440 | G>E | No |
ClinGen TOPMed |
|
|
CA9090237 COSM1239836 rs189209303 |
440 | G>R | oesophagus [Cosmic] | No |
ClinGen cosmic curated 1000Genomes ExAC TOPMed gnomAD |
|
rs904636078 CA403378143 |
441 | S>R | No |
ClinGen TOPMed gnomAD |
|
|
CA9090238 rs371787426 |
442 | G>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA403378169 rs1215495349 |
443 | A>V | No |
ClinGen gnomAD |
|
|
rs1367606866 CA403378206 |
446 | S>N | No |
ClinGen gnomAD |
|
|
rs745731303 CA9090243 |
447 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403378230 rs1382317580 |
448 | G>C | No |
ClinGen TOPMed gnomAD |
|
|
CA403378227 rs1382317580 |
448 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
CA9090247 rs768177514 |
450 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9090249 rs761339485 |
451 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9090250 rs764999661 COSM439496 |
452 | P>L | Variant assessed as Somatic; 0.0 impact. breast [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA403378296 rs1162136089 |
453 | V>M | No |
ClinGen TOPMed |
|
|
CA9090252 rs763380086 |
456 | M>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs538626178 CA9090254 |
461 | P>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA403378450 rs1258390981 |
461 | P>S | No |
ClinGen gnomAD |
|
|
CA9090257 rs76518919 |
463 | A>T | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1180472271 CA403378493 |
463 | A>V | No |
ClinGen gnomAD |
|
|
rs756273866 CA9090258 |
464 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9090259 rs756273866 |
464 | D>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1308007219 CA403378770 |
476 | S>L | No |
ClinGen gnomAD |
|
|
rs768619438 CA9090265 |
477 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs1450883689 CA403378809 |
478 | D>Y | No |
ClinGen gnomAD |
|
|
rs775999858 CA9090269 |
481 | E>V | No |
ClinGen ExAC gnomAD |
|
|
rs1446609561 CA403378887 |
482 | E>K | No |
ClinGen gnomAD |
|
|
rs1390832102 CA403378903 |
483 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
CA9090273 rs372546036 |
484 | E>D | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA403378938 rs1372193382 |
484 | E>Q | No |
ClinGen TOPMed |
|
|
CA403379074 rs769266512 |
488 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1200346084 CA403379088 |
489 | E>G | No |
ClinGen gnomAD |
|
|
CA9090277 rs772948956 |
489 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403379144 rs763362345 |
490 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9090279 rs766832572 |
491 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA403379197 rs1434952103 |
493 | G>R | No |
ClinGen gnomAD |
|
|
rs1428886412 CA403379253 |
495 | R>Q | No |
ClinGen gnomAD |
|
|
rs760119109 CA9090281 |
495 | R>W | No |
ClinGen ExAC |
|
|
rs1022727903 CA304444004 |
497 | K>M | No |
ClinGen TOPMed |
|
|
CA403379287 rs1344058915 |
498 | R>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs768200481 CA9090282 |
499 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9090283 rs375573896 |
499 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs375573896 CA403379307 |
499 | R>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1178269482 CA403379330 |
500 | C>* | No |
ClinGen gnomAD |
|
|
CA9090284 rs760810762 |
500 | C>F | No |
ClinGen ExAC |
|
|
rs1302736773 CA403379342 |
501 | P>S | No |
ClinGen TOPMed |
|
|
CA304444009 rs1000048417 |
503 | Q>H | No |
ClinGen TOPMed |
|
|
CA9090285 rs764177800 |
505 | G>S | No |
ClinGen ExAC gnomAD |
|
|
rs1369152617 CA403379444 |
507 | V>M | No |
ClinGen gnomAD |
|
|
rs757524630 CA9090287 |
508 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs757524630 CA403379488 |
508 | P>Q | No |
ClinGen ExAC TOPMed gnomAD |
No associated diseases with Q8N2W9
Functions
| Description | ||
|---|---|---|
| EC Number | 2.3.2.27 | Aminoacyltransferases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
6 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| nuclear matrix | The dense fibrillar network lying on the inner side of the nuclear membrane. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| PML body | A class of nuclear body; they react against SP100 auto-antibodies (PML, promyelocytic leukemia); cells typically contain 10-30 PML bodies per nucleus; alterations in the localization of PML bodies occurs after viral infection. |
| transferase complex | A protein complex capable of catalyzing the transfer of a group, e.g. a methyl group, glycosyl group, acyl group, phosphorus-containing, or other groups, from one compound (generally regarded as the donor) to another compound (generally regarded as the acceptor). |
8 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| protein C-terminus binding | Binding to a protein C-terminus, the end of a peptide chain at which the 1-carboxyl function of a constituent amino acid is not attached in peptide linkage to another amino-acid residue. |
| SUMO ligase activity | Catalysis of the transfer of SUMO to a substrate protein via the reaction X-SUMO + S --> X + S-SUMO, where X is either an E2 or E3 enzyme, the X-SUMO linkage is a thioester bond, and the S-SUMO linkage is an isopeptide bond between the C-terminal amino acid of SUMO and the epsilon-amino group of lysine residues in the substrate. |
| SUMO transferase activity | Catalysis of the transfer of SUMO from one protein to another via the reaction X-SUMO + Y --> Y-SUMO + X, where both X-SUMO and Y-SUMO are covalent linkages. |
| transcription coregulator activity | A transcription regulator activity that modulates the transcription of specific gene sets via binding to a DNA-bound DNA-binding transcription factor, either on its own or as part of a complex. Coregulators often act by altering chromatin structure and modifications. For example, one class of transcription coregulators modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. |
| transcription corepressor activity | A transcription coregulator activity that represses or decreases the transcription of specific gene sets via binding to a DNA-bound DNA-binding transcription factor, either on its own or as part of a complex. Corepressors often act by altering chromatin structure and modifications. For example, one class of transcription corepressors modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. |
| ubiquitin protein ligase binding | Binding to a ubiquitin protein ligase enzyme, any of the E3 proteins. |
| zinc ion binding | Binding to a zinc ion (Zn). |
16 GO annotations of biological process
| Name | Definition |
|---|---|
| central nervous system development | The process whose specific outcome is the progression of the central nervous system over time, from its formation to the mature structure. The central nervous system is the core nervous system that serves an integrating and coordinating function. In vertebrates it consists of the brain and spinal cord. In those invertebrates with a central nervous system it typically consists of a brain, cerebral ganglia and a nerve cord. |
| double-strand break repair | The repair of double-strand breaks in DNA via homologous and nonhomologous mechanisms to reform a continuous DNA helix. |
| hair follicle development | The process whose specific outcome is the progression of the hair follicle over time, from its formation to the mature structure. A hair follicle is a tube-like opening in the epidermis where the hair shaft develops and into which the sebaceous glands open. |
| limb epidermis development | The process whose specific outcome is the progression of the epidermis of the limb over time, from its formation to the mature structure. The limb epidermis is the outer epithelial layer of the limb, it is a complex stratified squamous epithelium. |
| negative regulation of DNA-templated transcription | Any process that stops, prevents, or reduces the frequency, rate or extent of cellular DNA-templated transcription. |
| negative regulation of NF-kappaB transcription factor activity | Any process that stops, prevents, or reduces the frequency, rate or extent of the activity of the transcription factor NF-kappaB. |
| negative regulation of transcription by RNA polymerase II | Any process that stops, prevents, or reduces the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| negative regulation of tumor necrosis factor-mediated signaling pathway | Any process that decreases the rate or extent of the tumor necrosis factor-mediated signaling pathway. The tumor necrosis factor-mediated signaling pathway is the series of molecular signals generated as a consequence of tumor necrosis factor binding to a cell surface receptor. |
| positive regulation of double-strand break repair via homologous recombination | Any process that activates or increases the frequency, rate or extent of double-strand break repair via homologous recombination. |
| positive regulation of intrinsic apoptotic signaling pathway in response to DNA damage | Any process that activates or increases the frequency, rate or extent of intrinsic apoptotic signaling pathway in response to DNA damage. |
| positive regulation of keratinocyte apoptotic process | Any process that activates or increases the frequency, rate or extent of keratinocyte apoptotic process. |
| positive regulation of protein sumoylation | Any process that activates or increases the frequency, rate or extent of the addition of SUMO groups to a protein. |
| protein sumoylation | The process in which a SUMO protein (small ubiquitin-related modifier) is conjugated to a target protein via an isopeptide bond between the carboxy-terminus of SUMO with an epsilon-amino group of a lysine residue of the target protein. |
| regulation of transcription by RNA polymerase II | Any process that modulates the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| vitamin D metabolic process | The chemical reactions and pathways involving vitamin D, any of a group of related, fat-soluble compounds that are derived from delta-5,7 steroids and play a central role in calcium metabolism. Specific forms of vitamin D include calciferol (ergocalciferol; vitamin D2) and cholecalciferol (calciol; vitamin D3). |
| Wnt signaling pathway | The series of molecular signals initiated by binding of a Wnt protein to a frizzled family receptor on the surface of the target cell and ending with a change in cell state. |
3 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q12216 | NFI1 | E3 SUMO-protein ligase SIZ2 | Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) | PR |
| Q04195 | SIZ1 | E3 SUMO-protein ligase SIZ1 | Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) | PR |
| O75925 | PIAS1 | E3 SUMO-protein ligase PIAS1 | Homo sapiens (Human) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAAELVEAKN | MVMSFRVSDL | QMLLGFVGRS | KSGLKHELVT | RALQLVQFDC | SPELFKKIKE |
| 70 | 80 | 90 | 100 | 110 | 120 |
| LYETRYAKKN | SEPAPQPHRP | LDPLTMHSTY | DRAGAVPRTP | LAGPNIDYPV | LYGKYLNGLG |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RLPAKTLKPE | VRLVKLPFFN | MLDELLKPTE | LVPQNNEKLQ | ESPCIFALTP | RQVELIRNSR |
| 190 | 200 | 210 | 220 | 230 | 240 |
| ELQPGVKAVQ | VVLRICYSDT | SCPQEDQYPP | NIAVKVNHSY | CSVPGYYPSN | KPGVEPKRPC |
| 250 | 260 | 270 | 280 | 290 | 300 |
| RPINLTHLMY | LSSATNRITV | TWGNYGKSYS | VALYLVRQLT | SSELLQRLKT | IGVKHPELCK |
| 310 | 320 | 330 | 340 | 350 | 360 |
| ALVKEKLRLD | PDSEIATTGV | RVSLICPLVK | MRLSVPCRAE | TCAHLQCFDA | VFYLQMNEKK |
| 370 | 380 | 390 | 400 | 410 | 420 |
| PTWMCPVCDK | PAPYDQLIID | GLLSKILSEC | EDADEIEYLV | DGSWCPIRAE | KERSCSPQGA |
| 430 | 440 | 450 | 460 | 470 | 480 |
| ILVLGPSDAN | GLLPAPSVNG | SGALGSTGGG | GPVGSMENGK | PGADVVDLTL | DSSSSSEDEE |
| 490 | 500 | ||||
| EEEEEEEDED | EEGPRPKRRC | PFQKGLVPAC |