Q12216
Gene name |
NFI1 (SIZ2, YOR156C) |
Protein name |
E3 SUMO-protein ligase SIZ2 |
Names |
E3 SUMO-protein transferase SIZ2, SAP and Miz-finger domain-containing protein 2 |
Species |
Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) |
KEGG Pathway |
sce:YOR156C |
EC number |
|
Protein Class |
|
Descriptions
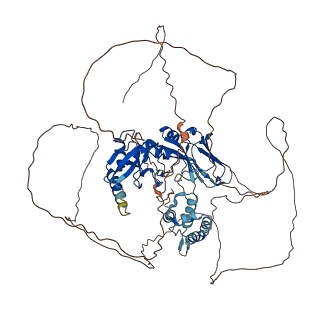
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
2 structures for Q12216
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 6U75 | X-ray | 263 A | A/B | 154-420 | PDB |
| AF-Q12216-F1 | Predicted | AlphaFoldDB |
13 variants for Q12216
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| s15-630474 | 23 | N>S | No | SGRP | |
| s15-629974 | 190 | S>P | No | SGRP | |
| s15-629804 | 246 | K>N | No | SGRP | |
| s15-629805 | 246 | K>R | No | SGRP | |
| s15-629511 | 344 | R>K | No | SGRP | |
| s15-629359 | 395 | V>L | No | SGRP | |
| s15-629133 | 470 | P>L | No | SGRP | |
| s15-629094 | 483 | F>Y | No | SGRP | |
| s15-629046 | 499 | D>G | No | SGRP | |
| s15-628690 | 618 | L>F | No | SGRP | |
| s15-628573 | 657 | V>L | No | SGRP | |
| s15-628540 | 668 | I>V | No | SGRP | |
| s15-628417 | 709 | D>N | No | SGRP |
No associated diseases with Q12216
3 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromatin | The ordered and organized complex of DNA, protein, and sometimes RNA, that forms the chromosome. |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
3 GO annotations of molecular function
| Name | Definition |
|---|---|
| double-stranded DNA binding | Binding to double-stranded DNA. |
| SUMO transferase activity | Catalysis of the transfer of SUMO from one protein to another via the reaction X-SUMO + Y --> Y-SUMO + X, where both X-SUMO and Y-SUMO are covalent linkages. |
| zinc ion binding | Binding to a zinc ion (Zn). |
3 GO annotations of biological process
| Name | Definition |
|---|---|
| chromosome segregation | The process in which genetic material, in the form of chromosomes, is organized into specific structures and then physically separated and apportioned to two or more sets. In eukaryotes, chromosome segregation begins with the condensation of chromosomes, includes chromosome separation, and ends when chromosomes have completed movement to the spindle poles. |
| DNA double-strand break attachment to nuclear envelope | A process in which the DNA double-strand breaks are attached to the inner surface of the nuclear envelope proximal to the spindle pole body, or iMTOCs. |
| protein sumoylation | The process in which a SUMO protein (small ubiquitin-related modifier) is conjugated to a target protein via an isopeptide bond between the carboxy-terminus of SUMO with an epsilon-amino group of a lysine residue of the target protein. |
3 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q04195 | SIZ1 | E3 SUMO-protein ligase SIZ1 | Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) | PR |
| Q8N2W9 | PIAS4 | E3 SUMO-protein ligase PIAS4 | Homo sapiens (Human) | PR |
| O75925 | PIAS1 | E3 SUMO-protein ligase PIAS1 | Homo sapiens (Human) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MASVMSNNNN | NNNNNNASYM | FTNPLSNTGG | GLINEIKDAI | NEMEQLKVLE | LKQICKSLDL |
| 70 | 80 | 90 | 100 | 110 | 120 |
| SITGKKAVLQ | DRIKQFLRKS | CDIGHIDPWR | PKAIKILIAK | VRINSSLPKY | STLWETLKTG |
| 130 | 140 | 150 | 160 | 170 | 180 |
| AFKHPVASGQ | LPVTALQSTA | LPPYSQQQAL | AYSFTSPFYK | PIVQIPDANK | KLKQSAGRGC |
| 190 | 200 | 210 | 220 | 230 | 240 |
| TKMKFKVSKS | NHDLLKSNKS | YKLYLFSGFS | IPFIYETVGH | EAIDFPYPCE | LVFNGTKLED |
| 250 | 260 | 270 | 280 | 290 | 300 |
| NVKGLKKQNG | TGNPANLTPY | LKVPTEMNHL | DLHYLNIDKE | YSISCFIVEV | FSPEALLGKI |
| 310 | 320 | 330 | 340 | 350 | 360 |
| LKRPKIIKQA | TTAYIKRTLN | EQDDDDIITT | STVLSLQCPI | SCTRMKYPAK | TDQCKHIQCF |
| 370 | 380 | 390 | 400 | 410 | 420 |
| DALWFLHSQS | QVPTWQCPIC | QHPIKFDQLK | ISEFVDNIIQ | NCNEDVEQVE | ISVDGSWKPI |
| 430 | 440 | 450 | 460 | 470 | 480 |
| HNSSAVITDT | VNQNHSVKNE | NQGTVKQEQD | YDSRNAFDTN | LRNGSNHNEP | EIISLDSSDD |
| 490 | 500 | 510 | 520 | 530 | 540 |
| EAFIPASKSF | PTHVNPRNDQ | LRADIFPSES | EGSSDYNPNH | TSTPKGSPTM | DQDNYQDAFQ |
| 550 | 560 | 570 | 580 | 590 | 600 |
| MRSFLNQGAT | TNINDTPTNN | SSINSFVTAT | NGDSRIFYNR | GPSTPLLPAV | LQNLTNQTEA |
| 610 | 620 | 630 | 640 | 650 | 660 |
| QRNPYGPNYN | TTAQDRNLLG | IEGDLPPIPP | VDPNSEAETE | LPTRTTSAAH | LPPYIHVSTS |
| 670 | 680 | 690 | 700 | 710 | 720 |
| GHGDDGKIRK | RRHSNVSIYI | PKNPYATLMK | RRPQANHAIM | NKTLAQTNDF | NTSAQDNSEV |
| VDLTSD |