Q86U70
Gene name |
LDB1 (CLIM2) |
Protein name |
LIM domain-binding protein 1 |
Names |
LDB-1, Carboxyl-terminal LIM domain-binding protein 2, CLIM-2, LIM domain-binding factor CLIM2, hLdb1, Nuclear LIM interactor |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:8861 |
EC number |
|
Protein Class |
|
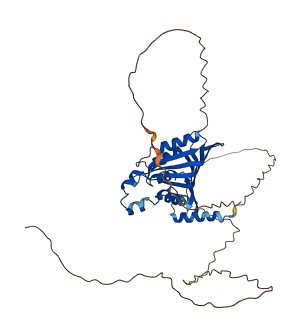
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
9 structures for Q86U70
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 2XJY | X-ray | 240 A | B | 334-368 | PDB |
| 2XJZ | X-ray | 280 A | I/J/K/L/M | 334-368 | PDB |
| 2YPA | X-ray | 280 A | D | 336-375 | PDB |
| 6TYD | X-ray | 280 A | V | 56-285 | PDB |
| 7OB5 | X-ray | 180 A | P | 401-411 | PDB |
| 7OB8 | X-ray | 180 A | B | 401-411 | PDB |
| 8HIB | X-ray | 245 A | V | 56-285 | PDB |
| 8SSU | X-ray | 289 A | A | 231-294 | PDB |
| AF-Q86U70-F1 | Predicted | AlphaFoldDB |
198 variants for Q86U70
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA377849215 rs1254777610 |
4 | G>A | No |
ClinGen gnomAD |
|
|
rs780482579 CA377846835 |
9 | G>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs780482579 CA5660541 |
9 | G>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1355681900 CA377846758 |
13 | K>R | No |
ClinGen gnomAD |
|
|
rs763253713 CA212174772 |
19 | S>L | No |
ClinGen gnomAD |
|
|
CA212174768 rs1019837144 |
20 | P>L | No |
ClinGen gnomAD |
|
|
CA377846020 rs1287820023 |
20 | P>S | No |
ClinGen gnomAD |
|
|
rs547343320 CA5660538 |
22 | E>D | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1405190254 CA377845978 |
23 | P>R | No |
ClinGen gnomAD |
|
|
CA5660537 rs761961476 |
24 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA5660535 rs201649218 |
26 | G>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA5660534 rs762949850 |
28 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA377845918 rs1449588043 |
29 | F>L | No |
ClinGen TOPMed |
|
|
CA377845908 rs1160820726 |
30 | P>T | No |
ClinGen gnomAD |
|
|
CA377845892 rs776230908 |
31 | P>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660531 rs776230908 |
31 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs776230908 CA5660530 |
31 | P>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA377845886 rs1456602440 |
32 | F>V | No |
ClinGen TOPMed |
|
|
CA377845875 rs1450866275 |
33 | H>N | No |
ClinGen gnomAD |
|
|
rs770596778 CA5660529 |
33 | H>Q | No |
ClinGen ExAC gnomAD |
|
|
CA377845851 rs777272483 |
35 | G>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs777272483 CA5660527 |
35 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA212174745 rs777272483 |
35 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1411383662 CA377845835 |
36 | T>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs1375768973 CA377845787 |
41 | D>Y | No |
ClinGen gnomAD |
|
|
CA5660524 rs780494241 |
42 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs1436065075 CA377845757 |
43 | G>A | No |
ClinGen gnomAD |
|
|
rs1436065075 CA377845759 |
43 | G>D | No |
ClinGen gnomAD |
|
|
CA377845735 rs1365075722 |
44 | P>L | No |
ClinGen gnomAD |
|
|
rs1442176036 CA377845737 |
44 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA377845725 rs1440518521 |
46 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1233122876 CA377845719 |
47 | M>L | No |
ClinGen TOPMed |
|
|
CA377845721 rs1233122876 |
47 | M>V | No |
ClinGen TOPMed |
|
|
CA5660506 rs776042607 |
48 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660505 rs770225174 |
49 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA377845693 rs1318426179 |
49 | P>Q | No |
ClinGen gnomAD |
|
|
rs770225174 CA377845697 |
49 | P>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA377845686 rs1392938518 |
50 | P>S | No |
ClinGen gnomAD |
|
|
rs938626844 CA212174553 |
51 | T>S | No |
ClinGen Ensembl |
|
|
CA5660503 rs781692988 |
53 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs757494369 CA5660502 |
55 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA377845610 rs1445964676 |
57 | I>T | No |
ClinGen TOPMed |
|
|
rs1345683599 CA377845524 |
61 | T>I | No |
ClinGen TOPMed |
|
|
CA377845504 rs755881985 |
63 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660475 rs755881985 |
63 | Y>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660474 rs200658541 |
65 | N>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1463085489 CA377845470 |
66 | Q>P | No |
ClinGen TOPMed gnomAD |
|
|
CA377845427 rs1164083234 |
68 | D>E | No |
ClinGen gnomAD |
|
|
rs761376100 CA5660472 |
69 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs767158126 CA5660473 |
69 | Y>N | No |
ClinGen ExAC gnomAD |
|
|
CA212174385 rs12767417 |
75 | N>T | No |
ClinGen Ensembl |
|
|
rs777243026 CA5660468 |
77 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs762616778 CA377845265 |
77 | R>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs898675596 CA212174377 |
81 | W>C | No |
ClinGen Ensembl |
|
|
rs201588496 CA5660451 |
87 | N>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs766930665 CA5660450 |
88 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660449 rs761104389 |
91 | D>G | No |
ClinGen ExAC gnomAD |
|
|
rs1231889564 CA377844809 |
92 | A>E | No |
ClinGen gnomAD |
|
|
CA5660445 rs774536883 |
95 | T>S | No |
ClinGen ExAC gnomAD |
|
|
CA5660443 rs749326604 |
105 | T>S | No |
ClinGen ExAC gnomAD |
|
|
rs780111951 CA5660442 |
108 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs1392630711 CA377844305 |
110 | L>V | No |
ClinGen TOPMed |
|
|
CA5660441 rs769661160 |
111 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs1428316921 CA377844218 |
112 | D>G | No |
ClinGen TOPMed |
|
|
CA377844109 rs1455886550 |
116 | R>K | No |
ClinGen gnomAD |
|
|
CA377844093 rs1564912926 |
117 | Y>C | No |
ClinGen Ensembl |
|
|
rs1391848028 CA377844063 |
118 | T>A | No |
ClinGen TOPMed |
|
|
rs962843747 CA212174083 |
118 | T>N | No |
ClinGen Ensembl |
|
|
CA377843841 rs1356417431 COSM215407 |
121 | R>W | central_nervous_system [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA5660412 rs767872374 |
126 | R>C | No |
ClinGen ExAC gnomAD |
|
|
rs757787986 CA5660411 |
126 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs1185246709 CA377843695 |
127 | Y>S | No |
ClinGen gnomAD |
|
|
rs751862555 CA5660410 |
129 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660409 rs764429245 |
129 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs199713070 CA5660407 |
133 | E>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1334446781 CA377843442 |
133 | E>V | No |
ClinGen TOPMed |
|
|
CA377843362 rs1435826108 |
136 | A>T | No |
ClinGen gnomAD |
|
|
CA212174041 rs144764727 |
137 | T>M | No |
ClinGen ESP TOPMed |
|
|
CA377843122 rs1204629069 |
142 | V>G | No |
ClinGen TOPMed |
|
|
rs770703563 CA5660403 |
145 | H>P | No |
ClinGen ExAC |
|
|
CA212174010 rs886165782 |
147 | K>R | No |
ClinGen Ensembl |
|
|
CA5660400 rs771963891 |
149 | A>T | No |
ClinGen ExAC |
|
|
CA377842864 rs1357297095 |
150 | F>L | No |
ClinGen gnomAD |
|
|
rs149408048 CA5660399 |
152 | S>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs143495877 CA5660396 |
157 | L>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA377842596 COSM1188030 COSM1188031 rs1392988031 |
158 | D>N | lung Variant assessed as Somatic; 0.0 impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
rs1044703972 CA212173946 |
162 | G>C | No |
ClinGen TOPMed gnomAD |
|
|
rs1044703972 CA212173948 |
162 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
rs778290861 CA5660392 |
171 | P>H | No |
ClinGen ExAC gnomAD |
|
|
CA377842063 rs1310876905 |
172 | M>I | No |
ClinGen TOPMed |
|
|
CA377842088 rs1273280872 |
172 | M>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1346120164 CA377841697 |
179 | E>D | No |
ClinGen gnomAD |
|
|
COSM426966 COSM1474315 CA377841615 rs1220258853 |
183 | Y>H | breast [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs373038125 CA5660372 |
187 | M>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA5660371 rs188642585 |
190 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ExAC NCI-TCGA TOPMed gnomAD |
|
rs754063958 CA5660370 |
191 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs1298371315 CA377841389 |
191 | M>T | No |
ClinGen gnomAD |
|
|
COSM2058822 CA5660369 COSM302541 rs766563001 |
193 | R>W | Variant assessed as Somatic; 4.705e-05 impact. central_nervous_system [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
CA377841273 rs1590281775 |
198 | H>P | No |
ClinGen Ensembl |
|
|
rs1264035751 CA377841152 |
202 | R>Q | No |
ClinGen gnomAD |
|
|
CA212173625 rs919693683 COSM1345423 COSM1345422 |
202 | R>W | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
rs761857156 CA377841080 |
205 | R>L | No |
ClinGen ExAC gnomAD |
|
|
CA5660365 rs761857156 |
205 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs1282894133 CA377841076 |
206 | E>K | No |
ClinGen gnomAD |
|
|
CA5660364 rs774214210 |
206 | E>V | No |
ClinGen ExAC gnomAD |
|
|
rs749985868 CA212173595 |
207 | L>F | No |
ClinGen Ensembl |
|
|
CA5660363 rs768491598 |
209 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs1216848177 CA377841008 |
210 | R>C | No |
ClinGen gnomAD |
|
|
rs762694194 CA5660362 |
210 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA377840969 rs1590281656 |
213 | L>V | No |
ClinGen Ensembl |
|
|
CA377840948 rs1353253496 |
214 | A>D | No |
ClinGen TOPMed gnomAD |
|
|
rs1413778386 CA377840954 |
214 | A>P | No |
ClinGen TOPMed gnomAD |
|
|
rs1466404255 CA377840933 |
215 | M>L | No |
ClinGen gnomAD |
|
|
CA377840928 rs1353731068 |
215 | M>T | No |
ClinGen gnomAD |
|
|
rs769457773 CA5660360 |
216 | H>Q | No |
ClinGen ExAC gnomAD |
|
|
CA377840724 rs1377520634 |
218 | Q>E | No |
ClinGen gnomAD |
|
|
rs1325080408 CA377840674 |
220 | P>S | No |
ClinGen gnomAD |
|
|
rs147037173 CA5660332 |
222 | M>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA5660330 rs139160379 |
225 | Q>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA377840490 rs1392882608 |
225 | Q>R | No |
ClinGen gnomAD |
|
|
rs764051483 CA5660329 |
230 | I>M | No |
ClinGen ExAC gnomAD |
|
|
rs34707683 CA212173400 |
230 | I>T | No |
ClinGen Ensembl |
|
|
CA377840330 rs1343697945 |
231 | T>S | No |
ClinGen gnomAD |
|
|
rs184966094 CA212173394 |
232 | R>W | No |
ClinGen 1000Genomes TOPMed |
|
|
CA5660328 rs758269767 |
233 | C>G | No |
ClinGen ExAC gnomAD |
|
|
CA212173387 rs34668927 |
233 | C>S | No |
ClinGen Ensembl |
|
|
rs759369989 CA5660325 |
237 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA5660323 rs766046306 |
241 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1209983970 CA377840075 |
242 | Y>C | No |
ClinGen gnomAD |
|
|
CA377839896 rs1488418952 |
250 | E>K | No |
ClinGen gnomAD |
|
|
CA377839873 rs1279342132 |
251 | P>R | No |
ClinGen gnomAD |
|
|
rs765994038 CA5660304 |
253 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
rs760258946 CA5660303 |
263 | S>N | No |
ClinGen ExAC gnomAD |
|
|
rs1446249347 CA377839645 |
267 | R>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
|
rs796461509 CA212173239 |
268 | D>E | No |
ClinGen gnomAD |
|
|
rs761428646 CA5660300 |
269 | C>S | No |
ClinGen ExAC gnomAD |
|
|
rs1400823826 CA377839610 |
272 | T>N | No |
ClinGen gnomAD |
|
|
rs1311407440 CA377839551 |
280 | R>C | No |
ClinGen gnomAD |
|
|
CA377839552 rs1311407440 |
280 | R>G | No |
ClinGen gnomAD |
|
|
rs1387060330 CA377839550 |
280 | R>H | No |
ClinGen TOPMed |
|
|
rs373863079 CA5660298 |
282 | V>L | No |
ClinGen ESP ExAC TOPMed |
|
|
CA5660271 rs748162410 |
286 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs561553415 CA5660269 |
290 | R>C | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs749220036 CA5660268 |
292 | Q>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1396778383 CA377839184 |
297 | R>Q | No |
ClinGen gnomAD |
|
|
VAR_036366 rs990101456 CA212173026 COSM1345421 COSM33199 |
299 | R>Q | large_intestine Variant assessed as Somatic; impact. a colorectal cancer sample; somatic mutation [Cosmic, NCI-TCGA, UniProt] | No |
ClinGen cosmic curated UniProt NCI-TCGA TOPMed dbSNP |
|
CA377839082 rs1590280465 |
301 | M>I | No |
ClinGen Ensembl |
|
|
CA377839038 rs1300183004 |
305 | S>G | No |
ClinGen TOPMed |
|
|
rs1326579967 CA377839015 |
307 | M>T | No |
ClinGen TOPMed |
|
|
rs370177977 CA5660265 |
307 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA377838968 rs780666243 |
309 | S>C | No |
ClinGen ExAC gnomAD |
|
|
CA5660264 rs780666243 |
309 | S>F | No |
ClinGen ExAC gnomAD |
|
|
CA5660263 rs756973927 |
310 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA377838914 rs1437536591 |
312 | G>A | No |
ClinGen gnomAD |
|
|
rs1432873447 CA377838918 |
312 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
CA5660262 rs751055946 |
313 | N>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs763679443 CA5660261 |
315 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1245036842 CA377838821 |
316 | N>S | No |
ClinGen gnomAD |
|
|
rs754264863 CA5660260 |
318 | N>K | No |
ClinGen ExAC gnomAD |
|
|
rs766955952 CA5660258 |
319 | S>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs766955952 CA212172991 |
319 | S>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs148871407 CA5660257 COSM3934899 COSM3934900 |
322 | K>R | oesophagus [Cosmic] | No |
ClinGen cosmic curated ESP ExAC TOPMed gnomAD |
|
CA5660256 rs773634189 |
324 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA377838500 rs1310467341 |
325 | A>V | No |
ClinGen gnomAD |
|
|
CA5660252 rs768693158 COSM1584758 COSM266813 |
329 | A>T | Variant assessed as Somatic; 0.0 impact. large_intestine endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs775239408 CA5660250 |
331 | S>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660218 rs757570010 |
348 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA5660217 COSM200220 rs751950349 |
353 | E>K | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
CA5660215 rs763248283 |
355 | E>V | No |
ClinGen ExAC gnomAD |
|
|
CA377837285 rs1416390062 |
360 | R>Q | No |
ClinGen gnomAD |
|
|
CA5660213 rs765351164 |
360 | R>W | No |
ClinGen ExAC gnomAD |
|
|
rs776684327 CA5660211 |
368 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA5660210 rs771012981 |
369 | A>T | No |
ClinGen ExAC |
|
|
rs375534318 CA212172505 |
371 | G>S | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA377836803 rs1319622754 |
374 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA5660205 CA377836751 rs768403370 |
375 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660206 COSM275834 rs531176307 |
375 | E>K | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated 1000Genomes ExAC NCI-TCGA gnomAD |
|
rs201759181 CA212172475 |
379 | N>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5660203 rs201759181 |
379 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs563847702 CA5660202 |
380 | N>K | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1396083162 CA377836599 |
380 | N>S | No |
ClinGen gnomAD |
|
|
rs141161148 CA5660199 |
386 | A>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs141161148 CA5660198 |
386 | A>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA377836454 rs1351873438 |
387 | N>S | No |
ClinGen gnomAD |
|
|
CA377836444 rs942330225 |
388 | S>C | No |
ClinGen TOPMed |
|
|
CA212172440 rs942330225 |
388 | S>R | No |
ClinGen TOPMed |
|
|
CA377836410 rs1439415369 |
389 | P>L | No |
ClinGen gnomAD |
|
|
rs1378861409 CA377836346 |
392 | S>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1038866820 CA212172434 |
395 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs755033362 CA5660195 |
398 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
rs143992634 CA5660194 |
400 | S>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA5660193 rs766364480 |
402 | S>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1283637045 CA377836039 |
405 | P>S | No |
ClinGen gnomAD |
|
|
rs773354858 CA212172425 COSM1345420 |
406 | T>M | large_intestine Variant assessed as Somatic; impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs773354858 CA5660191 |
406 | T>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA377835963 rs1385205763 |
409 | A>P | No |
ClinGen gnomAD |
|
|
rs774007214 CA5660188 |
409 | A>V | No |
ClinGen ExAC |
|
|
CA5660187 rs768226147 |
410 | S>F | No |
ClinGen ExAC gnomAD |
No associated diseases with Q86U70
1 regional properties for Q86U70
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | LIM interaction domain | 336 - 375 | IPR041363 |
7 GO annotations of cellular component
| Name | Definition |
|---|---|
| beta-catenin-TCF complex | A protein complex that contains beta-catenin and a member of the T-cell factor (TCF)/lymphoid enhancer binding factor (LEF) family of transcription factors. |
| cell leading edge | The area of a motile cell closest to the direction of movement. |
| chromatin | The ordered and organized complex of DNA, protein, and sometimes RNA, that forms the chromosome. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| protein-containing complex | A stable assembly of two or more macromolecules, i.e. proteins, nucleic acids, carbohydrates or lipids, in which at least one component is a protein and the constituent parts function together. |
| transcription regulator complex | A protein complex that is capable of associating with DNA by direct binding, or via other DNA-binding proteins or complexes, and regulating transcription. |
9 GO annotations of molecular function
| Name | Definition |
|---|---|
| chromatin binding | Binding to chromatin, the network of fibers of DNA, protein, and sometimes RNA, that make up the chromosomes of the eukaryotic nucleus during interphase. |
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| DNA-binding transcription factor binding | Binding to a DNA-binding transcription factor, a protein that interacts with a specific DNA sequence (sometimes referred to as a motif) within the regulatory region of a gene to modulate transcription. |
| enzyme binding | Binding to an enzyme, a protein with catalytic activity. |
| LIM domain binding | Binding to a LIM domain (for Lin-11 Isl-1 Mec-3) of a protein, a domain with seven conserved cysteine residues and a histidine, that binds two zinc ions and acts as an interface for protein-protein interactions. |
| protein homodimerization activity | Binding to an identical protein to form a homodimer. |
| protein self-association | Binding to a domain within the same polypeptide. |
| RNA polymerase II-specific DNA-binding transcription factor binding | Binding to a sequence-specific DNA binding RNA polymerase II transcription factor, any of the factors that interact selectively and non-covalently with a specific DNA sequence in order to modulate transcription. |
| transcription coregulator activity | A transcription regulator activity that modulates the transcription of specific gene sets via binding to a DNA-bound DNA-binding transcription factor, either on its own or as part of a complex. Coregulators often act by altering chromatin structure and modifications. For example, one class of transcription coregulators modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. |
25 GO annotations of biological process
| Name | Definition |
|---|---|
| anterior/posterior axis specification | The establishment, maintenance and elaboration of the anterior/posterior axis. The anterior-posterior axis is defined by a line that runs from the head or mouth of an organism to the tail or opposite end of the organism. |
| cell adhesion | The attachment of a cell, either to another cell or to an underlying substrate such as the extracellular matrix, via cell adhesion molecules. |
| cellular component assembly | The aggregation, arrangement and bonding together of a cellular component. |
| cerebellar Purkinje cell differentiation | The process in which neuroblasts acquire specialized structural and/or functional features that characterize the mature cerebellar Purkinje cell. Differentiation includes the processes involved in commitment of a neuroblast to a Purkinje cell fate. A Purkinje cell is an inhibitory GABAergic neuron found in the cerebellar cortex that projects to the deep cerebellar nuclei and brain stem. |
| epithelial structure maintenance | A tissue homeostatic process required for the maintenance of epithelial structure. |
| gastrulation with mouth forming second | A gastrulation process in which the initial invagination becomes the anus and the mouth forms second. |
| hair follicle development | The process whose specific outcome is the progression of the hair follicle over time, from its formation to the mature structure. A hair follicle is a tube-like opening in the epidermis where the hair shaft develops and into which the sebaceous glands open. |
| histone H3-K4 acetylation | The modification of histone H3 by the addition of an acetyl group to a lysine residue at position 4 of the histone. |
| mesendoderm development | The process whose specific outcome is the progression of the mesendoderm over time, from its formation to the mature structure. In animal embryos, mesendoderm development gives rise to both mesoderm and endoderm tissues. |
| negative regulation of DNA-templated transcription | Any process that stops, prevents, or reduces the frequency, rate or extent of cellular DNA-templated transcription. |
| negative regulation of erythrocyte differentiation | Any process that stops, prevents, or reduces the frequency, rate or extent of erythrocyte differentiation. |
| negative regulation of transcription by RNA polymerase II | Any process that stops, prevents, or reduces the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| nervous system development | The process whose specific outcome is the progression of nervous tissue over time, from its formation to its mature state. |
| neuron differentiation | The process in which a relatively unspecialized cell acquires specialized features of a neuron. |
| positive regulation of cell adhesion | Any process that activates or increases the frequency, rate or extent of cell adhesion. |
| positive regulation of hemoglobin biosynthetic process | Any process that activates or increases the frequency, rate or extent of the chemical reactions and pathways resulting in the formation of hemoglobin, an oxygen carrying, conjugated protein containing four heme groups and globin. |
| positive regulation of transcription by RNA polymerase II | Any process that activates or increases the frequency, rate or extent of transcription from an RNA polymerase II promoter. |
| regulation of cell migration | Any process that modulates the frequency, rate or extent of cell migration. |
| regulation of focal adhesion assembly | Any process that modulates the frequency, rate or extent of focal adhesion formation, the establishment and maturation of focal adhesions. |
| regulation of kinase activity | Any process that modulates the frequency, rate or extent of kinase activity, the catalysis of the transfer of a phosphate group, usually from ATP, to a substrate molecule. |
| regulation of transcription elongation by RNA polymerase II | Any process that modulates the frequency, rate or extent of transcription elongation, the extension of an RNA molecule after transcription initiation and promoter clearance by the addition of ribonucleotides, catalyzed by RNA polymerase II. |
| somatic stem cell population maintenance | Any process by which an organism retains a population of somatic stem cells, undifferentiated cells in the embryo or adult which can undergo unlimited division and give rise to cell types of the body other than those of the germ-line. |
| transcription by RNA polymerase II | The synthesis of RNA from a DNA template by RNA polymerase II (RNAP II), originating at an RNA polymerase II promoter. Includes transcription of messenger RNA (mRNA) and certain small nuclear RNAs (snRNAs). |
| transcription-dependent tethering of RNA polymerase II gene DNA at nuclear periphery | The chromosome organization process in which the DNA sequence containing a gene transcribed by RNA polymerase II is maintained in a specific location at the nuclear periphery. In S. cerevisiae, this process involves cis-acting DNA sequences such as the TATA box and upstream activating sequence (UAS) elements, trans-acting transcriptional activators, and also the 3'-UTR of the transcript. |
| Wnt signaling pathway | The series of molecular signals initiated by binding of a Wnt protein to a frizzled family receptor on the surface of the target cell and ending with a change in cell state. |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSVGCACPGC | SSKSFKLYSP | KEPPNGNAFP | PFHPGTMLDR | DVGPTPMYPP | TYLEPGIGRH |
| 70 | 80 | 90 | 100 | 110 | 120 |
| TPYGNQTDYR | IFELNKRLQN | WTEECDNLWW | DAFTTEFFED | DAMLTITFCL | EDGPKRYTIG |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RTLIPRYFRS | IFEGGATELY | YVLKHPKEAF | HSNFVSLDCD | QGSMVTQHGK | PMFTQVCVEG |
| 190 | 200 | 210 | 220 | 230 | 240 |
| RLYLEFMFDD | MMRIKTWHFS | IRQHRELIPR | SILAMHAQDP | QMLDQLSKNI | TRCGLSNSTL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| NYLRLCVILE | PMQELMSRHK | TYSLSPRDCL | KTCLFQKWQR | MVAPPAEPTR | QQPSKRRKRK |
| 310 | 320 | 330 | 340 | 350 | 360 |
| MSGGSTMSSG | GGNTNNSNSK | KKSPASTFAL | SSQVPDVMVV | GEPTLMGGEF | GDEDERLITR |
| 370 | 380 | 390 | 400 | 410 | |
| LENTQFDAAN | GIDDEDSFNN | SPALGANSPW | NSKPPSSQES | KSENPTSQAS | Q |