Q6NUK4
Gene name |
REEP3 (C10orf74) |
Protein name |
Receptor expression-enhancing protein 3 |
Names |
|
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:221035 |
EC number |
|
Protein Class |
|
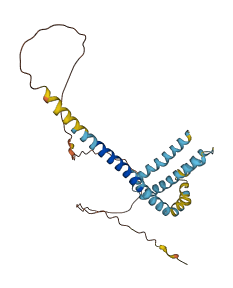
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q6NUK4
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q6NUK4-F1 | Predicted | AlphaFoldDB |
182 variants for Q6NUK4
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA377087012 rs1276020044 |
3 | S>F | No |
ClinGen gnomAD |
|
|
CA377087031 rs1411650257 |
5 | M>I | No |
ClinGen TOPMed |
|
|
CA5519321 rs765713511 |
6 | I>S | No |
ClinGen ExAC gnomAD |
|
|
rs199633181 CA5519322 |
9 | A>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA208677241 rs374920127 |
10 | V>A | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs573707168 CA208677242 |
11 | V>G | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
rs761312103 CA5519341 |
13 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs867051604 CA377086456 |
15 | G>A | No |
ClinGen TOPMed |
|
|
CA208681927 rs867051604 |
15 | G>V | No |
ClinGen TOPMed |
|
|
CA208681928 rs528665536 |
16 | M>I | No |
ClinGen gnomAD |
|
|
CA377086474 rs1462175687 |
16 | M>R | No |
ClinGen gnomAD |
|
|
CA377086472 rs1462175687 |
16 | M>T | No |
ClinGen gnomAD |
|
|
rs1254181905 CA377086510 |
17 | L>P | No |
ClinGen gnomAD |
|
|
CA208681929 rs371586859 |
18 | Y>H | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs374582467 CA208681930 |
19 | P>R | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA377086576 rs1423165320 |
21 | Y>H | No |
ClinGen gnomAD |
|
|
CA208681931 rs1039192013 |
21 | Y>S | No |
ClinGen gnomAD |
|
|
CA5519342 rs764716442 |
22 | Y>F | No |
ClinGen ExAC gnomAD |
|
|
CA208681932 rs867658121 COSM919532 |
23 | S>* | Variant assessed as Somatic; impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated Ensembl NCI-TCGA |
|
CA377086630 rs1465505200 |
24 | Y>C | No |
ClinGen gnomAD |
|
|
rs866343665 CA208681934 |
26 | A>D | No |
ClinGen Ensembl |
|
|
rs1000405867 CA208681933 |
26 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1564480400 CA377086726 |
29 | T>K | No |
ClinGen Ensembl |
|
|
CA5519345 rs766937672 |
32 | V>M | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 36 | V>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA5519355 rs779981551 |
37 | R>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs746739709 CA5519356 |
37 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
CA5519357 rs200806624 |
41 | Y>F | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA377087148 rs1310674245 |
45 | F>L | No |
ClinGen gnomAD |
|
|
CA377087157 rs1487316801 |
46 | A>S | No |
ClinGen gnomAD |
|
|
CA5519359 rs747849286 |
47 | L>V | No |
ClinGen ExAC |
|
|
CA208684851 COSM1627574 rs768683686 |
48 | Y>C | liver [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA208684850 rs760493875 |
48 | Y>H | No |
ClinGen Ensembl |
|
|
rs772554479 CA377087188 |
51 | I>S | No |
ClinGen ExAC gnomAD |
|
|
rs772554479 CA5519361 |
51 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA377087193 rs1419636397 |
52 | E>A | No |
ClinGen gnomAD |
|
|
CA5519362 rs1554807628 |
53 | T>I | No |
ClinGen Ensembl |
|
|
rs762544306 CA5519364 |
54 | V>L | No |
ClinGen ExAC gnomAD |
|
|
CA377087234 rs1564487686 |
58 | T>I | No |
ClinGen Ensembl |
|
|
rs774998631 CA5519366 |
60 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs750921710 CA208684852 |
61 | W>* | No |
ClinGen Ensembl |
|
|
CA377087286 rs1476610846 |
65 | Y>H | No |
ClinGen TOPMed |
|
|
rs747010885 CA5519378 COSM273181 |
66 | Y>C | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
rs1412384317 CA377087294 |
66 | Y>D | No |
ClinGen TOPMed gnomAD |
|
|
CA5519379 rs754748806 |
70 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs1589882828 CA377087363 |
76 | L>M | No |
ClinGen Ensembl |
|
|
rs1589882832 CA377087369 |
77 | L>V | No |
ClinGen Ensembl |
|
|
rs1447965684 CA377087379 |
78 | S>F | No |
ClinGen gnomAD |
|
|
rs781008184 CA377087390 |
80 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5519381 rs781008184 |
80 | Y>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1375284731 CA377087398 |
81 | T>S | No |
ClinGen gnomAD |
|
|
CA5519382 rs748008744 |
82 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA377087414 rs1235719572 |
84 | A>T | No |
ClinGen TOPMed |
|
|
rs769278826 CA5519385 |
85 | S>G | No |
ClinGen ExAC gnomAD |
|
|
CA5519386 rs772928461 |
85 | S>R | No |
ClinGen ExAC gnomAD |
|
|
rs770628789 CA5519388 |
87 | I>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs748675660 CA5519387 |
87 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs1197748825 CA377087459 |
91 | F>I | No |
ClinGen TOPMed gnomAD |
|
|
CA5519390 rs760168466 |
95 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 96 | L>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 97 | S>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs767961271 CA5519391 |
101 | R>T | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 103 | I>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA377087557 rs1191003183 |
103 | I>T | No |
ClinGen gnomAD |
|
|
rs1421936215 CA377087560 |
104 | D>N | No |
ClinGen gnomAD |
|
|
CA377087572 rs1453628338 |
105 | D>V | No |
ClinGen TOPMed |
|
|
rs1010876541 CA208685270 |
105 | D>Y | No |
ClinGen TOPMed |
|
|
rs1228215397 CA377087594 |
108 | V>A | No |
ClinGen TOPMed |
|
|
CA377087598 rs1396817962 |
109 | Q>* | No |
ClinGen TOPMed gnomAD |
|
|
CA5519410 rs200155346 |
110 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA208685273 rs966798577 |
112 | E>K | No |
ClinGen TOPMed |
|
|
rs769123093 CA5519411 COSM1223494 |
113 | R>* | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA5519413 rs373618451 |
113 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA5519414 rs765477411 |
114 | G>S | No |
ClinGen ExAC gnomAD |
|
|
rs1276474862 CA377087658 |
118 | M>T | No |
ClinGen gnomAD |
|
|
rs1043643944 CA208685274 |
119 | V>I | No |
ClinGen Ensembl |
|
|
rs1274223677 CA377087693 |
123 | R>Q | No |
ClinGen gnomAD |
|
|
rs562968137 CA5519415 |
123 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA377087702 rs1286504483 |
125 | G>S | No |
ClinGen gnomAD |
|
|
rs763030925 CA5519416 |
125 | G>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 129 | A>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA5519418 rs752743236 |
134 | V>I | No |
ClinGen ExAC gnomAD |
|
|
rs1214078335 CA377087769 |
135 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
CA377087768 rs1214078335 |
135 | T>S | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 138 | V>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA5519430 rs777016521 |
141 | Q>K | No |
ClinGen ExAC gnomAD |
|
|
CA208686423 rs753282196 |
142 | G>E | No |
ClinGen gnomAD |
|
| TCGA novel | 143 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA5519431 rs762191127 |
145 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 146 | E>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs372963754 CA5519432 |
147 | R>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs372963754 CA377087854 |
147 | R>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
COSM3415176 CA208686424 rs908483458 |
147 | R>H | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
rs1156906547 CA377087866 |
149 | R>K | No |
ClinGen gnomAD |
|
|
CA5519433 rs773424285 |
150 | S>N | No |
ClinGen ExAC gnomAD |
|
|
rs1458630686 CA377087886 |
152 | S>R | No |
ClinGen gnomAD |
|
|
CA5519435 rs766534851 |
154 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5519434 rs763012349 |
154 | H>Y | No |
ClinGen ExAC gnomAD |
|
|
rs775266362 CA377087910 |
155 | D>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs775266362 CA5519436 |
155 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5519437 rs760705999 |
158 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA5519438 rs763966753 |
159 | I>N | No |
ClinGen ExAC gnomAD |
|
|
CA377087937 rs763966753 |
159 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA5519439 rs753619150 |
161 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA377087968 rs1243628682 |
163 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
CA377087966 rs1235905454 |
163 | E>G | No |
ClinGen gnomAD |
|
|
rs1263301913 CA377087975 |
165 | V>M | No |
ClinGen gnomAD |
|
| TCGA novel | 166 | G>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1589888566 CA377088000 |
168 | R>S | No |
ClinGen Ensembl |
|
|
rs1040749870 CA208686427 |
170 | Y>N | No |
ClinGen Ensembl |
|
|
rs1589888571 CA377088010 |
170 | Y>S | No |
ClinGen Ensembl |
|
|
CA208686428 rs113298040 |
171 | Q>K | No |
ClinGen Ensembl |
|
|
VAR_048926 CA5519440 RCV000883312 rs10995569 |
171 | Q>R | No |
ClinGen ClinVar UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs764979700 CA5519441 |
172 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 174 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA377088042 rs1258353739 |
175 | E>D | No |
ClinGen gnomAD |
|
|
rs757960718 CA5519443 |
175 | E>Q | No |
ClinGen ExAC |
|
|
CA377088047 rs1424408175 |
176 | A>E | No |
ClinGen gnomAD |
|
|
rs572495959 CA208686429 |
178 | K>E | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
rs746536032 CA5519445 |
178 | K>N | No |
ClinGen ExAC gnomAD |
|
|
CA5519444 rs779659595 |
178 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs755466573 CA5519446 |
179 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs1304460329 CA377088092 |
183 | A>T | No |
ClinGen gnomAD |
|
|
CA5519448 rs748442346 |
183 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1589888603 CA377088102 |
184 | P>L | No |
ClinGen Ensembl |
|
|
CA377088110 rs1394942799 |
185 | S>R | No |
ClinGen gnomAD |
|
|
rs1225064691 CA377088107 |
185 | S>T | No |
ClinGen TOPMed |
|
|
CA5519449 rs770208373 |
187 | S>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA377088124 rs1341962544 |
188 | A>S | No |
ClinGen gnomAD |
|
|
CA377085945 rs1340357272 |
189 | G>D | No |
ClinGen gnomAD |
|
|
CA377085944 rs1340357272 |
189 | G>V | No |
ClinGen gnomAD |
|
|
rs750072566 CA5519459 |
191 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1233115069 CA377085969 |
193 | P>S | No |
ClinGen gnomAD |
|
|
rs377424496 CA5519460 |
196 | D>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5519462 rs751026758 |
197 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 197 | G>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs968995371 CA208687324 |
198 | D>G | No |
ClinGen TOPMed |
|
|
rs1197889378 CA377086005 |
199 | E>K | No |
ClinGen TOPMed |
|
|
CA377086026 rs1447557614 |
201 | T>I | No |
ClinGen TOPMed |
|
|
rs1262737561 CA377086045 |
204 | E>* | No |
ClinGen gnomAD |
|
|
rs1589891541 CA377086057 |
206 | E>K | No |
ClinGen Ensembl |
|
|
rs374380730 CA5519464 |
208 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA5519465 rs748708014 |
209 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs200677669 CA208687326 |
213 | E>D | No |
ClinGen Ensembl |
|
| TCGA novel | 213 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs370580261 CA5519467 |
216 | T>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1170387258 CA377086136 |
217 | H>P | No |
ClinGen Ensembl |
|
|
rs373975658 CA5519468 |
218 | K>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 218 | K>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs771133391 CA5519469 |
219 | G>E | No |
ClinGen ExAC gnomAD |
|
|
rs367870212 CA5519470 |
221 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs368691919 CA208687327 |
222 | R>K | No |
ClinGen Ensembl |
|
|
rs1203134212 CA377086168 |
222 | R>S | No |
ClinGen gnomAD |
|
|
rs371406997 CA5519471 |
223 | S>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA377086170 rs1301865524 |
223 | S>P | No |
ClinGen gnomAD |
|
|
CA377086183 rs969641778 |
225 | S>C | No |
ClinGen TOPMed gnomAD |
|
|
CA208687329 rs969641778 |
225 | S>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1315375408 CA377086184 |
225 | S>N | No |
ClinGen gnomAD |
|
|
rs1247069906 CA377086258 |
231 | T>I | No |
ClinGen gnomAD |
|
|
rs1415878387 CA377086262 |
232 | T>A | No |
ClinGen TOPMed |
|
|
CA5519475 rs368723146 |
232 | T>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1488399675 CA377086279 |
233 | K>Q | No |
ClinGen gnomAD |
|
|
rs773095084 CA5519476 |
235 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs962076751 CA208687330 |
235 | R>H | No |
ClinGen Ensembl |
|
|
CA377086331 rs1475634883 |
236 | K>R | No |
ClinGen TOPMed |
|
|
rs987850258 CA377086339 |
237 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
rs987850258 CA208687331 |
237 | E>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1318499688 CA377086487 |
238 | V>A | No |
ClinGen Ensembl |
|
|
CA377086478 rs1466605558 |
238 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
CA377086493 rs1368150192 |
239 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA377086490 rs1453294900 |
239 | R>W | No |
ClinGen TOPMed |
|
|
rs773291546 CA5519494 |
241 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA377086580 rs1378689723 |
243 | L>P | No |
ClinGen TOPMed gnomAD |
|
|
CA5519496 rs770685309 |
246 | K>N | No |
ClinGen ExAC gnomAD |
|
|
rs1318265828 CA377086645 |
247 | V>L | No |
ClinGen gnomAD |
|
|
rs1348791820 CA377086674 |
248 | K>R | No |
ClinGen TOPMed |
|
|
CA377086690 rs1270793234 |
249 | K>E | No |
ClinGen gnomAD |
|
|
CA5519498 rs759148421 |
250 | R>* | No |
ClinGen ExAC gnomAD |
|
|
rs767187683 CA5519499 |
250 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 251 | P>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA377086793 rs1474038509 |
253 | V>G | No |
ClinGen gnomAD |
|
|
rs915809786 CA208687417 |
256 | F>W | No |
ClinGen TOPMed |
No associated diseases with Q6NUK4
No regional properties for Q6NUK4
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for Q6NUK4 | |||
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasmic microtubule | Any microtubule in the cytoplasm of a cell. |
| endoplasmic reticulum membrane | The lipid bilayer surrounding the endoplasmic reticulum. |
| endoplasmic reticulum tubular network | A subcompartment of the endoplasmic reticulum consisting of tubules having membranes with high curvature in cross-section. |
| integral component of membrane | The component of a membrane consisting of the gene products and protein complexes having at least some part of their peptide sequence embedded in the hydrophobic region of the membrane. |
| membrane | A lipid bilayer along with all the proteins and protein complexes embedded in it an attached to it. |
1 GO annotations of molecular function
| Name | Definition |
|---|---|
| microtubule binding | Binding to a microtubule, a filament composed of tubulin monomers. |
4 GO annotations of biological process
| Name | Definition |
|---|---|
| cell division | The process resulting in division and partitioning of components of a cell to form more cells; may or may not be accompanied by the physical separation of a cell into distinct, individually membrane-bounded daughter cells. |
| endoplasmic reticulum tubular network organization | A process that is carried out at the cellular level which results in the assembly, arrangement of constituent parts, or disassembly of the endoplasmic reticulum (ER) tubular network. The ER tubular network is the ER part that that has membranes with high curvature in cross-section. |
| mitotic nuclear membrane reassembly | The mitotic cell cycle process involving ESCRTIII that results in reformation of the nuclear envelope after mitotic nuclear division. In organisms undergoing closed mitosis this involves resealing or 'repair' of the nuclear envelope in the nuclear bridge. |
| nuclear envelope organization | A process that is carried out at the cellular level which results in the assembly, arrangement of constituent parts, or disassembly of the nuclear envelope. |
3 homologous proteins in AiPD
| 10 | 20 | 30 | 40 | 50 | 60 |
| MVSWMISRAV | VLVFGMLYPA | YYSYKAVKTK | NVKEYVRWMM | YWIVFALYTV | IETVADQTVA |
| 70 | 80 | 90 | 100 | 110 | 120 |
| WFPLYYELKI | AFVIWLLSPY | TKGASLIYRK | FLHPLLSSKE | REIDDYIVQA | KERGYETMVN |
| 130 | 140 | 150 | 160 | 170 | 180 |
| FGRQGLNLAA | TAAVTAAVKS | QGAITERLRS | FSMHDLTTIQ | GDEPVGQRPY | QPLPEAKKKS |
| 190 | 200 | 210 | 220 | 230 | 240 |
| KPAPSESAGY | GIPLKDGDEK | TDEEAEGPYS | DNEMLTHKGL | RRSQSMKSVK | TTKGRKEVRY |
| 250 | |||||
| GSLKYKVKKR | PQVYF |