P54725
Gene name |
RAD23A |
Protein name |
UV excision repair protein RAD23 homolog A |
Names |
HR23A, hHR23A |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:5886 |
EC number |
|
Protein Class |
|
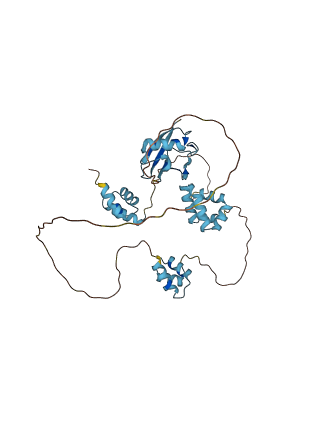
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
17 structures for P54725
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1DV0 | NMR | - | A | 319-363 | PDB |
| 1F4I | NMR | - | A | 319-363 | PDB |
| 1IFY | NMR | - | A | 156-204 | PDB |
| 1OQY | NMR | - | A | 1-363 | PDB |
| 1P98 | NMR | - | A | 1-78 | PDB |
| 1P9D | NMR | - | U | 1-78 | PDB |
| 1QZE | NMR | - | A | 2-363 | PDB |
| 1TP4 | NMR | - | A | 223-317 | PDB |
| 2WYQ | X-ray | 165 A | A | 1-82 | PDB |
| 5XBO | NMR | - | B | 156-204 | PDB |
| 6W2G | X-ray | 110 A | A/B | 155-204 | PDB |
| 6W2H | X-ray | 160 A | A | 155-204 | PDB |
| 6W2I | X-ray | 145 A | A | 155-204 | PDB |
| 6XQI | X-ray | 234 A | F/G | 319-358 | PDB |
| 6XQJ | NMR | - | A | 223-363 | PDB |
| 7TGP | X-ray | 140 A | A | 155-204 | PDB |
| AF-P54725-F1 | Predicted | AlphaFoldDB |
258 variants for P54725
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs1411161505 CA404317709 |
2 | A>S | No |
ClinGen gnomAD |
|
|
CA404317721 rs1426172837 |
4 | T>A | No |
ClinGen TOPMed |
|
|
rs753433859 CA9236116 |
4 | T>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236118 rs778413534 |
5 | I>S | No |
ClinGen ExAC gnomAD |
|
|
CA9236117 rs756873359 |
5 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1312576686 CA404317746 |
8 | K>R | No |
ClinGen gnomAD |
|
|
CA305523208 rs45546235 |
11 | Q>* | No |
ClinGen TOPMed gnomAD |
|
|
CA9236119 rs745342405 |
13 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
rs1411756392 CA404317787 |
14 | T>I | No |
ClinGen gnomAD |
|
|
CA9236120 rs769191860 |
15 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs1234650768 CA404317798 |
16 | K>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA9236122 rs748569014 |
19 | M>I | No |
ClinGen ExAC gnomAD |
|
|
CA404317819 rs1274910168 |
19 | M>V | No |
ClinGen gnomAD |
|
|
rs770051390 CA9236123 |
20 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236124 rs773560731 |
21 | P>A | No |
ClinGen ExAC gnomAD |
|
|
rs771137182 CA9236126 |
22 | D>E | No |
ClinGen ExAC gnomAD |
|
|
CA9236127 rs774608082 |
23 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA305523308 rs759661066 |
24 | T>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236128 rs759661066 |
24 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA404319572 rs1261308140 |
26 | K>R | No |
ClinGen gnomAD |
|
|
rs756611226 CA9236163 |
27 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs141708834 CA9236162 |
27 | V>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA404319678 rs1415818834 |
30 | E>D | No |
ClinGen gnomAD |
|
|
CA404319708 rs1474915283 |
32 | I>T | No |
ClinGen gnomAD |
|
| TCGA novel | 32 | I>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs778316310 CA9236164 |
34 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs749668247 CA9236165 COSM991547 |
38 | R>C | endometrium [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs749668247 CA9236166 |
38 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA404319859 rs1452100267 |
38 | R>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1288610281 CA404319947 |
42 | P>S | No |
ClinGen gnomAD |
|
|
rs746097976 CA9236168 |
43 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA404320358 CA9236175 rs146958349 |
58 | D>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs761578570 CA9236174 |
58 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
| TCGA novel | 59 | V>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA404320442 rs1484093479 |
62 | R>M | No |
ClinGen gnomAD |
|
|
CA9236176 rs772935104 |
64 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs765976759 CA9236178 |
65 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA404320501 rs1182917616 |
66 | I>V | No |
ClinGen gnomAD |
|
|
CA404320515 rs751071968 |
67 | D>H | No |
ClinGen ExAC gnomAD |
|
|
CA9236179 rs751071968 |
67 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA9236180 rs759068052 |
68 | E>K | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 73 | V>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs754368275 CA9236182 |
74 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 78 | K>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA9236202 rs750863392 |
79 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs199689360 CA9236204 |
82 | G>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA404320800 rs1272107992 |
83 | Q>P | No |
ClinGen TOPMed |
|
|
rs1384036048 CA404320817 |
84 | G>A | No |
ClinGen TOPMed |
|
|
rs1384036048 CA404320815 |
84 | G>D | No |
ClinGen TOPMed |
|
|
rs73505386 CA9236205 |
84 | G>R | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1286422563 CA404320837 |
86 | S>A | No |
ClinGen TOPMed |
|
|
CA9236206 rs538175343 |
88 | P>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
| TCGA novel | 89 | P>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 90 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 91 | A>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1340447793 CA404320902 |
91 | A>S | No |
ClinGen TOPMed |
|
|
rs923397006 CA305525592 |
91 | A>V | No |
ClinGen gnomAD |
|
|
rs781356707 CA9236207 |
93 | P>R | No |
ClinGen ExAC gnomAD |
|
|
rs748188762 CA9236208 |
94 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs1329620240 CA404320956 |
95 | A>P | No |
ClinGen TOPMed |
|
|
CA305525611 rs908908485 |
96 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1450454506 CA404320976 |
96 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA404320981 rs1416940431 |
97 | P>A | No |
ClinGen gnomAD |
|
|
rs1168205750 CA404320990 |
97 | P>L | No |
ClinGen TOPMed |
|
|
CA9236210 rs777666414 |
100 | S>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1164807985 CA404321054 |
102 | S>F | No |
ClinGen gnomAD |
|
|
CA9236211 rs375981873 |
104 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs773952708 CA9236213 |
107 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA404321149 rs1437005388 |
109 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
rs771580434 CA9236215 |
110 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA9236216 rs775176242 |
113 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1360056343 CA404321216 |
113 | H>Y | No |
ClinGen gnomAD |
|
| TCGA novel | 115 | P>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA404321273 rs765900414 |
115 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA9236218 rs765900414 |
115 | P>R | No |
ClinGen ExAC gnomAD |
|
|
CA305525701 rs1006063317 |
115 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA9236221 rs766779899 |
118 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs751822670 CA9236222 |
119 | R>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1280661165 CA404321377 |
120 | E>G | No |
ClinGen TOPMed |
|
|
rs1474855136 CA404321393 |
121 | D>N | No |
ClinGen gnomAD |
|
|
CA9236224 rs767606169 |
122 | K>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236225 rs752825559 |
123 | S>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1412540965 CA404321509 |
125 | S>P | No |
ClinGen gnomAD |
|
|
rs777756589 CA9236227 |
129 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs749232374 CA9236228 |
130 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
VAR_016251 rs11558955 CA9236230 |
131 | T>A | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA9236231 rs148187629 |
131 | T>K | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA9236232 rs148187629 |
131 | T>M | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs558256837 CA9236234 |
132 | T>K | No |
ClinGen ExAC gnomAD |
|
|
CA9236233 rs558256837 |
132 | T>M | No |
ClinGen ExAC gnomAD |
|
|
rs776223624 CA9236236 |
134 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA404321711 rs1282647501 |
135 | E>G | No |
ClinGen gnomAD |
|
|
CA9236237 rs763537337 |
136 | S>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236240 rs759798483 |
137 | V>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236239 rs200107326 |
137 | V>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9236238 rs200107326 |
137 | V>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1381401815 CA404321772 |
138 | S>L | No |
ClinGen TOPMed |
|
|
rs200506311 CA9236241 |
139 | G>C | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1186528553 CA404321779 |
139 | G>D | No |
ClinGen gnomAD |
|
|
CA404321849 rs1568453170 |
140 | S>C | No |
ClinGen Ensembl |
|
|
CA404321857 rs1463931095 |
141 | V>L | No |
ClinGen TOPMed |
|
|
rs1306029963 CA404321881 |
142 | P>L | No |
ClinGen gnomAD |
|
|
CA9236257 rs760016308 |
143 | S>P | No |
ClinGen ExAC gnomAD |
|
|
CA9236259 rs141369284 |
145 | G>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA9236260 rs369026746 |
147 | S>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9236262 rs753994476 CA9236263 |
148 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs1055842383 CA305526093 |
149 | R>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs765282021 CA9236264 |
149 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA404321966 rs201128109 |
152 | D>E | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA9236266 rs758351125 |
153 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs376900039 CA9236267 |
153 | A>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9236269 rs200238909 |
154 | A>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs780970129 CA9236270 |
155 | S>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA305526165 rs1030984404 |
156 | T>K | No |
ClinGen gnomAD |
|
|
rs1030984404 CA404322086 |
156 | T>M | No |
ClinGen gnomAD |
|
|
rs1030984404 CA404322085 |
156 | T>R | No |
ClinGen gnomAD |
|
|
rs150788485 CA9236291 |
159 | T>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1160441898 CA404322236 |
161 | S>F | No |
ClinGen gnomAD |
|
|
rs748795390 CA9236293 |
165 | T>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA9236295 rs780521795 |
166 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs538880947 CA9236296 |
168 | T>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA404322357 rs1309037665 |
171 | M>I | No |
ClinGen gnomAD |
|
|
rs547432572 CA9236298 |
171 | M>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA404322350 rs1354230142 |
171 | M>V | No |
ClinGen TOPMed gnomAD |
|
|
CA404322364 rs1314975685 |
173 | M>V | No |
ClinGen gnomAD |
|
|
rs1256385036 CA404322377 |
174 | G>A | No |
ClinGen gnomAD |
|
|
rs1237972905 CA404322373 |
174 | G>S | No |
ClinGen gnomAD |
|
|
rs778646826 CA305526468 |
176 | E>K | No |
ClinGen Ensembl |
|
|
rs1348809848 CA404322395 |
177 | R>* | No |
ClinGen gnomAD |
|
|
CA9236300 rs200493290 |
177 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs565619875 CA9236302 |
178 | E>A | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9236303 rs565619875 |
178 | E>G | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
VAR_020377 rs4987203 CA9236305 |
179 | R>Q | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA9236304 rs774428190 |
179 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA404322407 rs1417722670 |
180 | V>I | No |
ClinGen gnomAD |
|
|
CA9236307 rs554597904 |
181 | V>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9236308 rs755757631 |
182 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 183 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA404322453 rs1568453423 |
187 | S>R | No |
ClinGen Ensembl |
|
|
rs756752141 CA9236311 |
187 | S>T | No |
ClinGen ExAC |
|
|
rs778325372 CA9236312 |
190 | N>T | No |
ClinGen ExAC gnomAD |
|
|
rs1371016644 CA404322486 |
192 | H>P | No |
ClinGen TOPMed gnomAD |
|
|
rs747524787 COSM1711887 CA9236313 |
193 | R>* | skin [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs755462298 CA9236314 |
193 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA404322498 rs1372869284 |
194 | A>G | No |
ClinGen gnomAD |
|
|
CA404322499 COSM233228 rs1372869284 |
194 | A>V | skin [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA404322503 rs1268388032 |
195 | V>A | No |
ClinGen TOPMed |
|
|
rs748513382 CA9236316 |
195 | V>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA305527961 rs769180661 |
198 | L>V | No |
ClinGen TOPMed gnomAD |
|
|
VAR_016252 CA9236317 rs4987202 |
200 | T>M | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA404322562 rs1218017273 |
203 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA9236343 rs779167454 |
204 | G>V | No |
ClinGen ExAC |
|
|
CA404322574 rs1225395350 |
205 | S>N | No |
ClinGen gnomAD |
|
|
rs139644856 CA9236344 |
206 | P>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA gnomAD |
|
CA305528200 rs977516182 |
207 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA305528202 rs924695646 |
208 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
CA305528208 rs868641497 |
209 | E>K | No |
ClinGen gnomAD |
|
|
CA404322596 rs868641497 |
209 | E>Q | No |
ClinGen gnomAD |
|
|
CA9236349 rs776358401 |
211 | G>D | No |
ClinGen ExAC gnomAD |
|
|
rs768506976 CA9236348 |
211 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236350 rs761483338 |
212 | S>F | No |
ClinGen ExAC gnomAD |
|
|
CA404322654 rs1205455830 |
217 | Q>R | No |
ClinGen TOPMed |
|
|
rs531597926 CA9236353 |
219 | S>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9236352 rs542397046 |
219 | S>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs756523126 CA9236356 |
220 | E>A | No |
ClinGen ExAC gnomAD |
|
|
rs756523126 CA404322671 |
220 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA9236358 COSM1390693 rs778306837 |
222 | P>L | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
CA9236357 rs778306837 |
222 | P>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1357601475 CA404322685 |
222 | P>S | No |
ClinGen TOPMed |
|
| TCGA novel | 223 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA404322692 rs1313514139 |
223 | A>V | No |
ClinGen gnomAD |
|
|
rs148708384 CA9236361 |
224 | T>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA305528366 rs11558954 |
227 | A>V | No |
ClinGen Ensembl |
|
|
rs1163586176 CA404322742 |
229 | E>A | No |
ClinGen gnomAD |
|
|
CA404322743 rs1366709657 |
229 | E>D | No |
ClinGen gnomAD |
|
|
rs1237392203 CA404322749 |
230 | N>S | No |
ClinGen gnomAD |
|
|
rs1237392203 CA404322748 |
230 | N>T | No |
ClinGen gnomAD |
|
|
CA305528368 rs922436091 |
231 | P>T | No |
ClinGen gnomAD |
|
| TCGA novel | 232 | L>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs41561218 CA305528376 |
233 | E>* | No |
ClinGen Ensembl |
|
|
rs1229162656 CA404322779 |
235 | L>V | No |
ClinGen Ensembl |
|
|
CA9236386 rs754956151 |
236 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236385 rs747026594 |
236 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs910578874 CA305528408 |
237 | D>H | No |
ClinGen Ensembl |
|
|
CA9236387 rs781094089 |
237 | D>V | No |
ClinGen ExAC gnomAD |
|
|
rs1400116042 CA404322809 |
240 | Q>P | No |
ClinGen gnomAD |
|
|
CA9236389 rs769581525 |
243 | N>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236390 rs772826183 |
244 | M>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201928561 CA9236392 |
245 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201928561 CA9236393 |
245 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA404322846 rs1270308155 |
245 | R>W | No |
ClinGen gnomAD |
|
|
rs1599668535 CA404322861 |
247 | V>G | No |
ClinGen Ensembl |
|
|
rs1219918662 CA404322857 |
247 | V>L | No |
ClinGen TOPMed |
|
|
rs547674173 CA9236395 |
249 | Q>E | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs267605293 CA305528472 |
252 | P>S | No |
ClinGen Ensembl |
|
|
rs777277641 CA404322902 |
253 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs777277641 CA9236397 |
253 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236400 rs750711569 |
257 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs758684522 CA9236401 |
260 | Q>R | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 261 | Q>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs2242518 CA305528492 |
261 | Q>R | No |
ClinGen Ensembl |
|
|
rs766487138 CA9236402 |
264 | Q>K | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 264 | Q>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA404323000 rs1462311750 |
269 | L>H | No |
ClinGen gnomAD |
|
|
CA404323008 rs1167495427 |
270 | L>F | No |
ClinGen gnomAD |
|
| TCGA novel | 271 | Q>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA305531337 rs151314000 |
273 | I>V | No |
ClinGen ESP TOPMed |
|
|
CA9236425 rs760520920 |
275 | R>L | No |
ClinGen ExAC gnomAD |
|
|
CA9236424 rs760520920 |
275 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
CA305531342 rs1046715911 |
275 | R>W | No |
ClinGen TOPMed gnomAD |
|
|
CA305531388 rs1050265071 |
277 | Q>* | No |
ClinGen Ensembl |
|
|
CA305531398 rs902501491 |
278 | E>G | No |
ClinGen TOPMed |
|
|
rs778878178 CA9236428 |
278 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA9236429 rs752902956 |
284 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs778120001 CA9236431 |
287 | P>R | No |
ClinGen ExAC gnomAD |
|
|
CA9236432 rs747360004 |
288 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA9236434 rs771465178 |
290 | E>G | No |
ClinGen ExAC gnomAD |
|
|
rs1344742558 CA404323158 |
291 | L>V | No |
ClinGen gnomAD |
|
|
rs781751879 CA9236435 |
292 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs887596156 CA305531492 |
293 | D>Y | No |
ClinGen Ensembl |
|
|
rs773739832 CA9236440 |
296 | D>V | No |
ClinGen ExAC gnomAD |
|
|
CA9236441 rs761453504 |
297 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs1053804917 CA305531552 |
299 | G>E | No |
ClinGen TOPMed |
|
|
rs772899507 CA9236443 |
299 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 301 | V>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA9236446 rs753723172 |
303 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA305531590 rs1018065445 |
304 | I>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1599671529 CA404323237 |
304 | I>V | No |
ClinGen Ensembl |
|
|
rs1213042423 CA404323245 |
305 | G>E | No |
ClinGen gnomAD |
|
|
CA404323259 rs1401343234 |
307 | E>A | No |
ClinGen TOPMed |
|
|
CA404323275 rs1483231608 |
309 | P>L | No |
ClinGen gnomAD |
|
|
rs752710312 CA9236449 |
311 | M>I | No |
ClinGen ExAC |
|
|
CA404323308 rs758558966 |
314 | I>F | No |
ClinGen ExAC gnomAD |
|
|
CA9236450 rs758558966 |
314 | I>L | No |
ClinGen ExAC gnomAD |
|
|
rs758558966 CA9236451 |
314 | I>V | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 317 | T>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs751865333 CA9236452 |
317 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA404323332 rs781702169 |
318 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA9236455 rs746311517 |
318 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236454 rs781702169 |
318 | P>T | No |
ClinGen ExAC gnomAD |
|
|
CA404323339 rs1568455387 |
319 | Q>P | No |
ClinGen Ensembl |
|
|
TCGA novel CA9236459 rs747588545 |
320 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ExAC TOPMed gnomAD NCI-TCGA |
|
rs772809602 CA9236460 |
322 | E>A | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 322 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 323 | A>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 325 | E>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs776319080 CA9236485 |
329 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA404323468 rs1187715755 |
336 | L>V | No |
ClinGen gnomAD |
|
|
rs916747485 CA305531830 |
340 | A>V | No |
ClinGen TOPMed |
|
|
rs762963923 CA9236489 |
343 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 347 | N>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 349 | N>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA404323601 rs767826146 |
354 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs1399995264 CA404323613 |
357 | S>G | No |
ClinGen gnomAD |
|
|
rs775051740 CA305531878 |
357 | S>N | No |
ClinGen Ensembl |
|
|
rs756392712 CA404323658 |
362 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9236496 rs766788097 |
363 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA404323660 rs766788097 |
363 | E>Q | No |
ClinGen ExAC gnomAD |
No associated diseases with P54725
1 regional properties for P54725
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Small GTP-binding protein domain | 7 - 162 | IPR005225 |
8 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| Golgi apparatus | A membrane-bound cytoplasmic organelle of the endomembrane system that further processes the core oligosaccharides (e.g. N-glycans) added to proteins in the endoplasmic reticulum and packages them into membrane-bound vesicles. The Golgi apparatus operates at the intersection of the secretory, lysosomal, and endocytic pathways. |
| intracellular membrane-bounded organelle | Organized structure of distinctive morphology and function, bounded by a single or double lipid bilayer membrane and occurring within the cell. Includes the nucleus, mitochondria, plastids, vacuoles, and vesicles. Excludes the plasma membrane. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| proteasome complex | A large multisubunit complex which catalyzes protein degradation, found in eukaryotes, archaea and some bacteria. In eukaryotes, this complex consists of the barrel shaped proteasome core complex and one or two associated proteins or complexes that act in regulating entry into or exit from the core. |
| protein-containing complex | A stable assembly of two or more macromolecules, i.e. proteins, nucleic acids, carbohydrates or lipids, in which at least one component is a protein and the constituent parts function together. |
7 GO annotations of molecular function
| Name | Definition |
|---|---|
| damaged DNA binding | Binding to damaged DNA. |
| kinase binding | Binding to a kinase, any enzyme that catalyzes the transfer of a phosphate group. |
| polyubiquitin modification-dependent protein binding | Binding to a protein upon poly-ubiquitination of the target protein. |
| proteasome binding | Binding to a proteasome, a large multisubunit protein complex that catalyzes protein degradation. |
| single-stranded DNA binding | Binding to single-stranded DNA. |
| ubiquitin binding | Binding to ubiquitin, a protein that when covalently bound to other cellular proteins marks them for proteolytic degradation. |
| ubiquitin-specific protease binding | Binding to a ubiquitin-specific protease. |
7 GO annotations of biological process
| Name | Definition |
|---|---|
| nucleotide-excision repair | A DNA repair process in which a small region of the strand surrounding the damage is removed from the DNA helix as an oligonucleotide. The small gap left in the DNA helix is filled in by the sequential action of DNA polymerase and DNA ligase. Nucleotide excision repair recognizes a wide range of substrates, including damage caused by UV irradiation (pyrimidine dimers and 6-4 photoproducts) and chemicals (intrastrand cross-links and bulky adducts). |
| positive regulation of cell cycle | Any process that activates or increases the rate or extent of progression through the cell cycle. |
| positive regulation of proteasomal ubiquitin-dependent protein catabolic process | Any process that activates or increases the frequency, rate or extent of the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of ubiquitin, and mediated by the proteasome. |
| positive regulation of viral genome replication | Any process that activates or increases the frequency, rate or extent of viral genome replication. |
| proteasome-mediated ubiquitin-dependent protein catabolic process | The chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of ubiquitin, and mediated by the proteasome. |
| protein destabilization | Any process that decreases the stability of a protein, making it more vulnerable to degradative processes or aggregation. |
| regulation of proteasomal ubiquitin-dependent protein catabolic process | Any process that modulates the frequency, rate or extent of the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of ubiquitin, and mediated by the proteasome. |
3 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P32628 | RAD23 | UV excision repair protein RAD23 | Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) | PR |
| A3KMV2 | RAD23A | UV excision repair protein RAD23 homolog A | Bos taurus (Bovine) | PR |
| P54726 | Rad23a | UV excision repair protein RAD23 homolog A | Mus musculus (Mouse) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAVTITLKTL | QQQTFKIRME | PDETVKVLKE | KIEAEKGRDA | FPVAGQKLIY | AGKILSDDVP |
| 70 | 80 | 90 | 100 | 110 | 120 |
| IRDYRIDEKN | FVVVMVTKTK | AGQGTSAPPE | ASPTAAPESS | TSFPPAPTSG | MSHPPPAARE |
| 130 | 140 | 150 | 160 | 170 | 180 |
| DKSPSEESAP | TTSPESVSGS | VPSSGSSGRE | EDAASTLVTG | SEYETMLTEI | MSMGYERERV |
| 190 | 200 | 210 | 220 | 230 | 240 |
| VAALRASYNN | PHRAVEYLLT | GIPGSPEPEH | GSVQESQVSE | QPATEAAGEN | PLEFLRDQPQ |
| 250 | 260 | 270 | 280 | 290 | 300 |
| FQNMRQVIQQ | NPALLPALLQ | QLGQENPQLL | QQISRHQEQF | IQMLNEPPGE | LADISDVEGE |
| 310 | 320 | 330 | 340 | 350 | 360 |
| VGAIGEEAPQ | MNYIQVTPQE | KEAIERLKAL | GFPESLVIQA | YFACEKNENL | AANFLLSQNF |
| DDE |