P49427
Gene name |
CDC34 (UBCH3, UBE2R1) |
Protein name |
Ubiquitin-conjugating enzyme E2 R1 |
Names |
(E3-independent) E2 ubiquitin-conjugating enzyme R1, E2 ubiquitin-conjugating enzyme R1, Ubiquitin-conjugating enzyme E2-32 kDa complementing, Ubiquitin-conjugating enzyme E2-CDC34, Ubiquitin-protein ligase R1 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:997 |
EC number |
2.3.2.23: Aminoacyltransferases |
Protein Class |
|
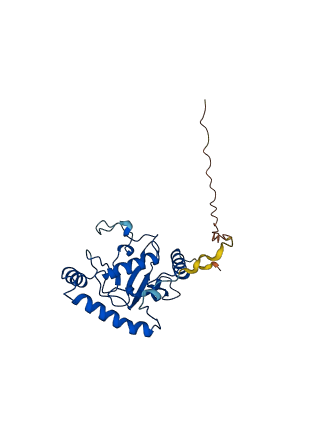
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
5 structures for P49427
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 2OB4 | X-ray | 240 A | A | 7-184 | PDB |
| 3RZ3 | X-ray | 230 A | A/B/C/D | 7-184 | PDB |
| 4MDK | X-ray | 261 A | A/B/C/D | 7-184 | PDB |
| 7M2K | X-ray | 247 A | A/C/E/G | 7-184 | PDB |
| AF-P49427-F1 | Predicted | AlphaFoldDB |
168 variants for P49427
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs748895553 CA9016733 |
3 | R>P | No |
ClinGen ExAC gnomAD |
|
|
rs772391519 CA9016734 |
4 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs143937615 CA9016735 |
6 | V>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs747285861 CA9016736 |
7 | P>R | No |
ClinGen ExAC gnomAD |
|
|
rs1490829755 CA402858991 |
7 | P>S | No |
ClinGen gnomAD |
|
|
rs1160918318 CA402859081 |
12 | A>T | No |
ClinGen TOPMed |
|
|
rs1419118549 CA402859097 |
12 | A>V | No |
ClinGen TOPMed |
|
| TCGA novel | 14 | L>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1254177049 CA402859154 |
17 | L>F | No |
ClinGen TOPMed |
|
|
CA402859164 rs1188580719 |
17 | L>P | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA303892264 rs866955717 |
18 | K>R | No |
ClinGen gnomAD |
|
| TCGA novel | 18 | K>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs777031141 CA9016738 |
22 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA402859271 rs1425868708 |
23 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA402859272 rs1425868708 |
23 | E>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA9016740 rs765510335 |
24 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9016739 rs759742031 |
24 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA402859354 rs1301290037 |
29 | R>L | No |
ClinGen TOPMed |
|
|
CA402859378 rs1373021081 |
32 | L>V | No |
ClinGen TOPMed |
|
|
CA9016744 rs148639611 |
35 | E>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9016746 rs757298312 |
36 | G>D | No |
ClinGen ExAC gnomAD |
|
|
rs975917752 CA303892296 |
36 | G>S | No |
ClinGen Ensembl |
|
|
rs767394877 CA9016747 |
37 | D>E | No |
ClinGen ExAC gnomAD |
|
|
CA9016749 rs755819680 |
38 | L>R | No |
ClinGen ExAC gnomAD |
|
|
rs750297342 CA9016748 |
38 | L>V | No |
ClinGen ExAC gnomAD |
|
|
rs778328367 CA9016753 |
44 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1403138220 CA402859538 |
46 | F>L | No |
ClinGen gnomAD |
|
|
rs1394129659 CA402859546 |
47 | G>R | No |
ClinGen TOPMed |
|
|
CA402859582 rs1345368372 |
49 | P>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
| TCGA novel | 49 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 52 | Y>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA9016758 rs746240753 |
56 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA9016781 rs768815065 |
61 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs774565109 CA9016782 |
61 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9016783 rs761984062 |
63 | K>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA9016784 rs146663310 |
66 | I>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1003265423 CA303895298 |
67 | D>Y | No |
ClinGen Ensembl |
|
|
CA402861696 rs1305056777 |
73 | P>S | No |
ClinGen gnomAD |
|
|
rs1035638093 CA303895312 |
74 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA9016787 rs375521090 |
76 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1568330110 CA402861727 |
76 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
| TCGA novel | 80 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 82 | W>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1600423052 CA402861813 |
83 | H>P | No |
ClinGen Ensembl |
|
|
CA9016840 rs765674047 |
92 | V>L | No |
ClinGen ExAC gnomAD |
|
|
CA9016839 rs765674047 |
92 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs757316651 CA9016844 |
97 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA9016845 rs200517034 |
98 | H>P | No |
ClinGen ExAC gnomAD |
|
|
rs1403833110 CA402862091 |
99 | P>L | No |
ClinGen TOPMed |
|
|
rs1309948530 CA402862101 |
100 | P>L | No |
ClinGen gnomAD |
|
|
CA402862120 rs1332343229 |
101 | V>G | No |
ClinGen gnomAD |
|
|
rs146527192 CA9016849 |
101 | V>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1326670665 CA402862132 |
102 | D>E | No |
ClinGen TOPMed gnomAD |
|
|
CA402862123 rs768235050 |
102 | D>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9016850 rs768235050 |
102 | D>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402862137 rs1225072936 |
103 | D>N | No |
ClinGen gnomAD |
|
|
rs773893349 CA9016851 |
104 | P>H | No |
ClinGen ExAC gnomAD |
|
|
CA9016854 rs772825347 |
107 | G>A | No |
ClinGen ExAC gnomAD |
|
|
rs1453268355 CA402862220 |
108 | E>K | No |
ClinGen gnomAD |
|
|
rs1220347807 CA402862346 |
117 | T>M | No |
ClinGen TOPMed |
|
|
CA9016857 rs753053260 |
118 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
rs1464970251 CA402862377 |
119 | N>T | No |
ClinGen gnomAD |
|
|
rs1274501561 CA402862388 |
120 | V>I | No |
ClinGen TOPMed |
|
|
rs376731647 CA402862403 |
121 | R>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA402862416 rs1306892010 |
121 | R>T | No |
ClinGen gnomAD |
|
|
rs564209470 CA9016909 |
123 | I>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
| TCGA novel | 124 | L>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA402862942 rs11557525 |
128 | I>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1218171541 CA402862993 |
133 | E>K | No |
ClinGen gnomAD |
|
|
CA402863074 rs1600425607 |
137 | F>L | No |
ClinGen Ensembl |
|
|
rs745378933 CA9016918 |
137 | F>S | No |
ClinGen ExAC gnomAD |
|
| rs749435711 | 137 | F>missing | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA303896888 rs992229990 |
139 | P>S | No |
ClinGen Ensembl |
|
|
CA402863102 rs1462106053 |
140 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs1568330806 CA402863190 |
144 | A>T | No |
ClinGen Ensembl |
|
|
rs1412183232 CA402863223 |
146 | V>M | No |
ClinGen gnomAD |
|
|
CA402863300 rs1431255257 |
149 | R>K | No |
ClinGen gnomAD |
|
|
rs1414962637 CA402863304 |
149 | R>S | No |
ClinGen gnomAD |
|
|
rs549379010 CA9016925 |
150 | K>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1186468318 CA402863444 |
157 | K>N | No |
ClinGen TOPMed |
|
|
rs1600425711 CA402863449 |
158 | D>H | No |
ClinGen Ensembl |
|
|
CA9016929 rs373877648 |
159 | R>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9016928 rs373877648 |
159 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 159 | R>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA9016930 rs368089180 |
162 | T>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9016931 rs763970240 |
165 | I>T | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 166 | R>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA402865849 rs1272691409 |
167 | K>E | No |
ClinGen gnomAD |
|
|
rs1381254137 CA402865853 |
167 | K>M | No |
ClinGen TOPMed |
|
|
rs956067449 CA402865888 |
169 | V>F | No |
ClinGen Ensembl |
|
|
rs956067449 CA303899744 |
169 | V>I | No |
ClinGen Ensembl |
|
|
CA303899745 rs1050890129 |
173 | K>M | No |
ClinGen TOPMed |
|
|
rs1267183464 CA402866002 |
175 | D>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1267183464 CA402866003 |
175 | D>V | No |
ClinGen TOPMed gnomAD |
|
|
rs757696666 CA9016995 |
176 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA303899752 rs917167001 |
176 | A>V | No |
ClinGen Ensembl |
|
|
rs372269784 CA9016997 |
177 | E>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs756462163 CA9016998 |
178 | R>H | No |
ClinGen ExAC gnomAD |
|
|
rs756462163 CA402866047 |
178 | R>L | No |
ClinGen ExAC gnomAD |
|
|
rs1293891976 CA402866079 |
180 | G>C | No |
ClinGen TOPMed gnomAD |
|
|
rs1293891976 CA402866081 |
180 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
CA303899785 rs76720850 |
181 | V>L | No |
ClinGen ESP ExAC gnomAD |
|
|
rs76720850 CA9017000 |
181 | V>M | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1600432311 CA402866110 |
182 | K>Q | No |
ClinGen Ensembl |
|
|
rs748241028 CA9017003 |
184 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA402866189 rs1227684760 |
186 | T>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA402866193 rs1323726074 |
187 | L>V | No |
ClinGen gnomAD |
|
|
rs1265199250 CA402866210 |
188 | A>T | No |
ClinGen gnomAD |
|
|
CA9017008 rs776469357 |
189 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs764877152 CA402866293 |
191 | C>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9017009 rs759186036 |
191 | C>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs774925566 CA9017011 |
192 | V>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA9017013 rs762396271 |
194 | T>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9017012 rs762396271 |
194 | T>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402866458 rs1257631281 |
195 | K>Q | No |
ClinGen Ensembl |
|
|
CA402866541 rs1165104526 |
196 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
CA402866534 rs1165104526 |
196 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs147105441 CA9017017 |
196 | A>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9017019 rs779289790 |
197 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 197 | P>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1167681324 CA402866589 |
198 | A>S | No |
ClinGen TOPMed |
|
|
rs1167681324 CA402866588 |
198 | A>T | No |
ClinGen TOPMed |
|
|
rs375818778 CA9017021 |
198 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9017027 rs377177218 |
200 | D>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs556391590 CA9017025 |
200 | D>N | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs762703606 CA9017029 |
201 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9017028 rs201584025 |
201 | E>K | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA402866739 rs762703606 |
201 | E>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402866817 rs1252854872 |
202 | G>V | No |
ClinGen TOPMed |
|
|
CA402866937 CA9017034 rs542019154 |
206 | F>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs369990220 CA9017035 |
207 | Y>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA402867011 rs1161096646 |
208 | D>G | No |
ClinGen gnomAD |
|
|
CA9017038 rs200761288 |
208 | D>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs200761288 CA9017037 |
208 | D>N | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA402867045 rs1299123897 |
209 | D>E | No |
ClinGen TOPMed |
|
|
rs777711920 CA9017040 |
209 | D>N | No |
ClinGen ExAC |
|
|
rs777711920 CA9017042 |
209 | D>Y | No |
ClinGen ExAC |
|
|
CA402867070 rs1156883031 |
210 | Y>* | No |
ClinGen gnomAD |
|
|
rs751666566 CA9017043 |
210 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1360855924 CA402867100 |
211 | Y>* | No |
ClinGen TOPMed gnomAD |
|
|
rs1400107184 CA402867082 |
211 | Y>C | No |
ClinGen gnomAD |
|
|
CA402867133 rs1302352352 |
212 | E>D | No |
ClinGen gnomAD |
|
|
CA9017044 rs757087028 |
212 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1411986019 CA402867165 |
213 | D>G | No |
ClinGen gnomAD |
|
|
rs1353727792 CA402867140 |
213 | D>N | No |
ClinGen TOPMed gnomAD |
|
|
CA402867203 rs1350306457 |
214 | G>C | No |
ClinGen gnomAD |
|
|
rs1034014803 CA303899936 |
214 | G>D | No |
ClinGen TOPMed |
|
|
CA9017046 rs745626145 |
215 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9017047 rs563776588 |
216 | V>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1270949054 CA402867312 |
217 | E>G | No |
ClinGen TOPMed |
|
|
CA402867302 rs1254971128 |
217 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA9017050 rs748875983 |
218 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA9017049 rs531877075 |
218 | E>K | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA402867319 rs531877075 |
218 | E>Q | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs550012804 CA9017051 |
219 | E>K | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs773664509 CA9017052 |
220 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9017054 rs771514074 |
221 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA402867542 rs1338082998 |
223 | C>R | No |
ClinGen TOPMed |
|
|
CA9017058 rs568742634 CA303899976 |
225 | G>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1175449924 CA402867638 |
226 | D>N | No |
ClinGen gnomAD |
|
|
CA303899986 VAR_021277 rs16990650 |
227 | D>H | No |
ClinGen UniProt ExAC TOPMed dbSNP gnomAD |
|
|
CA9017060 rs16990650 |
227 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201715065 CA9017061 |
228 | E>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402867701 rs1350136168 |
228 | E>G | No |
ClinGen gnomAD |
|
|
CA9017064 rs751546350 |
231 | S>C | No |
ClinGen ExAC gnomAD |
|
|
CA9017065 rs140384237 |
232 | G>D | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs750335335 CA9017067 |
233 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs376164577 CA9017070 |
235 | E>D | No |
ClinGen ESP ExAC gnomAD |
No associated diseases with P49427
Functions
| Description | ||
|---|---|---|
| EC Number | 2.3.2.23 | Aminoacyltransferases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
4 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nuclear speck | A discrete extra-nucleolar subnuclear domain, 20-50 in number, in which splicing factors are seen to be localized by immunofluorescence microscopy. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
3 GO annotations of molecular function
| Name | Definition |
|---|---|
| ATP binding | Binding to ATP, adenosine 5'-triphosphate, a universally important coenzyme and enzyme regulator. |
| ubiquitin conjugating enzyme activity | Isoenergetic transfer of ubiquitin from one protein to another via the reaction X-ubiquitin + Y -> Y-ubiquitin + X, where both the X-ubiquitin and Y-ubiquitin linkages are thioester bonds between the C-terminal glycine of ubiquitin and a sulfhydryl side group of a cysteine residue. |
| ubiquitin-protein transferase activity | Catalysis of the transfer of ubiquitin from one protein to another via the reaction X-Ub + Y --> Y-Ub + X, where both X-Ub and Y-Ub are covalent linkages. |
13 GO annotations of biological process
| Name | Definition |
|---|---|
| cellular response to interferon-beta | Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of an interferon-beta stimulus. Interferon-beta is a type I interferon. |
| DNA replication initiation | The process in which DNA-dependent DNA replication is started; this begins with the ATP dependent loading of an initiator complex onto the DNA, this is followed by DNA melting and helicase activity. In bacteria, the gene products that enable the helicase activity are loaded after the initial melting and in archaea and eukaryotes, the gene products that enable the helicase activity are inactive when they are loaded and subsequently activate. |
| G1/S transition of mitotic cell cycle | The mitotic cell cycle transition by which a cell in G1 commits to S phase. The process begins with the build up of G1 cyclin-dependent kinase (G1 CDK), resulting in the activation of transcription of G1 cyclins. The process ends with the positive feedback of the G1 cyclins on the G1 CDK which commits the cell to S phase, in which DNA replication is initiated. |
| negative regulation of cAMP-mediated signaling | Any process which stops, prevents, or reduces the frequency, rate or extent of cAMP-mediated signaling. |
| positive regulation of inclusion body assembly | Any process that increases the rate, frequency, or extent of inclusion body assembly. Inclusion body assembly is the aggregation, arrangement and bonding together of a set of components to form an inclusion body. |
| positive regulation of neuron apoptotic process | Any process that activates or increases the frequency, rate or extent of cell death of neurons by apoptotic process. |
| proteasome-mediated ubiquitin-dependent protein catabolic process | The chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of ubiquitin, and mediated by the proteasome. |
| protein K48-linked ubiquitination | A protein ubiquitination process in which a polymer of ubiquitin, formed by linkages between lysine residues at position 48 of the ubiquitin monomers, is added to a protein. K48-linked ubiquitination targets the substrate protein for degradation. |
| protein modification process | The covalent alteration of one or more amino acids occurring in proteins, peptides and nascent polypeptides (co-translational, post-translational modifications). Includes the modification of charged tRNAs that are destined to occur in a protein (pre-translation modification). |
| protein polyubiquitination | Addition of multiple ubiquitin groups to a protein, forming a ubiquitin chain. |
| protein ubiquitination | The process in which one or more ubiquitin groups are added to a protein. |
| response to growth factor | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a growth factor stimulus. |
| ubiquitin-dependent protein catabolic process | The chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of a ubiquitin group, or multiple ubiquitin groups, to the protein. |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MARPLVPSSQ | KALLLELKGL | QEEPVEGFRV | TLVDEGDLYN | WEVAIFGPPN | TYYEGGYFKA |
| 70 | 80 | 90 | 100 | 110 | 120 |
| RLKFPIDYPY | SPPAFRFLTK | MWHPNIYETG | DVCISILHPP | VDDPQSGELP | SERWNPTQNV |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RTILLSVISL | LNEPNTFSPA | NVDASVMYRK | WKESKGKDRE | YTDIIRKQVL | GTKVDAERDG |
| 190 | 200 | 210 | 220 | 230 | |
| VKVPTTLAEY | CVKTKAPAPD | EGSDLFYDDY | YEDGEVEEEA | DSCFGDDEDD | SGTEES |