P19388
Gene name |
POLR2E |
Protein name |
DNA-directed RNA polymerases I, II, and III subunit RPABC1 |
Names |
RNA polymerases I, II, and III subunit ABC1, DNA-directed RNA polymerase II 23 kDa polypeptide, DNA-directed RNA polymerase II subunit E, RPB5 homolog, XAP4 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:5434 |
EC number |
|
Protein Class |
|
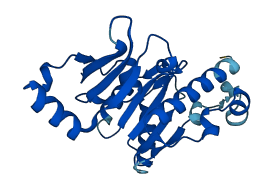
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
34 structures for P19388
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 5IY6 | EM | 720 A | E | 1-210 | PDB |
| 5IY7 | EM | 860 A | E | 1-210 | PDB |
| 5IY8 | EM | 790 A | E | 1-210 | PDB |
| 5IY9 | EM | 630 A | E | 1-210 | PDB |
| 5IYA | EM | 540 A | E | 1-210 | PDB |
| 5IYB | EM | 390 A | E | 1-210 | PDB |
| 5IYC | EM | 390 A | E | 1-210 | PDB |
| 5IYD | EM | 390 A | E | 1-210 | PDB |
| 6DRD | EM | 390 A | E | 1-210 | PDB |
| 6O9L | EM | 720 A | E | 1-210 | PDB |
| 6XRE | EM | 460 A | E | 1-210 | PDB |
| 7A6H | EM | 330 A | E | 1-210 | PDB |
| 7AE1 | EM | 280 A | E | 1-210 | PDB |
| 7AE3 | EM | 310 A | E | 1-210 | PDB |
| 7AEA | EM | 340 A | E | 1-210 | PDB |
| 7AST | EM | 400 A | F | 1-210 | PDB |
| 7D58 | EM | 290 A | E | 1-210 | PDB |
| 7D59 | EM | 310 A | E | 1-210 | PDB |
| 7DN3 | EM | 350 A | E | 1-210 | PDB |
| 7DU2 | EM | 335 A | E | 1-210 | PDB |
| 7FJI | EM | 360 A | E | 1-210 | PDB |
| 7FJJ | EM | 360 A | E | 1-210 | PDB |
| 7LBM | EM | 480 A | E | 1-210 | PDB |
| 7OB9 | EM | 270 A | E | 1-210 | PDB |
| 7OBA | EM | 310 A | E | 1-210 | PDB |
| 7OBB | EM | 330 A | E | 1-210 | PDB |
| 7VBA | EM | 289 A | E | 1-210 | PDB |
| 7VBB | EM | 281 A | E | 1-210 | PDB |
| 7VBC | EM | 301 A | E | 1-210 | PDB |
| 8A43 | EM | 409 A | E | 1-210 | PDB |
| 8ITY | EM | 390 A | E | 1-210 | PDB |
| 8IUE | EM | 410 A | E | 1-210 | PDB |
| 8IUH | EM | 340 A | E | 1-210 | PDB |
| AF-P19388-F1 | Predicted | AlphaFoldDB |
205 variants for P19388
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA403039726 rs1241827029 |
2 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs779992371 CA403039700 |
3 | D>A | No |
ClinGen ExAC gnomAD |
|
|
CA304051048 rs372837141 |
3 | D>E | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA9037070 rs779992371 |
3 | D>V | No |
ClinGen ExAC gnomAD |
|
|
rs148531513 CA9037071 |
3 | D>Y | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1168315618 CA403039677 |
4 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
CA403039681 rs1427372746 |
4 | E>G | No |
ClinGen TOPMed |
|
|
rs758201698 CA9037069 |
6 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 6 | E>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA9037068 rs750105802 |
6 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403039624 rs1456332319 |
7 | T>M | No |
ClinGen gnomAD |
|
|
CA9037067 rs778381561 |
7 | T>P | No |
ClinGen ExAC gnomAD |
|
|
CA403039592 rs531296731 |
8 | Y>* | No |
ClinGen TOPMed gnomAD |
|
|
rs144085491 CA304051025 |
9 | R>Q | No |
ClinGen ESP |
|
|
CA9037065 rs753258227 |
9 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs760026410 CA9037063 |
10 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA9037061 rs570436933 |
13 | I>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1362799688 CA403039522 |
13 | I>V | No |
ClinGen TOPMed |
|
|
CA403039474 rs1207334502 |
14 | R>C | No |
ClinGen TOPMed gnomAD |
|
|
rs748732500 CA304051005 |
15 | K>E | No |
ClinGen Ensembl |
|
|
rs748732500 CA403039464 |
15 | K>Q | No |
ClinGen Ensembl |
|
|
CA9037060 rs149504848 |
15 | K>R | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA9037058 rs376699715 |
17 | I>V | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA9037056 rs776836766 |
18 | M>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403038542 rs1225175422 |
21 | C>S | No |
ClinGen gnomAD |
|
|
CA9037025 rs747622772 |
23 | D>E | No |
ClinGen ExAC gnomAD |
|
|
rs138106261 CA9037026 |
23 | D>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs138106261 CA403038520 |
23 | D>Y | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs780585471 CA9037024 |
24 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9037023 rs200794578 |
24 | R>H | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA403038414 rs1402555063 |
28 | V>M | No |
ClinGen gnomAD |
|
|
rs765523565 CA9037021 |
30 | Q>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1017622535 CA304050005 |
30 | Q>R | No |
ClinGen TOPMed |
|
|
rs754136230 CA403038332 |
31 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9037018 rs764372975 |
32 | E>* | No |
ClinGen ExAC gnomAD |
|
|
CA403038323 rs764372975 |
32 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA403038249 rs760879470 |
34 | D>A | No |
ClinGen ExAC gnomAD |
|
|
rs1234676505 CA403038256 |
34 | D>H | No |
ClinGen gnomAD |
|
|
CA9037017 rs760879470 |
34 | D>V | No |
ClinGen ExAC gnomAD |
|
|
rs747356975 CA304050000 |
35 | Q>* | No |
ClinGen Ensembl |
|
|
rs752805743 CA9037016 |
36 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA403038218 rs752805743 |
36 | T>P | No |
ClinGen ExAC gnomAD |
|
|
rs767550886 CA9037015 |
38 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1267200270 CA403038144 |
39 | E>* | No |
ClinGen TOPMed gnomAD |
|
|
rs914404373 CA304049986 |
39 | E>D | No |
ClinGen TOPMed |
|
|
rs1267200270 CA403038137 |
39 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
rs1280634728 CA403038114 |
40 | F>I | No |
ClinGen TOPMed |
|
|
rs759391950 CA9037014 |
40 | F>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9037012 rs12459404 |
44 | S>C | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA9037011 rs12459404 VAR_028259 |
44 | S>F | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA304049947 rs12459404 |
44 | S>Y | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs953210323 CA304049936 |
45 | G>R | No |
ClinGen Ensembl |
|
|
rs772889135 CA9037010 |
46 | D>E | No |
ClinGen ExAC gnomAD |
|
|
rs769410946 CA9037009 |
48 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA9037007 rs141821175 |
49 | S>N | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs976132861 CA304049922 |
52 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1406420756 CA403037891 |
52 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA9037004 rs779428291 |
53 | P>L | Variant assessed as Somatic; 4.631e-05 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs1185676987 CA403037868 |
54 | R>Q | No |
ClinGen gnomAD |
|
|
rs1385893793 CA403037874 |
54 | R>W | No |
ClinGen gnomAD |
|
|
rs1463669532 CA403037853 |
55 | R>C | No |
ClinGen gnomAD |
|
|
rs1247192486 CA403037852 |
55 | R>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1287704982 CA403037795 |
60 | V>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs767504005 CA9036998 |
66 | D>N | No |
ClinGen ExAC gnomAD |
|
|
rs767504005 CA304049853 |
66 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
CA403037706 rs1599797438 |
67 | D>A | No |
ClinGen Ensembl |
|
|
rs1023720886 CA304049849 |
69 | T>I | No |
ClinGen TOPMed |
|
|
CA403037668 rs1219492381 |
70 | D>A | No |
ClinGen TOPMed |
|
|
rs1431991339 CA403037663 |
70 | D>E | No |
ClinGen TOPMed gnomAD |
|
|
CA403037671 rs367830828 |
70 | D>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9036996 rs367830828 |
70 | D>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs766305951 CA9036995 |
73 | F>L | No |
ClinGen ExAC gnomAD |
|
|
CA9036994 rs762783062 |
73 | F>S | No |
ClinGen ExAC gnomAD |
|
|
CA9036993 rs772976015 |
74 | V>G | No |
ClinGen ExAC |
|
|
CA403037619 rs1309943323 |
74 | V>L | No |
ClinGen TOPMed |
|
|
rs1241615239 CA403037607 |
75 | F>S | No |
ClinGen TOPMed |
|
|
rs1366284293 CA403037583 |
77 | P>A | No |
ClinGen gnomAD |
|
|
CA304049811 rs1043388313 |
77 | P>L | No |
ClinGen TOPMed |
|
|
CA403037575 rs1205375394 |
78 | E>K | No |
ClinGen gnomAD |
|
|
rs140799064 CA9036920 |
79 | E>* | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs140799064 CA403036655 |
79 | E>Q | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1303663913 CA403036635 |
80 | P>L | No |
ClinGen gnomAD |
|
|
CA403036632 rs1368117488 |
81 | K>E | No |
ClinGen gnomAD |
|
| TCGA novel | 83 | G>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA403036594 COSM3932870 rs1462124845 |
83 | G>D | urinary_tract [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
CA9036917 rs770852587 |
84 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs1479652332 CA403036159 |
85 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1200746815 CA403036095 |
88 | K>N | No |
ClinGen gnomAD |
|
|
CA9036914 rs377252494 |
90 | Y>* | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA403036060 rs1340238529 |
90 | Y>C | No |
ClinGen TOPMed gnomAD |
|
|
CA403036072 rs1195457733 |
90 | Y>N | No |
ClinGen gnomAD |
|
|
CA403036039 rs1322523360 |
91 | C>F | No |
ClinGen gnomAD |
|
|
rs1230869145 CA403036045 |
91 | C>S | No |
ClinGen TOPMed gnomAD |
|
|
CA304047531 rs371458354 |
92 | Q>* | No |
ClinGen ESP TOPMed gnomAD |
|
|
TCGA novel CA403036013 rs1599794368 |
93 | R>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA Ensembl |
|
CA403036008 rs1406642489 |
93 | R>H | No |
ClinGen gnomAD |
|
|
rs1348100349 CA403036002 |
94 | M>L | No |
ClinGen gnomAD |
|
|
CA403035995 rs1235720112 |
94 | M>T | No |
ClinGen TOPMed |
|
|
CA403036000 rs1348100349 |
94 | M>V | No |
ClinGen gnomAD |
|
| rs767944502 | 97 | E>missing | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs753673585 CA9036911 |
98 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA403035903 rs1428982211 |
99 | I>L | No |
ClinGen gnomAD |
|
|
CA9036908 rs143781514 |
100 | T>I | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs372313949 CA304047515 |
101 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP NCI-TCGA TOPMed gnomAD |
|
CA9036907 rs148984381 |
101 | R>W | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs760011436 CA9036906 |
102 | A>S | No |
ClinGen ExAC gnomAD |
|
|
CA403035855 rs1252974003 |
102 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA403035851 rs1460721946 |
103 | L>V | No |
ClinGen TOPMed gnomAD |
|
|
CA403035835 rs1225272071 |
104 | I>T | No |
ClinGen gnomAD |
|
|
rs147921895 COSM1221506 CA9036903 |
105 | V>M | large_intestine [Cosmic] | No |
ClinGen cosmic curated ESP ExAC TOPMed gnomAD |
|
rs913013040 CA304047460 |
106 | V>A | No |
ClinGen TOPMed |
|
|
CA403035804 rs1568513176 |
107 | Q>E | No |
ClinGen Ensembl |
|
|
rs774004270 CA9036902 |
108 | Q>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1160814656 CA403035736 |
109 | G>V | No |
ClinGen TOPMed |
|
|
rs762729935 CA9036900 |
110 | M>K | No |
ClinGen ExAC gnomAD |
|
|
rs144928792 CA9036901 |
110 | M>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA304047448 rs1028649314 |
112 | P>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs1028649314 CA403035675 |
112 | P>T | No |
ClinGen TOPMed gnomAD |
|
|
CA403035646 rs1471158981 |
113 | S>F | No |
ClinGen gnomAD |
|
|
rs1337729311 CA403035659 |
113 | S>P | No |
ClinGen gnomAD |
|
|
rs1599794193 CA403035630 |
114 | A>D | No |
ClinGen Ensembl |
|
|
CA9036897 rs11541898 |
114 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs11541898 CA304047442 |
114 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA304047429 rs963286964 |
115 | K>N | No |
ClinGen TOPMed gnomAD |
|
|
CA403035610 rs1470570762 |
115 | K>R | No |
ClinGen gnomAD |
|
|
rs770934264 CA9036895 CA9036896 |
116 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs897938139 CA304046390 |
117 | S>F | No |
ClinGen gnomAD |
|
|
rs765020060 CA9036848 |
119 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA9036845 COSM178112 rs766399285 |
120 | D>N | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs985055030 CA304046351 |
121 | M>T | No |
ClinGen TOPMed |
|
|
rs11959 CA304046345 |
123 | P>A | No |
ClinGen Ensembl |
|
|
rs1319472959 CA403035053 |
126 | I>L | No |
ClinGen TOPMed |
|
|
CA9036838 rs749600755 |
132 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
rs752979834 CA304046273 |
135 | L>P | No |
ClinGen TOPMed gnomAD |
|
|
rs780513362 CA9036837 |
137 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403034784 COSM990700 rs1197571602 |
138 | N>D | Variant assessed as Somatic; impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
CA9036836 rs770251481 |
138 | N>S | No |
ClinGen ExAC gnomAD |
|
|
rs948584739 CA304046242 |
140 | T>K | No |
ClinGen TOPMed |
|
|
rs948584739 CA304046238 |
140 | T>M | No |
ClinGen TOPMed |
|
|
rs1480683312 CA403034703 |
142 | H>D | No |
ClinGen gnomAD |
|
|
rs61740611 CA304046227 |
142 | H>Q | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1445652128 CA403033540 |
146 | P>A | No |
ClinGen gnomAD |
|
|
rs779847415 CA403033459 |
149 | V>F | No |
ClinGen ExAC gnomAD |
|
|
rs779847415 CA9036788 |
149 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA9036785 rs374965254 |
150 | V>I | No |
ClinGen ESP ExAC gnomAD |
|
|
rs374965254 CA9036786 |
150 | V>L | No |
ClinGen ESP ExAC gnomAD |
|
|
CA403033393 rs1246920956 |
151 | M>T | No |
ClinGen gnomAD |
|
|
rs757099189 CA9036784 |
151 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9036783 rs751535306 |
152 | T>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs1381438320 CA403033276 |
155 | E>D | No |
ClinGen gnomAD |
|
|
CA403033295 rs1293095773 |
155 | E>K | No |
ClinGen gnomAD |
|
|
rs1183728535 CA403033281 |
155 | E>V | No |
ClinGen TOPMed |
|
|
rs1364101114 CA403033272 |
156 | V>M | No |
ClinGen TOPMed |
|
|
CA9036782 rs764019574 |
159 | L>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9036781 rs758504093 |
160 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA9036779 rs759797327 |
162 | R>* | No |
ClinGen ExAC gnomAD |
|
|
CA9036780 rs759797327 |
162 | R>G | No |
ClinGen ExAC gnomAD |
|
|
CA9036777 rs369309356 |
162 | R>P | No |
ClinGen ESP ExAC gnomAD |
|
|
rs369309356 CA403033143 |
162 | R>Q | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1158509033 CA403032626 |
165 | L>R | No |
ClinGen gnomAD |
|
|
CA9036704 rs200525559 |
165 | L>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs201275503 CA9036703 |
166 | R>* | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA304044822 rs1055376064 |
166 | R>P | No |
ClinGen TOPMed |
|
|
CA304044821 rs972569097 |
169 | Q>* | No |
ClinGen TOPMed |
|
|
rs150847384 CA9036700 |
169 | Q>H | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1239129584 CA403032316 |
173 | I>T | No |
ClinGen gnomAD |
|
|
rs939539104 CA304044804 |
175 | A>V | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs769774420 CA9036697 |
177 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA9036696 rs746033391 |
177 | D>V | No |
ClinGen ExAC |
|
|
CA403032182 rs769774420 |
177 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
rs1416603100 CA403032121 |
178 | P>R | No |
ClinGen gnomAD |
|
|
CA9036695 rs781556560 |
178 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs781556560 CA403032134 |
178 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403032108 rs1382890907 |
179 | V>L | No |
ClinGen TOPMed gnomAD |
|
|
rs757607222 CA9036694 |
180 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs906660666 CA304044801 |
180 | A>V | No |
ClinGen gnomAD |
|
|
rs778316755 CA9036692 |
181 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403032039 rs1443797421 |
181 | R>P | No |
ClinGen gnomAD |
|
|
rs1189540314 CA403032015 |
182 | Y>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1261855355 CA403032011 |
182 | Y>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1015048713 CA304044771 |
184 | G>W | No |
ClinGen TOPMed |
|
|
rs1445278539 CA403031852 |
185 | I>M | No |
ClinGen gnomAD |
|
|
rs142308779 CA9036690 |
187 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA304044765 rs945424553 |
187 | R>H | No |
ClinGen TOPMed gnomAD |
|
|
rs945424553 CA403031784 |
187 | R>P | No |
ClinGen TOPMed gnomAD |
|
|
CA9036689 rs139328030 |
188 | G>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA9036687 rs749995612 |
189 | Q>K | No |
ClinGen ExAC gnomAD |
|
|
rs748440861 CA9036651 |
191 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs370150594 CA9036650 |
195 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1281904434 CA403030649 |
195 | R>W | Variant assessed as Somatic; 9.241e-05 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA9036649 rs769002822 |
196 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs780622181 CA9036647 |
199 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA403030493 rs1331871882 |
201 | G>D | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA9036645 rs375882249 |
203 | Y>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs758116915 CA9036643 |
205 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA403030412 rs1599790547 |
205 | T>P | No |
ClinGen Ensembl |
|
|
CA403030346 rs759491281 |
207 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs759491281 CA9036640 |
207 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA304044115 rs372881876 |
207 | R>W | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs753834886 CA9036639 |
209 | V>G | No |
ClinGen ExAC gnomAD |
|
|
CA9036638 rs766492286 |
210 | Q>E | No |
ClinGen ExAC |
|
|
rs773392791 CA9036636 |
210 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
rs760824411 CA9036637 |
210 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
CA304044075 rs967342267 |
211 | Q>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs772154822 CA9036635 |
211 | Q>Y | No |
ClinGen ExAC gnomAD |
No associated diseases with P19388
7 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| RNA polymerase I complex | RNA polymerase I, one of three nuclear DNA-directed RNA polymerases found in all eukaryotes, is a multisubunit complex; typically it produces rRNAs. Two large subunits comprise the most conserved portion including the catalytic site and share similarity with other eukaryotic and bacterial multisubunit RNA polymerases. The remainder of the complex is composed of smaller subunits (generally ten or more), some of which are also found in RNA polymerase III and others of which are also found in RNA polymerases II and III. Although the core is competent to mediate ribonucleic acid synthesis, it requires additional factors to select the appropriate template. |
| RNA polymerase II, core complex | RNA polymerase II, one of three nuclear DNA-directed RNA polymerases found in all eukaryotes, is a multisubunit complex; typically it produces mRNAs, snoRNAs, and some of the snRNAs. Two large subunits comprise the most conserved portion including the catalytic site and share similarity with other eukaryotic and bacterial multisubunit RNA polymerases. The largest subunit of RNA polymerase II contains an essential carboxyl-terminal domain (CTD) composed of a variable number of heptapeptide repeats (YSPTSPS). The remainder of the complex is composed of smaller subunits (generally ten or more), some of which are also found in RNA polymerases I and III. Although the core is competent to mediate ribonucleic acid synthesis, it requires additional factors to select the appropriate template. |
| RNA polymerase III complex | RNA polymerase III, one of three nuclear DNA-directed RNA polymerases found in all eukaryotes, is a multisubunit complex; typically it produces 5S rRNA, tRNAs and some of the small nuclear RNAs. Two large subunits comprise the most conserved portion including the catalytic site and share similarity with other eukaryotic and bacterial multisubunit RNA polymerases. The remainder of the complex is composed of smaller subunits (generally ten or more), some of which are also found in RNA polymerase I and others of which are also found in RNA polymerases I and II. Although the core is competent to mediate ribonucleic acid synthesis, it requires additional factors to select the appropriate template. |
| RPAP3/R2TP/prefoldin-like complex | A protein complex first characterized in human and comprised of a R2TP module (R2TP complex), a prefoldin-like module (containing both prefoldin-like proteins and canonical prefoldins), WD40 repeat protein Monad/WDR92 and DNA-dependent RNA polymerase subunit RPB5. This complex might have chaperone activity. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| DNA-directed 5'-3' RNA polymerase activity | Catalysis of the reaction: nucleoside triphosphate + RNA(n) = diphosphate + RNA(n+1). Utilizes a DNA template, i.e. the catalysis of DNA-template-directed extension of the 3'-end of an RNA strand by one nucleotide at a time. Can initiate a chain 'de novo'. |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| protein stabilization | Any process involved in maintaining the structure and integrity of a protein and preventing it from degradation or aggregation. |
| transcription by RNA polymerase II | The synthesis of RNA from a DNA template by RNA polymerase II (RNAP II), originating at an RNA polymerase II promoter. Includes transcription of messenger RNA (mRNA) and certain small nuclear RNAs (snRNAs). |
4 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q2T9T3 | POLR2E | DNA-directed RNA polymerases I, II, and III subunit RPABC1 | Bos taurus (Bovine) | PR |
| Q80UW8 | Polr2e | DNA-directed RNA polymerases I, II, and III subunit RPABC1 | Mus musculus (Mouse) | PR |
| B0BNE2 | Polr2e | DNA-directed RNA polymerases I, II, and III subunit RPABC1 | Rattus norvegicus (Rat) | PR |
| Q9N5K2 | rpb-5 | DNA-directed RNA polymerases I, II, and III subunit RPABC1 | Caenorhabditis elegans | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MDDEEETYRL | WKIRKTIMQL | CHDRGYLVTQ | DELDQTLEEF | KAQSGDKPSE | GRPRRTDLTV |
| 70 | 80 | 90 | 100 | 110 | 120 |
| LVAHNDDPTD | QMFVFFPEEP | KVGIKTIKVY | CQRMQEENIT | RALIVVQQGM | TPSAKQSLVD |
| 130 | 140 | 150 | 160 | 170 | 180 |
| MAPKYILEQF | LQQELLINIT | EHELVPEHVV | MTKEEVTELL | ARYKLRENQL | PRIQAGDPVA |
| 190 | 200 | ||||
| RYFGIKRGQV | VKIIRPSETA | GRYITYRLVQ |