F4JP48
Gene name |
MSH4 (At4g17380, dl4725w, FCAALL.423) |
Protein name |
DNA mismatch repair protein MSH4 |
Names |
AtMSH4, MutS protein homolog 4 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT4G17380 |
EC number |
|
Protein Class |
|
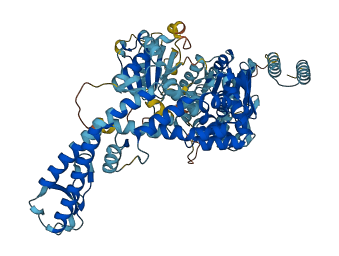
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for F4JP48
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-F4JP48-F1 | Predicted | AlphaFoldDB |
97 variants for F4JP48
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH11922544 | 5 | G>V | No | 1000Genomes | |
| ENSVATH00516243 | 14 | G>S | No | 1000Genomes | |
| ENSVATH06702494 | 51 | K>T | No | 1000Genomes | |
| ENSVATH06702495 | 55 | R>H | No | 1000Genomes | |
| ENSVATH06702495 | 55 | R>L | No | 1000Genomes | |
| ENSVATH14235672 | 59 | P>A | No | 1000Genomes | |
| tmp_4_9709127_C_T | 70 | A>V | No | 1000Genomes | |
| ENSVATH14235673 | 78 | S>L | No | 1000Genomes | |
| tmp_4_9709180_G_T | 88 | V>F | No | 1000Genomes | |
| ENSVATH06702496 | 89 | R>G | No | 1000Genomes | |
| tmp_4_9709443_C_G | 104 | A>G | No | 1000Genomes | |
| tmp_4_9709521_C_T | 130 | S>L | No | 1000Genomes | |
| tmp_4_9709533_C_G | 134 | A>G | No | 1000Genomes | |
| ENSVATH06702509 | 149 | V>I | No | 1000Genomes | |
| ENSVATH00516251 | 169 | A>V | No | 1000Genomes | |
| tmp_4_9710055_A_T | 174 | N>I | No | 1000Genomes | |
| tmp_4_9710085_C_T | 184 | A>V | No | 1000Genomes | |
| ENSVATH06702512 | 187 | G>A | No | 1000Genomes | |
| tmp_4_9710599_G_C | 237 | S>T | No | 1000Genomes | |
| ENSVATH00516255 | 240 | Q>R | No | 1000Genomes | |
| ENSVATH11922644 | 248 | V>F | No | 1000Genomes | |
| tmp_4_9710828_C_G | 271 | T>S | No | 1000Genomes | |
| tmp_4_9710833_G_A | 273 | A>T | No | 1000Genomes | |
| tmp_4_9710882_G_A | 289 | S>N | No | 1000Genomes | |
| tmp_4_9710908_G_C | 298 | D>H | No | 1000Genomes | |
| tmp_4_9710912_C_G | 299 | A>G | No | 1000Genomes | |
| tmp_4_9711071_G_A | 316 | A>T | No | 1000Genomes | |
| tmp_4_9711095_G_A | 324 | E>K | No | 1000Genomes | |
| ENSVATH00516258 | 326 | D>N | No | 1000Genomes | |
| ENSVATH06702528 | 328 | Y>F | No | 1000Genomes | |
| ENSVATH11922678 | 332 | R>G | No | 1000Genomes | |
| ENSVATH06702531 | 337 | E>D | No | 1000Genomes | |
| tmp_4_9711244_G_A | 338 | V>I | No | 1000Genomes | |
| ENSVATH06702532 | 348 | V>A | No | 1000Genomes | |
| ENSVATH14235704 | 383 | H>R | No | 1000Genomes | |
| ENSVATH06702534 | 400 | L>I | No | 1000Genomes | |
| ENSVATH11922710 | 403 | N>S | No | 1000Genomes | |
| tmp_4_9711546_T_A | 410 | F>I | No | 1000Genomes | |
| ENSVATH02865608 | 417 | V>I | No | 1000Genomes | |
| tmp_4_9711591_T_C | 425 | F>L | No | 1000Genomes | |
| ENSVATH02865609 | 427 | Q>L | No | 1000Genomes | |
| ENSVATH02865609 | 427 | Q>R | No | 1000Genomes | |
| ENSVATH06702536 | 429 | V>I | No | 1000Genomes | |
| tmp_4_9711696_A_T | 430 | K>I | No | 1000Genomes | |
| tmp_4_9711995_G_T | 455 | E>D | No | 1000Genomes | |
| tmp_4_9712015_C_G | 462 | T>R | No | 1000Genomes | |
| tmp_4_9712132_C_T | 466 | A>V | No | 1000Genomes | |
| ENSVATH00516263 | 497 | H>Y | No | 1000Genomes | |
| tmp_4_9712482_A_T | 529 | E>D | No | 1000Genomes | |
| ENSVATH00516270 | 536 | V>I | No | 1000Genomes | |
| tmp_4_9712737_A_C | 544 | E>D | No | 1000Genomes | |
| tmp_4_9712760_T_C | 552 | M>T | No | 1000Genomes | |
| tmp_4_9712943_G_A | 581 | A>T | No | 1000Genomes | |
| tmp_4_9712944_C_T | 581 | A>V | No | 1000Genomes | |
| tmp_4_9712973_C_T | 591 | R>C | No | 1000Genomes | |
| ENSVATH14235731 | 591 | R>H | No | 1000Genomes | |
| ENSVATH02865625 | 593 | F>L | No | 1000Genomes | |
| tmp_4_9713416_C_T | 654 | L>F | No | 1000Genomes | |
| ENSVATH11922783 | 657 | L>H | No | 1000Genomes | |
| ENSVATH06702576 | 665 | T>I | No | 1000Genomes | |
| tmp_4_9713552_C_G | 670 | L>V | No | 1000Genomes | |
| tmp_4_9713558_G_A | 672 | E>K | No | 1000Genomes | |
| tmp_4_9713596_T_A | 684 | H>Q | No | 1000Genomes | |
| ENSVATH06702579 | 685 | F>L | No | 1000Genomes | |
| ENSVATH06702580 | 691 | D>N | No | 1000Genomes | |
| ENSVATH00516280 | 699 | Q>H | No | 1000Genomes | |
| ENSVATH11922801 | 705 | L>P | No | 1000Genomes | |
| ENSVATH11922801 | 705 | L>R | No | 1000Genomes | |
| ENSVATH02865629 | 706 | H>P | No | 1000Genomes | |
| ENSVATH02865629 | 706 | H>R | No | 1000Genomes | |
| tmp_4_9713798_C_G | 727 | T>R | No | 1000Genomes | |
| tmp_4_9713804_G_C | 729 | R>T | No | 1000Genomes | |
| tmp_4_9713820_G_C | 734 | R>S | No | 1000Genomes | |
| tmp_4_9713832_A_C | 738 | K>N | No | 1000Genomes | |
| tmp_4_9713919_G_C | 744 | E>Q | No | 1000Genomes | |
| ENSVATH02865632 | 748 | G>E | No | 1000Genomes | |
| tmp_4_9713937_C_T | 750 | H>Y | No | 1000Genomes | |
| ENSVATH11922804 | 752 | E>D | No | 1000Genomes | |
| tmp_4_9713962_G_A | 758 | R>Q | No | 1000Genomes | |
| tmp_4_9713981_A_G | 764 | I>M | No | 1000Genomes | |
| tmp_4_9713998_G_A | 770 | R>K | No | 1000Genomes | |
| tmp_4_9713999_A_T | 770 | R>S | No | 1000Genomes | |
| tmp_4_9714006_G_A | 773 | E>K | No | 1000Genomes | |
| tmp_4_9714016_T_C,A | 776 | I>N | No | 1000Genomes | |
| tmp_4_9714016_T_C,A | 776 | I>T | No | 1000Genomes | |
| tmp_4_9714022_A_G | 778 | Q>R | No | 1000Genomes | |
| ENSVATH06702588 | 784 | N>I | No | 1000Genomes | |
| ENSVATH00516283 | 784 | N>K | No | 1000Genomes | |
| ENSVATH06702589 | 785 | E>D | No | 1000Genomes | |
| tmp_4_9714045_A_T | 786 | S>C | No | 1000Genomes | |
| ENSVATH02865634 | 786 | S>T | No | 1000Genomes | |
| ENSVATH11922860 | 788 | T>I | No | 1000Genomes | |
| ENSVATH02865635 | 789 | E>K | No | 1000Genomes | |
| ENSVATH00516284 | 790 | E>K | No | 1000Genomes | |
| ENSVATH11922861 | 791 | R>K | No | 1000Genomes | |
| ENSVATH11922861 | 791 | R>T | No | 1000Genomes | |
| tmp_4_9714063_C_A | 792 | L>I | No | 1000Genomes |
No associated diseases with F4JP48
Functions
4 GO annotations of cellular component
| Name | Definition |
|---|---|
| condensed nuclear chromosome | A highly compacted molecule of DNA and associated proteins resulting in a cytologically distinct nuclear chromosome. |
| germ cell nucleus | The nucleus of a germ cell, a reproductive cell in multicellular organisms. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| plasmodesma | A fine cytoplasmic channel, found in all higher plants, that connects the cytoplasm of one cell to that of an adjacent cell. |
4 GO annotations of molecular function
| Name | Definition |
|---|---|
| ATP binding | Binding to ATP, adenosine 5'-triphosphate, a universally important coenzyme and enzyme regulator. |
| ATP-dependent DNA damage sensor activity | A molecule that recognises toxic DNA structures, and initiates a signalling response, driven by ATP hydrolysis. |
| double-stranded DNA binding | Binding to double-stranded DNA. |
| mismatched DNA binding | Binding to a double-stranded DNA region containing one or more mismatches. |
4 GO annotations of biological process
| Name | Definition |
|---|---|
| homologous chromosome pairing at meiosis | The meiotic cell cycle process where side by side pairing and physical juxtaposition of homologous chromosomes is created during meiotic prophase. Homologous chromosome pairing begins when the chromosome arms begin to pair from the clustered telomeres and ends when synaptonemal complex or linear element assembly is complete. |
| homologous chromosome segregation | The cell cycle process in which replicated homologous chromosomes are organized and then physically separated and apportioned to two sets during the first division of the meiotic cell cycle. Each replicated chromosome, composed of two sister chromatids, aligns at the cell equator, paired with its homologous partner; this pairing off, referred to as synapsis, permits genetic recombination. One homolog (both sister chromatids) of each morphologic type goes into each of the resulting chromosome sets. |
| meiotic mismatch repair involved in reciprocal meiotic recombination | A system for the identification and correction of base-base mismatches, small insertion-deletion loops, and regions of heterology that are present in duplex DNA formed with strands from two recombining molecules resulting in meiotic recombination. Meiotic recombination is the cell cycle process in which double strand breaks are formed and repaired through a double Holliday junction intermediate. |
| reciprocal meiotic recombination | The cell cycle process in which double strand breaks are formed and repaired through a single or double Holliday junction intermediate. This results in the equal exchange of genetic material between non-sister chromatids in a pair of homologous chromosomes. These reciprocal recombinant products ensure the proper segregation of homologous chromosomes during meiosis I and create genetic diversity. |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MEDDGGERSS | FVAGLIENRA | KEVGMAAFDL | RSASLHLSQY | IETSSSYQNT | KTLLRFYDPS |
| 70 | 80 | 90 | 100 | 110 | 120 |
| VIIVPPNKLA | ADGMVGVSEL | VDRCYSTVRK | VVFARGCFDD | TKGAVLIQNL | AAEEPLALGL |
| 130 | 140 | 150 | 160 | 170 | 180 |
| DTYYKQHYLS | LAAAAATIKW | IEAEKGVIVT | NHSLTVTFNG | SFDHMNIDAT | SVENLELIDP |
| 190 | 200 | 210 | 220 | 230 | 240 |
| FHNALLGTSN | KKRSLFQMFK | TTKTAGGTRL | LRANLLQPLK | DIETINTRLD | CLDELMSNEQ |
| 250 | 260 | 270 | 280 | 290 | 300 |
| LFFGLSQVLR | KFPKETDRVL | CHFCFKPKKV | TEAVIGFENT | RKSQNMISSI | ILLKTALDAL |
| 310 | 320 | 330 | 340 | 350 | 360 |
| PILAKVLKDA | KCFLLANVYK | SVCENDRYAS | IRKKIGEVID | DDVLHARVPF | VARTQQCFAL |
| 370 | 380 | 390 | 400 | 410 | 420 |
| KAGIDGFLDI | ARRTFCDTSE | AIHNLASKYR | EEFNLPNLKL | PFNNRQGFFF | RIPQKEVQGK |
| 430 | 440 | 450 | 460 | 470 | 480 |
| LPNKFTQVVK | HGKNIHCSSL | ELASLNVRNK | SAAGECFIRT | ETCLEALMDA | IREDISALTL |
| 490 | 500 | 510 | 520 | 530 | 540 |
| LAEVLCLLDM | IVNSFAHTIS | TKPVDRYSRP | ELTDSGPLAI | DAGRHPILES | IHNDFVSNSI |
| 550 | 560 | 570 | 580 | 590 | 600 |
| FMSEATNMLV | VMGPNMSGKS | TYLQQVCLVV | ILAQIGCYVP | ARFATIRVVD | RIFTRMGTMD |
| 610 | 620 | 630 | 640 | 650 | 660 |
| NLESNSSTFM | TEMRETAFIM | QNVTNRSLIV | MDELGRATSS | SDGLAMAWSC | CEYLLSLKAY |
| 670 | 680 | 690 | 700 | 710 | 720 |
| TVFATHMDSL | AELATIYPNV | KVLHFYVDIR | DNRLDFKFQL | RDGTLHVPHY | GLLLAEVAGL |
| 730 | 740 | 750 | 760 | 770 | 780 |
| PSTVIDTARI | ITKRITDKEN | KRIELNCGKH | HEIHRIYRVA | QRLICLKYSR | QTEDSIRQAL |
| 790 | |||||
| QNLNESFTEE | RL |