B9DFG3
Gene name |
ISE2 (EMB25, PDE317, At1g70070, F20P5.20) |
Protein name |
DExH-box ATP-dependent RNA helicase DExH15 chloroplastic |
Names |
ATP-dependent RNA helicase ISE2, Protein EMBRYO DEFECTIVE 25, Protein INCREASED SIZE EXCLUSION LIMIT 2, Protein PIGMENT DEFECTIVE 317 |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT1G70070 |
EC number |
3.6.4.13: Acting on ATP; involved in cellular and subcellular movement |
Protein Class |
|
Descriptions
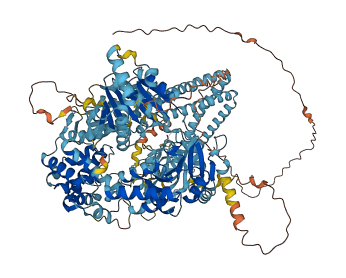
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for B9DFG3
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-B9DFG3-F1 | Predicted | AlphaFoldDB |
83 variants for B9DFG3
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH05116450 | 7 | V>A | No | 1000Genomes | |
| ENSVATH05116449 | 10 | T>A | No | 1000Genomes | |
| ENSVATH05116448 | 31 | P>A | No | 1000Genomes | |
| ENSVATH05116448 | 31 | P>S | No | 1000Genomes | |
| tmp_1_26394036_G_T | 38 | S>Y | No | 1000Genomes | |
| ENSVATH05116446 | 40 | I>F | No | 1000Genomes | |
| ENSVATH05116445 | 45 | H>N | No | 1000Genomes | |
| ENSVATH05116444 | 45 | H>Q | No | 1000Genomes | |
| tmp_1_26394006_A_T | 48 | F>Y | No | 1000Genomes | |
| ENSVATH05116443 | 51 | T>S | No | 1000Genomes | |
| ENSVATH05116442 | 57 | P>L | No | 1000Genomes | |
| tmp_1_26393980_G_A | 57 | P>S | No | 1000Genomes | |
| ENSVATH01513477 | 69 | E>D | No | 1000Genomes | |
| ENSVATH01513476 | 70 | E>D | No | 1000Genomes | |
| ENSVATH13781992 | 87 | D>E | No | 1000Genomes | |
| tmp_1_26393863_T_A | 96 | S>C | No | 1000Genomes | |
| ENSVATH01513475 | 96 | S>N | No | 1000Genomes | |
| ENSVATH01513475 | 96 | S>T | No | 1000Genomes | |
| ENSVATH01513473 | 110 | D>N | No | 1000Genomes | |
| ENSVATH05116441 | 111 | L>F | No | 1000Genomes | |
| ENSVATH00135033 | 116 | A>T | No | 1000Genomes | |
| tmp_1_26393775_T_C | 125 | Q>R | No | 1000Genomes | |
| tmp_1_26393719_T_C | 144 | I>V | No | 1000Genomes | |
| ENSVATH05116440 | 148 | I>V | No | 1000Genomes | |
| tmp_1_26393693_A_T | 152 | D>E | No | 1000Genomes | |
| tmp_1_26393593_C_A | 186 | A>S | No | 1000Genomes | |
| tmp_1_26393574_G_A | 192 | S>F | No | 1000Genomes | |
| tmp_1_26393382_C_T | 256 | S>N | No | 1000Genomes | |
| ENSVATH00135026 | 364 | S>T | No | 1000Genomes | |
| tmp_1_26392534_A_G | 373 | S>P | No | 1000Genomes | |
| ENSVATH14460328 | 382 | D>E | No | 1000Genomes | |
| ENSVATH05116423 | 386 | K>E | No | 1000Genomes | |
| ENSVATH09361311 | 402 | V>M | No | 1000Genomes | |
| tmp_1_26392428_G_A | 408 | P>L | No | 1000Genomes | |
| tmp_1_26392253_C_T | 427 | D>N | No | 1000Genomes | |
| tmp_1_26392229_T_C | 435 | K>E | No | 1000Genomes | |
| ENSVATH05116419 | 441 | I>V | No | 1000Genomes | |
| tmp_1_26392174_G_A | 453 | A>V | No | 1000Genomes | |
| ENSVATH14460325 | 459 | N>I | No | 1000Genomes | |
| ENSVATH05116416 | 545 | S>A | No | 1000Genomes | |
| ENSVATH05116414 | 606 | V>L | No | 1000Genomes | |
| ENSVATH14460323 | 672 | A>G | No | 1000Genomes | |
| ENSVATH05116413 | 679 | E>K | No | 1000Genomes | |
| tmp_1_26391494_T_G | 680 | I>L | No | 1000Genomes | |
| tmp_1_26391467_C_T | 689 | A>T | No | 1000Genomes | |
| tmp_1_26391443_G_A,T | 697 | L>F | No | 1000Genomes | |
| tmp_1_26391443_G_A,T | 697 | L>I | No | 1000Genomes | |
| ENSVATH05116412 | 700 | A>V | No | 1000Genomes | |
| ENSVATH05116408 | 730 | E>G | No | 1000Genomes | |
| ENSVATH05116408 | 730 | E>V | No | 1000Genomes | |
| ENSVATH05116407 | 732 | F>L | No | 1000Genomes | |
| ENSVATH00135017 | 733 | L>S | No | 1000Genomes | |
| tmp_1_26391325_T_C | 736 | K>R | No | 1000Genomes | |
| tmp_1_26391298_C_T | 745 | G>E | No | 1000Genomes | |
| ENSVATH05116405 | 754 | F>L | No | 1000Genomes | |
| ENSVATH13781962 | 778 | S>F | No | 1000Genomes | |
| ENSVATH13781961 | 784 | M>V | No | 1000Genomes | |
| tmp_1_26391158_A_T | 792 | L>I | No | 1000Genomes | |
| tmp_1_26391147_G_C | 795 | I>M | No | 1000Genomes | |
| tmp_1_26391122_G_A | 804 | P>S | No | 1000Genomes | |
| tmp_1_26391118_C_T | 805 | G>E | No | 1000Genomes | |
| tmp_1_26391028_T_A | 835 | Y>F | No | 1000Genomes | |
| ENSVATH14460321 | 845 | A>V | No | 1000Genomes | |
| tmp_1_26390941_A_G | 864 | M>T | No | 1000Genomes | |
| tmp_1_26390919_T_A | 871 | E>D | No | 1000Genomes | |
| tmp_1_26390918_A_T | 872 | S>T | No | 1000Genomes | |
| tmp_1_26390866_C_G | 889 | W>S | No | 1000Genomes | |
| tmp_1_26390819_C_A | 905 | V>L | No | 1000Genomes | |
| ENSVATH14460320 | 910 | E>K | No | 1000Genomes | |
| tmp_1_26390786_C_A | 916 | A>S | No | 1000Genomes | |
| ENSVATH05116399 | 980 | D>E | No | 1000Genomes | |
| ENSVATH14460319 | 983 | R>C | No | 1000Genomes | |
| ENSVATH05116398 | 984 | I>L | No | 1000Genomes | |
| ENSVATH13781958 | 1027 | A>S | No | 1000Genomes | |
| tmp_1_26390414_A_T | 1040 | C>S | No | 1000Genomes | |
| ENSVATH13781957 | 1046 | E>K | No | 1000Genomes | |
| tmp_1_26390359_T_A | 1058 | Y>F | No | 1000Genomes | |
| ENSVATH00135014 | 1064 | D>G | No | 1000Genomes | |
| tmp_1_26390324_C_T | 1070 | V>I | No | 1000Genomes | |
| tmp_1_26390273_G_A | 1087 | H>Y | No | 1000Genomes | |
| tmp_1_26390183_T_G | 1117 | M>L | No | 1000Genomes | |
| tmp_1_26390078_G_A | 1152 | R>C | No | 1000Genomes | |
| ENSVATH13781956 | 1153 | S>R | No | 1000Genomes |
No associated diseases with B9DFG3
4 regional properties for B9DFG3
Functions
| Description | ||
|---|---|---|
| EC Number | 3.6.4.13 | Acting on ATP; involved in cellular and subcellular movement |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
4 GO annotations of cellular component
| Name | Definition |
|---|---|
| chloroplast | A chlorophyll-containing plastid with thylakoids organized into grana and frets, or stroma thylakoids, and embedded in a stroma. |
| chloroplast stroma | The space enclosed by the double membrane of a chloroplast but excluding the thylakoid space. It contains DNA, ribosomes and some temporary products of photosynthesis. |
| cytoplasmic stress granule | A dense aggregation in the cytosol composed of proteins and RNAs that appear when the cell is under stress. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
5 GO annotations of molecular function
| Name | Definition |
|---|---|
| ATP binding | Binding to ATP, adenosine 5'-triphosphate, a universally important coenzyme and enzyme regulator. |
| ATP hydrolysis activity | Catalysis of the reaction: ATP + H2O = ADP + H+ phosphate. ATP hydrolysis is used in some reactions as an energy source, for example to catalyze a reaction or drive transport against a concentration gradient. |
| mRNA binding | Binding to messenger RNA (mRNA), an intermediate molecule between DNA and protein. mRNA includes UTR and coding sequences, but does not contain introns. |
| RNA binding | Binding to an RNA molecule or a portion thereof. |
| RNA helicase activity | Unwinding of an RNA helix, driven by ATP hydrolysis. |
8 GO annotations of biological process
| Name | Definition |
|---|---|
| chloroplast rRNA processing | Any rRNA processing that takes place in chloroplast. |
| cytidine to uridine editing | The conversion of a cytosine residue to uridine in an RNA molecule by deamination. |
| embryo development ending in seed dormancy | The process whose specific outcome is the progression of the embryo over time, from zygote formation to the end of seed dormancy. An example of this process is found in Arabidopsis thaliana. |
| gene silencing by RNA | A process in which an RNA molecule reduces expression of target genes. This can occur pre-transcriptionally by assembly of heterochromatin and prevention of transcription or co- or post-transcriptionally by targeting RNAs for degradation or by interfering with splicing or translation. This process starts once the inhibitory RNA molecule has been transcribed, and includes processing of the RNA such as cleavage, modifications, transport from the nucleus to the cytoplasm, loading onto the RISC complex, and the effect on transcription or translation. |
| Group II intron splicing | The splicing of Group II introns. This occurs by a ribozymic mechanism where the intron sequence forms a distinct 3D structure, characteristic of Group II introns and containing splice site consensus sequences, that is involved in catalyzing the splicing reactions, though protein factors are also required in vivo. Splicing occurs by a series of two transesterification reactions (mechanistically similar to those for splicing of nuclear mRNAs) initiated by a bulged adenosine residue within the intron sequence as the initiating nucleophile. The intron is excised as a lariat. |
| mRNA processing | Any process involved in the conversion of a primary mRNA transcript into one or more mature mRNA(s) prior to translation into polypeptide. |
| plasmodesmata-mediated intercellular transport | The movement of substances between cells via plasmodesmata. Plasmodesmata is a fine cytoplasmic channel, found in all higher plants, that connects the cytoplasm of one cell to that of an adjacent cell. |
| post-transcriptional gene silencing | The inactivation of gene expression that occurs after thanscription. |
3 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P51979 | HFM1 | ATP-dependent DNA helicase MER3 | Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) | PR |
| Q15477 | SKIV2L | Helicase SKI2W | Homo sapiens (Human) | PR |
| A2PYH4 | HFM1 | Probable ATP-dependent DNA helicase HFM1 | Homo sapiens (Human) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MNTLPVVSLT | ASSSFKFFHF | PSLHRSLSHS | PNFSFTKSLI | LNPNHLSFKS | TLNSLSPSQS |
| 70 | 80 | 90 | 100 | 110 | 120 |
| QLYEEEDDEE | EEEEDEDDDD | EAADEYDNIS | DEIRNSDDDD | DDEETEFSVD | LPTESARERV |
| 130 | 140 | 150 | 160 | 170 | 180 |
| EFRWQRVEKL | RSLVRDFGVE | MIDIDELISI | YDFRIDKFQR | LAIEAFLRGS | SVVVSAPTSS |
| 190 | 200 | 210 | 220 | 230 | 240 |
| GKTLIAEAAA | VSTVAKGRRL | FYTTPLKALS | NQKFREFRET | FGDDNVGLLT | GDSAINKDAQ |
| 250 | 260 | 270 | 280 | 290 | 300 |
| IVIMTTEILR | NMLYQSVGMA | SSGTGLFHVD | AIVLDEVHYL | SDISRGTVWE | EIVIYCPKEV |
| 310 | 320 | 330 | 340 | 350 | 360 |
| QLICLSATVA | NPDELAGWIG | EIHGKTELVT | STRRPVPLTW | YFSTKHSLLP | LLDEKGINVN |
| 370 | 380 | 390 | 400 | 410 | 420 |
| RKLSLNYLQL | SASEARFRDD | DDGYRKRRSK | KRGGDTSYNN | LVNVTDYPLS | KNEINKIRRS |
| 430 | 440 | 450 | 460 | 470 | 480 |
| QVPQISDTLW | HLQGKNMLPA | IWFIFNRRGC | DAAVQYVENF | QLLDDCEKSE | VELALKKFRV |
| 490 | 500 | 510 | 520 | 530 | 540 |
| LYPDAVRESA | EKGLLRGIAA | HHAGCLPLWK | SFIEELFQRG | LVKVVFATET | LAAGINMPAR |
| 550 | 560 | 570 | 580 | 590 | 600 |
| TAVISSLSKK | AGNERIELGP | NELYQMAGRA | GRRGIDEKGY | TVLVQTAFEG | AEECCKLVFA |
| 610 | 620 | 630 | 640 | 650 | 660 |
| GVKPLVSQFT | ASYGMVLNLV | AGSKVTRKSS | GTEAGKVLQA | GRSLEEAKKL | VEKSFGNYVS |
| 670 | 680 | 690 | 700 | 710 | 720 |
| SNVTVAAKQE | LAEIDNKIEI | LSSEISDEAI | DKKSRKLLSA | RDYKEITVLK | EELREEKRKR |
| 730 | 740 | 750 | 760 | 770 | 780 |
| AEQRRRMELE | RFLALKPLLK | GMEEGNLPFI | CLEFKDSEGR | EQSVPAVYLG | HIDSFQGSKL |
| 790 | 800 | 810 | 820 | 830 | 840 |
| QKMMSLDESF | ALNLIEDELA | ADEPGKPNVK | PSYYVALGSD | NSWYLFTEKW | VRTVYRTGFP |
| 850 | 860 | 870 | 880 | 890 | 900 |
| NIALALGDAL | PREIMKNLLD | KADMQWDKLA | ESELGSLWRL | EGSLETWSWS | LNVPVLSSLS |
| 910 | 920 | 930 | 940 | 950 | 960 |
| DEDEVLHMSE | EYDNAAQKYK | EQRSKISRLK | KKMSRSEGFR | EYKKILENAN | LTVEKMKRLK |
| 970 | 980 | 990 | 1000 | 1010 | 1020 |
| ARSRRLINRL | EQIEPSGWKD | FMRISNVIHE | SRALDINTHL | IFPLGETAAA | IRGENELWLA |
| 1030 | 1040 | 1050 | 1060 | 1070 | 1080 |
| MVLRNKALVD | LKPPQLAGVC | ASLVSEGIKV | RPWRDNNYIY | EPSDTVVDMV | NFLEDQRSSL |
| 1090 | 1100 | 1110 | 1120 | 1130 | 1140 |
| IKLQEKHEVM | IPCCLDVQFS | GMVEAWASGL | SWKEMMMECA | MDEGDLARLL | RRTIDLLAQI |
| 1150 | 1160 | 1170 | |||
| PKLPDIDPVL | QRSAAAAADI | MDRPPISELA | G |