Q9UH92
Gene name |
MLX (BHLHD13, TCFL4) |
Protein name |
Max-like protein X |
Names |
Class D basic helix-loop-helix protein 13, bHLHd13, Max-like bHLHZip protein, Protein BigMax, Transcription factor-like protein 4 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:6945 |
EC number |
|
Protein Class |
|
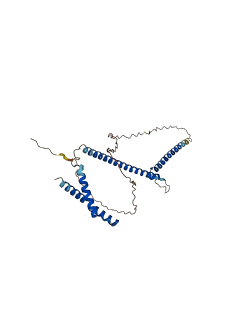
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9UH92
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9UH92-F1 | Predicted | AlphaFoldDB |
240 variants for Q9UH92
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs935353558 CA290773529 |
2 | T>M | No |
ClinGen TOPMed |
|
|
CA290773528 rs920415713 |
2 | T>S | No |
ClinGen Ensembl |
|
|
CA399600449 rs1236755728 |
3 | E>K | No |
ClinGen gnomAD |
|
|
rs1329020400 CA399600460 |
4 | P>Q | No |
ClinGen TOPMed |
|
|
CA290773532 rs929144048 |
6 | A>T | No |
ClinGen gnomAD |
|
|
rs182950482 CA8578462 |
6 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs754191585 CA399600477 |
8 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs868532594 CA290773546 |
8 | P>H | No |
ClinGen Ensembl |
|
|
rs754191585 CA8578463 |
8 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399600495 rs1402770868 |
10 | D>E | No |
ClinGen TOPMed |
|
|
CA8578465 rs754712752 |
10 | D>G | No |
ClinGen ExAC TOPMed |
|
|
rs548524602 CA8578466 |
11 | P>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs757883517 CA8578468 |
15 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs746975126 CA399600539 |
17 | P>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578470 rs746975126 |
17 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399600538 rs868376287 |
17 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
rs868376287 CA290773595 |
17 | P>T | No |
ClinGen TOPMed gnomAD |
|
|
CA399600548 rs1299521243 |
19 | G>R | No |
ClinGen gnomAD |
|
|
rs537756330 CA290773599 |
20 | A>S | No |
ClinGen 1000Genomes |
|
|
rs768887679 CA8578474 |
20 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1443531017 CA399600566 |
22 | A>S | No |
ClinGen TOPMed |
|
|
rs1460998986 CA399600588 |
25 | G>E | No |
ClinGen TOPMed gnomAD |
|
|
rs1460998986 CA399600590 |
25 | G>V | No |
ClinGen TOPMed gnomAD |
|
|
CA399600587 rs1244005398 |
25 | G>W | No |
ClinGen gnomAD |
|
|
CA399600595 rs1219558691 |
26 | R>M | No |
ClinGen Ensembl |
|
|
CA290773616 rs368562422 |
29 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs767553265 CA8578477 |
31 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578478 rs773287221 |
33 | R>C | No |
ClinGen ExAC gnomAD |
|
|
CA290773627 rs371378892 |
33 | R>H | No |
ClinGen Ensembl |
|
| TCGA novel | 34 | R>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA290773630 rs75782551 |
37 | G>R | No |
ClinGen Ensembl |
|
|
rs761094176 CA8578480 |
39 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs766957141 CA8578481 |
40 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs754281479 CA8578482 |
42 | S>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs755439287 CA8578483 |
43 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA290773636 rs765662123 |
44 | L>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1313248506 CA399600694 |
44 | L>R | No |
ClinGen TOPMed gnomAD |
|
|
CA8578484 rs765662123 |
44 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578485 rs752356404 |
45 | S>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399600697 rs1322373773 |
45 | S>Y | No |
ClinGen gnomAD |
|
|
CA290773649 rs1029915076 |
46 | P>R | No |
ClinGen Ensembl |
|
|
CA290773664 rs559253696 |
48 | S>A | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
rs1256171510 CA399600732 |
51 | L>F | No |
ClinGen TOPMed |
|
|
CA399600740 rs1205197323 |
52 | S>F | No |
ClinGen TOPMed |
|
|
CA399600750 rs1225448950 |
54 | P>H | No |
ClinGen gnomAD |
|
|
CA8578487 rs534650646 |
54 | P>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA399600754 rs1256482096 |
55 | R>Q | No |
ClinGen gnomAD |
|
|
CA8578488 rs746460209 |
55 | R>W | No |
ClinGen ExAC gnomAD |
|
|
CA399600760 rs1323140727 |
56 | G>D | No |
ClinGen TOPMed gnomAD |
|
|
rs1201998344 CA399600766 |
57 | C>F | No |
ClinGen gnomAD |
|
|
rs955652468 CA290773678 |
60 | D>V | No |
ClinGen gnomAD |
|
|
CA399600812 rs1248163438 |
61 | S>G | No |
ClinGen Ensembl |
|
|
rs367550767 CA8578489 |
61 | S>N | No |
ClinGen ESP ExAC gnomAD |
|
|
CA290773684 rs535621745 |
62 | S>C | No |
ClinGen Ensembl |
|
|
CA399600857 rs1240889169 |
64 | P>L | No |
ClinGen gnomAD |
|
|
CA399600851 rs1192877324 |
64 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1007102021 CA290773688 |
65 | A>T | No |
ClinGen Ensembl |
|
|
rs1367200651 CA399600955 |
69 | V>A | No |
ClinGen gnomAD |
|
|
rs1367200651 CA399600957 |
69 | V>G | No |
ClinGen gnomAD |
|
|
rs1156632613 CA399600948 |
69 | V>M | No |
ClinGen gnomAD |
|
|
rs763760312 CA8578506 |
72 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578505 rs763760312 |
72 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399601011 rs1597717790 |
74 | S>R | No |
ClinGen Ensembl |
|
| TCGA novel | 75 | D>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA399601020 rs1433297005 |
75 | D>G | No |
ClinGen TOPMed |
|
|
rs780677107 CA8578509 |
76 | N>S | No |
ClinGen ExAC |
|
|
rs1385186210 CA399601031 |
76 | N>Y | No |
ClinGen gnomAD |
|
|
rs1336621949 CA399601044 |
77 | S>C | No |
ClinGen gnomAD |
|
|
CA399601042 rs1336621949 |
77 | S>G | No |
ClinGen gnomAD |
|
|
rs1278207268 CA399601057 |
78 | L>Q | No |
ClinGen gnomAD |
|
|
rs1278207268 CA399601060 |
78 | L>R | No |
ClinGen gnomAD |
|
|
rs1238599049 CA399601056 |
78 | L>V | No |
ClinGen gnomAD |
|
|
CA8578513 rs749073467 |
80 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs547233193 CA399602059 |
81 | G>E | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs547233193 CA8578537 |
81 | G>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA8578538 rs770227149 |
82 | L>F | No |
ClinGen ExAC gnomAD |
|
|
CA8578539 rs776114176 |
82 | L>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs769122835 CA8578541 |
85 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399602112 rs769122835 |
85 | E>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578542 rs774639334 |
86 | S>G | No |
ClinGen ExAC gnomAD |
|
|
rs1264426750 CA399602143 |
87 | T>I | No |
ClinGen gnomAD |
|
|
rs1264426750 CA399602140 |
87 | T>S | No |
ClinGen gnomAD |
|
|
rs547490527 CA290775116 |
87 | T>S | No |
ClinGen Ensembl |
|
|
rs761458396 CA8578543 |
88 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578544 rs761458396 |
88 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578545 rs142766491 |
88 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8578546 rs142766491 |
88 | R>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8578547 rs765771374 |
93 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA399602207 rs1434971115 |
94 | S>P | No |
ClinGen TOPMed |
|
|
rs754861601 CA8578549 |
95 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs765097681 CA8578550 |
96 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1420205474 CA399602240 |
96 | A>V | No |
ClinGen TOPMed |
|
|
rs1260989720 CA399602261 |
97 | N>K | No |
ClinGen TOPMed gnomAD |
|
|
CA399602271 rs1484955354 |
98 | S>N | No |
ClinGen TOPMed |
|
|
CA8578551 rs752476588 |
99 | I>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201079657 CA8578553 |
100 | G>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 100 | G>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1038225340 CA290775168 |
102 | T>A | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
| TCGA novel | 103 | S>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs746067080 CA8578554 |
103 | S>R | No |
ClinGen ExAC gnomAD |
|
|
CA8578555 rs756258939 |
105 | S>F | Variant assessed as Somatic; 9.239e-05 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA399602384 rs1384929856 |
106 | S>A | No |
ClinGen gnomAD |
|
|
rs1398690350 CA399602400 |
107 | V>I | No |
ClinGen gnomAD |
|
|
rs147400711 CA8578556 |
109 | N>S | No |
ClinGen 1000Genomes ESP ExAC gnomAD |
|
|
rs749814079 CA8578557 |
111 | D>H | No |
ClinGen ExAC gnomAD |
|
|
CA399602454 rs749814079 |
111 | D>Y | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 113 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs982349429 CA290775337 |
114 | D>E | No |
ClinGen TOPMed gnomAD |
|
|
CA8578595 rs766460362 |
114 | D>H | No |
ClinGen ExAC gnomAD |
|
|
rs374345141 CA8578596 |
115 | S>G | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA8578597 rs755087009 |
116 | D>E | No |
ClinGen ExAC gnomAD |
|
|
CA8578598 rs778956968 |
118 | H>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1397726183 CA399602585 |
119 | Q>* | No |
ClinGen gnomAD |
|
|
rs753256987 CA8578599 |
120 | E>G | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 121 | A>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA8578601 rs778119116 |
122 | Y>F | No |
ClinGen ExAC gnomAD |
|
|
CA8578600 rs758848942 |
122 | Y>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs747300000 CA399602612 |
123 | K>E | No |
ClinGen ExAC gnomAD |
|
|
CA399602614 rs1362515516 |
123 | K>M | No |
ClinGen gnomAD |
|
|
rs747300000 CA8578602 |
123 | K>Q | No |
ClinGen ExAC gnomAD |
|
|
CA290775344 rs139677858 |
125 | S>F | No |
ClinGen ESP TOPMed |
|
|
rs1316361565 CA399602636 |
126 | Y>C | No |
ClinGen gnomAD |
|
|
rs143700523 CA8578604 |
129 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1263926960 CA399602657 |
129 | R>W | No |
ClinGen gnomAD |
|
|
rs745504523 CA399602661 |
130 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs769496179 CA8578606 |
131 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA8578607 rs775127202 |
132 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs775127202 CA399602673 |
132 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578609 rs371444407 |
133 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs769263207 CA8578611 |
140 | K>Q | No |
ClinGen ExAC gnomAD |
|
|
CA8578612 rs568777376 |
143 | D>E | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
COSM269601 rs759737992 CA8578614 |
144 | A>T | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs1320015483 CA399602757 |
145 | I>V | No |
ClinGen gnomAD |
|
|
CA399602799 rs1329976607 |
149 | Y>S | No |
ClinGen TOPMed |
|
|
rs765407614 CA8578633 |
150 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA290775430 rs570620164 |
155 | I>T | No |
ClinGen Ensembl |
|
|
rs148497001 CA8578636 |
156 | V>I | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA8578637 rs752074528 |
158 | T>S | No |
ClinGen ExAC gnomAD |
|
|
CA8578638 rs757769608 |
160 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
CA399602882 rs767788086 |
161 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1222632361 CA399602884 |
162 | Q>K | No |
ClinGen TOPMed gnomAD |
|
|
CA399602913 rs1266046244 |
165 | S>F | No |
ClinGen gnomAD |
|
|
CA8578640 rs750775768 |
166 | I>T | No |
ClinGen ExAC |
|
|
CA399602931 rs1449568993 |
168 | S>F | No |
ClinGen gnomAD |
|
|
rs1015383378 CA290775446 |
169 | Q>H | No |
ClinGen gnomAD |
|
|
CA399602969 rs1166401759 |
174 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
CA8578641 rs755852891 |
175 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA399602983 rs1156557930 |
176 | V>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs1419149105 CA399603004 |
179 | K>R | No |
ClinGen gnomAD |
|
|
rs779900314 CA8578642 |
180 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578669 rs780954981 |
181 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs768857309 CA8578671 |
185 | Q>H | No |
ClinGen ExAC TOPMed |
|
|
rs1285266902 CA399603077 |
188 | H>D | No |
ClinGen TOPMed |
|
|
rs1054095958 CA290775542 |
188 | H>P | No |
ClinGen TOPMed |
|
|
rs201470982 CA290775549 |
189 | K>R | No |
ClinGen 1000Genomes |
|
|
CA399603108 rs1199620026 |
190 | E>G | No |
ClinGen gnomAD |
|
|
rs772011845 CA8578674 |
194 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
rs1424407318 CA399603176 |
195 | E>D | No |
ClinGen gnomAD |
|
|
CA399603172 rs1195508352 |
195 | E>G | No |
ClinGen gnomAD |
|
|
rs528569258 CA8578675 |
195 | E>Q | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA399603197 rs761247919 |
197 | E>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578676 rs761247919 |
197 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA290775558 rs1048805920 |
200 | T>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs766861331 CA8578677 |
200 | T>P | No |
ClinGen ExAC gnomAD |
|
|
COSM1257812 rs759146238 CA8578679 |
202 | R>C | Variant assessed as Somatic; 0.0 impact. oesophagus [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs759146238 CA8578680 |
202 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs774834596 CA8578681 COSM1215245 |
202 | R>H | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA290775563 rs1009349298 |
203 | K>T | No |
ClinGen TOPMed gnomAD |
|
|
rs757969851 CA8578682 |
206 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA399603296 rs751557461 |
207 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578684 rs751557461 |
207 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs562122560 CA8578686 |
209 | K>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs750296353 CA8578706 |
215 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
CA8578707 rs756002887 |
216 | E>K | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 218 | I>M | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs748411344 CA8578709 |
222 | H>R | No |
ClinGen ExAC |
|
|
rs1165000260 CA399603521 |
223 | Q>* | No |
ClinGen TOPMed gnomAD |
|
|
CA399603523 rs1165000260 |
223 | Q>K | No |
ClinGen TOPMed gnomAD |
|
|
rs665268 CA399603527 |
223 | Q>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA399603525 rs665268 |
223 | Q>P | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs665268 CA8578710 VAR_049547 |
223 | Q>R | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs984039391 CA290775690 |
225 | N>S | No |
ClinGen gnomAD |
|
|
CA399603562 rs747033129 |
226 | P>A | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 226 | P>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA399603564 rs747033129 |
226 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs747033129 CA8578712 |
226 | P>T | No |
ClinGen ExAC gnomAD |
|
|
CA399603577 rs1447306646 |
227 | H>R | No |
ClinGen TOPMed gnomAD |
|
|
CA399603592 rs1374660839 |
228 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
rs771115404 CA8578713 |
228 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA399603600 rs1290426197 |
229 | G>E | No |
ClinGen gnomAD |
|
|
rs1008625060 CA290775708 |
229 | G>W | No |
ClinGen TOPMed gnomAD |
|
|
rs370455047 CA290775712 |
230 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
rs777239344 CA8578714 |
231 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
CA8578716 rs770252469 |
232 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
rs775660549 CA8578717 |
238 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs143736694 CA290775746 |
240 | N>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs143736694 CA8578718 |
240 | N>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1185964649 CA399603733 |
241 | V>M | No |
ClinGen gnomAD |
|
|
rs761350836 CA8578721 |
243 | Q>E | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs761350836 CA290775751 |
243 | Q>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1162062759 CA399604430 |
247 | D>E | No |
ClinGen gnomAD |
|
|
rs1254111230 CA399604418 |
247 | D>N | No |
ClinGen TOPMed |
|
|
CA399604468 rs1213833738 |
250 | F>L | No |
ClinGen TOPMed |
|
| TCGA novel | 250 | F>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 251 | Q>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs755944141 CA8578724 |
254 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578725 rs199695342 |
255 | A>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA8578726 rs199695342 |
255 | A>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs111260159 CA290775769 |
256 | S>P | No |
ClinGen Ensembl |
|
|
CA8578730 rs757483745 |
260 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA8578731 rs781122018 |
262 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs1320351365 CA399604637 |
263 | Q>* | No |
ClinGen TOPMed gnomAD |
|
|
rs1248932634 CA399604695 |
267 | A>G | No |
ClinGen TOPMed |
|
|
CA399604688 rs1199525755 |
267 | A>S | No |
ClinGen gnomAD |
|
|
COSM282826 rs1248932634 CA399604697 |
267 | A>V | large_intestine Variant assessed as Somatic; impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated NCI-TCGA TOPMed |
|
rs1212623144 CA399604708 |
268 | C>Y | No |
ClinGen gnomAD |
|
|
rs775956555 COSM417512 CA8578735 |
273 | I>M | Variant assessed as Somatic; 0.0 impact. urinary_tract [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA399604782 rs1388644291 |
273 | I>V | No |
ClinGen TOPMed |
|
|
rs780372140 CA290775803 |
275 | E>A | No |
ClinGen TOPMed gnomAD |
|
|
rs780372140 CA290775807 |
275 | E>G | No |
ClinGen TOPMed gnomAD |
|
|
CA8578736 rs201627294 |
275 | E>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA8578737 rs768975531 |
276 | H>Q | No |
ClinGen ExAC gnomAD |
|
|
rs1420960638 CA399604891 |
280 | Q>H | No |
ClinGen gnomAD |
|
|
CA290776709 rs140676383 |
282 | L>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ESP NCI-TCGA TOPMed |
|
CA399605108 rs1597720539 |
282 | L>V | No |
ClinGen Ensembl |
|
|
CA8578763 rs759537997 |
283 | R>P | No |
ClinGen ExAC gnomAD |
|
|
CA8578762 rs759537997 |
283 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs150470672 CA290776721 |
284 | E>K | No |
ClinGen ESP |
|
|
rs1245733780 CA399605163 |
285 | I>M | No |
ClinGen gnomAD |
|
|
rs752474682 CA8578764 |
285 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578765 rs762127321 |
287 | I>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs767588014 CA8578766 |
288 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8578768 rs756214487 |
289 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs756214487 CA399605205 |
289 | V>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399605241 rs1419289573 |
291 | H>L | No |
ClinGen TOPMed |
|
|
CA8578769 rs780167658 |
291 | H>Y | No |
ClinGen ExAC gnomAD |
|
|
rs543511292 CA290776770 |
292 | Q>E | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
CA399605320 rs1460465255 |
296 | Q>R | No |
ClinGen TOPMed |
|
|
rs200600765 CA290776786 |
297 | L>P | No |
ClinGen 1000Genomes |
|
| TCGA novel | 299 | Y>= | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
No associated diseases with Q9UH92
5 regional properties for Q9UH92
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| conserved_site | MoaA/NifB/PqqE, iron-sulphur binding, conserved site | 73 - 84 | IPR000385 |
| domain | Molybdopterin cofactor biosynthesis C (MoaC) domain | 490 - 625 | IPR002820 |
| domain | Elp3/MiaA/NifB-like, radical SAM core domain | 67 - 270 | IPR006638 |
| domain | Radical SAM | 56 - 380 | IPR007197 |
| domain | Molybdenum cofactor biosynthesis protein A-like, twitch domain | 239 - 373 | IPR010505 |
6 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromatin | The ordered and organized complex of DNA, protein, and sometimes RNA, that forms the chromosome. |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nuclear membrane | Either of the lipid bilayers that surround the nucleus and form the nuclear envelope; excludes the intermembrane space. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
10 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| DNA-binding transcription factor activity | A transcription regulator activity that modulates transcription of gene sets via selective and non-covalent binding to a specific double-stranded genomic DNA sequence (sometimes referred to as a motif) within a cis-regulatory region. Regulatory regions include promoters (proximal and distal) and enhancers. Genes are transcriptional units, and include bacterial operons. |
| DNA-binding transcription factor activity, RNA polymerase II-specific | A DNA-binding transcription factor activity that modulates the transcription of specific gene sets transcribed by RNA polymerase II. |
| DNA-binding transcription repressor activity, RNA polymerase II-specific | A DNA-binding transcription factor activity that represses or decreases the transcription of specific gene sets transcribed by RNA polymerase II. |
| protein heterodimerization activity | Binding to a nonidentical protein to form a heterodimer. |
| protein homodimerization activity | Binding to an identical protein to form a homodimer. |
| RNA polymerase II cis-regulatory region sequence-specific DNA binding | Binding to a specific upstream regulatory DNA sequence (transcription factor recognition sequence or binding site) located in cis relative to the transcription start site (i.e., on the same strand of DNA) of a gene transcribed by RNA polymerase II. |
| RNA polymerase II transcription regulatory region sequence-specific DNA binding | Binding to a specific sequence of DNA that is part of a regulatory region that controls the transcription of a gene or cistron by RNA polymerase II. |
| RNA polymerase II-specific DNA-binding transcription factor binding | Binding to a sequence-specific DNA binding RNA polymerase II transcription factor, any of the factors that interact selectively and non-covalently with a specific DNA sequence in order to modulate transcription. |
| sequence-specific double-stranded DNA binding | Binding to double-stranded DNA of a specific nucleotide composition, e.g. GC-rich DNA binding, or with a specific sequence motif or type of DNA, e.g. promotor binding or rDNA binding. |
5 GO annotations of biological process
| Name | Definition |
|---|---|
| negative regulation of DNA-templated transcription | Any process that stops, prevents, or reduces the frequency, rate or extent of cellular DNA-templated transcription. |
| negative regulation of transcription by RNA polymerase II | Any process that stops, prevents, or reduces the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| positive regulation of transcription by RNA polymerase II | Any process that activates or increases the frequency, rate or extent of transcription from an RNA polymerase II promoter. |
| regulation of DNA-templated transcription | Any process that modulates the frequency, rate or extent of cellular DNA-templated transcription. |
| regulation of transcription by RNA polymerase II | Any process that modulates the frequency, rate or extent of transcription mediated by RNA polymerase II. |
1 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| O08609 | Mlx | Max-like protein X | Mus musculus (Mouse) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MTEPGASPED | PWVKASPVGA | HAGEGRAGRA | RARRGAGRRG | ASLLSPKSPT | LSVPRGCRED |
| 70 | 80 | 90 | 100 | 110 | 120 |
| SSHPACAKVE | YAYSDNSLDP | GLFVESTRKG | SVVSRANSIG | STSASSVPNT | DDEDSDYHQE |
| 130 | 140 | 150 | 160 | 170 | 180 |
| AYKESYKDRR | RRAHTQAEQK | RRDAIKRGYD | DLQTIVPTCQ | QQDFSIGSQK | LSKAIVLQKT |
| 190 | 200 | 210 | 220 | 230 | 240 |
| IDYIQFLHKE | KKKQEEEVST | LRKDVTALKI | MKVNYEQIVK | AHQDNPHEGE | DQVSDQVKFN |
| 250 | 260 | 270 | 280 | 290 | |
| VFQGIMDSLF | QSFNASISVA | SFQELSACVF | SWIEEHCKPQ | TLREIVIGVL | HQLKNQLY |