Q9LIL1
Gene name |
At3g22870 (F5N5.4) |
Protein name |
Putative F-box/kelch-repeat protein At3g22870 |
Names |
|
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT3G22870 |
EC number |
|
Protein Class |
|
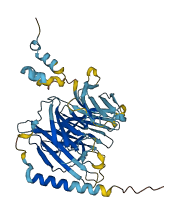
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9LIL1
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9LIL1-F1 | Predicted | AlphaFoldDB |
91 variants for Q9LIL1
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| tmp_3_8096240_C_T | 4 | T>M | No | 1000Genomes | |
| tmp_3_8096245_T_A | 6 | S>T | No | 1000Genomes | |
| tmp_3_8096249_A_T | 7 | D>V | No | 1000Genomes | |
| ENSVATH05888887 | 9 | P>R | No | 1000Genomes | |
| ENSVATH10873335 | 11 | D>Y | No | 1000Genomes | |
| ENSVATH10873336 | 13 | K>M | No | 1000Genomes | |
| ENSVATH05888888 | 14 | K>N | No | 1000Genomes | |
| ENSVATH13972345 | 17 | F>L | No | 1000Genomes | |
| ENSVATH02181110 | 17 | F>V | No | 1000Genomes | |
| tmp_3_8096281_T_G | 18 | S>A | No | 1000Genomes | |
| ENSVATH05888889 | 27 | A>T | No | 1000Genomes | |
| ENSVATH05888890 | 37 | T>N | No | 1000Genomes | |
| ENSVATH05888891 | 38 | L>* | No | 1000Genomes | |
| ENSVATH00340907 | 40 | K>N | No | 1000Genomes | |
| ENSVATH05888892 | 62 | C>F | No | 1000Genomes | |
| ENSVATH05888894 | 66 | K>E | No | 1000Genomes | |
| tmp_3_8096485_G_A | 86 | E>K | No | 1000Genomes | |
| tmp_3_8096497_G_A | 90 | V>I | No | 1000Genomes | |
| ENSVATH05888895 | 91 | S>Y | No | 1000Genomes | |
| tmp_3_8096503_A_C | 92 | M>L | No | 1000Genomes | |
| tmp_3_8096508_G_C | 93 | L>F | No | 1000Genomes | |
| ENSVATH13972346 | 98 | G>S | No | 1000Genomes | |
| ENSVATH13972347 | 107 | D>N | No | 1000Genomes | |
| ENSVATH02181112 | 109 | T>S | No | 1000Genomes | |
| tmp_3_8096580_T_A | 117 | Y>* | No | 1000Genomes | |
| ENSVATH05888896 | 120 | Q>E | No | 1000Genomes | |
| tmp_3_8096588_A_C | 120 | Q>P | No | 1000Genomes | |
| tmp_3_8096590_A_G | 121 | R>G | No | 1000Genomes | |
| tmp_3_8096624_C_T | 132 | P>L | No | 1000Genomes | |
| ENSVATH10873337 | 135 | W>* | No | 1000Genomes | |
| tmp_3_8096648_A_T | 140 | Y>F | No | 1000Genomes | |
| tmp_3_8096677_A_T | 150 | M>L | No | 1000Genomes | |
| ENSVATH05888897 | 152 | K>R | No | 1000Genomes | |
| ENSVATH10873338 | 161 | D>Y | No | 1000Genomes | |
| ENSVATH05888898 | 163 | F>L | No | 1000Genomes | |
| ENSVATH10873341 | 175 | Y>* | No | 1000Genomes | |
| ENSVATH10873340 | 175 | Y>F | No | 1000Genomes | |
| ENSVATH10873339 | 175 | Y>N | No | 1000Genomes | |
| tmp_3_8096831_T_G | 201 | V>G | No | 1000Genomes | |
| ENSVATH05888902 | 201 | V>I | No | 1000Genomes | |
| ENSVATH10873342 | 204 | K>T | No | 1000Genomes | |
| ENSVATH05888903 | 207 | T>I | No | 1000Genomes | |
| tmp_3_8096868_A_T | 213 | E>D | No | 1000Genomes | |
| ENSVATH00340910 | 216 | P>S | No | 1000Genomes | |
| ENSVATH05888905 | 237 | E>* | No | 1000Genomes | |
| ENSVATH02181113 | 237 | E>D | No | 1000Genomes | |
| tmp_3_8096941_A_G | 238 | R>G | No | 1000Genomes | |
| tmp_3_8096942_G_C | 238 | R>T | No | 1000Genomes | |
| ENSVATH02181114 | 243 | V>L | No | 1000Genomes | |
| ENSVATH02181115 | 244 | P>R | No | 1000Genomes | |
| ENSVATH10873343 | 246 | P>S | No | 1000Genomes | |
| ENSVATH00340911 | 248 | R>K | No | 1000Genomes | |
| ENSVATH13972349 | 251 | K>R | No | 1000Genomes | |
| tmp_3_8096996_C_G | 256 | T>S | No | 1000Genomes | |
| tmp_3_8097002_C_T | 258 | S>F | No | 1000Genomes | |
| ENSVATH00340912 | 265 | L>R | No | 1000Genomes | |
| ENSVATH02181116 | 267 | A>V | No | 1000Genomes | |
| ENSVATH05888908 | 268 | L>I | No | 1000Genomes | |
| tmp_3_8097041_G_A | 271 | R>H | No | 1000Genomes | |
| ENSVATH13972350 | 272 | D>N | No | 1000Genomes | |
| tmp_3_8097063_G_T | 278 | W>C | No | 1000Genomes | |
| ENSVATH00340913 | 285 | F>S | No | 1000Genomes | |
| ENSVATH02181117 | 286 | D>N | No | 1000Genomes | |
| ENSVATH05888910 | 292 | K>N | No | 1000Genomes | |
| tmp_3_8097106_T_C | 293 | F>L | No | 1000Genomes | |
| tmp_3_8097109_T_G | 294 | L>V | No | 1000Genomes | |
| ENSVATH00340914 | 299 | R>C | No | 1000Genomes | |
| ENSVATH00340914 | 299 | R>G | No | 1000Genomes | |
| ENSVATH00340915 | 300 | D>E | No | 1000Genomes | |
| tmp_3_8097127_G_A | 300 | D>N | No | 1000Genomes | |
| tmp_3_8097163_T_A | 312 | F>I | No | 1000Genomes | |
| tmp_3_8097187_G_T | 320 | A>S | No | 1000Genomes | |
| ENSVATH00340916 | 321 | V>M | No | 1000Genomes | |
| tmp_3_8097223_G_A | 332 | V>I | No | 1000Genomes | |
| ENSVATH10873427 | 350 | A>D | No | 1000Genomes | |
| ENSVATH10873426 | 350 | A>S | No | 1000Genomes | |
| tmp_3_8097290_G_A | 354 | S>N | No | 1000Genomes | |
| tmp_3_8097326_T_A | 366 | V>E | No | 1000Genomes | |
| ENSVATH02181120 | 367 | K>Q | No | 1000Genomes | |
| ENSVATH05888911 | 371 | P>H | No | 1000Genomes | |
| ENSVATH02181121 | 372 | P>Q | No | 1000Genomes | |
| tmp_3_8097343_C_T | 372 | P>S | No | 1000Genomes | |
| ENSVATH02181122 | 375 | K>E | No | 1000Genomes | |
| tmp_3_8097382_C_G | 385 | R>G | No | 1000Genomes | |
| tmp_3_8097386_G_T | 386 | R>L | No | 1000Genomes | |
| ENSVATH05888912 | 387 | Y>H | No | 1000Genomes | |
| tmp_3_8097409_C_A,G | 394 | L>I | No | 1000Genomes | |
| tmp_3_8097409_C_A,G | 394 | L>V | No | 1000Genomes | |
| tmp_3_8097437_C_T | 403 | A>V | No | 1000Genomes | |
| ENSVATH13972351 | 404 | M>T | No | 1000Genomes | |
| ENSVATH02181123 | 412 | T>A | No | 1000Genomes |
No associated diseases with Q9LIL1
No GO annotations of cellular component
| Name | Definition |
|---|---|
| No GO annotations for cellular component |
No GO annotations of molecular function
| Name | Definition |
|---|---|
| No GO annotations for molecular function |
No GO annotations of biological process
| Name | Definition |
|---|---|
| No GO annotations for biological process |
11 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q9LUI8 | At3g22730 | Putative F-box/kelch-repeat protein At3g22730 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9SCK7 | At3g49520 | Putative F-box protein At3g49520 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9LRW6 | At3g13820 | F-box protein At3g13820 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9S9T0 | At4g05080 | F-box/kelch-repeat protein At4g05080 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9FVQ9 | At1g32140 | Putative F-box protein At1g32140 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9LRZ2 | At3g16820 | Putative F-box protein At3g16820 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q8LCE9 | At3g19470 | F-box protein At3g19470 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9SZA6 | At4g33290 | F-box/kelch-repeat protein At4g33290 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9FFS9 | At5g41510 | Putative F-box protein At5g41510 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9CAP3 | At1g77650 | Putative F-box protein At1g77650 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9ZV78 | At2g07140 | F-box protein At2g07140 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MTLTISDLPR | DLKKKIFSRI | PLRYVRALRL | TCKEWETLIK | SRSLKIDEEE | SQMVALMDYN |
| 70 | 80 | 90 | 100 | 110 | 120 |
| LCLMSKSFNG | GDPSTEIKGK | LTCFDEQVKV | SMLFHCEGLL | LCILKDDNTK | VVVWNPYLGQ |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RRFIQVRFSH | IPGGWDQFSY | ALGYYKNNNM | MKSFKLLRFF | DYFYTSNDFV | FYEIYDFDSG |
| 190 | 200 | 210 | 220 | 230 | 240 |
| LWKTLDVTPY | WRIRFFDDIG | VSLKGNTYWC | AKERKPEWNA | DPFIIVDHII | CFDFTSERFG |
| 250 | 260 | 270 | 280 | 290 | 300 |
| PLVPLPFRAM | KESLVTLSCV | REEKLAALFC | RDVVVEVWIT | TTIEFDKVSW | SKFLTFGVRD |
| 310 | 320 | 330 | 340 | 350 | 360 |
| CPMIYSCTGS | FFIDEVNKVA | VIFGQPLKRD | KVFIIGEAGQ | VRDVDLGEPA | HQDSWLYVCP |
| 370 | 380 | 390 | 400 | 410 | |
| YVPSLVKIKQ | PPGCKRRRQS | SSENRRYKRN | MMRLVELEKY | HIAMEPKRGD | KTI |