Q9C560
Gene name |
INVF |
Protein name |
Probable alkaline/neutral invertase F |
Names |
A/N-INVF |
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT1G72000 |
EC number |
3.2.1.26: Glycosidases, ie enzymes hydrolyzing O- and S-glycosyl compounds |
Protein Class |
|
Descriptions
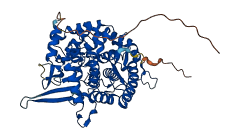
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9C560
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9C560-F1 | Predicted | AlphaFoldDB |
45 variants for Q9C560
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH05129510 | 23 | F>V | No | 1000Genomes | |
| ENSVATH13795202 | 42 | L>F | No | 1000Genomes | |
| tmp_1_27103415_G_A | 47 | V>I | No | 1000Genomes | |
| ENSVATH05129511 | 51 | G>E | No | 1000Genomes | |
| tmp_1_27103451_G_A | 59 | A>T | No | 1000Genomes | |
| ENSVATH05129512 | 71 | D>Y | No | 1000Genomes | |
| tmp_1_27103703_G_A | 79 | V>I | No | 1000Genomes | |
| tmp_1_27103707_C_G | 80 | P>R | No | 1000Genomes | |
| tmp_1_27103807_G_T | 113 | K>N | No | 1000Genomes | |
| ENSVATH05129518 | 146 | A>T | No | 1000Genomes | |
| ENSVATH00138425 | 154 | D>E | No | 1000Genomes | |
| ENSVATH05129521 | 173 | H>Y | No | 1000Genomes | |
| tmp_1_27103999_G_C | 177 | E>D | No | 1000Genomes | |
| ENSVATH05129524 | 182 | Q>H | No | 1000Genomes | |
| ENSVATH13795215 | 192 | C>R | No | 1000Genomes | |
| ENSVATH01523688 | 195 | E>D | No | 1000Genomes | |
| tmp_1_27104085_C_T | 206 | A>V | No | 1000Genomes | |
| ENSVATH13795216 | 211 | M>I | No | 1000Genomes | |
| tmp_1_27104336_G_A | 227 | A>T | No | 1000Genomes | |
| tmp_1_27104360_T_C | 235 | S>P | No | 1000Genomes | |
| tmp_1_27104366_C_T | 237 | L>F | No | 1000Genomes | |
| tmp_1_27104390_G_A | 245 | E>K | No | 1000Genomes | |
| ENSVATH05129531 | 248 | E>D | No | 1000Genomes | |
| tmp_1_27104402_T_G | 249 | F>V | No | 1000Genomes | |
| tmp_1_27104408_G_A | 251 | E>K | No | 1000Genomes | |
| ENSVATH05129532 | 256 | R>W | No | 1000Genomes | |
| tmp_1_27104480_C_T | 275 | L>F | No | 1000Genomes | |
| ENSVATH13795219 | 277 | D>G | No | 1000Genomes | |
| tmp_1_27104498_T_C | 281 | Y>H | No | 1000Genomes | |
| tmp_1_27104601_A_G | 315 | Y>C | No | 1000Genomes | |
| ENSVATH05129540 | 323 | A>T | No | 1000Genomes | |
| tmp_1_27104628_G_A | 324 | R>H | No | 1000Genomes | |
| tmp_1_27104644_G_C | 329 | W>C | No | 1000Genomes | |
| tmp_1_27104661_G_T | 335 | C>F | No | 1000Genomes | |
| ENSVATH05129545 | 381 | G>R | No | 1000Genomes | |
| ENSVATH13795224 | 386 | C>Y | No | 1000Genomes | |
| ENSVATH14471183 | 389 | K>T | No | 1000Genomes | |
| ENSVATH14471184 | 396 | H>L | No | 1000Genomes | |
| tmp_1_27105385_C_G | 408 | L>V | No | 1000Genomes | |
| tmp_1_27105413_G_A | 417 | R>Q | No | 1000Genomes | |
| tmp_1_27105418_C_T | 419 | Q>* | No | 1000Genomes | |
| ENSVATH13795246 | 436 | G>E | No | 1000Genomes | |
| tmp_1_27105507_C_A | 448 | F>L | No | 1000Genomes | |
| ENSVATH05129557 | 496 | S>C | No | 1000Genomes | |
| tmp_1_27105662_A_C | 500 | T>S | No | 1000Genomes |
No associated diseases with Q9C560
No regional properties for Q9C560
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for Q9C560 | |||
Functions
| Description | ||
|---|---|---|
| EC Number | 3.2.1.26 | Glycosidases, ie enzymes hydrolyzing O- and S-glycosyl compounds |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
No GO annotations of cellular component
| Name | Definition |
|---|---|
| No GO annotations for cellular component |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| glycopeptide alpha-N-acetylgalactosaminidase activity | Catalysis of the reaction: D-galactosyl-3-(N-acetyl-alpha-D-galactosaminyl)-L-serine + H2O = D-galactosyl-3-N-acetyl-alpha-D-galactosamine + L-serine in mucin-type glycoproteins. |
| sucrose alpha-glucosidase activity | Catalysis of the reaction: sucrose + H2O = alpha-D-glucose + beta-D-fructose. |
1 GO annotations of biological process
| Name | Definition |
|---|---|
| sucrose catabolic process | The chemical reactions and pathways resulting in the breakdown of sucrose, the disaccharide fructofuranosyl-glucopyranoside. |
5 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q69T31 | CINV1 | Cytosolic invertase 1 | Oryza sativa subsp japonica (Rice) | PR |
| F4I2X9 | INVD | Probable alkaline/neutral invertase D | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q84JL5 | INVH | Probable alkaline/neutral invertase A, chloroplastic | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9FXA8 | INVA | Alkaline/neutral invertase A, mitochondrial | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q9LQF2 | CINV1 | Alkaline/neutral invertase CINV1 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSLSLYDSAH | SLDGKSGWDT | PVFSMKDSMD | RNPMVTEAWE | ALCQSQVYFR | GKPVGTIAAY |
| 70 | 80 | 90 | 100 | 110 | 120 |
| DHASEEVLNY | DQVFVRDFVP | SALAFLMNGE | PEIVKNFLLK | TLHIQGQDKM | IDKFKLGDGA |
| 130 | 140 | 150 | 160 | 170 | 180 |
| MPASFKVLHN | PIKKTDTIIA | DFGESAIGRV | APVDSGFWWI | ILLRAYTKST | GDHSLAERPE |
| 190 | 200 | 210 | 220 | 230 | 240 |
| CQKGMRLILS | LCLSEGFDTF | PTLLCADGCS | MVDRRMGIYG | YPIEIQALFF | MALRSALSML |
| 250 | 260 | 270 | 280 | 290 | 300 |
| KHDSEGKEFM | EKIVKRLHAL | SFHMRSYFWL | DFQQLNDIYR | YKTEEYSHTA | VNKFNVIPDS |
| 310 | 320 | 330 | 340 | 350 | 360 |
| IPDWIFDFMP | LRGGYFVGNV | SPARMDFRWF | ALGNCIAILS | SLATPEQSMA | IMDLIEARWE |
| 370 | 380 | 390 | 400 | 410 | 420 |
| ELVGEMPLKI | CYPAMESHEW | GIVTGCDPKN | TRWSYHNGGS | WPVLLWLLTA | ASIKTGRPQI |
| 430 | 440 | 450 | 460 | 470 | 480 |
| ARRAIELAEA | RLLKDGWPEY | YDGKSGRFIG | KQARKSQTWS | IAGYLVAKMM | MDDPTHVGMI |
| 490 | |||||
| SMEEEKHMKP | PLRRSSSWT |