Q9BRA0
Gene name |
NAA38 (LSMD1, MAK31, PFAAP2) |
Protein name |
N-alpha-acetyltransferase 38, NatC auxiliary subunit |
Names |
LSM domain-containing protein 1, Phosphonoformate immuno-associated protein 2 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:84316 |
EC number |
|
Protein Class |
|
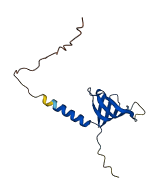
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
2 structures for Q9BRA0
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 7MX2 | EM | 364 A | C | 1-125 | PDB |
| AF-Q9BRA0-F1 | Predicted | AlphaFoldDB |
126 variants for Q9BRA0
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs375496712 CA8361984 |
3 | G>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs746272624 CA8361985 CA397931691 |
3 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8361983 rs375496712 |
3 | G>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs921537325 CA287528203 |
5 | G>E | No |
ClinGen TOPMed |
|
|
CA8361982 rs61744305 |
6 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs61744305 CA397931674 |
6 | P>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1157305506 CA397931669 |
7 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
CA397931667 rs1157305506 |
7 | T>N | No |
ClinGen TOPMed gnomAD |
|
|
CA8361978 rs766268302 |
8 | M>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8361980 rs372123662 CA8361979 |
8 | M>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8361981 rs372123662 |
8 | M>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8361976 rs750243558 |
12 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA397931632 rs764815714 |
13 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1202470779 CA397931629 |
14 | N>Y | No |
ClinGen gnomAD |
|
|
CA397931620 rs1465007556 |
15 | G>D | No |
ClinGen gnomAD |
|
| TCGA novel | 15 | G>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs75012482 CA8361974 |
16 | C>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1282263683 CA397931610 |
16 | C>Y | No |
ClinGen TOPMed |
|
|
CA8361972 rs760148454 |
17 | C>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8361973 rs776217403 |
17 | C>S | No |
ClinGen ExAC gnomAD |
|
|
rs776032070 CA8361970 |
18 | S>R | No |
ClinGen ExAC |
|
|
CA397931589 rs1246772868 |
19 | R>P | No |
ClinGen gnomAD |
|
|
rs1011689525 CA287528165 |
20 | R>L | No |
ClinGen Ensembl |
|
|
CA8361967 rs141942411 |
21 | Q>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1055664784 CA287528156 |
22 | S>G | No |
ClinGen Ensembl |
|
|
rs1435903526 CA397931564 |
22 | S>R | No |
ClinGen gnomAD |
|
|
CA287528151 rs558135552 |
23 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
CA8361966 rs771211255 |
25 | S>I | No |
ClinGen ExAC |
|
|
rs1318643532 CA397931531 |
26 | A>V | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
COSM1387277 CA397931520 rs1391769681 |
27 | G>= | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
rs1237369819 CA397931527 |
27 | G>R | No |
ClinGen TOPMed |
|
|
CA397931156 rs1298568112 |
28 | D>G | No |
ClinGen TOPMed |
|
|
CA287527849 rs764071998 |
28 | D>N | No |
ClinGen TOPMed gnomAD |
|
|
CA8361907 rs751002933 |
29 | S>L | No |
ClinGen ExAC gnomAD |
|
|
CA8361905 rs139370554 |
30 | D>E | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs776807764 CA8361904 |
31 | G>A | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 32 | E>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA397931134 rs1322357168 |
32 | E>Q | No |
ClinGen TOPMed |
|
|
CA287527813 rs908907085 |
33 | R>C | No |
ClinGen TOPMed |
|
|
CA397931125 rs1158076566 |
33 | R>H | No |
ClinGen gnomAD |
|
|
CA8361902 rs760700594 |
34 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA397931118 rs1181610906 |
34 | E>V | No |
ClinGen gnomAD |
|
|
CA397931108 rs1307719585 |
35 | D>E | No |
ClinGen TOPMed |
|
|
rs1235804240 CA397931111 |
35 | D>G | No |
ClinGen TOPMed |
|
|
rs775563570 CA8361901 |
36 | S>L | No |
ClinGen ExAC gnomAD |
|
|
CA397931099 rs770836926 |
37 | A>E | No |
ClinGen ExAC gnomAD |
|
|
CA397931102 rs1190633287 |
37 | A>T | No |
ClinGen gnomAD |
|
|
rs770836926 CA8361900 |
37 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA397931096 rs1222762250 |
38 | A>T | No |
ClinGen gnomAD |
|
|
rs983154834 CA287527808 |
38 | A>V | No |
ClinGen TOPMed |
|
| TCGA novel | 40 | R>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs375549790 CA8361898 |
40 | R>S | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs747987481 CA8361896 |
41 | A>G | No |
ClinGen ExAC gnomAD |
|
|
CA397931075 rs747987481 |
41 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA397931071 rs1297655615 |
42 | R>P | No |
ClinGen gnomAD |
|
|
CA397931072 rs1297655615 |
42 | R>Q | No |
ClinGen gnomAD |
|
|
rs1024681594 CA287527767 |
43 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA397931060 rs1436707798 |
44 | Q>* | No |
ClinGen gnomAD |
|
|
CA397931055 rs754690128 |
44 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8361893 rs746450587 |
45 | L>V | No |
ClinGen ExAC gnomAD |
|
|
CA8361891 rs750869109 |
46 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA8361890 rs750869109 |
46 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA8361889 rs765809610 |
47 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA397931034 rs1170546356 |
49 | L>I | No |
ClinGen gnomAD |
|
|
rs764245628 CA8361886 |
50 | N>Y | No |
ClinGen ExAC gnomAD |
|
|
rs866612553 CA287527726 |
51 | K>E | No |
ClinGen gnomAD |
|
|
rs866612553 CA397931021 |
51 | K>Q | No |
ClinGen gnomAD |
|
|
rs1489600328 CA397931012 |
52 | T>P | No |
ClinGen gnomAD |
|
|
CA8361885 rs752818984 |
53 | M>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA287527718 rs752818984 |
53 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8361884 rs775757791 |
56 | R>H | No |
ClinGen ExAC gnomAD |
|
|
rs1597870222 CA397930971 |
58 | T>I | No |
ClinGen Ensembl |
|
|
CA8361883 rs767483490 |
60 | G>V | No |
ClinGen ExAC |
|
|
CA397930953 rs1229972517 |
61 | R>P | No |
ClinGen gnomAD |
|
|
rs759710523 CA8361882 |
61 | R>W | No |
ClinGen ExAC gnomAD |
|
|
CA287527672 rs1001352322 |
62 | T>A | No |
ClinGen TOPMed gnomAD |
|
|
rs375441629 CA287527670 |
63 | L>V | No |
ClinGen ESP |
|
|
rs1404165168 CA397930922 |
67 | F>I | No |
ClinGen gnomAD |
|
|
rs1460414315 CA397930903 |
69 | C>F | No |
ClinGen TOPMed gnomAD |
|
|
rs1460414315 CA397930905 |
69 | C>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA287527615 rs994069426 |
72 | R>L | No |
ClinGen Ensembl |
|
|
rs755621692 CA8361876 |
73 | D>E | No |
ClinGen ExAC gnomAD |
|
|
CA397930881 rs1199133724 |
73 | D>N | No |
ClinGen gnomAD |
|
|
rs543597286 CA8361874 |
75 | N>S | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs757811947 CA8361872 |
79 | G>V | No |
ClinGen ExAC gnomAD |
|
|
CA397930829 rs1350818844 |
81 | A>P | No |
ClinGen TOPMed gnomAD |
|
|
CA397930827 rs1350818844 |
81 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs745419193 CA8361871 |
83 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA397930806 rs1597870064 |
84 | F>V | No |
ClinGen Ensembl |
|
|
rs779242477 CA8361869 |
84 | F>Y | No |
ClinGen ExAC gnomAD |
|
|
rs896826068 CA287527561 |
85 | L>H | No |
ClinGen TOPMed gnomAD |
|
|
rs757778170 CA8361868 |
85 | L>I | No |
ClinGen ExAC gnomAD |
|
|
CA397930785 rs1175888602 |
87 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
CA397930787 rs1567810991 |
87 | P>S | No |
ClinGen Ensembl |
|
|
CA397930697 rs1597869590 |
89 | D>G | No |
ClinGen Ensembl |
|
|
rs1414588003 CA397930777 |
89 | D>N | No |
ClinGen gnomAD |
|
|
CA397930689 rs144941102 |
90 | S>F | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs144941102 CA8361832 |
90 | S>Y | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA8361830 rs775372148 |
94 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA397930664 rs1423253990 |
94 | G>V | No |
ClinGen gnomAD |
|
|
rs775372148 CA397930667 |
94 | G>W | No |
ClinGen ExAC gnomAD |
|
|
CA287527137 rs928991976 |
95 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
rs1385211128 CA397930659 |
95 | E>G | No |
ClinGen gnomAD |
|
|
rs375659768 CA8361828 |
96 | P>S | No |
ClinGen ESP ExAC gnomAD |
|
|
rs375659768 CA8361829 |
96 | P>T | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1422414095 CA397930630 |
100 | G>V | No |
ClinGen TOPMed |
|
|
CA287527122 rs971187381 |
106 | G>A | No |
ClinGen Ensembl |
|
|
CA8361824 rs748837046 |
110 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1224501770 CA397930559 |
111 | S>F | No |
ClinGen gnomAD |
|
|
rs1597869518 CA397930554 |
112 | I>T | No |
ClinGen Ensembl |
|
|
rs1489834045 CA397930557 |
112 | I>V | No |
ClinGen gnomAD |
|
|
rs778213185 CA397930542 |
114 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs778213185 CA8361823 |
114 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA8361821 rs748393800 |
115 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
rs1268511157 CA397930529 |
116 | R>K | No |
ClinGen gnomAD |
|
|
rs755354923 CA8361819 |
117 | E>* | No |
ClinGen ExAC gnomAD |
|
|
rs201597277 CA8361817 |
118 | S>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8361818 rs747230149 |
118 | S>R | No |
ClinGen ExAC gnomAD |
|
|
CA8361816 rs758509027 |
118 | S>R | No |
ClinGen ExAC TOPMed |
|
|
CA397930503 rs1297961061 |
120 | T>I | No |
ClinGen TOPMed |
|
|
rs750548835 CA8361815 |
120 | T>S | No |
ClinGen ExAC |
|
|
rs1365502479 CA397930502 |
121 | G>R | No |
ClinGen gnomAD |
|
|
rs994038267 CA287527070 |
122 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
CA287527059 rs959446279 |
123 | P>L | No |
ClinGen TOPMed |
|
|
rs3744250 CA8361812 |
125 | L>F | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs3744250 CA287527042 |
125 | L>I | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
No associated diseases with Q9BRA0
4 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| NatC complex | A conserved complex that catalyzes the transfer of an acetyl group to the N-terminal residue of a protein acceptor molecule that has a Met-Ile, Met-Leu, Met-Trp, or Met-Phe N-terminus. In Saccharomyces the complex includes Mak3p, Mak10p, and Mak31p. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
No GO annotations of molecular function
| Name | Definition |
|---|---|
| No GO annotations for molecular function |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| N-terminal peptidyl-methionine acetylation | The acetylation of the N-terminal methionine of proteins to form the derivative N-acetyl-L-methionine. |
| negative regulation of apoptotic process | Any process that stops, prevents, or reduces the frequency, rate or extent of cell death by apoptotic process. |
1 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q9D2U5 | Naa38 | N-alpha-acetyltransferase 38, NatC auxiliary subunit | Mus musculus (Mouse) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAGAGPTMLL | REENGCCSRR | QSSSSAGDSD | GEREDSAAER | ARQQLEALLN | KTMRIRMTDG |
| 70 | 80 | 90 | 100 | 110 | 120 |
| RTLVGCFLCT | DRDCNVILGS | AQEFLKPSDS | FSAGEPRVLG | LAMVPGHHIV | SIEVQRESLT |
| GPPYL |