Q92600
Gene name |
CNOT9 |
Protein name |
CCR4-NOT transcription complex subunit 9 |
Names |
Cell differentiation protein RQCD1 homolog, Rcd-1 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:9125 |
EC number |
|
Protein Class |
|
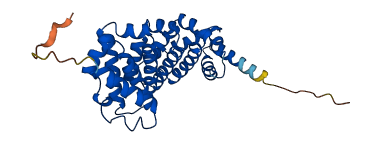
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
11 structures for Q92600
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 2FV2 | X-ray | 220 A | A/B/C/D | 18-285 | PDB |
| 4CRU | X-ray | 165 A | B | 19-285 | PDB |
| 4CRV | X-ray | 205 A | B | 19-285 | PDB |
| 4CT6 | X-ray | 210 A | B | 18-285 | PDB |
| 4CT7 | X-ray | 190 A | B | 16-285 | PDB |
| 5LSW | X-ray | 215 A | A/C | 19-285 | PDB |
| 5ONA | X-ray | 270 A | B/E | 19-285 | PDB |
| 5ONB | X-ray | 300 A | A/C/E/G | 19-285 | PDB |
| 6HOM | X-ray | 210 A | A/C | 19-285 | PDB |
| 6HON | X-ray | 220 A | A/C | 19-285 | PDB |
| AF-Q92600-F1 | Predicted | AlphaFoldDB |
88 variants for Q92600
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
RCV000427048 rs1057519957 RCV000434591 CA16602956 RCV000426322 RCV000444398 COSM247126 RCV000443624 |
87 | S>C | urinary_tract Hepatocellular carcinoma prostate Gastric adenocarcinoma Prostate adenocarcinoma Malignant melanoma of skin [Cosmic, ClinVar] | Yes |
ClinGen cosmic curated ClinVar Ensembl dbSNP |
|
CA16602955 rs1057519956 RCV000431838 RCV000421602 RCV000422236 RCV000438382 RCV000431636 |
87 | S>P | Variant assessed as Somatic; impact. Hepatocellular carcinoma Gastric adenocarcinoma Prostate adenocarcinoma Malignant melanoma of skin [NCI-TCGA, ClinVar] | Yes |
ClinGen ClinVar Ensembl NCI-TCGA dbSNP |
|
CA16602256 rs267599211 RCV002286407 COSM1692012 RCV000428811 |
131 | P>L | NS Variant assessed as Somatic; impact. skin CNOT9-associated neurodevelopmental disorder Malignant melanoma of skin [Cosmic, NCI-TCGA, ClinVar] | Yes |
ClinGen cosmic curated ClinVar Ensembl NCI-TCGA dbSNP |
|
CA16602954 RCV000439915 rs1057519955 |
131 | P>S | Variant assessed as Somatic; impact. Malignant melanoma of skin [NCI-TCGA, ClinVar] | Yes |
ClinGen ClinVar Ensembl NCI-TCGA dbSNP |
|
CA65769598 rs955622194 |
2 | H>Y | No |
ClinGen TOPMed |
|
|
rs781199533 CA2107601 |
5 | A>P | No |
ClinGen ExAC gnomAD |
|
|
CA65769611 rs758572192 |
5 | A>V | No |
ClinGen gnomAD |
|
|
rs1223363126 CA350566350 |
9 | P>S | No |
ClinGen gnomAD |
|
|
rs778082401 CA2107628 |
12 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2107631 rs201648255 |
17 | V>G | No |
ClinGen ExAC gnomAD |
|
|
CA2107630 rs771337558 |
17 | V>L | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 18 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 21 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 25 | W>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs759865221 CA2107632 |
28 | E>D | No |
ClinGen ExAC gnomAD |
|
|
CA2107633 rs769980167 |
31 | S>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA350566687 rs1422163728 |
31 | S>N | No |
ClinGen TOPMed |
|
|
rs1170015272 CA350566797 |
37 | N>S | No |
ClinGen TOPMed |
|
|
CA350566955 rs1405200853 |
50 | P>A | No |
ClinGen gnomAD |
|
|
rs761810000 CA2107635 |
53 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs1293627863 CA350566994 |
54 | P>H | No |
ClinGen gnomAD |
|
|
CA2107637 rs750409757 |
54 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA65776016 CA2107638 rs760332092 |
55 | M>I | No |
ClinGen ExAC gnomAD |
|
|
CA350567001 rs1433395376 |
55 | M>V | No |
ClinGen gnomAD |
|
|
rs1559245853 CA350567063 |
58 | H>Y | No |
ClinGen Ensembl |
|
|
rs866418872 CA65776021 |
59 | S>L | No |
ClinGen Ensembl |
|
|
CA65776023 rs868797174 |
62 | T>N | No |
ClinGen Ensembl |
|
| TCGA novel | 67 | L>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs757833728 CA2107661 |
71 | V>I | No |
ClinGen ExAC |
|
|
rs757833728 CA65777773 |
71 | V>L | No |
ClinGen ExAC |
|
|
TCGA novel rs761843684 CA2107662 |
74 | Y>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ExAC gnomAD NCI-TCGA |
|
rs751992889 CA2107663 |
75 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA65777785 rs1008307604 |
77 | I>V | No |
ClinGen gnomAD |
|
|
CA2107666 rs746201725 |
78 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA2107668 rs780367087 |
80 | P>H | No |
ClinGen ExAC gnomAD |
|
|
rs769567492 CA65777807 |
80 | P>S | No |
ClinGen Ensembl |
|
| TCGA novel | 90 | V>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
COSM1405470 CA350568423 rs1384270952 |
104 | P>L | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
COSM1240105 CA2107691 rs781114199 |
109 | A>V | oesophagus [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
CA350569014 rs148321797 |
112 | A>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA2107694 rs148321797 |
112 | A>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA350569035 rs1184159389 |
115 | I>V | No |
ClinGen gnomAD |
|
|
rs985331034 CA65779145 |
118 | F>C | No |
ClinGen TOPMed |
|
|
rs909910605 CA65779164 |
125 | T>S | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 127 | S>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA350569177 rs1303194811 |
136 | R>W | No |
ClinGen TOPMed gnomAD |
|
| VAR_042429 | 143 | I>T | No | UniProt | |
|
CA350569559 rs1489429363 |
147 | V>G | No |
ClinGen TOPMed gnomAD |
|
|
rs745779361 CA2107714 |
152 | Q>K | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 154 | V>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs769758941 CA2107715 |
156 | N>H | No |
ClinGen ExAC gnomAD |
|
|
CA350570000 rs1162179403 |
176 | E>K | No |
ClinGen gnomAD |
|
|
CA2107719 rs773985784 |
179 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs1559251516 CA350570986 |
186 | L>V | No |
ClinGen Ensembl |
|
|
rs1235938009 CA350571093 |
195 | G>R | No |
ClinGen TOPMed |
|
|
CA2107732 rs758592868 |
199 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs1283268656 CA350571218 |
203 | Y>C | No |
ClinGen TOPMed |
|
| TCGA novel | 205 | R>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs751598557 CA2107734 |
213 | L>S | No |
ClinGen ExAC gnomAD |
|
|
rs371657767 CA2107747 |
214 | G>S | No |
ClinGen ESP ExAC gnomAD |
|
|
rs369421512 CA2107749 |
221 | S>F | No |
ClinGen ESP ExAC gnomAD |
|
|
CA65784838 rs916840193 |
223 | E>D | No |
ClinGen TOPMed |
|
|
CA2107751 rs549239629 |
224 | P>A | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs757260957 CA2107753 |
232 | V>I | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 234 | R>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 238 | R>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs752696337 CA2107776 |
246 | R>C | No |
ClinGen ExAC gnomAD |
|
|
rs758205812 CA2107777 |
246 | R>H | No |
ClinGen ExAC gnomAD |
|
|
CA350573303 rs1362166553 |
258 | K>R | No |
ClinGen gnomAD |
|
| TCGA novel | 260 | T>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1400260914 CA350573337 |
260 | T>K | No |
ClinGen gnomAD |
|
|
rs769358178 CA2107783 |
263 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA350573409 rs1246426545 |
264 | Q>R | No |
ClinGen gnomAD |
|
|
COSM1224281 rs780357139 CA2107784 |
269 | D>G | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
CA350573544 rs1411948409 |
272 | T>M | No |
ClinGen TOPMed |
|
|
rs768993950 CA2107786 |
274 | R>C | No |
ClinGen ExAC gnomAD |
|
|
rs774747597 CA2107787 |
274 | R>H | No |
ClinGen ExAC gnomAD |
|
|
CA65785735 rs917847077 |
278 | Q>E | No |
ClinGen TOPMed |
|
|
rs1575000213 CA350573657 |
280 | V>G | No |
ClinGen Ensembl |
|
|
rs761992464 CA2107788 |
288 | V>F | No |
ClinGen ExAC gnomAD |
|
|
rs1575000233 CA350573771 |
288 | V>G | No |
ClinGen Ensembl |
|
|
rs772244185 CA2107789 |
289 | T>S | No |
ClinGen ExAC gnomAD |
|
|
CA2107791 rs760616522 |
290 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2107792 rs762147895 |
291 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2107794 rs554656744 |
292 | R>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA65785756 rs981210817 |
292 | R>W | No |
ClinGen TOPMed |
|
|
CA350573871 rs1575000262 |
298 | P>A | No |
ClinGen Ensembl |
|
|
rs751356765 CA2107796 |
299 | Q>* | No |
ClinGen ExAC gnomAD |
No associated diseases with Q92600
No regional properties for Q92600
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for Q92600 | |||
7 GO annotations of cellular component
| Name | Definition |
|---|---|
| CCR4-NOT complex | The Ccr4-Not complex is an eukaryotically conserved deadenylase that can initiate cytoplasmic mRNA decay, and reduce translation by releasing poly(A)-binding protein (Pab1/PABPC1). Ccr4-Not contains seven core subunits, including two poly(A)-specific exonucleases, Ccr4/CNOT6/CNOT6L and Caf1/Pop2/CNOT7/CNOT8. |
| CCR4-NOT core complex | The core of the CCR4-NOT complex. In Saccharomyces the CCR4-NOT core complex comprises Ccr4p, Caf1p, Caf40p, Caf130p, Not1p, Not2p, Not3p, Not4p, and Not5p. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| membrane | A lipid bilayer along with all the proteins and protein complexes embedded in it an attached to it. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| P-body | A focus in the cytoplasm where mRNAs may become inactivated by decapping or some other mechanism. Protein and RNA localized to these foci are involved in mRNA degradation, nonsense-mediated mRNA decay (NMD), translational repression, and RNA-mediated gene silencing. |
| protein-containing complex | A stable assembly of two or more macromolecules, i.e. proteins, nucleic acids, carbohydrates or lipids, in which at least one component is a protein and the constituent parts function together. |
5 GO annotations of molecular function
| Name | Definition |
|---|---|
| epidermal growth factor receptor binding | Binding to an epidermal growth factor receptor. |
| kinase binding | Binding to a kinase, any enzyme that catalyzes the transfer of a phosphate group. |
| nuclear receptor coactivator activity | A transcription coactivator activity that activates or increases the transcription of specific gene sets via binding to a DNA-bound nuclear receptor, either on its own or as part of a complex. Coactivators often act by altering chromatin structure and modifications. For example, one class of transcription coregulators modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. A fourth class of coactivator activity is the bridging of a DNA-binding transcription factor to the general (basal) transcription machinery. The Mediator complex, which bridges sequence-specific DNA binding transcription factors and RNA polymerase, is also a transcription coactivator. |
| protein domain specific binding | Binding to a specific domain of a protein. |
| protein homodimerization activity | Binding to an identical protein to form a homodimer. |
8 GO annotations of biological process
| Name | Definition |
|---|---|
| cytokine-mediated signaling pathway | The series of molecular signals initiated by the binding of a cytokine to a receptor on the surface of a cell, and ending with the regulation of a downstream cellular process, e.g. transcription. |
| gene silencing by RNA | A process in which an RNA molecule reduces expression of target genes. This can occur pre-transcriptionally by assembly of heterochromatin and prevention of transcription or co- or post-transcriptionally by targeting RNAs for degradation or by interfering with splicing or translation. This process starts once the inhibitory RNA molecule has been transcribed, and includes processing of the RNA such as cleavage, modifications, transport from the nucleus to the cytoplasm, loading onto the RISC complex, and the effect on transcription or translation. |
| negative regulation of intracellular estrogen receptor signaling pathway | Any process that stops, prevents, or reduces the frequency, rate or extent of the activity of an intracellular estrogen receptor signaling pathway. |
| negative regulation of translation | Any process that stops, prevents, or reduces the frequency, rate or extent of the chemical reactions and pathways resulting in the formation of proteins by the translation of mRNA or circRNA. |
| nuclear-transcribed mRNA poly(A) tail shortening | Shortening of the poly(A) tail of a nuclear-transcribed mRNA from full length to an oligo(A) length. |
| positive regulation of epidermal growth factor receptor signaling pathway | Any process that activates or increases the frequency, rate or extent of epidermal growth factor receptor signaling pathway activity. |
| positive regulation of peptidyl-serine phosphorylation | Any process that activates or increases the frequency, rate or extent of the phosphorylation of peptidyl-serine. |
| sex differentiation | The establishment of the sex of an organism by physical differentiation. |
5 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| A7MB47 | CNOT9 | CCR4-NOT transcription complex subunit 9 | Bos taurus (Bovine) | PR |
| Q9JKY0 | Cnot9 | CCR4-NOT transcription complex subunit 9 | Mus musculus (Mouse) | PR |
| Q5PQL2 | Cnot9 | CCR4-NOT transcription complex subunit 9 | Rattus norvegicus (Rat) | PR |
| Q6P819 | cnot9 | CCR4-NOT transcription complex subunit 9 | Xenopus tropicalis (Western clawed frog) (Silurana tropicalis) | PR |
| Q6NWL4 | cnot9 | CCR4-NOT transcription complex subunit 9 | Danio rerio (Zebrafish) (Brachydanio rerio) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MHSLATAAPV | PTTLAQVDRE | KIYQWINELS | SPETRENALL | ELSKKRESVP | DLAPMLWHSF |
| 70 | 80 | 90 | 100 | 110 | 120 |
| GTIAALLQEI | VNIYPSINPP | TLTAHQSNRV | CNALALLQCV | ASHPETRSAF | LAAHIPLFLY |
| 130 | 140 | 150 | 160 | 170 | 180 |
| PFLHTVSKTR | PFEYLRLTSL | GVIGALVKTD | EQEVINFLLT | TEIIPLCLRI | MESGSELSKT |
| 190 | 200 | 210 | 220 | 230 | 240 |
| VATFILQKIL | LDDTGLAYIC | QTYERFSHVA | MILGKMVLQL | SKEPSARLLK | HVVRCYLRLS |
| 250 | 260 | 270 | 280 | 290 | |
| DNPRAREALR | QCLPDQLKDT | TFAQVLKDDT | TTKRWLAQLV | KNLQEGQVTD | PRGIPLPPQ |