Q8WVD3
Gene name |
RNF138 |
Protein name |
E3 ubiquitin-protein ligase RNF138 |
Names |
Nemo-like kinase-associated RING finger protein, NLK-associated RING finger protein, hNARF, RING finger protein 138, RING-type E3 ubiquitin transferase RNF138 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:51444 |
EC number |
2.3.2.27: Aminoacyltransferases |
Protein Class |
|
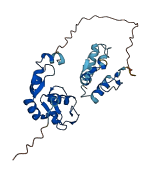
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q8WVD3
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q8WVD3-F1 | Predicted | AlphaFoldDB |
117 variants for Q8WVD3
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA402255445 rs1399475410 |
2 | A>V | No |
ClinGen gnomAD |
|
|
CA8930616 rs768736694 |
3 | E>A | No |
ClinGen ExAC gnomAD |
|
|
CA8930617 rs116403100 |
3 | E>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA8930615 rs768736694 |
3 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA402255447 rs1289349465 |
3 | E>K | No |
ClinGen TOPMed |
|
|
CA402255455 rs1341861985 |
4 | D>A | No |
ClinGen gnomAD |
|
|
CA298319553 rs552128671 |
5 | L>F | No |
ClinGen 1000Genomes TOPMed |
|
|
CA402255462 rs1398614699 |
5 | L>H | No |
ClinGen gnomAD |
|
|
CA8930618 rs770913259 |
6 | S>C | No |
ClinGen ExAC gnomAD |
|
|
rs1326281405 CA402255474 |
7 | A>V | No |
ClinGen gnomAD |
|
|
CA8930619 rs776550133 |
8 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402255492 rs1254717414 |
10 | S>F | No |
ClinGen gnomAD |
|
|
rs764761557 CA8930621 |
11 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs1445480537 CA402255505 |
12 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
CA298319554 rs971442195 |
14 | D>V | No |
ClinGen Ensembl |
|
|
CA402255522 rs1262208209 |
15 | D>H | No |
ClinGen gnomAD |
|
|
CA8930623 rs762391892 |
20 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA8930626 rs757749867 |
26 | K>R | No |
ClinGen ExAC gnomAD |
|
|
CA298319556 rs927403921 |
27 | T>R | No |
ClinGen gnomAD |
|
| TCGA novel | 29 | V>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA8930630 rs780166210 |
32 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402255635 rs780166210 |
32 | T>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1193003840 CA402255645 |
33 | A>V | No |
ClinGen TOPMed |
|
| TCGA novel | 35 | Q>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA402255661 rs1568220269 |
35 | Q>H | No |
ClinGen Ensembl |
|
|
CA402255654 rs1487578116 |
35 | Q>K | No |
ClinGen TOPMed |
|
|
CA402255658 rs1264931099 |
35 | Q>R | No |
ClinGen TOPMed |
|
|
rs1351514733 CA402255670 |
37 | V>F | No |
ClinGen gnomAD |
|
|
rs758508871 CA8930655 |
47 | M>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs748204194 CA8930654 |
47 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8930656 rs781300995 |
48 | R>K | No |
ClinGen ExAC gnomAD |
|
|
CA402255775 rs1315971206 |
50 | S>G | No |
ClinGen gnomAD |
|
|
rs775349440 CA8930659 |
51 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs1481305138 CA402255791 |
52 | A>V | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs768267760 CA8930661 |
53 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs1422182371 CA402255829 |
58 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs1370502566 CA402255844 |
60 | N>S | No |
ClinGen TOPMed |
|
|
CA298321934 rs754554442 |
63 | R>I | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 67 | A>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA402255916 rs1363216536 |
71 | R>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs1402590553 CA402255921 |
72 | A>S | No |
ClinGen gnomAD |
|
| TCGA novel | 74 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1175427545 CA402255943 |
75 | L>F | No |
ClinGen gnomAD |
|
|
CA8930663 rs761336148 |
76 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA8930664 rs766960918 |
77 | N>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8930667 rs200018900 |
78 | I>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA402255978 rs1315758650 |
80 | R>K | No |
ClinGen gnomAD |
|
|
rs7229690 CA8930668 VAR_052109 |
81 | K>R | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs766714253 CA8930669 |
82 | F>L | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 84 | G>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 91 | K>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA402256069 rs1483366182 |
92 | Q>H | No |
ClinGen gnomAD |
|
|
rs771639268 CA8930688 |
95 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs747736592 CA8930686 |
95 | F>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs761132854 CA8930689 |
96 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402256113 rs1455606551 |
97 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs771435681 CA8930690 |
97 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402256205 rs1418941462 |
109 | Q>P | No |
ClinGen gnomAD |
|
|
rs1318713318 CA402256210 |
110 | D>N | No |
ClinGen gnomAD |
|
|
CA298322110 rs200800390 |
117 | I>V | No |
ClinGen gnomAD |
|
|
CA402256265 rs1306686290 |
118 | I>V | No |
ClinGen gnomAD |
|
|
rs1352506409 CA402256279 |
120 | N>Y | No |
ClinGen gnomAD |
|
|
rs763261761 CA8930695 |
122 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
rs764136681 CA8930696 |
123 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA8930700 rs753660399 |
126 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA8930699 rs780062639 |
126 | D>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8930701 rs754775307 |
127 | S>A | No |
ClinGen ExAC gnomAD |
|
|
rs1009524449 CA298322111 |
129 | G>A | No |
ClinGen TOPMed |
|
|
CA8930702 rs778679208 |
130 | N>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA298323221 rs76178144 |
131 | S>R | No |
ClinGen Ensembl |
|
|
rs1330533554 CA402256376 |
133 | R>G | No |
ClinGen gnomAD |
|
|
rs1338322894 CA402256379 |
133 | R>T | No |
ClinGen gnomAD |
|
|
CA298323222 rs78071298 |
135 | E>K | No |
ClinGen Ensembl |
|
|
rs1327006694 CA402256407 |
137 | S>F | No |
ClinGen Ensembl |
|
|
rs1294294734 CA402256411 |
138 | T>A | No |
ClinGen gnomAD |
|
|
rs1357692531 CA402256428 |
140 | D>E | No |
ClinGen TOPMed gnomAD |
|
|
CA402256457 rs1217358916 |
144 | T>I | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 144 | T>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA402256463 rs1555699737 |
145 | Y>F | No |
ClinGen Ensembl |
|
|
CA298323223 rs1040860551 |
147 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
CA402256490 rs1318740748 |
149 | T>A | No |
ClinGen gnomAD |
|
|
rs1211908053 CA402256518 |
151 | S>F | No |
ClinGen gnomAD |
|
|
rs1282702998 CA402256529 |
153 | G>D | No |
ClinGen gnomAD |
|
| TCGA novel | 155 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA402256547 rs1275655873 |
156 | T>A | No |
ClinGen TOPMed |
|
| TCGA novel | 165 | S>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs772660133 CA298323334 |
168 | T>I | No |
ClinGen Ensembl |
|
|
COSM987714 CA8930742 rs759513121 |
171 | R>C | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs554701391 CA8930743 |
171 | R>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs752580212 CA8930744 |
174 | D>A | No |
ClinGen ExAC gnomAD |
|
|
CA298323335 rs914673896 |
181 | L>R | No |
ClinGen Ensembl |
|
|
rs1477384304 CA402256742 |
183 | Q>H | No |
ClinGen gnomAD |
|
|
CA298323336 rs968861963 |
184 | I>T | No |
ClinGen gnomAD |
|
|
CA402256761 rs1481844928 |
186 | P>L | No |
ClinGen gnomAD |
|
| TCGA novel | 186 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1173920254 CA402256764 |
187 | V>L | No |
ClinGen gnomAD |
|
|
rs1246796336 CA402256794 |
190 | P>A | No |
ClinGen TOPMed |
|
|
rs369606904 CA8930756 |
193 | V>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs780720605 CA8930755 |
193 | V>M | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 196 | P>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs971419660 CA298323530 |
197 | W>G | No |
ClinGen TOPMed |
|
|
CA8930758 rs779136044 |
199 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA402256864 rs1364774010 |
200 | P>S | No |
ClinGen gnomAD |
|
|
rs1309524763 CA402256932 |
208 | V>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
CA402256943 rs1390633384 |
209 | S>T | No |
ClinGen gnomAD |
|
| TCGA novel | 213 | Q>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 217 | F>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA402257018 rs1328011069 |
218 | D>E | No |
ClinGen gnomAD |
|
|
CA402257072 rs1310311957 |
224 | N>S | No |
ClinGen TOPMed gnomAD |
|
|
CA298323813 rs111517421 |
226 | Q>R | No |
ClinGen Ensembl |
|
|
rs1182230646 CA402257095 |
228 | D>H | No |
ClinGen TOPMed |
|
|
rs777981886 CA8930778 |
233 | Y>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1274943635 CA402257143 |
234 | Q>R | No |
ClinGen gnomAD |
|
|
rs747164148 CA8930779 |
235 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA8930780 rs771064744 |
239 | E>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA402257189 rs1203194550 |
241 | F>S | No |
ClinGen gnomAD |
|
|
rs1251598383 CA402257216 |
245 | I>V | No |
ClinGen gnomAD |
No associated diseases with Q8WVD3
1 regional properties for Q8WVD3
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | HemY, N-terminal | 27 - 116 | IPR010817 |
Functions
| Description | ||
|---|---|---|
| EC Number | 2.3.2.27 | Aminoacyltransferases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
2 GO annotations of cellular component
| Name | Definition |
|---|---|
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| site of double-strand break | A region of a chromosome at which a DNA double-strand break has occurred. DNA damage signaling and repair proteins accumulate at the lesion to respond to the damage and repair the DNA to form a continuous DNA helix. |
4 GO annotations of molecular function
| Name | Definition |
|---|---|
| metal ion binding | Binding to a metal ion. |
| protein kinase binding | Binding to a protein kinase, any enzyme that catalyzes the transfer of a phosphate group, usually from ATP, to a protein substrate. |
| single-stranded DNA binding | Binding to single-stranded DNA. |
| ubiquitin protein ligase activity | Catalysis of the transfer of ubiquitin to a substrate protein via the reaction X-ubiquitin + S -> X + S-ubiquitin, where X is either an E2 or E3 enzyme, the X-ubiquitin linkage is a thioester bond, and the S-ubiquitin linkage is an amide bond: an isopeptide bond between the C-terminal glycine of ubiquitin and the epsilon-amino group of lysine residues in the substrate or, in the linear extension of ubiquitin chains, a peptide bond the between the C-terminal glycine and N-terminal methionine of ubiquitin residues. |
4 GO annotations of biological process
| Name | Definition |
|---|---|
| DNA double-strand break processing involved in repair via single-strand annealing | The 5' to 3' exonucleolytic resection of the DNA at the site of the break to form a 3' single-strand DNA overhang that results in the repair of a double strand break via single-strand annealing. |
| double-strand break repair via homologous recombination | The error-free repair of a double-strand break in DNA in which the broken DNA molecule is repaired using homologous sequences. A strand in the broken DNA searches for a homologous region in an intact chromosome to serve as the template for DNA synthesis. The restoration of two intact DNA molecules results in the exchange, reciprocal or nonreciprocal, of genetic material between the intact DNA molecule and the broken DNA molecule. |
| protein ubiquitination | The process in which one or more ubiquitin groups are added to a protein. |
| Wnt signaling pathway | The series of molecular signals initiated by binding of a Wnt protein to a frizzled family receptor on the surface of the target cell and ending with a change in cell state. |
1 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q9CQE0 | Rnf138 | E3 ubiquitin-protein ligase RNF138 | Mus musculus (Mouse) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAEDLSAATS | YTEDDFYCPV | CQEVLKTPVR | TTACQHVFCR | KCFLTAMRES | GAHCPLCRGN |
| 70 | 80 | 90 | 100 | 110 | 120 |
| VTRRERACPE | RALDLENIMR | KFSGSCRCCA | KQIKFYRMRH | HYKSCKKYQD | EYGVSSIIPN |
| 130 | 140 | 150 | 160 | 170 | 180 |
| FQISQDSVGN | SNRSETSTSD | NTETYQENTS | SSGHPTFKCP | LCQESNFTRQ | RLLDHCNSNH |
| 190 | 200 | 210 | 220 | 230 | 240 |
| LFQIVPVTCP | ICVSLPWGDP | SQITRNFVSH | LNQRHQFDYG | EFVNLQLDEE | TQYQTAVEES |
| FQVNI |