Q8NHG8
Gene name |
ZNRF2 (RNF202) |
Protein name |
E3 ubiquitin-protein ligase ZNRF2 |
Names |
Protein Ells2, RING finger protein 202, RING-type E3 ubiquitin transferase ZNRF2, Zinc/RING finger protein 2 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:223082 |
EC number |
2.3.2.27: Aminoacyltransferases |
Protein Class |
|
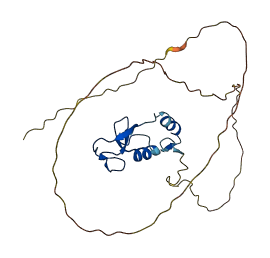
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q8NHG8
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q8NHG8-F1 | Predicted | AlphaFoldDB |
183 variants for Q8NHG8
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs1221536508 CA367245261 |
2 | G>C | No |
ClinGen TOPMed |
|
|
CA367245274 rs1347821428 |
3 | A>T | No |
ClinGen gnomAD |
|
|
CA367245322 rs1239768249 |
4 | K>Q | No |
ClinGen gnomAD |
|
|
CA367245337 rs1262391942 |
5 | Q>E | No |
ClinGen gnomAD |
|
|
rs1303274563 CA367245361 |
7 | G>C | No |
ClinGen TOPMed gnomAD |
|
|
rs1303274563 CA367245360 |
7 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1303274563 CA367245359 |
7 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
CA367245364 rs1339711874 |
7 | G>V | No |
ClinGen TOPMed gnomAD |
|
|
rs761956095 CA4204248 |
8 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs952268581 CA156592049 |
8 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
CA367245401 rs1227590084 |
10 | A>V | No |
ClinGen gnomAD |
|
|
rs1398971025 CA367245405 |
11 | A>V | No |
ClinGen TOPMed |
|
|
CA367245414 rs1269720585 |
12 | N>K | No |
ClinGen TOPMed gnomAD |
|
|
rs1224760969 CA367245412 |
12 | N>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1488218643 CA367245419 |
13 | G>D | No |
ClinGen gnomAD |
|
|
rs1192135641 CA367245426 |
14 | R>L | No |
ClinGen gnomAD |
|
|
CA367245422 rs1201784771 |
14 | R>S | No |
ClinGen TOPMed gnomAD |
|
|
CA367245433 rs1475940580 |
15 | T>M | No |
ClinGen TOPMed gnomAD |
|
|
CA4204250 rs750693861 |
16 | R>H | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 16 | R>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1411141608 CA367245442 |
17 | A>E | No |
ClinGen TOPMed gnomAD |
|
|
rs1411141608 CA367245443 |
17 | A>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1411141608 CA367245444 |
17 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA367245458 rs1163616735 |
19 | S>L | No |
ClinGen gnomAD |
|
|
rs1273268126 CA367245461 |
20 | G>C | No |
ClinGen TOPMed |
|
|
rs1332143328 CA367245468 |
21 | S>L | No |
ClinGen TOPMed |
|
|
rs991752819 CA156592052 |
22 | D>E | No |
ClinGen TOPMed |
|
|
CA367245475 rs1162382138 |
22 | D>G | No |
ClinGen gnomAD |
|
|
CA156592053 rs913585707 |
24 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA156592054 rs945106276 |
25 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
CA367245489 rs1327003842 |
25 | S>P | No |
ClinGen gnomAD |
|
|
CA367245498 rs1446972989 |
26 | S>N | No |
ClinGen gnomAD |
|
|
CA367245504 rs1282240144 |
27 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
CA367245510 rs1429196772 |
28 | S>G | No |
ClinGen TOPMed |
|
|
CA367245516 rs1352186120 |
28 | S>R | No |
ClinGen TOPMed |
|
| TCGA novel | 29 | G>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA367245532 rs1395560838 |
31 | A>D | No |
ClinGen TOPMed gnomAD |
|
|
rs780405670 CA4204252 |
32 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4204253 rs753728684 |
33 | G>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA367245556 rs1214623819 |
35 | A>E | No |
ClinGen gnomAD |
|
|
rs1214623819 CA367245558 |
35 | A>V | No |
ClinGen gnomAD |
|
|
rs1308820217 CA367245565 |
37 | G>S | No |
ClinGen gnomAD |
|
|
CA156592056 rs932535983 |
40 | G>D | No |
ClinGen TOPMed |
|
|
CA367245593 rs1187232561 |
41 | A>G | No |
ClinGen TOPMed gnomAD |
|
|
CA367245589 rs1380538610 |
41 | A>S | No |
ClinGen gnomAD |
|
|
CA156592057 rs1050106525 |
42 | R>W | No |
ClinGen TOPMed |
|
| TCGA novel | 43 | A>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA367245622 rs1236109641 |
47 | G>W | No |
ClinGen TOPMed gnomAD |
|
|
rs1227671330 CA367245631 |
48 | R>T | No |
ClinGen TOPMed |
|
|
CA367245639 rs1360237580 |
49 | F>S | No |
ClinGen TOPMed gnomAD |
|
|
CA156592058 rs962023236 |
49 | F>V | No |
ClinGen TOPMed |
|
|
CA367245653 rs1213237700 |
51 | A>V | No |
ClinGen TOPMed |
|
|
rs1370286948 CA367245657 |
52 | Q>P | No |
ClinGen TOPMed |
|
|
CA367245680 rs1333493051 |
55 | S>R | No |
ClinGen TOPMed |
|
|
CA367245687 rs1462684963 |
56 | A>V | No |
ClinGen TOPMed |
|
|
CA367245695 rs1249803865 |
57 | H>Q | No |
ClinGen gnomAD |
|
|
CA367245701 rs1372785071 |
58 | Q>L | No |
ClinGen TOPMed |
|
|
rs1434693833 CA367245708 |
59 | P>R | No |
ClinGen TOPMed |
|
|
CA156592061 rs557498081 |
60 | S>G | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
CA367245732 rs1480098921 |
63 | G>D | No |
ClinGen TOPMed |
|
|
rs536666116 CA4204254 |
64 | G>A | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1392053724 CA367245747 |
66 | A>P | No |
ClinGen TOPMed |
|
|
rs1375810810 CA367245758 |
68 | A>T | No |
ClinGen TOPMed |
|
|
rs1159833655 CA367245765 |
69 | A>P | No |
ClinGen gnomAD |
|
|
rs1418003829 CA367245769 |
69 | A>V | No |
ClinGen TOPMed |
|
|
CA367245786 rs1210693413 |
72 | P>R | No |
ClinGen TOPMed |
|
|
CA367245784 rs1281490797 |
72 | P>S | No |
ClinGen TOPMed |
|
|
rs1385392217 CA367245789 |
73 | A>P | No |
ClinGen TOPMed gnomAD |
|
|
CA367245788 rs1385392217 |
73 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
CA367245790 rs1385392217 |
73 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
CA367245793 rs1445891464 |
73 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA367245795 rs1312029847 |
74 | A>P | No |
ClinGen TOPMed |
|
|
CA367245794 rs1312029847 |
74 | A>T | No |
ClinGen TOPMed |
|
|
rs1372172775 CA367245798 |
74 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1583559001 CA367245806 |
76 | A>T | No |
ClinGen Ensembl |
|
|
CA156592070 rs913553039 |
78 | P>A | No |
ClinGen TOPMed |
|
|
rs1299669432 CA367245826 |
79 | R>P | No |
ClinGen TOPMed gnomAD |
|
|
CA367245837 rs1166377589 |
81 | R>S | No |
ClinGen TOPMed |
|
|
CA367245847 rs1475324365 |
82 | S>F | No |
ClinGen TOPMed |
|
|
CA367245851 rs1256386645 |
83 | L>V | No |
ClinGen TOPMed |
|
|
CA367245863 rs1264419941 |
85 | G>W | No |
ClinGen TOPMed |
|
|
CA4204255 rs184594665 |
87 | V>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs931332579 CA156592073 |
89 | S>G | No |
ClinGen TOPMed |
|
|
CA156592075 rs925095983 |
94 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
CA156592074 rs925095983 |
94 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1049546256 CA367245928 |
96 | A>E | No |
ClinGen TOPMed gnomAD |
|
|
CA156592076 rs1049546256 |
96 | A>G | No |
ClinGen TOPMed gnomAD |
|
|
CA367245929 rs1049546256 |
96 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA367245939 rs1315982767 |
98 | Q>R | No |
ClinGen gnomAD |
|
|
CA367245948 rs1412653577 |
99 | S>F | No |
ClinGen TOPMed |
|
|
CA156592077 rs912396825 |
100 | P>A | No |
ClinGen TOPMed |
|
|
CA367245951 rs912396825 |
100 | P>S | No |
ClinGen TOPMed |
|
|
rs1281380957 CA367245961 |
101 | F>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1200398311 CA367245979 |
104 | P>A | No |
ClinGen gnomAD |
|
|
rs1200398311 CA367245980 |
104 | P>S | No |
ClinGen gnomAD |
|
|
rs1166397645 CA367245991 |
105 | N>K | No |
ClinGen TOPMed |
|
| TCGA novel | 105 | N>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1462922885 CA367246019 |
109 | G>D | No |
ClinGen gnomAD |
|
|
rs1461514467 CA367246016 |
109 | G>S | No |
ClinGen TOPMed |
|
|
rs777225411 CA4204258 |
110 | P>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs777225411 CA367246026 |
110 | P>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA367246023 rs1583559075 |
110 | P>S | No |
ClinGen Ensembl |
|
|
rs897814682 CA156592079 |
112 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
rs897814682 CA367246035 |
112 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
CA367246073 rs1468987960 |
117 | V>G | No |
ClinGen TOPMed |
|
|
rs1215564193 CA367246069 |
117 | V>L | No |
ClinGen TOPMed |
|
|
rs1272727353 CA367246095 |
120 | S>I | No |
ClinGen TOPMed |
|
|
rs1170740940 CA367246100 |
121 | P>S | No |
ClinGen gnomAD |
|
|
CA156592081 rs1049606979 |
123 | D>E | No |
ClinGen TOPMed gnomAD |
|
|
rs1270537197 CA367246116 |
123 | D>G | No |
ClinGen TOPMed |
|
|
CA367246124 rs1470108774 |
124 | G>V | No |
ClinGen gnomAD |
|
|
rs776251695 CA4204262 |
126 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA367246135 rs1399785257 |
126 | G>V | No |
ClinGen gnomAD |
|
|
rs1203633005 CA367246136 |
127 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
rs763439410 CA4204263 |
129 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1330913241 CA367246148 |
129 | D>H | No |
ClinGen gnomAD |
|
|
rs768835266 CA4204264 |
130 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs774932282 CA4204265 |
131 | P>A | No |
ClinGen ExAC TOPMed |
|
|
CA156592082 rs927409888 |
132 | V>G | No |
ClinGen Ensembl |
|
|
rs1326330641 CA367246175 CA367246174 |
134 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
CA367246176 rs1326330641 |
134 | G>W | No |
ClinGen TOPMed gnomAD |
|
|
CA156592083 rs937468746 |
135 | S>G | No |
ClinGen Ensembl |
|
|
rs767733858 CA4204267 |
135 | S>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs750567165 CA4204268 |
136 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1250881912 CA367246194 |
137 | G>D | No |
ClinGen gnomAD |
|
|
CA367246192 rs1197184095 |
137 | G>R | No |
ClinGen gnomAD |
|
|
rs1196197106 CA367246201 |
138 | G>V | No |
ClinGen gnomAD |
|
|
rs1033830989 CA367246207 |
139 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1033830989 CA156592085 |
139 | P>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs760828374 CA4204269 |
140 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs766778624 CA367246219 |
142 | V>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs766778624 CA4204270 |
142 | V>M | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 144 | G>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA367246231 rs1194975102 |
144 | G>R | No |
ClinGen TOPMed |
|
|
rs754819476 CA4204272 |
146 | L>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs541343305 CA367246257 |
148 | A>G | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs541343305 CA4204273 |
148 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA4204276 rs758372967 |
149 | H>Q | No |
ClinGen ExAC gnomAD |
|
|
CA4204274 rs752713010 |
149 | H>Y | No |
ClinGen ExAC gnomAD |
|
|
CA4204277 rs746578454 |
150 | L>F | No |
ClinGen ExAC gnomAD |
|
|
CA367246285 rs966347232 |
153 | H>P | No |
ClinGen TOPMed |
|
|
CA4204281 rs745452890 |
153 | H>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA156592087 rs966347232 |
153 | H>R | No |
ClinGen TOPMed |
|
|
rs774537833 CA4204282 |
154 | M>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs772751188 CA4204284 |
154 | M>R | No |
ClinGen ExAC gnomAD |
|
|
CA4204283 rs774537833 |
154 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA156592088 rs1032432013 |
155 | F>L | No |
ClinGen TOPMed gnomAD |
|
|
CA4204379 rs147318339 |
165 | K>E | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1239798095 CA367249087 |
166 | F>L | No |
ClinGen TOPMed |
|
|
CA4204380 rs756452477 |
167 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA367249133 rs1345556040 |
173 | D>G | No |
ClinGen gnomAD |
|
|
CA156596520 rs868553154 |
174 | L>S | No |
ClinGen Ensembl |
|
|
CA367249169 rs1363725715 |
178 | M>I | No |
ClinGen gnomAD |
|
|
CA4204381 rs140727226 |
178 | M>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs979815730 CA156596521 |
178 | M>V | No |
ClinGen Ensembl |
|
|
rs1424332478 CA367249215 |
184 | R>* | No |
ClinGen gnomAD |
|
|
CA4204383 rs142290977 |
184 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1350517194 CA367249245 |
186 | T>I | No |
ClinGen gnomAD |
|
|
CA367245090 rs1435544394 |
189 | E>A | No |
ClinGen gnomAD |
|
| TCGA novel | 191 | V>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA156600130 rs749781284 |
191 | V>I | No |
ClinGen Ensembl |
|
| TCGA novel | 194 | K>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs550905339 CA4204402 |
195 | D>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs758403495 CA4204403 |
199 | C>Y | No |
ClinGen ExAC gnomAD |
|
|
rs1470187292 CA367245163 |
200 | A>T | No |
ClinGen gnomAD |
|
|
rs751775912 CA4204405 |
202 | C>W | No |
ClinGen ExAC gnomAD |
|
|
CA156600132 rs866147007 |
204 | E>D | No |
ClinGen Ensembl |
|
|
rs745627656 CA4204408 |
208 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
rs181107014 CA367245224 |
208 | Q>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1331015548 CA367245222 |
208 | Q>R | No |
ClinGen gnomAD |
|
|
rs779838395 CA4204410 |
210 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
CA367245251 rs1282002657 |
212 | I>L | No |
ClinGen gnomAD |
|
|
rs748891643 CA4204411 |
213 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA4204412 rs767981100 |
214 | R>* | No |
ClinGen ExAC gnomAD |
|
|
CA4204414 rs761417571 |
220 | I>M | No |
ClinGen ExAC gnomAD |
|
|
CA367245315 rs1291550203 |
220 | I>V | No |
ClinGen gnomAD |
|
|
CA367245351 rs1583596949 |
222 | H>L | No |
ClinGen Ensembl |
|
|
CA367245346 rs1490147486 |
222 | H>Y | No |
ClinGen gnomAD |
|
|
CA367246341 rs1391067439 |
227 | D>G | No |
ClinGen gnomAD |
|
|
CA156600938 rs868322083 |
234 | R>K | No |
ClinGen gnomAD |
|
|
CA367246394 rs868322083 |
234 | R>T | No |
ClinGen gnomAD |
|
|
rs747638902 CA156600940 |
238 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4204434 rs771774085 |
242 | D>V | No |
ClinGen ExAC |
No associated diseases with Q8NHG8
1 regional properties for Q8NHG8
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Zinc finger, RING-type | 198 - 239 | IPR001841 |
Functions
| Description | ||
|---|---|---|
| EC Number | 2.3.2.27 | Aminoacyltransferases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
14 GO annotations of cellular component
| Name | Definition |
|---|---|
| anchoring junction | A cell junction that mechanically attaches a cell (and its cytoskeleton) to neighboring cells or to the extracellular matrix. |
| cell projection | A prolongation or process extending from a cell, e.g. a flagellum or axon. |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| cytoplasmic vesicle membrane | The lipid bilayer surrounding a cytoplasmic vesicle. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| endosome membrane | The lipid bilayer surrounding an endosome. |
| fibrillar center | A structure found most metazoan nucleoli, but not usually found in lower eukaryotes; surrounded by the dense fibrillar component; the zone of transcription from multiple copies of the pre-rRNA genes is in the border region between these two structures. |
| intracellular membrane-bounded organelle | Organized structure of distinctive morphology and function, bounded by a single or double lipid bilayer membrane and occurring within the cell. Includes the nucleus, mitochondria, plastids, vacuoles, and vesicles. Excludes the plasma membrane. |
| lysosomal membrane | The lipid bilayer surrounding the lysosome and separating its contents from the cell cytoplasm. |
| membrane | A lipid bilayer along with all the proteins and protein complexes embedded in it an attached to it. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| plasma membrane | The membrane surrounding a cell that separates the cell from its external environment. It consists of a phospholipid bilayer and associated proteins. |
| presynaptic membrane | A specialized area of membrane of the axon terminal that faces the plasma membrane of the neuron or muscle fiber with which the axon terminal establishes a synaptic junction; many synaptic junctions exhibit structural presynaptic characteristics, such as conical, electron-dense internal protrusions, that distinguish it from the remainder of the axon plasma membrane. |
| protein-containing complex | A stable assembly of two or more macromolecules, i.e. proteins, nucleic acids, carbohydrates or lipids, in which at least one component is a protein and the constituent parts function together. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| metal ion binding | Binding to a metal ion. |
| ubiquitin protein ligase activity | Catalysis of the transfer of ubiquitin to a substrate protein via the reaction X-ubiquitin + S -> X + S-ubiquitin, where X is either an E2 or E3 enzyme, the X-ubiquitin linkage is a thioester bond, and the S-ubiquitin linkage is an amide bond: an isopeptide bond between the C-terminal glycine of ubiquitin and the epsilon-amino group of lysine residues in the substrate or, in the linear extension of ubiquitin chains, a peptide bond the between the C-terminal glycine and N-terminal methionine of ubiquitin residues. |
2 GO annotations of biological process
| Name | Definition |
|---|---|
| proteasome-mediated ubiquitin-dependent protein catabolic process | The chemical reactions and pathways resulting in the breakdown of a protein or peptide by hydrolysis of its peptide bonds, initiated by the covalent attachment of ubiquitin, and mediated by the proteasome. |
| protein K48-linked ubiquitination | A protein ubiquitination process in which a polymer of ubiquitin, formed by linkages between lysine residues at position 48 of the ubiquitin monomers, is added to a protein. K48-linked ubiquitination targets the substrate protein for degradation. |
1 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q71FD5 | Znrf2 | E3 ubiquitin-protein ligase ZNRF2 | Mus musculus (Mouse) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MGAKQSGPAA | ANGRTRAYSG | SDLPSSSSGG | ANGTAGGGGG | ARAAAAGRFP | AQVPSAHQPS |
| 70 | 80 | 90 | 100 | 110 | 120 |
| ASGGAAAAAA | APAAPAAPRS | RSLGGAVGSV | ASGARAAQSP | FSIPNSSSGP | YGSQDSVHSS |
| 130 | 140 | 150 | 160 | 170 | 180 |
| PEDGGGGRDR | PVGGSPGGPR | LVIGSLPAHL | SPHMFGGFKC | PVCSKFVSSD | EMDLHLVMCL |
| 190 | 200 | 210 | 220 | 230 | 240 |
| TKPRITYNED | VLSKDAGECA | ICLEELQQGD | TIARLPCLCI | YHKGCIDEWF | EVNRSCPEHP |
| SD |