Q8N6I1
Gene name |
EID2 |
Protein name |
EP300-interacting inhibitor of differentiation 2 |
Names |
EID-2, CREBBP/EP300 inhibitor 2, EID-1-like inhibitor of differentiation 2 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:163126 |
EC number |
|
Protein Class |
|
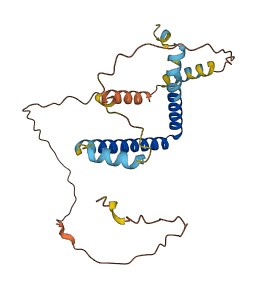
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q8N6I1
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q8N6I1-F1 | Predicted | AlphaFoldDB |
200 variants for Q8N6I1
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs1476359575 CA405819515 |
2 | S>P | No |
ClinGen gnomAD |
|
|
rs780962605 CA9433089 |
3 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs376406346 CA9433088 |
5 | P>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
VAR_038351 rs7252027 CA9433087 |
6 | A>T | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs766205291 CA9433086 |
7 | D>H | No |
ClinGen ExAC gnomAD |
|
|
rs1234918762 CA405819429 |
8 | S>R | No |
ClinGen gnomAD |
|
|
rs368921747 CA9433084 |
9 | S>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA405819414 rs1482362233 |
9 | S>T | No |
ClinGen TOPMed |
|
|
CA308246166 rs878874622 |
11 | P>L | No |
ClinGen Ensembl |
|
|
CA405819359 rs761190422 |
13 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs527811892 CA9433083 |
13 | T>P | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9433082 rs761190422 |
13 | T>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405819340 rs1180304424 |
15 | A>T | No |
ClinGen TOPMed |
|
|
rs776112037 CA9433081 |
15 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA9433079 rs759958970 |
16 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1319076287 CA405819299 |
18 | G>S | No |
ClinGen gnomAD |
|
|
rs774702560 CA9433078 |
19 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405818284 rs1421197211 |
24 | Q>* | No |
ClinGen gnomAD |
|
|
rs749543194 CA9433076 |
26 | E>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9433075 rs777815889 |
27 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs1485225755 CA405818161 |
27 | V>I | No |
ClinGen gnomAD |
|
|
rs983336566 CA308243099 |
28 | G>D | No |
ClinGen TOPMed gnomAD |
|
|
rs769953956 CA405818127 |
29 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9433074 rs769953956 |
29 | R>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9433072 rs781339867 |
30 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA9433071 rs200885423 |
32 | R>Q | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs751479329 CA9433070 |
33 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9433069 rs780008791 |
34 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA405817926 rs1295459634 |
35 | A>V | No |
ClinGen gnomAD |
|
|
CA9433067 rs750122220 |
37 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA405817846 rs1447778803 |
38 | Q>E | No |
ClinGen gnomAD |
|
|
rs1600774540 CA405817824 |
38 | Q>H | No |
ClinGen Ensembl |
|
|
CA405817789 rs1293375471 |
40 | E>K | No |
ClinGen gnomAD |
|
|
rs565043525 CA308243087 |
40 | E>V | No |
ClinGen 1000Genomes |
|
|
CA9433066 rs764767748 |
41 | E>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405817740 rs1355931023 |
42 | A>T | No |
ClinGen gnomAD |
|
|
rs77663137 CA405817686 |
43 | G>A | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9433064 rs77663137 |
43 | G>E | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs761442952 CA405817697 CA9433065 |
43 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs1194944950 CA405817578 |
46 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
rs760044833 CA9433062 |
47 | M>L | No |
ClinGen ExAC gnomAD |
|
|
rs1252229428 CA405817518 |
48 | A>E | No |
ClinGen gnomAD |
|
|
CA9433061 rs766758554 |
49 | A>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405817514 rs1481466555 |
49 | A>T | No |
ClinGen gnomAD |
|
|
CA9433060 rs766758554 |
49 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA308243071 rs544272604 |
50 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
CA405817502 rs544272604 |
50 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
CA9433059 rs763193902 |
50 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA9433058 rs773534199 |
51 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1345335547 CA405817467 |
52 | G>A | No |
ClinGen TOPMed |
|
|
rs1345335547 CA405817468 |
52 | G>E | No |
ClinGen TOPMed |
|
| TCGA novel | 53 | G>C | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs76427625 CA9433057 |
54 | P>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9433056 rs76427625 |
54 | P>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1485790378 CA405817434 |
55 | V>L | No |
ClinGen gnomAD |
|
|
rs1372364956 CA405817402 |
57 | A>T | No |
ClinGen gnomAD |
|
| TCGA novel | 57 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA405817382 rs572188094 |
58 | A>P | No |
ClinGen 1000Genomes gnomAD |
|
|
rs572188094 CA308243065 |
58 | A>T | No |
ClinGen 1000Genomes gnomAD |
|
|
VAR_050964 CA9433055 rs3746086 |
60 | E>A | No |
ClinGen UniProt 1000Genomes ExAC TOPMed dbSNP gnomAD |
|
| TCGA novel | 60 | E>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA308243057 rs927575978 |
61 | G>A | No |
ClinGen TOPMed |
|
|
rs1295711745 CA405817324 |
61 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
CA308243051 rs1011075161 |
63 | M>I | No |
ClinGen TOPMed gnomAD |
|
|
CA405817298 rs1600774450 |
63 | M>R | No |
ClinGen Ensembl |
|
|
CA405817290 rs1375930556 |
64 | A>V | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs768798913 CA9433054 |
65 | A>V | Variant assessed as Somatic; 0.0004941 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA9433053 rs746965679 |
66 | A>D | No |
ClinGen ExAC |
|
|
rs1376900565 CA405817284 |
66 | A>S | No |
ClinGen gnomAD |
|
|
CA405817271 rs1266503065 |
68 | A>P | No |
ClinGen TOPMed |
|
|
CA308243041 rs1055692898 |
70 | P>A | No |
ClinGen Ensembl |
|
|
rs1055692898 CA308243043 |
70 | P>T | No |
ClinGen Ensembl |
|
|
rs1476997343 CA405817250 |
71 | A>G | No |
ClinGen TOPMed |
|
|
rs1476997343 CA405817249 |
71 | A>V | No |
ClinGen TOPMed |
|
|
rs927017052 CA308243036 |
72 | A>V | No |
ClinGen TOPMed |
|
|
CA308243033 rs1045430519 |
75 | R>K | No |
ClinGen TOPMed |
|
|
CA405817228 rs1045430519 |
75 | R>M | No |
ClinGen TOPMed |
|
|
CA405817223 rs1315068909 |
76 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1033087356 CA308243029 |
77 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1033087356 CA405817219 |
77 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
CA9433049 rs745634901 |
77 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1251040653 CA405817203 |
80 | A>T | No |
ClinGen gnomAD |
|
|
rs778692509 CA9433048 |
82 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405817181 rs1255952065 |
83 | A>V | No |
ClinGen gnomAD |
|
|
rs753431194 CA405817176 |
84 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs756864090 CA9433047 |
84 | L>M | No |
ClinGen ExAC gnomAD |
|
|
CA405817172 rs1308243691 |
85 | A>S | No |
ClinGen gnomAD |
|
|
CA405817168 rs1171232481 |
86 | R>G | No |
ClinGen gnomAD |
|
|
CA9433045 rs763613260 |
87 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs1430757505 CA405817157 |
87 | A>V | No |
ClinGen gnomAD |
|
|
CA9433044 rs755577157 |
89 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs752098045 CA9433043 |
90 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs1400923081 CA405817141 |
90 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA308243002 rs983369272 |
91 | G>S | No |
ClinGen Ensembl |
|
|
CA405817104 rs1449702870 |
94 | S>R | No |
ClinGen TOPMed |
|
|
rs766846649 CA9433038 |
96 | A>G | No |
ClinGen ExAC |
|
|
CA9433036 rs763435288 |
97 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA9433034 rs765574260 |
100 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs994490614 CA405816972 |
103 | A>G | No |
ClinGen TOPMed gnomAD |
|
|
rs761958828 CA405816978 |
103 | A>P | No |
ClinGen ExAC gnomAD |
|
|
rs761958828 CA9433028 |
103 | A>S | No |
ClinGen ExAC gnomAD |
|
|
CA9433030 rs761958828 |
103 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs994490614 CA308242980 |
103 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA405816917 COSM293630 rs1390440550 |
106 | A>V | large_intestine Variant assessed as Somatic; impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated NCI-TCGA TOPMed |
|
CA405816910 COSM1304564 rs1600774303 |
107 | E>K | urinary_tract [Cosmic] | No |
ClinGen cosmic curated Ensembl |
|
rs1228191294 CA405816877 |
108 | V>F | No |
ClinGen gnomAD |
|
|
CA405816873 rs1600774297 |
108 | V>G | No |
ClinGen Ensembl |
|
|
rs1228191294 CA405816883 |
108 | V>I | No |
ClinGen gnomAD |
|
|
CA405816871 rs1327477029 |
109 | A>T | No |
ClinGen gnomAD |
|
|
CA9433027 rs555882270 |
109 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA405816859 rs1233579558 |
110 | R>C | No |
ClinGen gnomAD |
|
|
CA9433026 rs768889030 |
111 | L>F | No |
ClinGen ExAC gnomAD |
|
|
CA405816836 rs920467211 |
112 | L>V | No |
ClinGen TOPMed |
|
|
rs1331701171 CA405816817 |
114 | E>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs748066706 CA9433025 |
115 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405816786 rs1319747923 |
115 | P>L | No |
ClinGen gnomAD |
|
|
rs748066706 CA405816790 |
115 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs771897313 CA9433024 CA405816767 |
116 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs771897313 CA9433023 |
116 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA9433022 rs745750021 |
117 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA405816749 rs745750021 |
117 | D>V | No |
ClinGen ExAC gnomAD |
|
|
CA9433019 rs200060326 |
120 | G>A | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA405816631 rs200060326 |
120 | G>D | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA9433020 rs757024402 |
120 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1430333932 CA405816616 |
121 | P>L | No |
ClinGen gnomAD |
|
|
CA405816580 rs1208698093 |
123 | G>V | No |
ClinGen gnomAD |
|
|
CA405816564 rs1216134569 |
124 | R>K | No |
ClinGen TOPMed |
|
|
CA405816542 rs1600774253 |
125 | P>L | No |
ClinGen Ensembl |
|
|
rs1275196657 CA405816545 |
125 | P>S | No |
ClinGen TOPMed |
|
|
rs1463919609 CA405816534 |
126 | R>G | No |
ClinGen gnomAD |
|
|
rs1275508604 CA405816525 |
126 | R>K | No |
ClinGen gnomAD |
|
|
CA9433017 rs755666985 |
128 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs752192167 CA9433016 COSM3712924 |
128 | R>T | upper_aerodigestive_tract [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
CA9433015 rs766980168 |
129 | H>Y | No |
ClinGen ExAC gnomAD |
|
|
rs1186365761 CA405816472 |
130 | G>R | No |
ClinGen TOPMed |
|
| TCGA novel | 132 | G>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1568460280 CA405816400 |
132 | G>A | No |
ClinGen Ensembl |
|
|
rs758836307 CA405816382 |
133 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs758836307 CA9433014 |
133 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA308242949 rs1011146910 |
134 | L>V | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 136 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1600774214 CA405816291 |
137 | L>V | No |
ClinGen Ensembl |
|
|
CA9433012 rs765542168 |
138 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA405816270 rs765542168 |
138 | P>T | No |
ClinGen ExAC gnomAD |
|
|
rs1161640598 CA405816236 |
139 | Y>C | No |
ClinGen TOPMed gnomAD |
|
|
CA9433011 rs780114375 |
139 | Y>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405816248 rs780114375 |
139 | Y>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405816232 rs1161640598 |
139 | Y>S | No |
ClinGen TOPMed gnomAD |
|
|
rs754154805 CA9433010 |
140 | L>F | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs764391216 CA9433009 |
141 | R>G | No |
ClinGen ExAC gnomAD |
|
|
CA9433008 rs760902160 |
143 | R>C | No |
ClinGen ExAC gnomAD |
|
|
CA9433007 rs775714558 |
146 | L>F | No |
ClinGen ExAC |
|
|
CA9433006 rs772132619 |
146 | L>R | No |
ClinGen ExAC gnomAD |
|
|
rs1357075984 CA405815942 |
147 | S>G | No |
ClinGen gnomAD |
|
|
CA9433005 rs759414406 |
147 | S>R | No |
ClinGen ExAC gnomAD |
|
|
rs926061690 CA308242932 |
151 | I>S | No |
ClinGen TOPMed |
|
|
rs770668659 CA9433003 |
152 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9433001 rs567845080 |
158 | R>H | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA405815618 rs1225538818 |
159 | H>R | No |
ClinGen gnomAD |
|
|
CA405815586 rs1275322575 |
161 | L>M | No |
ClinGen gnomAD |
|
|
CA9433000 rs769435100 |
165 | P>R | No |
ClinGen ExAC gnomAD |
|
|
rs754498911 CA308242923 |
166 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
CA405815477 rs1411925188 |
168 | P>S | No |
ClinGen gnomAD |
|
|
CA308242921 rs974860825 |
169 | G>S | No |
ClinGen TOPMed |
|
|
rs750928494 CA9432996 |
172 | Q>P | No |
ClinGen ExAC gnomAD |
|
|
CA405815401 rs1468059012 |
173 | E>Q | No |
ClinGen Ensembl |
|
|
CA405815372 rs1173628483 |
174 | L>P | No |
ClinGen gnomAD |
|
|
rs987273623 CA308242918 |
175 | E>G | No |
ClinGen TOPMed |
|
|
rs1477969675 CA405815313 |
178 | R>C | No |
ClinGen gnomAD |
|
|
rs1376404748 CA405815241 |
182 | V>L | No |
ClinGen Ensembl |
|
|
rs1568460232 CA405815185 |
184 | A>S | No |
ClinGen Ensembl |
|
|
rs754244593 CA9432993 |
188 | R>G | No |
ClinGen ExAC gnomAD |
|
|
rs764483293 CA9432992 |
191 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA405814985 rs1167215294 |
192 | F>S | No |
ClinGen TOPMed |
|
|
CA405814944 rs1202437012 |
194 | A>G | No |
ClinGen TOPMed gnomAD |
|
|
rs752911187 CA9432990 |
199 | N>D | No |
ClinGen ExAC gnomAD |
|
|
CA405814694 rs1218629495 |
200 | P>R | No |
ClinGen gnomAD |
|
|
CA9432989 rs566630361 |
201 | H>Y | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA9432988 rs759628844 |
202 | R>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA9432987 rs774203684 |
203 | V>L | No |
ClinGen ExAC gnomAD |
|
|
CA308242898 rs372306245 |
204 | D>N | No |
ClinGen ESP TOPMed gnomAD |
|
|
CA405814576 rs1348622870 |
205 | L>F | No |
ClinGen gnomAD |
|
|
rs772998243 CA9432984 |
207 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs1377397335 CA405814488 |
208 | L>V | No |
ClinGen TOPMed gnomAD |
|
|
CA308242885 rs898824120 |
209 | T>S | No |
ClinGen TOPMed |
|
|
rs1253727054 CA405814353 |
212 | I>V | No |
ClinGen TOPMed |
|
|
CA9432981 rs747822250 |
215 | T>A | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 216 | A>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1352275422 CA405814255 |
216 | A>S | No |
ClinGen TOPMed |
|
|
rs1160660599 CA405814236 |
217 | S>A | No |
ClinGen gnomAD |
|
|
rs1267134832 CA405814234 |
217 | S>C | No |
ClinGen TOPMed |
|
|
rs1473095060 CA405814206 |
218 | E>G | No |
ClinGen gnomAD |
|
|
rs1001964458 CA308242874 |
222 | P>S | No |
ClinGen TOPMed |
|
|
rs1179618859 CA405814069 |
223 | L>V | No |
ClinGen gnomAD |
|
|
CA9432978 rs746509987 |
224 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405813963 rs1270014203 |
226 | E>K | No |
ClinGen TOPMed |
|
|
CA9432977 rs779348803 |
227 | L>I | No |
ClinGen ExAC TOPMed |
|
|
rs1462453328 CA405813779 |
233 | I>F | No |
ClinGen gnomAD |
|
|
rs778300745 CA9432972 |
236 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA405813719 rs1180488637 |
236 | E>Q | No |
ClinGen TOPMed gnomAD |
No associated diseases with Q8N6I1
No regional properties for Q8N6I1
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for Q8N6I1 | |||
2 GO annotations of cellular component
| Name | Definition |
|---|---|
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| SMAD binding | Binding to a SMAD signaling protein. |
| transcription corepressor activity | A transcription coregulator activity that represses or decreases the transcription of specific gene sets via binding to a DNA-bound DNA-binding transcription factor, either on its own or as part of a complex. Corepressors often act by altering chromatin structure and modifications. For example, one class of transcription corepressors modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. |
9 GO annotations of biological process
| Name | Definition |
|---|---|
| cell differentiation | The process in which relatively unspecialized cells, e.g. embryonic or regenerative cells, acquire specialized structural and/or functional features that characterize the cells, tissues, or organs of the mature organism or some other relatively stable phase of the organism's life history. Differentiation includes the processes involved in commitment of a cell to a specific fate and its subsequent development to the mature state. |
| muscle organ development | The process whose specific outcome is the progression of the muscle over time, from its formation to the mature structure. The muscle is an organ consisting of a tissue made up of various elongated cells that are specialized to contract and thus to produce movement and mechanical work. |
| negative regulation of DNA-templated transcription | Any process that stops, prevents, or reduces the frequency, rate or extent of cellular DNA-templated transcription. |
| negative regulation of transcription by RNA polymerase II | Any process that stops, prevents, or reduces the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| negative regulation of transforming growth factor beta receptor signaling pathway | Any process that stops, prevents, or reduces the frequency, rate or extent of any TGF-beta receptor signaling pathway. |
| regulation of cell population proliferation | Any process that modulates the frequency, rate or extent of cell proliferation. |
| regulation of transforming growth factor beta receptor signaling pathway | Any process that modulates the frequency, rate or extent of activity of any TGF-beta receptor signaling pathway. |
| SMAD protein complex assembly | The aggregation, arrangement and bonding together of a set of components to form a protein complex that contains SMAD proteins. |
| transforming growth factor beta receptor complex assembly | The aggregation, arrangement and bonding together of a ligand-bound type II transforming growth factor beta (TGF-beta) receptor dimer with a type I TGF-beta receptor dimer, following ligand binding, to form a heterotetrameric TGF-beta receptor complex. |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSKLPADSSV | PQTGAANGDR | DVPQAEVGRG | RREPAPAQPE | EAGEGAMAAA | RGGPVPAARE |
| 70 | 80 | 90 | 100 | 110 | 120 |
| GRMAAARAAP | AAAARGAPVA | AAALARAAAA | GRESPAAAAA | REARMAEVAR | LLGEPVDEEG |
| 130 | 140 | 150 | 160 | 170 | 180 |
| PEGRPRSRHG | NGGLAALPYL | RLRHPLSVLG | INYQQFLRHY | LENYPIAPGR | IQELEERRRR |
| 190 | 200 | 210 | 220 | 230 | |
| FVEACRAREA | AFDAEYQRNP | HRVDLDILTF | TIALTASEVI | NPLIEELGCD | KFINRE |