Q84W27
Gene name |
SCPL43 (At2g12480, T27D6.5) |
Protein name |
Serine carboxypeptidase-like 43 |
Names |
|
Species |
Arabidopsis thaliana (Mouse-ear cress) |
KEGG Pathway |
ath:AT2G12480 |
EC number |
|
Protein Class |
|
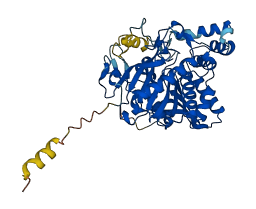
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q84W27
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q84W27-F1 | Predicted | AlphaFoldDB |
95 variants for Q84W27
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| ENSVATH00222934 | 4 | S>C | No | 1000Genomes | |
| tmp_2_5072201_C_A | 9 | M>I | No | 1000Genomes | |
| ENSVATH01747142 | 9 | M>V | No | 1000Genomes | |
| ENSVATH12914212 | 11 | I>V | No | 1000Genomes | |
| tmp_2_5072194_T_C | 12 | M>V | No | 1000Genomes | |
| ENSVATH05404997 | 13 | V>G | No | 1000Genomes | |
| ENSVATH05404998 | 13 | V>I | No | 1000Genomes | |
| tmp_2_5072184_A_G | 15 | V>A | No | 1000Genomes | |
| ENSVATH01747140 | 16 | T>S | No | 1000Genomes | |
| tmp_2_5072161_C_T | 23 | A>T | No | 1000Genomes | |
| tmp_2_5072156_T_A | 24 | E>D | No | 1000Genomes | |
| tmp_2_5072157_T_C | 24 | E>G | No | 1000Genomes | |
| ENSVATH14336337 | 26 | Y>F | No | 1000Genomes | |
| ENSVATH14336337 | 26 | Y>S | No | 1000Genomes | |
| ENSVATH05404994 | 30 | D>E | No | 1000Genomes | |
| ENSVATH05404995 | 30 | D>N | No | 1000Genomes | |
| ENSVATH00222932 | 38 | Q>E | No | 1000Genomes | |
| ENSVATH01747138 | 46 | F>Y | No | 1000Genomes | |
| ENSVATH05404993 | 53 | D>N | No | 1000Genomes | |
| ENSVATH00222930 | 55 | E>A | No | 1000Genomes | |
| ENSVATH05404990 | 66 | E>K | No | 1000Genomes | |
| ENSVATH05404989 | 67 | A>S | No | 1000Genomes | |
| ENSVATH00222929 | 70 | E>Q | No | 1000Genomes | |
| ENSVATH01747132 | 93 | A>S | No | 1000Genomes | |
| ENSVATH12914165 | 93 | A>V | No | 1000Genomes | |
| ENSVATH05404984 | 103 | T>M | No | 1000Genomes | |
| ENSVATH01747126 | 126 | E>D | No | 1000Genomes | |
| ENSVATH01747125 | 127 | S>L | No | 1000Genomes | |
| ENSVATH05404978 | 140 | S>A | No | 1000Genomes | |
| ENSVATH01747124 | 148 | S>T | No | 1000Genomes | |
| tmp_2_5071528_T_C | 151 | N>S | No | 1000Genomes | |
| ENSVATH12914092 | 153 | M>I | No | 1000Genomes | |
| ENSVATH12914090 | 166 | E>G | No | 1000Genomes | |
| tmp_2_5071484_C_T | 166 | E>K | No | 1000Genomes | |
| ENSVATH12914089 | 169 | S>A | No | 1000Genomes | |
| tmp_2_5071469_C_T | 171 | D>N | No | 1000Genomes | |
| ENSVATH00222925 | 173 | F>C | No | 1000Genomes | |
| tmp_2_5071301_G_C | 182 | H>D | No | 1000Genomes | |
| ENSVATH12914088 | 184 | I>L | No | 1000Genomes | |
| tmp_2_5071291_G_A | 185 | P>L | No | 1000Genomes | |
| ENSVATH05404962 | 188 | A>V | No | 1000Genomes | |
| ENSVATH01747117 | 189 | D>N | No | 1000Genomes | |
| ENSVATH12914087 | 196 | S>P | No | 1000Genomes | |
| ENSVATH01747116 | 197 | R>C | No | 1000Genomes | |
| ENSVATH05404960 | 199 | S>R | No | 1000Genomes | |
| tmp_2_5070877_G_A | 213 | P>S | No | 1000Genomes | |
| ENSVATH05404949 | 218 | D>H | No | 1000Genomes | |
| ENSVATH14336113 | 219 | R>K | No | 1000Genomes | |
| ENSVATH12914002 | 230 | S>* | No | 1000Genomes | |
| ENSVATH01747106 | 241 | T>R | No | 1000Genomes | |
| tmp_2_5070790_T_C | 242 | I>V | No | 1000Genomes | |
| tmp_2_5070762_G_A | 251 | P>L | No | 1000Genomes | |
| ENSVATH05404947 | 252 | K>E | No | 1000Genomes | |
| ENSVATH00222924 | 262 | I>V | No | 1000Genomes | |
| ENSVATH05404945 | 274 | S>N | No | 1000Genomes | |
| tmp_2_5070685_T_C | 277 | I>V | No | 1000Genomes | |
| tmp_2_5070654_A_G | 287 | V>A | No | 1000Genomes | |
| ENSVATH01747105 | 289 | Q>E | No | 1000Genomes | |
| tmp_2_5070475_C_T | 298 | A>T | No | 1000Genomes | |
| ENSVATH05404942 | 298 | A>V | No | 1000Genomes | |
| ENSVATH05404941 | 304 | T>N | No | 1000Genomes | |
| ENSVATH05404941 | 304 | T>S | No | 1000Genomes | |
| ENSVATH00222922 | 305 | R>C | No | 1000Genomes | |
| ENSVATH00222921 | 305 | R>H | No | 1000Genomes | |
| ENSVATH00222920 | 313 | C>S | No | 1000Genomes | |
| ENSVATH05404937 | 316 | R>Q | No | 1000Genomes | |
| ENSVATH00222918 | 316 | R>W | No | 1000Genomes | |
| tmp_2_5070317_T_C | 320 | S>G | No | 1000Genomes | |
| tmp_2_5070316_C_A | 320 | S>I | No | 1000Genomes | |
| ENSVATH01747102 | 322 | I>L | No | 1000Genomes | |
| ENSVATH12914000 | 326 | I>N | No | 1000Genomes | |
| ENSVATH05404936 | 339 | Q>* | No | 1000Genomes | |
| tmp_2_5070253_G_A | 341 | P>L | No | 1000Genomes | |
| ENSVATH05404931 | 351 | S>F | No | 1000Genomes | |
| tmp_2_5070148_T_C | 353 | I>V | No | 1000Genomes | |
| ENSVATH05404930 | 363 | R>Q | No | 1000Genomes | |
| ENSVATH14336112 | 368 | D>H | No | 1000Genomes | |
| ENSVATH01747100 | 371 | F>Y | No | 1000Genomes | |
| ENSVATH00222916 | 375 | I>V | No | 1000Genomes | |
| ENSVATH05404929 | 379 | A>G | No | 1000Genomes | |
| tmp_2_5069965_C_A | 387 | G>C | No | 1000Genomes | |
| tmp_2_5069952_G_A | 391 | T>I | No | 1000Genomes | |
| ENSVATH00222912 | 396 | L>Q | No | 1000Genomes | |
| ENSVATH05404927 | 413 | E>K | No | 1000Genomes | |
| tmp_2_5069886_T_A | 413 | E>V | No | 1000Genomes | |
| tmp_2_5069884_GC_AC,G | 414 | P>S | No | 1000Genomes | |
| tmp_2_5069849_C_A | 425 | M>I | No | 1000Genomes | |
| ENSVATH00222911 | 425 | M>L | No | 1000Genomes | |
| ENSVATH00222911 | 425 | M>V | No | 1000Genomes | |
| tmp_2_5069834_C_A | 430 | L>F | No | 1000Genomes | |
| ENSVATH12913996 | 433 | K>R | No | 1000Genomes | |
| ENSVATH05404925 | 434 | P>L | No | 1000Genomes | |
| ENSVATH12913995 | 436 | L>* | No | 1000Genomes | |
| tmp_2_5069813_C_A | 437 | K>N | No | 1000Genomes | |
| tmp_2_5069800_C_T | 442 | D>N | No | 1000Genomes |
No associated diseases with Q84W27
1 regional properties for Q84W27
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| active_site | Serine carboxypeptidase, serine active site | 174 - 181 | IPR018202 |
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| extracellular region | The space external to the outermost structure of a cell. For cells without external protective or external encapsulating structures this refers to space outside of the plasma membrane. This term covers the host cell environment outside an intracellular parasite. |
1 GO annotations of molecular function
| Name | Definition |
|---|---|
| serine-type carboxypeptidase activity | Catalysis of the hydrolysis of a single C-terminal amino acid residue from the C-terminus of a polypeptide chain by a catalytic mechanism that involves a catalytic triad consisting of a serine nucleophile that is activated by a proton relay involving an acidic residue (e.g. aspartate or glutamate) and a basic residue (usually histidine). |
1 GO annotations of biological process
| Name | Definition |
|---|---|
| proteolysis | The hydrolysis of proteins into smaller polypeptides and/or amino acids by cleavage of their peptide bonds. |
1 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q9MAR8 | SCPL44 | Serine carboxypeptidase-like 44 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MVSSRAVVMA | IMVLVTVQWL | VFAEGYPEED | LVARLPGQPN | VGFRQFAGYV | DVDSENGRSL |
| 70 | 80 | 90 | 100 | 110 | 120 |
| FYYYVEAVKE | PDTKPLTLWL | NGGPGCSSVG | GGAFTELGPF | YPTGDGRGLR | LNSMSWNKAS |
| 130 | 140 | 150 | 160 | 170 | 180 |
| NLLFVESPAG | VGWSYSNRSS | DYNTGDKSTV | NDMLVFLLRW | FNKFPELKSR | DLFLTGESYA |
| 190 | 200 | 210 | 220 | 230 | 240 |
| GHYIPQLADV | ILSYNSRSSG | FKFNVKGIAI | GNPLLKLDRD | FAAAYEYFWS | HGMISDEVRL |
| 250 | 260 | 270 | 280 | 290 | 300 |
| TIMNQCDFAN | PKNMSNACIY | AIVESSVLTE | YINSYHILLD | VCYPSIVQQE | LRLKKMNALH |
| 310 | 320 | 330 | 340 | 350 | 360 |
| ANRTRLPYEW | TMCSNRLNYS | GIDGYIDMLP | SLKRIIQNQT | PVWIFSGDQD | SVIPLQSSRT |
| 370 | 380 | 390 | 400 | 410 | 420 |
| LVRELAEDLN | FKTTIPYGAW | FHKEQVGGWV | TEYGNLLTFA | TVRGAAHMVP | YAEPSRALHM |
| 430 | 440 | ||||
| FSSFMNGRRL | PNKPDLKSST | DD |