Q6P6C2
Gene name |
ALKBH5 (ABH5, OFOXD1) |
Protein name |
RNA demethylase ALKBH5 |
Names |
Alkylated DNA repair protein alkB homolog 5, Alpha-ketoglutarate-dependent dioxygenase alkB homolog 5 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:54890 |
EC number |
1.14.11.53: With 2-oxoglutarate as one donor, and incorporation of one atom each of oxygen into both donors |
Protein Class |
|
Descriptions
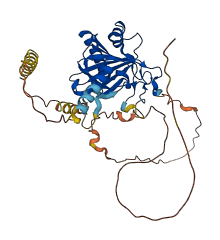
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
12 structures for Q6P6C2
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 4NJ4 | X-ray | 202 A | A/B | 66-292 | PDB |
| 4NRM | X-ray | 217 A | A | 66-292 | PDB |
| 4NRO | X-ray | 230 A | A | 66-292 | PDB |
| 4NRP | X-ray | 180 A | A | 66-292 | PDB |
| 4NRQ | X-ray | 250 A | A | 66-292 | PDB |
| 4O61 | X-ray | 190 A | A/B | 74-294 | PDB |
| 4O7X | X-ray | 178 A | A | 66-292 | PDB |
| 4OCT | X-ray | 228 A | A/B | 74-294 | PDB |
| 7V4G | X-ray | 210 A | A/B/C | 74-292 | PDB |
| 7WKV | X-ray | 210 A | A/C/E | 74-292 | PDB |
| 7WL0 | X-ray | 250 A | A/C/E/G/I | 74-292 | PDB |
| AF-Q6P6C2-F1 | Predicted | AlphaFoldDB |
247 variants for Q6P6C2
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs1416725227 CA398646197 |
3 | A>S | No |
ClinGen gnomAD |
|
|
CA398646195 rs1416725227 |
3 | A>T | No |
ClinGen gnomAD |
|
| TCGA novel | 4 | A>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA288425324 rs997201124 |
4 | A>S | No |
ClinGen TOPMed |
|
|
CA398646208 rs1171937599 |
5 | S>G | No |
ClinGen TOPMed gnomAD |
|
|
CA398646216 rs1460271736 |
6 | G>D | No |
ClinGen gnomAD |
|
|
rs913465156 CA398646215 |
6 | G>R | No |
ClinGen gnomAD |
|
|
rs913465156 CA288425327 |
6 | G>S | No |
ClinGen gnomAD |
|
|
rs1323300455 CA398646220 |
7 | Y>H | No |
ClinGen gnomAD |
|
|
CA398646230 rs1438823509 |
8 | T>K | No |
ClinGen gnomAD |
|
|
CA398646232 rs1438823509 |
8 | T>M | No |
ClinGen gnomAD |
|
|
CA398646289 rs1455988890 |
17 | M>L | No |
ClinGen TOPMed |
|
|
rs1415461631 CA398646293 |
17 | M>T | No |
ClinGen gnomAD |
|
|
CA398646308 rs1457334990 |
19 | S>F | No |
ClinGen gnomAD |
|
|
rs1451855806 CA398646334 |
23 | Y>C | No |
ClinGen gnomAD |
|
|
rs1288843691 CA398646332 |
23 | Y>H | No |
ClinGen gnomAD |
|
|
CA288425342 rs1016845020 |
24 | K>Q | No |
ClinGen TOPMed |
|
|
CA288425345 rs1001599161 |
25 | A>T | No |
ClinGen Ensembl |
|
|
rs1223249251 CA398646348 |
25 | A>V | No |
ClinGen gnomAD |
|
|
CA398646350 rs1477173466 |
26 | G>S | No |
ClinGen gnomAD |
|
|
CA398646359 rs1252666463 |
27 | S>N | No |
ClinGen TOPMed |
|
|
CA398646366 rs1426486555 |
28 | R>Q | No |
ClinGen gnomAD |
|
| TCGA novel | 29 | E>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA288425347 rs963583867 |
29 | E>K | No |
ClinGen TOPMed |
|
|
CA398646378 rs1474501623 |
30 | A>T | No |
ClinGen gnomAD |
|
|
CA398646381 rs1163070686 |
30 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1391844043 CA398646382 |
31 | A>T | No |
ClinGen gnomAD |
|
|
rs1316403804 CA398646390 |
32 | A>S | No |
ClinGen gnomAD |
|
|
CA398646412 rs1242469413 |
36 | A>T | No |
ClinGen gnomAD |
|
|
CA398646417 rs1283407160 |
36 | A>V | No |
ClinGen gnomAD |
|
|
rs1356715248 CA398646418 |
37 | A>P | No |
ClinGen gnomAD |
|
|
rs1356715248 CA398646420 |
37 | A>T | No |
ClinGen gnomAD |
|
|
CA288425368 rs887898438 |
38 | V>A | No |
ClinGen TOPMed |
|
|
CA398646427 rs887898438 |
38 | V>E | No |
ClinGen TOPMed |
|
| rs779550198 | 38 | V>missing | Variant assessed as Somatic; 7.56e-05 impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA398646432 rs1283527374 |
39 | A>D | No |
ClinGen gnomAD |
|
|
rs1487752522 CA398646435 |
40 | A>T | No |
ClinGen gnomAD |
|
|
rs1216768513 CA398646443 |
41 | A>T | No |
ClinGen gnomAD |
|
|
rs1170596628 CA398646447 |
42 | A>T | No |
ClinGen TOPMed |
|
|
rs1187380646 CA398646455 |
43 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
CA398646453 rs1187380646 |
43 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
CA398646461 rs1369410099 |
44 | A>S | No |
ClinGen TOPMed gnomAD |
|
|
rs1014963993 CA288425397 |
44 | A>V | No |
ClinGen TOPMed |
|
|
rs1474016096 CA398646464 |
45 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs758673141 CA8426044 |
45 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA288425405 rs1016527303 |
46 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1244526144 CA398646471 |
46 | A>V | No |
ClinGen gnomAD |
|
|
CA8426045 rs780246148 |
47 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs768757008 CA8426047 |
48 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs1340993145 CA398646486 |
49 | E>K | No |
ClinGen gnomAD |
|
|
rs1352582996 CA398646497 |
50 | P>L | No |
ClinGen gnomAD |
|
|
CA398646494 rs1306782653 |
50 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA398646492 rs1306782653 |
50 | P>T | No |
ClinGen TOPMed gnomAD |
|
|
CA398646501 rs1240355443 |
51 | Y>C | No |
ClinGen gnomAD |
|
|
CA398646508 rs1342171854 |
52 | P>S | No |
ClinGen gnomAD |
|
|
CA8426049 rs748081999 |
53 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA398646512 rs1199380758 |
53 | V>M | No |
ClinGen gnomAD |
|
|
rs769720160 CA288425422 |
54 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8426050 rs769720160 |
54 | S>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1444613519 CA398646519 |
54 | S>P | No |
ClinGen gnomAD |
|
|
rs1413768781 CA398646522 |
55 | G>R | No |
ClinGen TOPMed |
|
|
CA398646532 rs1440574837 |
56 | A>V | No |
ClinGen gnomAD |
|
|
CA398646538 rs1393355592 |
57 | K>M | No |
ClinGen TOPMed gnomAD |
|
|
CA398646536 rs1393355592 |
57 | K>T | No |
ClinGen TOPMed gnomAD |
|
|
CA398646541 rs1173224616 |
58 | R>C | No |
ClinGen gnomAD |
|
|
rs1032708221 CA288425435 |
59 | K>E | No |
ClinGen Ensembl |
|
|
rs1416073756 CA398646559 |
60 | Y>C | No |
ClinGen gnomAD |
|
|
CA398646592 rs1311080940 |
65 | D>N | No |
ClinGen gnomAD |
|
|
rs767011110 CA398646601 |
66 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs767011110 CA8426056 |
66 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs61999283 CA288425446 |
67 | E>* | No |
ClinGen Ensembl |
|
|
CA398646610 rs1347788665 |
67 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
rs61999283 CA288425445 |
67 | E>Q | No |
ClinGen Ensembl |
|
|
rs1197251011 CA398646613 |
68 | R>C | No |
ClinGen gnomAD |
|
|
rs1422958161 CA398646614 |
68 | R>P | No |
ClinGen TOPMed gnomAD |
|
|
rs982195215 CA288425451 |
70 | D>N | No |
ClinGen TOPMed |
|
|
rs779516667 CA8426058 |
71 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
CA398646639 rs1180895350 |
72 | E>K | No |
ClinGen gnomAD |
|
|
CA398646668 rs1478973888 |
75 | Q>H | No |
ClinGen gnomAD |
|
|
CA8426060 rs750849685 |
75 | Q>L | No |
ClinGen ExAC gnomAD |
|
|
rs747203510 CA398646682 |
77 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs576498560 CA8426065 |
78 | K>E | No |
ClinGen 1000Genomes ExAC TOPMed |
|
|
CA398646690 rs1388179496 |
79 | E>K | No |
ClinGen gnomAD |
|
|
rs1301385983 CA398646703 |
80 | E>A | No |
ClinGen gnomAD |
|
|
CA8426068 rs769914553 |
81 | E>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8426067 rs748052555 |
81 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs199911950 CA8426069 |
84 | K>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1597834785 CA398646736 |
85 | V>G | No |
ClinGen Ensembl |
|
|
rs868728988 CA288425475 |
88 | G>D | No |
ClinGen Ensembl |
|
|
CA8426072 rs201845081 |
93 | R>H | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1269559774 CA398646795 |
94 | L>F | No |
ClinGen gnomAD |
|
|
rs376859691 CA8426074 |
96 | S>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs374187597 CA8426077 |
101 | A>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8426079 rs763328324 |
102 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs561311814 CA8426080 |
105 | A>S | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs751736728 CA8426081 |
106 | R>L | No |
ClinGen ExAC gnomAD |
|
|
CA398573197 rs1220965113 |
112 | S>F | No |
ClinGen gnomAD |
|
| TCGA novel | 112 | S>P | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs756235862 CA8426086 |
113 | R>C | No |
ClinGen ExAC gnomAD |
|
|
CA398573207 rs1287162990 |
113 | R>L | No |
ClinGen TOPMed |
|
|
CA8426085 rs756235862 |
113 | R>S | No |
ClinGen ExAC gnomAD |
|
|
rs1244741057 CA398573212 |
114 | A>S | No |
ClinGen TOPMed |
|
|
CA398573317 rs745633033 |
121 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA8426090 rs745633033 |
121 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA8426091 rs201004949 |
122 | H>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs760226514 CA8426093 |
126 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA398573509 rs1567672973 |
131 | N>S | No |
ClinGen Ensembl |
|
| TCGA novel | 139 | Y>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs767824688 CA8426100 |
140 | T>A | No |
ClinGen ExAC gnomAD |
|
|
rs371248302 CA288407703 |
143 | A>T | No |
ClinGen ESP TOPMed |
|
|
CA288407704 rs1023750539 |
146 | Q>R | No |
ClinGen TOPMed |
|
|
rs1221113890 CA398574138 |
154 | R>L | No |
ClinGen TOPMed |
|
|
rs1293577400 CA398574228 |
158 | P>L | No |
ClinGen TOPMed |
|
|
rs778708217 CA8426106 |
158 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA288407731 rs1020349428 |
160 | D>E | No |
ClinGen Ensembl |
|
|
rs1235723796 CA398574457 |
166 | E>G | No |
ClinGen gnomAD |
|
|
rs971071501 CA288407735 |
168 | V>L | No |
ClinGen Ensembl |
|
|
rs1597834905 CA398574545 |
169 | H>D | No |
ClinGen Ensembl |
|
|
rs372474496 CA8426109 |
170 | Q>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1437464000 CA398574592 |
170 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA398574627 rs1597834915 |
172 | V>G | No |
ClinGen Ensembl |
|
|
COSM120089 rs1282708778 CA398574672 |
174 | Q>R | ovary [Cosmic] | No |
ClinGen cosmic curated TOPMed |
|
CA398574746 rs1359133006 |
177 | V>G | No |
ClinGen gnomAD |
|
|
rs1466967345 CA398574786 |
178 | E>D | No |
ClinGen gnomAD |
|
|
CA288407736 rs956896770 |
179 | H>R | No |
ClinGen TOPMed |
|
|
CA398574830 rs1375068660 |
180 | R>H | No |
ClinGen TOPMed gnomAD |
|
|
rs759998156 CA398574982 |
186 | F>L | No |
ClinGen ExAC gnomAD |
|
|
CA398575004 rs1346120529 |
188 | N>D | No |
ClinGen TOPMed |
|
|
CA398575124 rs1311566426 |
192 | I>M | No |
ClinGen gnomAD |
|
|
CA8426118 rs775888304 |
192 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA398575367 rs1178002817 |
201 | I>T | No |
ClinGen gnomAD |
|
|
rs940741503 CA288407812 |
208 | I>V | No |
ClinGen Ensembl |
|
|
CA8426125 rs373471903 |
212 | E>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA398575726 rs1332435764 |
216 | V>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
| TCGA novel | 219 | S>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 220 | F>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs372491826 CA288407865 |
225 | A>V | No |
ClinGen ESP TOPMed |
|
|
rs1315958769 COSM3691336 CA398575907 |
229 | G>D | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
|
CA8426134 rs772492243 |
235 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs776053537 CA8426135 |
236 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA8426136 rs761113226 |
237 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs745817011 CA288407901 |
239 | V>A | No |
ClinGen Ensembl |
|
|
rs889695478 CA288407916 |
244 | L>F | No |
ClinGen Ensembl |
|
|
rs376470149 CA8426138 |
245 | S>F | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1200942190 CA398576099 |
245 | S>P | No |
ClinGen gnomAD |
|
|
CA8426137 rs376470149 |
245 | S>Y | No |
ClinGen ESP ExAC gnomAD |
|
|
rs371096564 CA8426141 |
248 | V>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA398576137 rs1403829834 |
249 | R>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA398576139 rs1323069792 |
249 | R>H | No |
ClinGen gnomAD |
|
|
CA398576170 rs1350685998 |
252 | S>N | No |
ClinGen gnomAD |
|
|
CA398576206 rs1296382448 |
255 | V>L | No |
ClinGen gnomAD |
|
| TCGA novel | 256 | L>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA8426172 rs755667731 |
263 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8426173 rs777475340 |
268 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1375683882 CA398579016 |
282 | L>F | No |
ClinGen gnomAD |
|
|
rs1369512071 CA398581607 |
286 | R>K | No |
ClinGen TOPMed |
|
|
rs1423920867 CA398581671 |
288 | D>G | No |
ClinGen TOPMed gnomAD |
|
|
CA398581887 rs1451164195 |
296 | S>T | No |
ClinGen gnomAD |
|
|
CA398581915 rs1200223677 |
297 | L>M | No |
ClinGen gnomAD |
|
|
rs769558802 CA8426195 |
301 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs752123279 CA8426197 |
302 | L>S | No |
ClinGen ExAC gnomAD |
|
|
rs755598519 CA8426198 |
303 | P>A | No |
ClinGen ExAC gnomAD |
|
|
rs781720809 CA8426199 |
304 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs377225153 CA288417012 |
306 | Y>C | No |
ClinGen ESP gnomAD |
|
|
rs1303206051 CA398582187 |
309 | D>E | No |
ClinGen gnomAD |
|
| TCGA novel | 309 | D>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1347962377 CA398582195 |
310 | R>C | No |
ClinGen gnomAD |
|
|
rs748504025 CA8426200 |
310 | R>H | No |
ClinGen ExAC gnomAD |
|
|
rs1277969333 CA398582222 |
312 | S>L | No |
ClinGen gnomAD |
|
|
CA398582238 rs1308387793 |
314 | N>D | No |
ClinGen gnomAD |
|
|
rs756479743 CA8426201 |
314 | N>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA398582257 rs777881500 |
315 | N>I | No |
ClinGen ExAC gnomAD |
|
|
CA8426202 rs777881500 |
315 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA398582253 rs1355580421 |
315 | N>Y | No |
ClinGen TOPMed |
|
|
rs1400438509 CA398582274 |
316 | R>K | No |
ClinGen Ensembl |
|
|
CA8426203 rs749475182 |
317 | D>A | No |
ClinGen ExAC gnomAD |
|
|
CA398582305 rs1012911005 |
318 | P>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1012911005 CA288417023 |
318 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs771007455 CA8426204 |
318 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1191347876 CA398582316 |
319 | A>G | No |
ClinGen gnomAD |
|
|
CA398582336 rs1247088205 |
321 | K>Q | No |
ClinGen TOPMed |
|
|
CA8426207 rs772033885 |
323 | K>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs772033885 CA398582371 |
323 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA398582375 rs772033885 |
323 | K>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs760405725 CA8426209 |
324 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs775474036 CA8426208 |
324 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs1163702519 CA398582418 COSM1182544 |
327 | R>C | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA gnomAD |
| TCGA novel | 327 | R>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 329 | A>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs371868380 CA8426212 |
330 | D>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8426213 rs764967708 |
331 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1597843364 CA398582492 |
332 | D>N | No |
ClinGen Ensembl |
|
|
rs757592449 CA8426243 |
337 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA398582990 rs1174648070 |
338 | R>Q | No |
ClinGen gnomAD |
|
|
rs1164248193 CA398582989 |
338 | R>W | No |
ClinGen TOPMed |
|
|
rs1555551372 CA8426244 |
344 | K>R | No |
ClinGen Ensembl |
|
| TCGA novel | 346 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA8426246 rs779127018 |
348 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs919866254 CA288417471 |
349 | R>C | No |
ClinGen Ensembl |
|
|
rs1339081895 CA398583069 |
349 | R>H | No |
ClinGen gnomAD |
|
|
CA8426248 rs758409355 |
350 | S>L | No |
ClinGen ExAC gnomAD |
|
|
CA398583123 rs1375550598 |
353 | L>P | No |
ClinGen gnomAD |
|
|
CA8426253 rs748007768 |
356 | H>Y | No |
ClinGen ExAC gnomAD |
|
|
CA8426255 rs773031505 |
357 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8426254 rs767112785 COSM1520496 |
357 | R>W | lung [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs770364449 CA8426257 |
358 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs762603610 COSM976234 CA8426256 |
358 | R>W | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
CA8426258 rs773971516 |
359 | R>G | No |
ClinGen ExAC gnomAD |
|
|
CA398583246 rs758966619 |
361 | S>G | No |
ClinGen ExAC gnomAD |
|
|
rs758966619 CA8426259 |
361 | S>R | No |
ClinGen ExAC gnomAD |
|
|
CA8426260 rs764631695 |
362 | F>Y | No |
ClinGen ExAC gnomAD |
|
|
rs1409620968 CA398583291 |
363 | S>I | No |
ClinGen gnomAD |
|
|
rs754292160 CA8426261 |
363 | S>R | No |
ClinGen ExAC gnomAD |
|
|
CA398583303 rs1212473184 |
365 | E>A | No |
ClinGen TOPMed |
|
|
rs762193110 CA8426262 |
365 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs912403946 CA288417528 |
366 | N>K | No |
ClinGen Ensembl |
|
|
rs765516157 CA8426263 |
368 | W>C | No |
ClinGen ExAC gnomAD |
|
|
CA8426264 rs750655723 |
369 | R>C | Variant assessed as Somatic; 4.638e-05 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA398583335 rs1567678122 |
369 | R>H | No |
ClinGen Ensembl |
|
|
rs1555551378 CA398583347 |
371 | S>L | No |
ClinGen Ensembl |
|
|
CA398583350 rs1226170428 |
372 | Y>H | No |
ClinGen TOPMed |
|
|
rs751699434 CA8426267 COSM1381310 |
373 | E>K | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs1193352172 CA398583375 |
375 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
rs781303076 CA8426269 |
376 | E>G | No |
ClinGen ExAC gnomAD |
|
|
rs754991517 CA8426268 |
376 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA8426271 rs552116660 |
378 | C>F | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA398583403 COSM1640608 rs1490657892 |
379 | S>C | stomach [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
CA398583402 rs1490657892 |
379 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
rs777657592 CA8426272 |
380 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs749027485 CA8426273 |
381 | A>E | No |
ClinGen ExAC gnomAD |
|
|
rs373570928 CA8426274 |
382 | A>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8426275 rs773848076 |
383 | G>S | No |
ClinGen ExAC gnomAD |
|
|
rs759105052 CA8426276 |
384 | S>I | No |
ClinGen ExAC gnomAD |
|
|
CA8426278 rs777123260 |
385 | P>R | No |
ClinGen ExAC gnomAD |
|
|
CA8426279 rs376329155 |
386 | A>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA398583441 rs1304956863 |
386 | A>V | No |
ClinGen gnomAD |
|
|
CA288417585 rs267604766 |
387 | R>* | No |
ClinGen TOPMed |
|
|
CA288417581 rs267604766 |
387 | R>G | No |
ClinGen TOPMed |
|
|
CA288417588 rs947071965 |
387 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA398583464 rs1270505304 |
390 | K>R | No |
ClinGen gnomAD |
|
|
CA398583478 rs1243236963 |
392 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA8426280 rs765718566 |
392 | R>W | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
| TCGA novel | 393 | R>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1192475606 CA398583482 |
393 | R>W | No |
ClinGen TOPMed |
|
|
CA398583487 rs1597844115 |
394 | H>D | No |
ClinGen Ensembl |
|
|
CA398583489 rs1597844120 |
394 | H>P | No |
ClinGen Ensembl |
|
| TCGA novel | 395 | H>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
No associated diseases with Q6P6C2
1 regional properties for Q6P6C2
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Alpha-ketoglutarate-dependent dioxygenase AlkB-like | 153 - 275 | IPR027450 |
Functions
| Description | ||
|---|---|---|
| EC Number | 1.14.11.53 | With 2-oxoglutarate as one donor, and incorporation of one atom each of oxygen into both donors |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| Golgi apparatus | A membrane-bound cytoplasmic organelle of the endomembrane system that further processes the core oligosaccharides (e.g. N-glycans) added to proteins in the endoplasmic reticulum and packages them into membrane-bound vesicles. The Golgi apparatus operates at the intersection of the secretory, lysosomal, and endocytic pathways. |
| nuclear speck | A discrete extra-nucleolar subnuclear domain, 20-50 in number, in which splicing factors are seen to be localized by immunofluorescence microscopy. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
5 GO annotations of molecular function
| Name | Definition |
|---|---|
| 2-oxoglutarate-dependent dioxygenase activity | Catalysis of the reaction: A + 2-oxoglutarate + O2 = B + succinate + CO2. This is an oxidation-reduction (redox) reaction in which hydrogen or electrons are transferred from 2-oxoglutarate and one other donor, and one atom of oxygen is incorporated into each donor. |
| metal ion binding | Binding to a metal ion. |
| mRNA N6-methyladenosine dioxygenase activity | Catalysis of the oxidative demethylation of N6-methyladenosine RNA, with concomitant decarboxylation of 2-oxoglutarate and releases oxidized methyl group on N6-methyladenosine as formaldehyde. |
| oxidative RNA demethylase activity | Catalysis of the removal of a methyl group from one or more nucleosides within a RNA molecule involving the oxidation (i.e. electron loss) of one or more atoms. |
| RNA binding | Binding to an RNA molecule or a portion thereof. |
7 GO annotations of biological process
| Name | Definition |
|---|---|
| cell differentiation | The process in which relatively unspecialized cells, e.g. embryonic or regenerative cells, acquire specialized structural and/or functional features that characterize the cells, tissues, or organs of the mature organism or some other relatively stable phase of the organism's life history. Differentiation includes the processes involved in commitment of a cell to a specific fate and its subsequent development to the mature state. |
| mRNA export from nucleus | The directed movement of mRNA from the nucleus to the cytoplasm. |
| mRNA processing | Any process involved in the conversion of a primary mRNA transcript into one or more mature mRNA(s) prior to translation into polypeptide. |
| oxidative single-stranded RNA demethylation | Removal of the methyl group from one or more nucleotides within a single-stranded RNA molecule involving the oxidation (i.e. electron loss) of one or more atoms. |
| regulation of mRNA stability | Any process that modulates the propensity of mRNA molecules to degradation. Includes processes that both stabilize and destabilize mRNAs. |
| response to hypoxia | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a stimulus indicating lowered oxygen tension. Hypoxia, defined as a decline in O2 levels below normoxic levels of 20.8 - 20.95%, results in metabolic adaptation at both the cellular and organismal level. |
| spermatogenesis | The developmental process by which male germ line stem cells self renew or give rise to successive cell types resulting in the development of a spermatozoa. |
3 homologous proteins in AiPD
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAAASGYTDL | REKLKSMTSR | DNYKAGSREA | AAAAAAAVAA | AAAAAAAAEP | YPVSGAKRKY |
| 70 | 80 | 90 | 100 | 110 | 120 |
| QEDSDPERSD | YEEQQLQKEE | EARKVKSGIR | QMRLFSQDEC | AKIEARIDEV | VSRAEKGLYN |
| 130 | 140 | 150 | 160 | 170 | 180 |
| EHTVDRAPLR | NKYFFGEGYT | YGAQLQKRGP | GQERLYPPGD | VDEIPEWVHQ | LVIQKLVEHR |
| 190 | 200 | 210 | 220 | 230 | 240 |
| VIPEGFVNSA | VINDYQPGGC | IVSHVDPIHI | FERPIVSVSF | FSDSALCFGC | KFQFKPIRVS |
| 250 | 260 | 270 | 280 | 290 | 300 |
| EPVLSLPVRR | GSVTVLSGYA | ADEITHCIRP | QDIKERRAVI | ILRKTRLDAP | RLETKSLSSS |
| 310 | 320 | 330 | 340 | 350 | 360 |
| VLPPSYASDR | LSGNNRDPAL | KPKRSHRKAD | PDAAHRPRIL | EMDKEENRRS | VLLPTHRRRG |
| 370 | 380 | 390 | |||
| SFSSENYWRK | SYESSEDCSE | AAGSPARKVK | MRRH |