Q2TAY7
Gene name |
SMU1 |
Protein name |
WD40 repeat-containing protein SMU1 |
Names |
Smu-1 suppressor of mec-8 and unc-52 protein homolog |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:55234 |
EC number |
|
Protein Class |
|
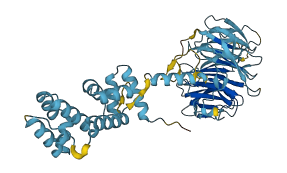
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
152 variants for Q2TAY7
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA373186857 rs1405651905 |
8 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
rs755514676 CA5023525 |
9 | D>H | No |
ClinGen ExAC gnomAD |
|
|
CA5023501 rs751139820 |
24 | H>L | No |
ClinGen ExAC gnomAD |
|
|
rs751139820 CA373186555 |
24 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs1340939120 CA373186557 |
24 | H>Y | No |
ClinGen TOPMed |
|
|
rs1241310721 CA373186550 |
25 | R>Q | No |
ClinGen gnomAD |
|
|
rs1564025861 CA373186542 |
26 | A>V | No |
ClinGen Ensembl |
|
|
rs774944719 CA5023498 |
28 | A>V | No |
ClinGen ExAC gnomAD |
|
|
COSM608725 rs764925690 CA5023497 |
36 | V>L | lung [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs1037873605 CA192432977 |
42 | D>E | No |
ClinGen TOPMed gnomAD |
|
|
rs1564025847 CA373186441 |
42 | D>G | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
|
CA5023495 rs537864362 |
42 | D>N | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs770903254 CA5023494 |
44 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA5023491 rs771989256 |
59 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs1245450943 CA373186293 |
63 | I>V | No |
ClinGen gnomAD |
|
|
rs755224688 CA5023488 |
69 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs1342221466 CA373186231 |
72 | T>A | No |
ClinGen TOPMed |
|
|
rs1446741656 CA373186229 |
72 | T>N | No |
ClinGen gnomAD |
|
|
rs749722919 CA5023487 |
78 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA192431293 rs45509097 |
94 | R>K | No |
ClinGen Ensembl |
|
|
CA192431279 rs866746026 |
102 | P>S | No |
ClinGen Ensembl |
|
|
CA373186012 rs1344483229 |
103 | M>V | No |
ClinGen gnomAD |
|
|
CA5023454 rs766003515 |
105 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs760531089 CA5023453 |
108 | Q>H | No |
ClinGen ExAC gnomAD |
|
|
rs1441222373 CA373185948 |
111 | P>L | No |
ClinGen TOPMed |
|
|
CA373185888 rs1409892258 |
120 | L>F | No |
ClinGen gnomAD |
|
|
rs767408086 CA5023451 |
120 | L>H | No |
ClinGen ExAC gnomAD |
|
|
rs1170021217 CA373185876 |
122 | A>S | No |
ClinGen gnomAD |
|
|
CA373185869 rs1243278069 |
123 | R>T | No |
ClinGen TOPMed |
|
|
CA192431233 rs930415686 |
129 | R>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
| TCGA novel | 132 | Y>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1587712521 CA373185787 |
133 | P>S | No |
ClinGen Ensembl |
|
|
CA5023439 rs747509692 |
134 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1417763292 CA373185778 |
134 | D>V | No |
ClinGen TOPMed |
|
|
CA373185765 rs1481536413 |
136 | S>N | No |
ClinGen gnomAD |
|
|
rs754542329 CA5023437 |
141 | R>S | No |
ClinGen ExAC gnomAD |
|
|
rs371094119 CA192428961 |
143 | A>T | No |
ClinGen ESP |
|
|
rs1291490169 CA373185705 |
145 | I>V | No |
ClinGen TOPMed |
|
|
CA373185661 rs1460733632 |
151 | G>V | No |
ClinGen gnomAD |
|
|
rs1205240197 CA373185654 |
152 | E>D | No |
ClinGen gnomAD |
|
|
rs747621759 CA192428937 |
152 | E>K | No |
ClinGen Ensembl |
|
|
CA5023434 rs755773572 |
159 | S>F | No |
ClinGen ExAC gnomAD |
|
|
rs866865953 COSM3765450 CA192428915 |
160 | R>C | Variant assessed as Somatic; impact. central_nervous_system [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated Ensembl NCI-TCGA |
|
CA192428907 rs79227130 |
160 | R>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
| TCGA novel | 163 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA5023433 rs750210590 |
165 | L>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1184469675 CA373185107 |
168 | A>S | No |
ClinGen gnomAD |
|
|
CA373185099 rs1486652540 |
169 | L>R | No |
ClinGen gnomAD |
|
|
rs780866174 CA5023409 |
173 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
CA192423759 rs796362881 |
173 | Q>L | No |
ClinGen Ensembl |
|
|
rs796947857 CA192423754 |
175 | Q>* | No |
ClinGen Ensembl |
|
| TCGA novel | 178 | L>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA373185009 rs1421604950 |
182 | M>I | No |
ClinGen TOPMed |
|
|
rs201686974 CA192423753 |
182 | M>V | No |
ClinGen 1000Genomes |
|
|
CA373185002 rs1290277193 |
183 | T>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA373184969 rs1295283908 |
188 | R>Q | No |
ClinGen gnomAD |
|
|
rs1319081546 CA373184940 |
193 | V>I | No |
ClinGen Ensembl |
|
|
CA373184859 rs1388530155 |
204 | Q>E | No |
ClinGen TOPMed |
|
|
rs375123428 CA192423743 |
204 | Q>L | No |
ClinGen ESP |
|
|
CA373184847 rs1364356726 |
206 | S>G | No |
ClinGen gnomAD |
|
|
CA373184811 rs1363757338 |
210 | K>N | No |
ClinGen gnomAD |
|
|
CA5023389 rs769292838 |
213 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
CA5023387 rs780962825 |
220 | A>G | No |
ClinGen ExAC gnomAD |
|
|
CA5023386 rs763537701 |
221 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
CA5023382 rs752613555 |
240 | V>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5023379 rs753832537 |
250 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs1408425458 CA373184205 |
252 | L>V | No |
ClinGen TOPMed |
|
| TCGA novel | 255 | Q>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs764707269 CA5023352 |
258 | D>A | No |
ClinGen ExAC gnomAD |
|
|
CA373184157 rs538564093 |
258 | D>E | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA5023350 rs776234785 |
261 | M>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA373184125 rs1188575517 |
262 | M>I | No |
ClinGen gnomAD |
|
|
rs765920904 CA5023349 |
263 | M>I | No |
ClinGen ExAC TOPMed |
|
|
rs1355768965 CA373184105 |
265 | D>H | No |
ClinGen TOPMed |
|
|
rs760415476 CA5023348 |
270 | M>T | No |
ClinGen ExAC gnomAD |
|
|
rs200292288 CA5023347 |
276 | T>K | No |
ClinGen 1000Genomes ExAC gnomAD |
|
| TCGA novel | 277 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA192421354 rs112341772 |
278 | M>I | No |
ClinGen Ensembl |
|
|
CA5023346 rs376079944 |
279 | L>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA373183993 rs1291006854 |
280 | A>V | No |
ClinGen gnomAD |
|
| TCGA novel | 283 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs773968747 CA5023344 |
287 | K>R | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 293 | I>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA373183559 rs1348402185 |
294 | Q>L | No |
ClinGen TOPMed |
|
|
rs774201482 CA5023320 |
296 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA5023317 rs775475727 |
305 | A>G | No |
ClinGen ExAC gnomAD |
|
|
rs749100840 CA5023318 |
305 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs912555089 CA192416467 |
307 | S>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1197401945 CA373183388 |
307 | S>N | No |
ClinGen gnomAD |
|
|
rs74393879 CA192416465 |
308 | K>T | No |
ClinGen Ensembl |
|
|
rs1247270973 CA373183317 |
313 | L>I | No |
ClinGen gnomAD |
|
|
CA192416462 rs781195040 |
314 | S>N | No |
ClinGen ExAC TOPMed |
|
|
rs781195040 CA5023314 |
314 | S>T | No |
ClinGen ExAC TOPMed |
|
|
CA373183235 rs1359458959 |
319 | S>N | No |
ClinGen TOPMed |
|
| TCGA novel | 324 | S>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs778211977 CA5023311 |
331 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA373183053 rs1480805784 |
335 | G>S | No |
ClinGen TOPMed |
|
|
rs1328928646 CA373183007 |
341 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
rs769740534 CA5023299 |
346 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201033994 CA192416314 |
352 | V>A | No |
ClinGen 1000Genomes |
|
|
rs1387703323 CA373182917 |
355 | A>T | No |
ClinGen TOPMed |
|
|
CA373182910 rs1211758093 |
356 | T>A | No |
ClinGen TOPMed gnomAD |
|
|
CA373182900 rs1170289933 |
357 | F>C | No |
ClinGen TOPMed |
|
|
CA373182857 rs1221516090 |
363 | Y>C | No |
ClinGen gnomAD |
|
|
CA373182719 rs1420656056 |
381 | T>A | No |
ClinGen TOPMed |
|
|
rs759482316 CA5023280 |
382 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs867659133 CA192415680 |
383 | C>F | No |
ClinGen Ensembl |
|
|
rs1166655789 CA373182631 |
394 | A>T | No |
ClinGen gnomAD |
|
| TCGA novel | 397 | D>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA192415673 rs762103267 |
400 | V>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
|
rs145996733 CA192415671 |
401 | N>S | No |
ClinGen ESP |
|
|
CA192415669 rs934656069 |
402 | S>G | No |
ClinGen Ensembl |
|
|
CA373182580 rs1324285924 |
402 | S>N | No |
ClinGen TOPMed |
|
|
rs1191021152 CA373182562 |
405 | L>I | No |
ClinGen gnomAD |
|
|
rs1306951886 CA373182532 |
409 | N>I | No |
ClinGen TOPMed |
|
|
rs866247778 CA192415663 |
410 | P>S | No |
ClinGen gnomAD |
|
|
CA5023273 rs779435806 |
415 | V>L | No |
ClinGen ExAC gnomAD |
|
|
CA5023272 rs769203919 |
417 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA373182452 rs1353831260 |
421 | T>A | No |
ClinGen TOPMed |
|
|
rs1342512833 CA373182447 |
421 | T>M | No |
ClinGen gnomAD |
|
| TCGA novel | 422 | V>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs986295998 CA192415654 |
422 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
CA5023268 rs751049620 |
423 | V>I | No |
ClinGen ExAC gnomAD |
|
|
rs538011443 CA5023267 |
425 | M>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA373182405 rs1290001414 |
427 | M>I | No |
ClinGen TOPMed |
|
|
rs1052691996 CA192414398 |
434 | S>N | No |
ClinGen Ensembl |
|
|
CA373182332 rs1306922214 |
436 | S>N | No |
ClinGen gnomAD |
|
| TCGA novel | 437 | S>F | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 437 | S>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA373182304 rs1448787281 |
440 | R>K | No |
ClinGen gnomAD |
|
|
CA192414394 rs935146382 |
442 | G>D | No |
ClinGen Ensembl |
|
| TCGA novel | 443 | G>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 444 | D>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA5023240 rs372926186 |
448 | C>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA373182239 rs1335755144 |
449 | A>V | No |
ClinGen gnomAD |
|
|
rs750052117 CA192414384 |
450 | L>F | No |
ClinGen Ensembl |
|
|
rs976675742 CA192414379 |
451 | S>C | No |
ClinGen Ensembl |
|
|
rs1306717255 CA373182221 |
453 | R>G | No |
ClinGen TOPMed |
|
|
rs1452382335 CA373182167 |
460 | V>I | No |
ClinGen gnomAD |
|
|
CA192414367 rs897034442 |
466 | L>F | No |
ClinGen TOPMed |
|
|
CA5023235 rs764437910 |
474 | G>D | No |
ClinGen ExAC gnomAD |
|
|
CA373181795 rs1426722440 |
489 | G>C | No |
ClinGen TOPMed |
|
|
rs1207865272 CA373181787 |
490 | I>T | No |
ClinGen gnomAD |
|
|
CA373181790 rs1169652792 |
490 | I>V | No |
ClinGen TOPMed |
|
|
rs753017552 CA5023216 |
491 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA5023215 rs765371310 |
491 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA192414159 rs139150841 |
493 | H>Q | No |
ClinGen ESP |
|
|
rs146185445 CA5023213 |
499 | I>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA5023214 rs759983891 |
499 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA373181717 rs1229686838 |
501 | T>S | No |
ClinGen TOPMed gnomAD |
|
|
CA373181674 rs1350827322 |
507 | L>V | No |
ClinGen gnomAD |
|
|
rs761103565 CA5023211 |
508 | L>V | No |
ClinGen ExAC gnomAD |
No associated diseases with Q2TAY7
11 regional properties for Q2TAY7
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| repeat | WD40 repeat | 202 - 251 | IPR001680-1 |
| repeat | WD40 repeat | 253 - 426 | IPR001680-2 |
| repeat | WD40 repeat | 428 - 470 | IPR001680-3 |
| repeat | WD40 repeat | 473 - 513 | IPR001680-4 |
| domain | LIS1 homology motif | 6 - 38 | IPR006594 |
| domain | CTLH, C-terminal LisH motif | 40 - 92 | IPR006595 |
| conserved_site | WD40 repeat, conserved site | 229 - 243 | IPR019775-1 |
| conserved_site | WD40 repeat, conserved site | 364 - 378 | IPR019775-2 |
| repeat | G-protein beta WD-40 repeat | 229 - 243 | IPR020472-1 |
| repeat | G-protein beta WD-40 repeat | 279 - 293 | IPR020472-2 |
| repeat | G-protein beta WD-40 repeat | 364 - 378 | IPR020472-3 |
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| nuclear speck | A discrete extra-nucleolar subnuclear domain, 20-50 in number, in which splicing factors are seen to be localized by immunofluorescence microscopy. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| precatalytic spliceosome | A spliceosomal complex that is formed by the recruitment of a preassembled U5-containing tri-snRNP to the prespliceosome. Although all 5 snRNPs are present, the precatalytic spliceosome is catalytically inactive. The precatalytic spliceosome includes many proteins in addition to those found in the associated snRNPs. |
| U2-type precatalytic spliceosome | A spliceosomal complex that is formed by the recruitment of the preassembled U4/U6.U5 tri-snRNP to the prespliceosome. Although all 5 snRNPs are present, the precatalytic spliceosome is catalytically inactive. The precatalytic spliceosome includes many proteins in addition to those found in the U1, U2 and U4/U6.U5 snRNPs. |
No GO annotations of molecular function
| Name | Definition |
|---|---|
| No GO annotations for molecular function |
3 GO annotations of biological process
| Name | Definition |
|---|---|
| mRNA splicing, via spliceosome | The joining together of exons from one or more primary transcripts of messenger RNA (mRNA) and the excision of intron sequences, via a spliceosomal mechanism, so that mRNA consisting only of the joined exons is produced. |
| regulation of alternative mRNA splicing, via spliceosome | Any process that modulates the frequency, rate or extent of alternative splicing of nuclear mRNAs. |
| RNA splicing | The process of removing sections of the primary RNA transcript to remove sequences not present in the mature form of the RNA and joining the remaining sections to form the mature form of the RNA. |
6 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q2TBS9 | SMU1 | WD40 repeat-containing protein SMU1 | Bos taurus (Bovine) | PR |
| Q5ZME8 | SMU1 | WD40 repeat-containing protein SMU1 | Gallus gallus (Chicken) | PR |
| Q3UKJ7 | Smu1 | WD40 repeat-containing protein SMU1 | Mus musculus (Mouse) | PR |
| Q99M63 | Smu1 | WD40 repeat-containing protein SMU1 | Rattus norvegicus (Rat) | PR |
| Q8W117 | SMU1 | Suppressor of mec-8 and unc-52 protein homolog 1 | Arabidopsis thaliana (Mouse-ear cress) | PR |
| Q7ZVA0 | smu1 | WD40 repeat-containing protein SMU1 | Danio rerio (Zebrafish) (Brachydanio rerio) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSIEIESSDV | IRLIMQYLKE | NSLHRALATL | QEETTVSLNT | VDSIESFVAD | INSGHWDTVL |
| 70 | 80 | 90 | 100 | 110 | 120 |
| QAIQSLKLPD | KTLIDLYEQV | VLELIELREL | GAARSLLRQT | DPMIMLKQTQ | PERYIHLENL |
| 130 | 140 | 150 | 160 | 170 | 180 |
| LARSYFDPRE | AYPDGSSKEK | RRAAIAQALA | GEVSVVPPSR | LMALLGQALK | WQQHQGLLPP |
| 190 | 200 | 210 | 220 | 230 | 240 |
| GMTIDLFRGK | AAVKDVEEEK | FPTQLSRHIK | FGQKSHVECA | RFSPDGQYLV | TGSVDGFIEV |
| 250 | 260 | 270 | 280 | 290 | 300 |
| WNFTTGKIRK | DLKYQAQDNF | MMMDDAVLCM | CFSRDTEMLA | TGAQDGKIKV | WKIQSGQCLR |
| 310 | 320 | 330 | 340 | 350 | 360 |
| RFERAHSKGV | TCLSFSKDSS | QILSASFDQT | IRIHGLKSGK | TLKEFRGHSS | FVNEATFTQD |
| 370 | 380 | 390 | 400 | 410 | 420 |
| GHYIISASSD | GTVKIWNMKT | TECSNTFKSL | GSTAGTDITV | NSVILLPKNP | EHFVVCNRSN |
| 430 | 440 | 450 | 460 | 470 | 480 |
| TVVIMNMQGQ | IVRSFSSGKR | EGGDFVCCAL | SPRGEWIYCV | GEDFVLYCFS | TVTGKLERTL |
| 490 | 500 | 510 | |||
| TVHEKDVIGI | AHHPHQNLIA | TYSEDGLLKL | WKP |