Q14919
Gene name |
DRAP1 |
Protein name |
Dr1-associated corepressor |
Names |
Dr1-associated protein 1, Negative cofactor 2-alpha, NC2-alpha |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:10589 |
EC number |
|
Protein Class |
|
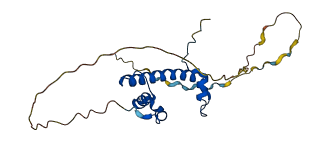
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
2 structures for Q14919
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1JFI | X-ray | 262 A | A | 1-77 | PDB |
| AF-Q14919-F1 | Predicted | AlphaFoldDB |
172 variants for Q14919
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA381376252 rs1230599132 |
2 | P>L | No |
ClinGen gnomAD |
|
| TCGA novel | 3 | S>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1341197444 CA381376271 |
4 | K>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA381376279 rs1222897599 |
4 | K>R | No |
ClinGen gnomAD |
|
|
CA6112148 rs747634661 |
10 | A>S | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 12 | F>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 14 | P>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 15 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1394777832 CA381378343 |
18 | K>R | No |
ClinGen Ensembl |
|
| TCGA novel | 20 | I>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs765527473 CA6112173 |
21 | M>V | No |
ClinGen ExAC gnomAD |
|
|
CA381378418 rs1303832206 |
22 | Q>* | No |
ClinGen TOPMed |
|
|
CA6112174 rs775993555 |
23 | T>M | No |
ClinGen ExAC gnomAD |
|
|
rs370030690 CA224016933 |
26 | E>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1277141575 CA381378565 |
30 | V>M | No |
ClinGen gnomAD |
|
|
CA6112179 rs201738884 |
32 | A>G | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA381378597 rs1442396393 |
32 | A>T | No |
ClinGen gnomAD |
|
|
CA6112178 rs201738884 |
32 | A>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1591101379 CA381378633 |
34 | V>G | No |
ClinGen Ensembl |
|
|
rs753828914 CA6112180 |
35 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA381378666 rs1172273425 |
37 | I>V | No |
ClinGen TOPMed |
|
| TCGA novel | 38 | I>= | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1181745938 CA381378710 |
39 | S>A | No |
ClinGen gnomAD |
|
|
CA224017023 rs1003675475 |
40 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1435106278 CA381378793 |
40 | R>W | No |
ClinGen gnomAD |
|
|
rs895419376 CA381378826 |
41 | A>E | No |
ClinGen TOPMed gnomAD |
|
|
rs539142750 CA6112199 |
41 | A>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA224017026 rs895419376 |
41 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA381378880 rs1471754549 |
43 | E>D | No |
ClinGen TOPMed |
|
|
CA6112201 rs752391356 |
44 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 45 | F>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA6112203 rs777230237 |
46 | L>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs924507193 CA224017042 |
48 | S>L | No |
ClinGen TOPMed |
|
|
rs1457645937 CA381379007 |
49 | L>P | No |
ClinGen TOPMed |
|
|
CA381379110 rs1447630272 |
52 | K>N | No |
ClinGen gnomAD |
|
|
CA6112205 rs756973190 |
53 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs745436509 CA6112207 |
55 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
rs1161100696 CA381379207 |
55 | Q>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1591101497 CA381379234 |
56 | V>G | No |
ClinGen Ensembl |
|
|
rs1245544184 CA381379384 |
61 | N>K | No |
ClinGen TOPMed |
|
|
rs780642209 CA6112209 |
65 | M>V | No |
ClinGen ExAC gnomAD |
|
|
rs1385799799 CA381379518 |
66 | T>I | No |
ClinGen gnomAD |
|
|
CA6112210 rs143982811 |
67 | T>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA381379555 rs1342638376 |
69 | H>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA381379808 rs1230992913 |
71 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
CA381379811 rs1230992913 |
71 | K>T | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 78 | Q>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA224017271 rs761980588 |
82 | F>L | No |
ClinGen Ensembl |
|
|
CA6112244 rs765897732 |
88 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA6112245 rs753337480 |
89 | S>A | No |
ClinGen ExAC gnomAD |
|
|
CA381380356 rs1309140747 |
91 | P>R | No |
ClinGen TOPMed |
|
|
rs1432041576 CA381380351 |
91 | P>S | No |
ClinGen gnomAD |
|
|
rs140904739 CA224017287 |
93 | M>V | No |
ClinGen ESP gnomAD |
|
|
CA6112248 rs779595242 |
95 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs748470098 CA6112249 |
95 | G>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs778071745 CA6112251 |
96 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA6112252 rs143062944 |
97 | G>R | No |
ClinGen ESP ExAC gnomAD |
|
|
CA381380625 rs1331053839 |
98 | E>K | No |
ClinGen TOPMed |
|
|
CA381380686 rs1462964506 |
100 | N>D | No |
ClinGen TOPMed |
|
|
CA6112256 rs768545872 |
102 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs141033990 CA6112255 |
102 | M>T | No |
ClinGen ESP ExAC gnomAD |
|
|
CA6112254 rs543738162 |
102 | M>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA381380784 rs774294429 |
103 | D>H | No |
ClinGen ExAC gnomAD |
|
|
CA6112257 rs774294429 |
103 | D>N | No |
ClinGen ExAC gnomAD |
|
|
rs761538985 CA6112258 |
104 | G>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA6112260 rs371036532 |
106 | K>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA6112261 rs760351628 |
108 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs150283691 CA6112262 |
109 | R>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1438025090 CA381380901 |
109 | R>P | No |
ClinGen TOPMed |
|
|
CA381381168 rs1212848910 |
111 | G>S | No |
ClinGen gnomAD |
|
|
rs368472384 COSM1739748 CA6112284 |
112 | R>Q | NS [Cosmic] | No |
ClinGen cosmic curated 1000Genomes ESP ExAC TOPMed gnomAD |
|
CA6112283 rs759048752 |
112 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1254200181 CA381381282 |
115 | G>C | No |
ClinGen gnomAD |
|
| TCGA novel | 116 | S>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs763532913 CA6112287 |
117 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA224017377 rs867126309 |
118 | G>D | No |
ClinGen gnomAD |
|
|
rs1159566380 CA381381382 |
118 | G>S | No |
ClinGen TOPMed |
|
|
CA224017379 rs969878412 |
119 | R>G | No |
ClinGen TOPMed |
|
|
rs1373398145 CA381381430 |
119 | R>Q | No |
ClinGen gnomAD |
|
|
CA381381412 COSM1204541 rs969878412 |
119 | R>W | large_intestine [Cosmic] | No |
ClinGen cosmic curated TOPMed |
|
CA381381447 rs1591101908 |
120 | K>E | No |
ClinGen Ensembl |
|
|
rs1308282104 CA381381487 |
121 | N>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1351998924 CA381381506 |
122 | G>S | No |
ClinGen gnomAD |
|
|
CA381381561 rs1439528891 |
123 | G>E | No |
ClinGen gnomAD |
|
|
rs973368266 CA224017380 |
123 | G>R | No |
ClinGen Ensembl |
|
|
rs992162385 CA224017382 |
124 | M>T | No |
ClinGen TOPMed gnomAD |
|
|
CA381381686 rs1367675675 |
126 | T>M | No |
ClinGen gnomAD |
|
|
CA381381682 rs1367675675 |
126 | T>R | No |
ClinGen gnomAD |
|
|
CA381381712 rs1278736552 |
127 | K>R | No |
ClinGen gnomAD |
|
|
rs528558933 CA6112290 |
128 | S>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA381381759 rs1206254669 |
129 | K>E | No |
ClinGen gnomAD |
|
|
CA6112291 rs370429317 |
130 | D>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA381381792 rs1482220567 |
130 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs750651508 CA6112292 |
131 | K>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs950426651 CA224017386 |
134 | S>C | No |
ClinGen TOPMed |
|
|
TCGA novel rs749407519 CA6112295 |
135 | G>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
NCI-TCGA ClinGen ExAC gnomAD |
|
rs1228881174 CA381382143 |
138 | S>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA6112316 rs529754496 |
142 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA381382524 rs1437763431 |
143 | E>K | No |
ClinGen TOPMed |
|
|
CA224017481 rs781110835 |
144 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA6112317 rs781110835 |
144 | S>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA381382667 rs769532800 |
146 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs745699388 CA6112318 |
146 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
COSM358561 CA224017487 rs1018604621 |
147 | T>A | lung [Cosmic] | No |
ClinGen cosmic curated Ensembl |
|
CA381382704 rs1473613514 |
147 | T>I | No |
ClinGen gnomAD |
|
|
CA6112320 rs199540648 |
148 | D>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA224017494 rs111381779 |
149 | T>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA6112321 rs111381779 |
149 | T>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA224017497 rs777795705 |
151 | G>R | No |
ClinGen Ensembl |
|
|
CA6112322 rs138267909 |
152 | E>K | No |
ClinGen ESP ExAC gnomAD |
|
|
CA6112324 rs762216373 |
154 | E>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs762216373 CA381382948 |
154 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA224017503 rs909423551 |
154 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
rs1591102205 CA381383056 |
157 | Q>H | No |
ClinGen Ensembl |
|
|
rs1292826685 CA381383075 |
158 | P>H | No |
ClinGen gnomAD |
|
|
rs773522319 CA381383071 |
158 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA6112326 rs773522319 |
158 | P>T | No |
ClinGen ExAC gnomAD |
|
|
rs535528544 CA6112327 |
159 | P>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs923531664 CA224017524 |
160 | P>L | No |
ClinGen TOPMed |
|
|
rs1313682527 CA381383111 |
160 | P>S | No |
ClinGen gnomAD |
|
|
rs1348509305 CA381383124 |
161 | Q>K | No |
ClinGen gnomAD |
|
|
CA6112329 rs754063411 |
161 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
CA381383173 rs1470000923 |
162 | A>T | No |
ClinGen TOPMed |
|
|
CA381383246 rs1380517232 |
163 | S>R | No |
ClinGen TOPMed gnomAD |
|
|
CA381383259 rs1256669222 |
164 | H>D | No |
ClinGen gnomAD |
|
|
rs755293005 CA6112330 |
165 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1486498200 CA381383300 |
165 | P>S | No |
ClinGen gnomAD |
|
|
rs1133928 CA224017536 |
166 | S>F | No |
ClinGen gnomAD |
|
|
rs1133928 CA381383329 |
166 | S>Y | No |
ClinGen gnomAD |
|
|
rs1338500918 CA381383338 |
167 | A>T | No |
ClinGen TOPMed gnomAD |
|
|
rs10143 CA224017541 |
168 | H>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs10143 CA6112332 |
168 | H>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs924222620 CA224017545 |
169 | F>C | No |
ClinGen TOPMed |
|
|
rs1303469823 CA381383631 |
171 | S>R | No |
ClinGen gnomAD |
|
|
CA381383637 rs1443524049 |
172 | P>A | No |
ClinGen TOPMed |
|
|
CA6112356 rs756191355 |
173 | P>L | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA381383666 rs756191355 |
173 | P>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
| rs751570365 | 174 | T>D | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs753718615 CA6112358 |
175 | P>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs201871633 CA6112359 |
177 | L>P | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs778647605 CA6112360 |
178 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA381383801 rs777331540 |
180 | A>P | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs777331540 COSM930582 CA6112363 |
180 | A>T | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
rs747500157 CA6112364 |
180 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1055612 CA224017737 |
181 | S>F | No |
ClinGen Ensembl |
|
|
CA381383900 rs1430597685 |
183 | L>M | No |
ClinGen TOPMed gnomAD |
|
|
rs1430597685 CA381383902 |
183 | L>V | No |
ClinGen TOPMed gnomAD |
|
|
CA6112366 rs200905448 |
184 | P>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA381383917 rs1591102485 |
184 | P>S | No |
ClinGen Ensembl |
|
|
rs1469950476 CA381383950 |
185 | L>F | No |
ClinGen TOPMed gnomAD |
|
|
rs568931883 CA6112368 |
186 | P>L | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA381383997 rs1293575746 |
187 | P>L | No |
ClinGen TOPMed |
|
|
CA6112370 rs763060612 |
188 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA381384032 rs1315549961 |
189 | P>H | No |
ClinGen TOPMed |
|
|
CA6112373 rs368226803 |
190 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs754813408 CA6112376 |
192 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA6112378 rs752385950 |
193 | S>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA224017762 COSM1561657 rs143922438 |
194 | A>T | large_intestine Variant assessed as Somatic; impact. [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated ESP NCI-TCGA |
|
CA6112380 rs777241976 |
196 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA6112381 rs144277926 |
198 | E>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs371695352 CA224017773 |
199 | D>E | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA224017769 rs957107181 |
199 | D>N | No |
ClinGen Ensembl |
|
|
CA381384226 rs1249147380 |
199 | D>V | No |
ClinGen gnomAD |
|
|
rs1159505236 CA381384238 |
200 | E>G | No |
ClinGen TOPMed |
|
|
CA6112383 rs781734189 |
200 | E>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs746162493 CA6112384 |
201 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1424674528 CA381384246 |
201 | E>K | No |
ClinGen gnomAD |
|
|
CA381384250 rs1424674528 |
201 | E>Q | No |
ClinGen gnomAD |
|
|
CA6112385 rs201827894 |
202 | D>N | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs552975920 CA6112387 |
204 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ExAC NCI-TCGA gnomAD |
|
CA381384342 rs1345762640 |
205 | S>P | No |
ClinGen gnomAD |
|
|
CA381384367 rs1198595991 |
206 | S>W | No |
ClinGen TOPMed |
No associated diseases with Q14919
3 GO annotations of cellular component
| Name | Definition |
|---|---|
| negative cofactor 2 complex | A heterodimeric protein complex that can stably associate with TATA-binding protein on promoters, thereby preventing the assembly of transcription factors TFIIA and TFIIB and leading to repression of RNA polymerase II transcription. The two subunits, NC2alpha (Drap1) and NC2beta (Dr1), dimerize through histone fold domains of the H2A/H2B type present in the amino termini. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| RNA polymerase II transcription regulator complex | A transcription factor complex that acts at a regulatory region of a gene transcribed by RNA polymerase II. |
8 GO annotations of molecular function
| Name | Definition |
|---|---|
| core promoter sequence-specific DNA binding | Binding to a sequence of DNA that is part of a core promoter region. The core promoter is composed of the transcription start site and binding sites for the RNA polymerase and the basal transcription machinery. The transcribed region might be described as a gene, cistron, or operon. |
| identical protein binding | Binding to an identical protein or proteins. |
| protein heterodimerization activity | Binding to a nonidentical protein to form a heterodimer. |
| RNA polymerase II general transcription initiation factor activity | A general transcription initiation factor activity that contributes to transcription start site selection and transcription initiation of genes transcribed by RNA polymerase II. The general transcription factors for RNA polymerase II include TFIIB, TFIID, TFIIE, TFIIF, TFIIH and TATA-binding protein (TBP). In most species, RNA polymerase II transcribes all messenger RNAs (mRNAs), most untranslated regulatory RNAs, the majority of the snoRNAs, four of the five snRNAs (U1, U2, U4, and U5), and other small noncoding RNAs. For some small RNAs there is variability between species as to whether it is transcribed by RNA polymerase II or RNA polymerase III. However there are also rare exceptions, such as Trypanosoma brucei, where RNA polymerase I transcribes certain mRNAs in addition to its normal role in rRNA transcription. |
| RNA polymerase II general transcription initiation factor binding | Binding to a basal RNA polymerase II transcription factor, any of the factors involved in formation of the preinitiation complex (PIC) by RNA polymerase II and defined as a basal or general transcription factor. |
| TBP-class protein binding | Binding to a member of the class of TATA-binding proteins (TBP), including any of the TBP-related factors (TRFs). |
| transcription coactivator activity | A transcription coregulator activity that activates or increases the transcription of specific gene sets via binding to a DNA-bound DNA-binding transcription factor, either on its own or as part of a complex. Coactivators often act by altering chromatin structure and modifications. For example, one class of transcription coactivators modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. A fourth class of coactivator activity is the bridging of a DNA-binding transcription factor to the general (basal) transcription machinery. The Mediator complex, which bridges sequence-specific DNA binding transcription factors and RNA polymerase, is also a transcription coactivator. |
| transcription corepressor activity | A transcription coregulator activity that represses or decreases the transcription of specific gene sets via binding to a DNA-bound DNA-binding transcription factor, either on its own or as part of a complex. Corepressors often act by altering chromatin structure and modifications. For example, one class of transcription corepressors modifies chromatin structure through covalent modification of histones. A second class remodels the conformation of chromatin in an ATP-dependent fashion. A third class modulates interactions of DNA-bound DNA-binding transcription factors with other transcription coregulators. |
4 GO annotations of biological process
| Name | Definition |
|---|---|
| negative regulation of transcription by RNA polymerase II | Any process that stops, prevents, or reduces the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| positive regulation of transcription by RNA polymerase II | Any process that activates or increases the frequency, rate or extent of transcription from an RNA polymerase II promoter. |
| regulation of DNA-templated transcription | Any process that modulates the frequency, rate or extent of cellular DNA-templated transcription. |
| transcription by RNA polymerase II | The synthesis of RNA from a DNA template by RNA polymerase II (RNAP II), originating at an RNA polymerase II promoter. Includes transcription of messenger RNA (mRNA) and certain small nuclear RNAs (snRNAs). |
4 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P40096 | BUR6 | Negative cofactor 2 complex subunit alpha | Saccharomyces cerevisiae (strain ATCC 204508 / S288c) (Baker's yeast) | PR |
| Q2YDP3 | DRAP1 | Dr1-associated corepressor | Bos taurus (Bovine) | PR |
| Q9D6N5 | Drap1 | Dr1-associated corepressor | Mus musculus (Mouse) | PR |
| A0JPP1 | Drap1 | Dr1-associated corepressor | Rattus norvegicus (Rat) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MPSKKKKYNA | RFPPARIKKI | MQTDEEIGKV | AAAVPVIISR | ALELFLESLL | KKACQVTQSR |
| 70 | 80 | 90 | 100 | 110 | 120 |
| NAKTMTTSHL | KQCIELEQQF | DFLKDLVASV | PDMQGDGEDN | HMDGDKGARR | GRKPGSGGRK |
| 130 | 140 | 150 | 160 | 170 | 180 |
| NGGMGTKSKD | KKLSGTDSEQ | EDESEDTDTD | GEEETSQPPP | QASHPSAHFQ | SPPTPFLPFA |
| 190 | 200 | ||||
| STLPLPPAPP | GPSAPDEEDE | EDYDS |