Q08752
Gene name |
PPID |
Protein name |
Peptidyl-prolyl cis-trans isomerase D |
Names |
PPIase D, 40 kDa peptidyl-prolyl cis-trans isomerase, Cyclophilin-40, CYP-40, Cyclophilin-related protein, Rotamase D |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:5481 |
EC number |
5.2.1.8: Cis-trans isomerases |
Protein Class |
|
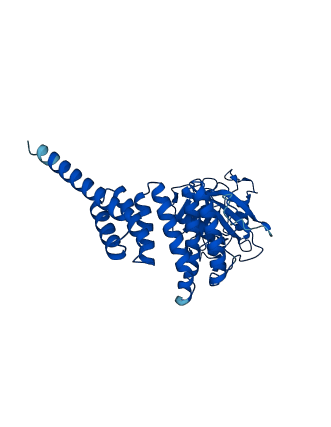
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q08752
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q08752-F1 | Predicted | AlphaFoldDB |
300 variants for Q08752
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA358573226 rs1229416573 |
2 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1229416573 CA358573227 |
2 | S>W | No |
ClinGen TOPMed gnomAD |
|
|
rs1580435656 CA358573221 |
3 | H>P | No |
ClinGen Ensembl |
|
| TCGA novel | 3 | H>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs373064507 CA3123120 |
4 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA3123119 rs373064507 |
4 | P>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 5 | S>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA358573205 rs760272453 |
6 | P>A | No |
ClinGen ExAC gnomAD |
|
|
CA3123114 rs144881111 |
6 | P>L | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA3123115 rs760272453 |
6 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs1390705717 CA358573195 |
7 | Q>H | No |
ClinGen gnomAD |
|
|
CA3123110 rs774062745 |
8 | A>D | No |
ClinGen ExAC gnomAD |
|
|
rs774062745 CA358573191 |
8 | A>G | No |
ClinGen ExAC gnomAD |
|
|
CA358573190 COSM3714825 rs774062745 |
8 | A>V | upper_aerodigestive_tract [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
CA108832831 rs199533620 |
10 | P>S | No |
ClinGen Ensembl |
|
|
CA108832823 rs1044099116 |
12 | N>D | No |
ClinGen Ensembl |
|
|
CA108832818 rs948458237 |
12 | N>S | No |
ClinGen Ensembl |
|
|
rs1285722186 CA358573160 |
13 | P>R | No |
ClinGen gnomAD |
|
|
rs536936871 CA3123107 |
14 | S>G | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1254303632 CA358573137 |
17 | R>G | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA358573135 rs1183554758 |
17 | R>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
| TCGA novel | 19 | F>L | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1561258782 CA358573124 |
19 | F>V | No |
ClinGen Ensembl |
|
|
rs1456547562 CA358573114 |
20 | F>C | No |
ClinGen TOPMed |
|
|
CA3123102 rs772342097 |
27 | E>A | No |
ClinGen ExAC gnomAD |
|
| rs1305691320 | 28 | R>= | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1348917239 CA358573062 |
28 | R>G | No |
ClinGen gnomAD |
|
|
CA358573058 rs1340569084 |
28 | R>L | No |
ClinGen TOPMed |
|
|
CA3123101 rs746212415 |
29 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA358572876 rs1187991058 |
30 | G>D | No |
ClinGen gnomAD |
|
|
rs778127676 CA3123077 |
31 | R>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA108831652 rs746957379 |
31 | R>L | No |
ClinGen gnomAD |
|
|
CA358572863 rs746957379 |
31 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs1442101224 CA358572859 |
32 | I>V | No |
ClinGen gnomAD |
|
|
CA3123074 rs752223056 |
35 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA3123075 rs756732759 |
35 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA358572822 rs756732759 |
35 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA3123072 rs754557537 |
39 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA3123071 rs751116720 |
40 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358572756 rs1446788454 |
40 | I>V | No |
ClinGen gnomAD |
|
|
rs762653393 CA3123069 |
41 | V>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs1387282089 CA358572725 |
42 | P>H | No |
ClinGen gnomAD |
|
|
rs1165501560 CA358572716 |
43 | K>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs750293636 CA3123068 |
44 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs201322183 CA3123067 |
45 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs147585130 CA3123065 |
46 | E>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1190762888 CA358572660 |
47 | N>I | No |
ClinGen gnomAD |
|
|
CA3123064 rs2070631 VAR_021021 |
49 | R>C | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA108831585 rs369501739 |
49 | R>H | No |
ClinGen 1000Genomes ESP ExAC gnomAD |
|
|
rs369501739 CA3123063 |
49 | R>P | No |
ClinGen 1000Genomes ESP ExAC gnomAD |
|
|
rs774428808 CA3123062 |
50 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1561258066 CA358572619 |
50 | A>V | No |
ClinGen Ensembl |
|
|
CA3123061 rs771239741 |
51 | L>P | No |
ClinGen ExAC gnomAD |
|
|
CA358572604 rs1301801325 |
52 | C>F | No |
ClinGen TOPMed |
|
|
rs749592443 CA3123060 |
53 | T>R | No |
ClinGen ExAC gnomAD |
|
|
rs186494786 CA3123058 |
58 | I>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1432463452 CA358572513 |
58 | I>V | No |
ClinGen gnomAD |
|
|
CA3123056 rs761231161 |
61 | T>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3123057 rs761231161 |
61 | T>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358572451 rs1286247910 |
62 | T>I | No |
ClinGen TOPMed |
|
|
CA358572445 rs1348114462 |
63 | G>R | No |
ClinGen gnomAD |
|
|
CA108831562 rs553055223 |
66 | L>F | No |
ClinGen Ensembl |
|
| rs1310420226 | 66 | L>P | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs148824218 CA358572400 |
67 | H>N | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA3123055 rs148824218 |
67 | H>Y | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA358572349 rs1486092318 |
70 | G>E | No |
ClinGen TOPMed |
|
|
CA358572324 rs1421409992 |
72 | P>R | No |
ClinGen gnomAD |
|
|
rs1410262229 CA358572326 |
72 | P>S | No |
ClinGen gnomAD |
|
|
rs200023691 CA3123053 |
73 | F>L | No |
ClinGen 1000Genomes ExAC TOPMed |
|
|
CA3123052 rs572328740 |
74 | H>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA3123051 rs199670143 |
75 | R>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs764980502 CA358572304 |
75 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs764980502 CA3123050 COSM1052687 |
75 | R>Q | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
CA358572302 rs1194397416 |
76 | I>V | No |
ClinGen gnomAD |
|
|
rs371764900 CA3123030 |
77 | I>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1580433007 CA358572061 |
79 | K>E | No |
ClinGen Ensembl |
|
|
rs1401784711 CA358572015 |
81 | M>I | No |
ClinGen TOPMed gnomAD |
|
|
CA3123027 rs903097312 |
81 | M>V | No |
ClinGen Ensembl |
|
|
CA358572009 rs1414924295 |
82 | I>V | No |
ClinGen gnomAD |
|
|
rs763989732 CA3123026 |
87 | F>V | No |
ClinGen ExAC |
|
|
CA358571937 rs1180657774 |
87 | F>Y | No |
ClinGen gnomAD |
|
|
CA3123025 rs756128169 |
89 | N>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs982513574 CA108826802 |
89 | N>T | No |
ClinGen TOPMed gnomAD |
|
|
CA3123024 rs752599902 |
91 | N>D | No |
ClinGen ExAC gnomAD |
|
|
rs150071508 CA3123023 |
91 | N>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs762946236 CA3123022 |
93 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA358571811 rs1254877052 |
96 | E>D | No |
ClinGen gnomAD |
|
|
rs1561257024 CA358571822 |
96 | E>K | No |
ClinGen Ensembl |
|
|
rs773510320 CA3123021 |
97 | S>N | No |
ClinGen ExAC gnomAD |
|
|
CA3123019 rs762261940 |
99 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
CA3123020 rs765612772 |
99 | Y>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs1323006671 CA358571734 |
102 | K>N | No |
ClinGen TOPMed |
|
|
rs1449475073 CA358571732 |
103 | F>L | No |
ClinGen Ensembl |
|
|
CA108826762 rs548685262 |
104 | E>D | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA3123015 rs775889500 |
108 | F>L | No |
ClinGen ExAC gnomAD |
|
|
rs958686023 CA108826749 |
110 | Y>* | No |
ClinGen TOPMed gnomAD |
|
|
rs10027955 CA108826752 |
110 | Y>F | No |
ClinGen Ensembl |
|
|
CA3123014 rs771556640 |
110 | Y>H | No |
ClinGen ExAC gnomAD |
|
|
CA3122993 rs772525566 |
112 | H>R | No |
ClinGen ExAC |
|
|
CA358571282 rs1456649301 |
114 | R>P | No |
ClinGen gnomAD |
|
|
rs1456649301 CA358571281 |
114 | R>Q | No |
ClinGen gnomAD |
|
|
rs139251147 CA3122991 |
114 | R>W | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA108825721 rs1006795714 |
116 | G>A | No |
ClinGen Ensembl |
|
|
rs373945693 CA3122990 |
118 | L>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs200244153 CA3122988 |
119 | S>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358571238 rs1274616009 |
120 | M>I | No |
ClinGen TOPMed |
|
|
CA358571248 rs1561256269 |
120 | M>L | No |
ClinGen Ensembl |
|
|
COSM139555 rs964869489 CA358571245 |
120 | M>R | skin [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
CA108825708 rs964869489 |
120 | M>T | No |
ClinGen TOPMed gnomAD |
|
|
rs777295635 CA3122986 |
122 | N>D | No |
ClinGen ExAC gnomAD |
|
|
rs781184174 CA3122983 |
125 | R>C | No |
ClinGen ExAC gnomAD |
|
|
rs370283252 CA3122982 |
125 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs143782344 CA3122978 |
129 | G>S | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA3122977 rs764285658 |
130 | S>C | No |
ClinGen ExAC gnomAD |
|
|
CA108825669 rs982283669 |
131 | Q>H | No |
ClinGen Ensembl |
|
|
CA108825664 rs948300718 |
133 | F>C | No |
ClinGen Ensembl |
|
| rs1456058528 | 134 | I>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs761099901 CA3122976 |
135 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs1561256235 CA358571043 |
137 | V>A | No |
ClinGen Ensembl |
|
|
rs767991856 CA3122974 |
138 | P>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3122973 rs140112626 |
139 | T>A | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA358571011 rs1366570184 |
140 | P>L | No |
ClinGen TOPMed |
|
|
CA3122971 rs1029605285 |
141 | H>L | No |
ClinGen TOPMed gnomAD |
|
|
CA3122970 rs774872033 |
143 | D>A | No |
ClinGen ExAC |
|
|
rs765810473 CA3122969 |
144 | G>R | No |
ClinGen ExAC gnomAD |
|
|
rs368268182 RCV000882917 |
146 | H>missing | No |
ClinVar dbSNP |
|
|
CA3122967 rs772905514 |
146 | H>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358570928 rs1432566041 |
146 | H>Q | No |
ClinGen gnomAD |
|
|
rs772905514 CA358570934 COSM1663636 |
146 | H>R | kidney [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
CA108825632 rs1005637193 |
147 | V>M | No |
ClinGen TOPMed |
|
|
CA3122964 rs747942920 |
148 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs769399237 CA3122965 |
148 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs1272662860 CA358570877 |
151 | Q>* | No |
ClinGen gnomAD |
|
|
rs1044603213 CA108825598 |
156 | I>L | No |
ClinGen TOPMed gnomAD |
|
|
CA358570815 rs1044603213 |
156 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
CA3122962 rs768592429 |
160 | R>G | No |
ClinGen ExAC |
|
|
CA358570708 rs1411992948 |
166 | E>A | No |
ClinGen gnomAD |
|
|
CA358570698 rs1349032627 |
167 | V>G | No |
ClinGen gnomAD |
|
|
CA108825586 rs917527213 |
174 | K>E | No |
ClinGen TOPMed |
|
|
rs1414716231 CA358570653 |
174 | K>T | No |
ClinGen gnomAD |
|
|
CA3122939 rs61756415 RCV000971744 |
177 | V>I | No |
ClinGen ClinVar 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA3122938 rs376881696 |
178 | I>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs750052850 CA108824662 |
179 | A>P | No |
ClinGen Ensembl |
|
|
rs563148248 CA108824661 |
179 | A>V | No |
ClinGen 1000Genomes |
|
|
CA3122937 rs756250902 |
181 | C>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358570487 rs1441867276 |
181 | C>S | No |
ClinGen gnomAD |
|
|
rs1248760341 CA358570427 |
185 | K>N | No |
ClinGen gnomAD |
|
|
rs1211094428 CA358570421 |
186 | E>* | No |
ClinGen TOPMed gnomAD |
|
|
rs1365193739 CA358570390 |
188 | D>G | No |
ClinGen gnomAD |
|
|
rs201748429 CA358570369 |
190 | G>R | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ExAC NCI-TCGA gnomAD |
|
rs201748429 CA3122935 |
190 | G>W | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1282004467 CA358570350 |
191 | G>E | No |
ClinGen gnomAD |
|
|
rs577887554 CA3122931 |
192 | I>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA108824587 rs148089573 |
193 | F>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA3122930 rs148089573 |
193 | F>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1322017334 CA358570327 |
194 | P>L | No |
ClinGen gnomAD |
|
|
CA108824562 rs2230222 |
196 | D>A | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
VAR_051771 CA3122927 rs2230222 |
196 | D>V | No |
ClinGen UniProt 1000Genomes ExAC TOPMed dbSNP gnomAD |
|
|
rs760519600 CA3122923 |
198 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs760519600 CA358570288 |
198 | S>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3122924 rs763894272 |
198 | S>P | No |
ClinGen ExAC gnomAD |
|
|
rs759355144 CA3122921 |
200 | D>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs759355144 CA3122920 |
200 | D>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358570261 rs1390845320 |
201 | S>G | No |
ClinGen gnomAD |
|
|
rs774351867 CA3122919 |
202 | H>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358570242 rs774351867 |
202 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA108824538 rs557793411 |
203 | P>L | No |
ClinGen Ensembl |
|
|
rs1463933963 CA358570201 |
205 | F>C | No |
ClinGen gnomAD |
|
| TCGA novel | 208 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs769706660 CA3122918 |
209 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs1580430927 CA358570134 |
210 | D>V | No |
ClinGen Ensembl |
|
|
CA358570087 rs1453631075 |
214 | K>Q | No |
ClinGen gnomAD |
|
|
rs914731857 CA108824534 |
214 | K>R | No |
ClinGen TOPMed |
|
|
rs1288203826 CA358570069 |
215 | D>A | No |
ClinGen gnomAD |
|
| TCGA novel | 215 | D>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs555544713 CA3122901 |
216 | V>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ExAC NCI-TCGA gnomAD |
|
rs1278758748 CA358569998 |
217 | D>E | No |
ClinGen gnomAD |
|
| TCGA novel | 217 | D>Y | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs770969643 CA3122900 |
219 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs887553720 CA108824322 |
222 | I>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1410129025 CA358569924 |
223 | T>I | No |
ClinGen gnomAD |
|
|
rs776740589 CA3122897 |
228 | N>D | No |
ClinGen ExAC gnomAD |
|
| rs1386625884 | 228 | N>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA358569853 rs1428101315 |
228 | N>T | No |
ClinGen gnomAD |
|
|
rs1353982742 CA358569842 |
229 | I>F | No |
ClinGen gnomAD |
|
|
rs1277402768 CA358569836 |
229 | I>T | No |
ClinGen TOPMed |
|
|
rs768744307 CA3122896 |
230 | G>E | No |
ClinGen ExAC gnomAD |
|
|
CA358569831 rs1211886739 |
230 | G>R | No |
ClinGen TOPMed |
|
|
rs747190918 CA3122895 |
233 | F>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358569790 rs1182779511 |
235 | K>N | No |
ClinGen TOPMed |
|
| rs766208165 | 235 | K>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1253933623 CA358569784 |
236 | S>F | No |
ClinGen TOPMed |
|
|
rs1199334796 CA358569783 |
237 | Q>* | No |
ClinGen gnomAD |
|
|
rs1199334796 CA358569781 |
237 | Q>E | No |
ClinGen gnomAD |
|
|
rs1199334796 CA358569782 |
237 | Q>K | No |
ClinGen gnomAD |
|
|
rs772265116 CA3122892 |
242 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA3122891 rs746297654 |
243 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs1480133395 CA358569734 |
243 | I>V | No |
ClinGen gnomAD |
|
|
CA358569713 rs1561255595 |
246 | Y>H | No |
ClinGen Ensembl |
|
|
CA108824287 rs935239695 |
247 | A>G | No |
ClinGen TOPMed |
|
|
CA108824291 rs952857221 |
247 | A>S | No |
ClinGen Ensembl |
|
|
CA358569701 rs935239695 |
247 | A>V | No |
ClinGen TOPMed |
|
|
CA358569688 rs1429549618 |
249 | V>A | No |
ClinGen TOPMed |
|
|
rs199788740 CA108823133 |
252 | Y>* | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA108823123 rs201693237 |
253 | V>M | No |
ClinGen ESP gnomAD |
|
|
CA358569285 rs1344392404 |
255 | S>R | No |
ClinGen gnomAD |
|
|
rs760754001 CA3122875 |
258 | A>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358569266 rs760754001 |
258 | A>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3122876 rs764093550 |
258 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs775558715 CA3122874 |
259 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs1261263060 CA358569257 |
260 | I>F | No |
ClinGen gnomAD |
|
|
CA358569255 rs1225441048 |
260 | I>T | No |
ClinGen TOPMed gnomAD |
|
|
CA3122873 rs772400759 |
261 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358569250 rs772400759 |
261 | E>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3122872 rs746200400 |
262 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs1230271816 CA358569229 |
264 | D>G | No |
ClinGen gnomAD |
|
|
rs1236342608 CA358569208 |
267 | K>R | No |
ClinGen TOPMed |
|
|
CA358569198 rs1272428425 |
269 | Q>E | No |
ClinGen TOPMed |
|
|
rs769087843 CA358569192 |
269 | Q>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1377023683 CA358569194 |
269 | Q>L | No |
ClinGen gnomAD |
|
|
CA358569191 rs1203927418 |
270 | P>S | No |
ClinGen TOPMed |
|
|
CA3122870 rs771456590 |
271 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs923360033 CA108823078 |
271 | I>V | No |
ClinGen TOPMed |
|
|
CA358569162 rs1481736307 |
274 | S>N | No |
ClinGen TOPMed |
|
|
rs149337294 CA3122868 |
275 | C>* | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA3122866 rs747727482 |
276 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3122865 rs780678246 |
280 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA358569089 rs1384055493 |
285 | K>N | No |
ClinGen gnomAD |
|
|
CA358569079 rs1188709742 |
286 | M>I | No |
ClinGen gnomAD |
|
|
CA358569077 rs1451250915 |
287 | S>P | No |
ClinGen gnomAD |
|
|
CA3122863 rs751192669 |
288 | N>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
CA789739879 rs1418011911 |
289 | W>* | No |
ClinGen TOPMed |
|
|
CA358569051 rs1277520271 |
289 | W>C | No |
ClinGen gnomAD |
|
|
rs201519841 CA3122862 |
290 | Q>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1488657103 CA358569025 |
292 | A>P | No |
ClinGen gnomAD |
|
|
rs1267035192 CA358569007 |
293 | I>T | No |
ClinGen gnomAD |
|
|
rs1053419968 CA108823033 |
293 | I>V | No |
ClinGen TOPMed |
|
|
CA358568947 rs1324829381 |
297 | L>S | No |
ClinGen TOPMed |
|
|
rs574999524 CA3122843 |
299 | A>P | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs746604180 CA3122842 |
300 | L>P | No |
ClinGen ExAC gnomAD |
|
|
rs9410 CA3122841 VAR_021022 |
302 | L>I | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA3122840 rs758172917 |
302 | L>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA358568227 rs9410 |
302 | L>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA358568217 rs1345291158 |
303 | D>H | No |
ClinGen gnomAD |
|
|
CA108821857 rs375866696 |
304 | P>A | No |
ClinGen ESP |
|
|
CA358568185 COSM3825468 CA358568184 rs1411312747 |
305 | S>* | Variant assessed as Somatic; 0.0 impact. breast [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD NCI-TCGA |
|
CA3122838 rs750282624 |
306 | N>D | No |
ClinGen ExAC gnomAD |
|
|
rs1041141226 CA108821821 |
308 | K>E | No |
ClinGen Ensembl |
|
|
CA3122837 rs778787483 |
308 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1353697125 CA358568132 |
309 | A>E | No |
ClinGen TOPMed |
|
| TCGA novel | 309 | A>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA358568110 rs1466484017 |
311 | Y>N | No |
ClinGen gnomAD |
|
|
CA3122836 rs757140682 |
312 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3122834 rs146023246 |
312 | R>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs146023246 CA3122835 |
312 | R>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1479958003 CA358568072 |
314 | A>T | No |
ClinGen gnomAD |
|
|
rs759551376 CA358568056 |
315 | Q>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs759551376 CA3122833 |
315 | Q>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA3122832 rs751795274 |
317 | W>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs1212799546 CA358568013 |
318 | Q>E | No |
ClinGen gnomAD |
|
|
rs1341211295 CA358567998 |
319 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
CA358567976 rs1248495241 |
320 | L>F | No |
ClinGen gnomAD |
|
|
rs766776446 CA3122831 |
321 | K>R | No |
ClinGen ExAC gnomAD |
|
|
CA3122830 rs763378856 |
323 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
CA358567946 rs1345815916 |
323 | Y>H | No |
ClinGen TOPMed gnomAD |
|
|
CA3122829 rs773761913 |
325 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
rs1159307954 CA358567903 |
326 | A>T | No |
ClinGen TOPMed |
|
|
CA358567900 rs1410287340 |
326 | A>V | No |
ClinGen TOPMed |
|
|
CA358567854 rs1451814315 |
328 | A>G | No |
ClinGen gnomAD |
|
|
rs1312346676 CA358567858 |
328 | A>S | No |
ClinGen gnomAD |
|
|
rs766688594 CA3122810 |
329 | D>H | No |
ClinGen ExAC gnomAD |
|
|
CA108821691 rs375804461 |
330 | L>F | No |
ClinGen ESP TOPMed |
|
| TCGA novel | 331 | K>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs750704015 CA3122808 |
332 | K>Q | No |
ClinGen ExAC gnomAD |
|
|
rs17843956 VAR_021023 CA3122806 |
335 | G>E | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs762097732 CA358567774 COSM1671399 |
336 | I>L | haematopoietic_and_lymphoid_tissue [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
CA358567765 rs1444087441 |
336 | I>M | No |
ClinGen TOPMed gnomAD |
|
|
rs762097732 CA3122805 |
336 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1471103469 CA358567761 |
337 | A>P | No |
ClinGen TOPMed |
|
|
CA3122803 rs769106998 |
341 | K>N | No |
ClinGen ExAC gnomAD |
|
|
rs1404605458 CA358567436 |
343 | I>F | No |
ClinGen gnomAD |
|
|
rs1371217115 CA358567417 |
344 | Q>P | No |
ClinGen TOPMed gnomAD |
|
|
rs1371217115 CA358567419 |
344 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA108821078 rs867529343 |
345 | A>T | No |
ClinGen Ensembl |
|
|
rs1419346648 CA358567339 |
349 | K>E | No |
ClinGen gnomAD |
|
|
CA3122768 rs769662759 |
350 | V>D | No |
ClinGen ExAC gnomAD |
|
|
CA358567303 rs1227038539 |
351 | K>R | No |
ClinGen TOPMed |
|
|
CA3122767 rs748030399 |
353 | K>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs758537870 CA3122765 |
359 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA3122762 rs757465987 |
362 | K>R | No |
ClinGen ExAC gnomAD |
|
|
CA3122761 rs538421682 |
363 | A>P | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1282449617 CA358567099 |
364 | V>A | No |
ClinGen gnomAD |
|
|
rs756487143 CA3122758 |
365 | Y>C | No |
ClinGen ExAC TOPMed |
|
|
CA358567094 rs1443766657 |
365 | Y>H | No |
ClinGen gnomAD |
|
|
rs753193581 CA3122757 |
366 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs768083464 CA3122756 |
367 | K>E | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 367 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA3122755 rs759016469 |
368 | M>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1580427286 CA358567055 |
368 | M>T | No |
ClinGen Ensembl |
|
|
CA358567027 rs1354037728 |
370 | A>V | No |
ClinGen gnomAD |
No associated diseases with Q08752
5 regional properties for Q08752
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Cyclophilin-type peptidyl-prolyl cis-trans isomerase domain | 19 - 183 | IPR002130 |
| repeat | Tetratricopeptide repeat | 223 - 256 | IPR019734-1 |
| repeat | Tetratricopeptide repeat | 273 - 306 | IPR019734-2 |
| repeat | Tetratricopeptide repeat | 307 - 340 | IPR019734-3 |
| conserved_site | Cyclophilin-type peptidyl-prolyl cis-trans isomerase, conserved site | 68 - 85 | IPR020892 |
Functions
| Description | ||
|---|---|---|
| EC Number | 5.2.1.8 | Cis-trans isomerases |
| Subcellular Localization |
|
|
| PANTHER Family | ||
| PANTHER Subfamily | ||
| PANTHER Protein Class | ||
| PANTHER Pathway Category | No pathway information available | |
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| nucleolus | A small, dense body one or more of which are present in the nucleus of eukaryotic cells. It is rich in RNA and protein, is not bounded by a limiting membrane, and is not seen during mitosis. Its prime function is the transcription of the nucleolar DNA into 45S ribosomal-precursor RNA, the processing of this RNA into 5.8S, 18S, and 28S components of ribosomal RNA, and the association of these components with 5S RNA and proteins synthesized outside the nucleolus. This association results in the formation of ribonucleoprotein precursors; these pass into the cytoplasm and mature into the 40S and 60S subunits of the ribosome. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
7 GO annotations of molecular function
| Name | Definition |
|---|---|
| cyclosporin A binding | Binding to cyclosporin A, a cyclic undecapeptide that contains several N-methylated and unusual amino acids. |
| heat shock protein binding | Binding to a heat shock protein, a protein synthesized or activated in response to heat shock. |
| Hsp70 protein binding | Binding to a Hsp70 protein, heat shock proteins around 70kDa in size. |
| Hsp90 protein binding | Binding to Hsp90 proteins, any of a group of heat shock proteins around 90kDa in size. |
| nuclear estrogen receptor binding | Binding to a nuclear estrogen receptor. |
| peptidyl-prolyl cis-trans isomerase activity | Catalysis of the reaction: peptidyl-proline (omega=180) = peptidyl-proline (omega=0). |
| transcription factor binding | Binding to a transcription factor, a protein required to initiate or regulate transcription. |
13 GO annotations of biological process
| Name | Definition |
|---|---|
| apoptotic process | A programmed cell death process which begins when a cell receives an internal (e.g. DNA damage) or external signal (e.g. an extracellular death ligand), and proceeds through a series of biochemical events (signaling pathway phase) which trigger an execution phase. The execution phase is the last step of an apoptotic process, and is typically characterized by rounding-up of the cell, retraction of pseudopodes, reduction of cellular volume (pyknosis), chromatin condensation, nuclear fragmentation (karyorrhexis), plasma membrane blebbing and fragmentation of the cell into apoptotic bodies. When the execution phase is completed, the cell has died. |
| cellular response to UV-A | Any process that results in a change in state or activity of a cell (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a UV-A radiation stimulus. UV-A radiation (UV-A light) spans the wavelengths 315 to 400 nm. |
| chaperone-mediated protein folding | The process of inhibiting aggregation and assisting in the covalent and noncovalent assembly of single chain polypeptides or multisubunit complexes into the correct tertiary structure that is dependent on interaction with a chaperone. |
| lipid droplet organization | A process that is carried out at the cellular level which results in the assembly, arrangement of constituent parts, or disassembly of a lipid particle. |
| negative regulation of transcription by RNA polymerase II | Any process that stops, prevents, or reduces the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| positive regulation of apoptotic process | Any process that activates or increases the frequency, rate or extent of cell death by apoptotic process. |
| positive regulation of protein secretion | Any process that activates or increases the frequency, rate or extent of the controlled release of a protein from a cell. |
| positive regulation of viral genome replication | Any process that activates or increases the frequency, rate or extent of viral genome replication. |
| protein folding | The process of assisting in the covalent and noncovalent assembly of single chain polypeptides or multisubunit complexes into the correct tertiary structure. |
| protein peptidyl-prolyl isomerization | The modification of a protein by cis-trans isomerization of a proline residue. |
| protein transport | The directed movement of proteins into, out of or within a cell, or between cells, by means of some agent such as a transporter or pore. |
| protein-containing complex assembly | The aggregation, arrangement and bonding together of a set of macromolecules to form a protein-containing complex. |
| viral release from host cell | The dissemination of mature viral particles from the host cell, e.g. by cell lysis or the budding of virus particles from the cell membrane. |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSHPSPQAKP | SNPSNPRVFF | DVDIGGERVG | RIVLELFADI | VPKTAENFRA | LCTGEKGIGH |
| 70 | 80 | 90 | 100 | 110 | 120 |
| TTGKPLHFKG | CPFHRIIKKF | MIQGGDFSNQ | NGTGGESIYG | EKFEDENFHY | KHDREGLLSM |
| 130 | 140 | 150 | 160 | 170 | 180 |
| ANAGRNTNGS | QFFITTVPTP | HLDGKHVVFG | QVIKGIGVAR | ILENVEVKGE | KPAKLCVIAE |
| 190 | 200 | 210 | 220 | 230 | 240 |
| CGELKEGDDG | GIFPKDGSGD | SHPDFPEDAD | IDLKDVDKIL | LITEDLKNIG | NTFFKSQNWE |
| 250 | 260 | 270 | 280 | 290 | 300 |
| MAIKKYAEVL | RYVDSSKAVI | ETADRAKLQP | IALSCVLNIG | ACKLKMSNWQ | GAIDSCLEAL |
| 310 | 320 | 330 | 340 | 350 | 360 |
| ELDPSNTKAL | YRRAQGWQGL | KEYDQALADL | KKAQGIAPED | KAIQAELLKV | KQKIKAQKDK |
| EKAVYAKMFA |