P56856
Gene name |
CLDN18 (UNQ778/PRO1572) |
Protein name |
Claudin-18 |
Names |
|
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:51208 |
EC number |
|
Protein Class |
|
Descriptions
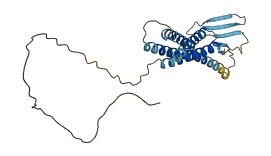
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for P56856
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-P56856-F1 | Predicted | AlphaFoldDB |
209 variants for P56856
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA354656146 rs1295314490 |
2 | S>P | No |
ClinGen gnomAD |
|
|
rs1559804259 CA354656158 |
4 | T>A | No |
ClinGen Ensembl |
|
|
CA2634359 rs775529414 |
6 | C>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs775529414 CA354656170 |
6 | C>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1329552872 CA354656171 |
6 | C>Y | No |
ClinGen gnomAD |
|
|
rs760479633 CA2634360 |
7 | Q>K | No |
ClinGen ExAC TOPMed |
|
|
CA2634361 rs764171839 |
8 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA83859141 rs958268174 |
8 | V>M | No |
ClinGen Ensembl |
|
|
rs776623998 CA2634362 |
9 | V>A | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 9 | V>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA2634363 rs761875755 |
10 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA354656196 rs1320406847 |
10 | A>V | No |
ClinGen gnomAD |
|
|
rs765498189 CA2634364 |
12 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs750585890 CA2634365 |
15 | I>L | No |
ClinGen ExAC gnomAD |
|
|
rs750585890 CA354656221 |
15 | I>V | No |
ClinGen ExAC gnomAD |
|
|
rs373852186 CA2634367 |
16 | L>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA2634368 rs752124309 |
17 | G>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
COSM1726259 CA2634370 rs781764259 |
20 | G>S | liver [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs1167620357 CA354656254 |
21 | C>G | No |
ClinGen TOPMed |
|
|
CA354656256 rs1460736707 |
21 | C>S | No |
ClinGen TOPMed |
|
|
CA2634372 rs748868334 |
23 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
| TCGA novel | 23 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA354656288 rs1443429734 |
26 | G>E | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
CA2634377 rs771924320 |
26 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 28 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA83859234 rs866539095 COSM1693504 |
28 | D>N | skin [Cosmic] | No |
ClinGen cosmic curated Ensembl |
|
CA354656326 rs1377403248 |
31 | S>N | No |
ClinGen gnomAD |
|
|
rs1398347939 CA354656336 |
32 | T>I | No |
ClinGen gnomAD |
|
|
rs1237172779 CA354656331 |
32 | T>P | No |
ClinGen TOPMed |
|
|
CA354656339 rs1339353667 |
33 | Q>* | No |
ClinGen gnomAD |
|
|
CA354656345 rs1216177690 |
34 | D>Y | No |
ClinGen gnomAD |
|
|
CA354656366 rs1208960210 |
37 | D>N | No |
ClinGen gnomAD |
|
|
rs753511405 CA83859279 |
38 | N>D | No |
ClinGen Ensembl |
|
|
rs376378448 CA2634382 |
39 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA83859286 rs933221408 |
40 | V>I | No |
ClinGen TOPMed |
|
|
CA354656405 rs1357156860 |
43 | V>E | No |
ClinGen TOPMed |
|
|
rs201678067 CA2634384 |
43 | V>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs371070256 CA2634386 |
44 | F>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1410791007 CA354656417 |
45 | Q>* | No |
ClinGen gnomAD |
|
|
rs763032242 CA2634387 |
47 | E>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs763032242 CA354656431 |
47 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA83859334 rs1054052863 |
48 | G>E | No |
ClinGen TOPMed |
|
|
CA2634388 rs766775832 |
48 | G>R | No |
ClinGen ExAC gnomAD |
|
|
CA2634389 rs374173675 |
50 | W>R | No |
ClinGen ESP ExAC gnomAD |
|
|
rs759969828 CA354656458 |
51 | R>K | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs768188619 CA2634391 |
51 | R>S | No |
ClinGen ExAC TOPMed |
|
|
CA2634390 rs759969828 |
51 | R>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs753226794 CA2634393 |
52 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1397615423 CA354656466 |
52 | S>R | No |
ClinGen gnomAD |
|
|
CA2634394 rs756859479 |
53 | C>R | No |
ClinGen ExAC gnomAD |
|
|
CA354656475 rs1218344613 COSM291861 |
54 | V>M | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
CA2634396 rs375872728 |
55 | R>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs375872728 CA2634397 |
55 | R>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA2634398 rs200350564 |
56 | Q>E | No |
ClinGen 1000Genomes ExAC |
|
|
rs912287789 CA83859404 |
56 | Q>H | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs1285265915 CA354656494 |
57 | S>C | No |
ClinGen gnomAD |
|
|
rs1487242183 CA354656508 |
59 | G>D | No |
ClinGen TOPMed gnomAD |
|
|
rs939773412 CA83859408 |
59 | G>S | No |
ClinGen Ensembl |
|
|
CA2634399 rs374110052 |
61 | T>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA2634400 rs768414784 |
62 | E>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs781145268 CA2634401 |
65 | P>T | No |
ClinGen ExAC |
|
| TCGA novel | 66 | Y>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs769881298 CA2634403 |
66 | Y>D | No |
ClinGen ExAC gnomAD |
|
|
CA354656566 rs1174601183 |
68 | T>P | No |
ClinGen gnomAD |
|
|
CA354656594 rs1360263884 |
72 | L>R | No |
ClinGen gnomAD |
|
|
CA83859440 rs906212531 |
72 | L>V | No |
ClinGen TOPMed |
|
|
rs372756802 CA2634406 |
73 | P>S | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1169705902 CA354657338 |
75 | M>T | No |
ClinGen TOPMed |
|
|
rs746038647 CA2634428 |
78 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2634430 rs775929081 |
79 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA2634431 rs761116930 COSM1419400 |
80 | R>* | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
CA2634432 COSM1718423 rs764565705 |
80 | R>Q | Variant assessed as Somatic; 0.0 impact. NS [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA gnomAD |
|
CA83866874 rs949699149 |
83 | M>I | No |
ClinGen TOPMed gnomAD |
|
|
CA2634436 rs139920646 |
85 | V>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA2634435 rs558186375 |
85 | V>I | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs767157044 CA2634438 |
87 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs114998965 CA2634439 |
88 | V>I | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA2634442 rs749210958 |
92 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs777615642 CA2634441 |
92 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs779079104 CA2634444 |
94 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1445818415 CA354657456 |
96 | V>L | No |
ClinGen gnomAD |
|
|
CA83866920 rs1051145533 |
97 | S>C | No |
ClinGen gnomAD |
|
|
rs746093722 CA2634445 |
98 | I>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs746093722 CA83866926 |
98 | I>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA354657478 rs1201528217 |
100 | A>T | No |
ClinGen Ensembl |
|
|
CA2634446 rs369712344 |
105 | R>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs200466463 COSM581915 CA2634447 |
105 | R>H | lung [Cosmic] | No |
ClinGen cosmic curated ESP ExAC TOPMed gnomAD |
|
CA354657515 rs200466463 |
105 | R>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1405432106 CA354657516 |
106 | I>L | No |
ClinGen TOPMed |
|
|
rs1559807415 CA354657520 |
106 | I>T | No |
ClinGen Ensembl |
|
|
CA2634448 rs747380065 |
109 | M>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA354657537 rs1337643624 |
109 | M>L | No |
ClinGen gnomAD |
|
|
CA2634449 rs769032958 |
110 | E>G | No |
ClinGen ExAC gnomAD |
|
|
rs1004206091 CA83866951 |
110 | E>K | No |
ClinGen Ensembl |
|
|
rs1186121523 CA354657564 |
112 | S>F | No |
ClinGen gnomAD |
|
|
rs762329918 CA2634451 |
113 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2634453 rs773920904 |
115 | A>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2634454 rs759037089 |
116 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA83866996 rs529685225 |
121 | S>F | No |
ClinGen Ensembl |
|
|
rs752318671 CA2634456 |
122 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1412484800 CA354657637 |
124 | M>T | No |
ClinGen gnomAD |
|
|
CA354657651 rs1314652651 |
126 | I>V | No |
ClinGen gnomAD |
|
|
CA354657684 rs771022353 |
129 | G>D | No |
ClinGen gnomAD |
|
|
CA83867365 rs771022353 |
129 | G>V | No |
ClinGen gnomAD |
|
|
CA2634472 rs149872077 |
132 | A>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs113915562 CA2634473 |
133 | I>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA2634474 rs776936834 |
134 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA354657720 rs1232586228 |
135 | G>A | No |
ClinGen gnomAD |
|
|
CA354657719 rs1232586228 |
135 | G>E | No |
ClinGen gnomAD |
|
|
rs1349038259 CA354657723 |
136 | V>M | No |
ClinGen gnomAD |
|
|
rs753734770 CA2634476 |
138 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs1486564137 CA354657747 |
140 | A>T | No |
ClinGen gnomAD |
|
|
rs765312866 CA2634478 |
141 | N>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs758581460 CA2634480 |
142 | M>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs750354490 CA2634479 |
142 | M>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1253466990 CA354657804 |
148 | W>S | No |
ClinGen gnomAD |
|
|
VAR_033775 CA2634481 rs17204075 |
149 | M>L | No |
ClinGen UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
CA354657822 rs1156796188 |
150 | S>F | No |
ClinGen gnomAD |
|
|
CA354657818 rs1328161970 |
150 | S>P | No |
ClinGen TOPMed |
|
|
rs1365403895 CA354657829 |
152 | A>T | No |
ClinGen gnomAD |
|
|
rs1455443408 CA354657848 |
154 | M>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1455443408 CA354657847 |
154 | M>T | No |
ClinGen TOPMed gnomAD |
|
|
CA2634482 rs751738961 |
155 | Y>H | No |
ClinGen ExAC gnomAD |
|
|
CA2634483 rs755158124 |
156 | T>A | No |
ClinGen ExAC gnomAD |
|
|
rs1322871870 CA354657866 |
157 | G>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs748597305 CA2634485 |
157 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2634486 rs770118215 |
158 | M>L | No |
ClinGen ExAC gnomAD |
|
|
CA2634487 rs147117084 |
159 | G>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs147117084 CA354657881 |
159 | G>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA2634488 COSM1693505 rs574049183 |
160 | G>E | skin [Cosmic] | No |
ClinGen cosmic curated 1000Genomes ExAC gnomAD |
|
CA2634489 rs771584128 |
162 | V>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA354657903 rs1240359260 |
163 | Q>* | No |
ClinGen gnomAD |
|
|
CA354657907 rs1457977965 |
163 | Q>H | No |
ClinGen TOPMed |
|
|
rs543360704 CA2634490 |
166 | Q>* | No |
ClinGen 1000Genomes ExAC |
|
|
rs752826625 CA2634503 |
168 | R>S | No |
ClinGen ExAC |
|
|
CA2634492 rs768411693 |
168 | R>T | No |
ClinGen ExAC gnomAD |
|
|
rs1378543153 CA354658351 |
173 | A>T | No |
ClinGen Ensembl |
|
|
rs756497056 CA2634504 |
173 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA83869971 rs866957585 |
174 | A>D | No |
ClinGen Ensembl |
|
|
CA354658361 rs1255227498 |
174 | A>T | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 175 | L>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1474284804 CA354658378 |
176 | F>L | No |
ClinGen gnomAD |
|
|
CA2634507 rs757829492 |
177 | V>M | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1428181422 CA354658399 |
178 | G>S | No |
ClinGen gnomAD |
|
|
CA354658431 rs1356705095 |
181 | A>T | No |
ClinGen gnomAD |
|
|
rs1340696645 CA354658463 |
184 | L>F | No |
ClinGen TOPMed |
|
|
rs1335744033 CA354658467 |
184 | L>H | No |
ClinGen TOPMed |
|
|
rs776377104 CA2634511 |
186 | L>P | No |
ClinGen ExAC gnomAD |
|
|
rs768017889 CA2634510 |
186 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2634513 rs538221100 |
189 | G>D | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs201345180 CA2634512 |
189 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs538221100 CA354658513 |
189 | G>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs773070571 CA2634514 |
192 | M>I | No |
ClinGen ExAC gnomAD |
|
|
CA354658537 rs1212499207 |
192 | M>K | No |
ClinGen TOPMed gnomAD |
|
|
rs370938675 CA83870011 |
193 | C>G | No |
ClinGen ESP TOPMed |
|
|
CA2634516 rs138443095 |
195 | A>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA354658579 rs1278131062 |
195 | A>V | No |
ClinGen gnomAD |
|
|
rs143363724 CA2634518 |
197 | R>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs574352940 CA83870018 |
197 | R>W | No |
ClinGen gnomAD |
|
|
CA354658602 rs1185014224 |
198 | G>S | No |
ClinGen gnomAD |
|
|
CA2634519 rs767450889 |
200 | A>E | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 201 | P>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 203 | E>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs200763024 CA83870035 |
204 | T>A | No |
ClinGen 1000Genomes gnomAD |
|
|
rs756262218 CA2634521 |
205 | N>D | No |
ClinGen ExAC gnomAD |
|
|
rs868800887 CA83870045 |
205 | N>S | No |
ClinGen Ensembl |
|
|
CA2634535 rs180927693 |
209 | V>I | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1559809017 CA354658751 |
210 | S>A | No |
ClinGen Ensembl |
|
|
CA354658768 rs1271367873 |
212 | H>D | No |
ClinGen TOPMed |
|
|
rs376205087 CA83870485 |
212 | H>R | No |
ClinGen ESP |
|
|
rs1160721387 CA354658784 COSM1038959 |
213 | A>T | Variant assessed as Somatic; 0.0 impact. endometrium [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated NCI-TCGA TOPMed gnomAD |
|
rs919906363 CA83870511 |
218 | V>F | No |
ClinGen Ensembl |
|
|
rs764350012 CA2634539 |
220 | Y>C | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs754026762 CA354658914 |
221 | K>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2634540 rs754026762 |
221 | K>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1441280441 CA354658924 |
221 | K>N | No |
ClinGen TOPMed gnomAD |
|
|
CA2634541 rs757669567 |
223 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA2634542 rs765470182 |
224 | G>A | No |
ClinGen ExAC gnomAD |
|
|
CA354658998 rs1225377853 |
227 | A>T | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs375252888 CA2634543 |
230 | G>A | No |
ClinGen ESP ExAC gnomAD |
|
|
rs1213313296 CA354659080 |
232 | G>A | No |
ClinGen gnomAD |
|
|
rs1213313296 CA354659079 |
232 | G>E | No |
ClinGen gnomAD |
|
|
rs758762263 CA2634544 |
234 | N>D | No |
ClinGen ExAC gnomAD |
|
|
CA354659128 rs1194599199 |
235 | T>I | No |
ClinGen gnomAD |
|
|
CA354659124 rs1194599199 |
235 | T>N | No |
ClinGen gnomAD |
|
|
rs1469089330 CA354659152 |
237 | N>H | No |
ClinGen gnomAD |
|
|
CA354659161 rs949540806 |
237 | N>K | No |
ClinGen TOPMed |
|
|
CA2634545 rs780698250 |
240 | I>L | No |
ClinGen ExAC gnomAD |
|
|
CA354659206 rs1408151519 |
240 | I>T | No |
ClinGen gnomAD |
|
|
rs567940448 CA2634547 |
241 | Y>* | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs141484279 CA2634548 |
242 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA TOPMed gnomAD |
|
CA2634549 rs376386414 |
243 | G>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA83870582 rs971943909 |
244 | G>V | No |
ClinGen TOPMed |
|
|
rs765684908 CA2634550 |
246 | R>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs778506065 CA2634551 |
246 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1053286810 CA83870596 |
250 | E>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
CA2634553 rs771962732 |
250 | E>V | No |
ClinGen ExAC gnomAD |
|
|
CA2634556 rs775385710 |
251 | V>I | No |
ClinGen ExAC |
|
|
CA2634555 rs775385710 |
251 | V>L | No |
ClinGen ExAC |
|
|
rs556733884 CA83870610 |
254 | Y>F | No |
ClinGen 1000Genomes |
|
|
rs768680816 CA2634558 |
254 | Y>H | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 255 | P>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA354659396 rs1356063337 |
255 | P>L | No |
ClinGen gnomAD |
|
|
rs761882973 CA2634560 |
257 | K>Q | No |
ClinGen ExAC gnomAD |
|
|
CA2634561 rs138222227 |
257 | K>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1436417931 CA354659409 |
258 | H>N | No |
ClinGen gnomAD |
|
|
CA2634563 rs763361247 |
259 | D>N | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs763361247 CA354659418 |
259 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
rs752075988 CA2634565 |
261 | V>L | No |
ClinGen ExAC gnomAD |
No associated diseases with P56856
4 regional properties for P56856
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Neurotransmitter-gated ion-channel transmembrane domain | 242 - 355 | IPR006029-1 |
| domain | Neurotransmitter-gated ion-channel transmembrane domain | 370 - 431 | IPR006029-2 |
| domain | Neurotransmitter-gated ion-channel ligand-binding domain | 33 - 234 | IPR006202 |
| conserved_site | Neurotransmitter-gated ion-channel, conserved site | 155 - 169 | IPR018000 |
3 GO annotations of cellular component
| Name | Definition |
|---|---|
| bicellular tight junction | An occluding cell-cell junction that is composed of a branching network of sealing strands that completely encircles the apical end of each cell in an epithelial sheet; the outer leaflets of the two interacting plasma membranes are seen to be tightly apposed where sealing strands are present. Each sealing strand is composed of a long row of transmembrane adhesion proteins embedded in each of the two interacting plasma membranes. |
| integral component of membrane | The component of a membrane consisting of the gene products and protein complexes having at least some part of their peptide sequence embedded in the hydrophobic region of the membrane. |
| plasma membrane | The membrane surrounding a cell that separates the cell from its external environment. It consists of a phospholipid bilayer and associated proteins. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| identical protein binding | Binding to an identical protein or proteins. |
| structural molecule activity | The action of a molecule that contributes to the structural integrity of a complex or its assembly within or outside a cell. |
10 GO annotations of biological process
| Name | Definition |
|---|---|
| bicellular tight junction assembly | The aggregation, arrangement and bonding together of a set of components to form a tight junction, an occluding cell-cell junction that is composed of a branching network of sealing strands that completely encircles the apical end of each cell in an epithelial sheet. |
| calcium-independent cell-cell adhesion via plasma membrane cell-adhesion molecules | The attachment of one cell to another cell via adhesion molecules that do not require the presence of calcium for the interaction. |
| cell adhesion | The attachment of a cell, either to another cell or to an underlying substrate such as the extracellular matrix, via cell adhesion molecules. |
| digestive tract development | The process whose specific outcome is the progression of the digestive tract over time, from its formation to the mature structure. The digestive tract is the anatomical structure through which food passes and is processed. |
| negative regulation of bone resorption | Any process that stops, prevents, or reduces the frequency, rate or extent of bone resorption. |
| negative regulation of osteoclast development | Any process that stops, prevents or reduces the frequency, rate or extent of osteoclast development. |
| negative regulation of protein localization to nucleus | Any process that stops, prevents or reduces the frequency, rate or extent of protein localization to nucleus. |
| protein localization to nucleus | A process in which a protein transports or maintains the localization of another protein to the nucleus. |
| response to ethanol | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of an ethanol stimulus. |
| TNFSF11-mediated signaling pathway | The series of molecular signals initiated by the binding of tumor necrosis factor ligand superfamily member 11 (TNFSF11) to its receptor on the surface of a target cell, and ending with the regulation of a downstream cellular process, e.g. transcription. |
6 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| Q0VCN0 | CLDN18 | Claudin-18 | Bos taurus (Bovine) | PR |
| Q9Y5I7 | CLDN16 | Claudin-16 | Homo sapiens (Human) | PR |
| O95832 | CLDN1 | Claudin-1 | Homo sapiens (Human) | PR |
| O95484 | CLDN9 | Claudin-9 | Homo sapiens (Human) | PR |
| P56857 | Cldn18 | Claudin-18 | Mus musculus (Mouse) | PR |
| Q9NGJ7 | clc-5 | Clc-like protein 5 | Caenorhabditis elegans | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MSTTTCQVVA | FLLSILGLAG | CIAATGMDMW | STQDLYDNPV | TSVFQYEGLW | RSCVRQSSGF |
| 70 | 80 | 90 | 100 | 110 | 120 |
| TECRPYFTIL | GLPAMLQAVR | ALMIVGIVLG | AIGLLVSIFA | LKCIRIGSME | DSAKANMTLT |
| 130 | 140 | 150 | 160 | 170 | 180 |
| SGIMFIVSGL | CAIAGVSVFA | NMLVTNFWMS | TANMYTGMGG | MVQTVQTRYT | FGAALFVGWV |
| 190 | 200 | 210 | 220 | 230 | 240 |
| AGGLTLIGGV | MMCIACRGLA | PEETNYKAVS | YHASGHSVAY | KPGGFKASTG | FGSNTKNKKI |
| 250 | 260 | ||||
| YDGGARTEDE | VQSYPSKHDY | V |