P54274
Gene name |
TERF1 (PIN2, TRBF1, TRF, TRF1) |
Protein name |
Telomeric repeat-binding factor 1 |
Names |
NIMA-interacting protein 2, TTAGGG repeat-binding factor 1, Telomeric protein Pin2/TRF1 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:7013 |
EC number |
|
Protein Class |
|
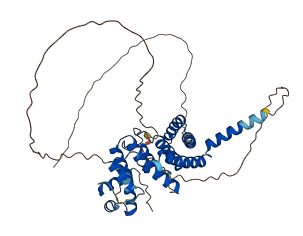
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
18 structures for P54274
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 1BA5 | NMR | - | A | 378-430 | PDB |
| 1H6O | X-ray | 290 A | A | 62-265 | PDB |
| 1ITY | NMR | - | A | 371-439 | PDB |
| 1IV6 | NMR | - | A | 371-439 | PDB |
| 1W0T | X-ray | 200 A | A/B | 379-431 | PDB |
| 3BQO | X-ray | 200 A | A | 58-268 | PDB |
| 3L82 | X-ray | 240 A | A | 58-268 | PDB |
| 5HKP | X-ray | 220 A | C/D | 1-55 | PDB |
| 5WIR | X-ray | 210 A | A/B | 62-265 | PDB |
| 5XUP | X-ray | 210 A | A/B | 65-266 | PDB |
| 8F0A | EM | 260 A | a/b/c | 404-430 | PDB |
| 8F0U | EM | 310 A | a | 404-430 | PDB |
| 8F1T | EM | 1210 A | a/b/c | 404-430 | PDB |
| 8F1U | EM | 1380 A | a/b/c | 404-430 | PDB |
| 8F21 | EM | 1410 A | a/b/c | 404-430 | PDB |
| 8F26 | EM | 970 A | a | 404-430 | PDB |
| 8OX1 | EM | 270 A | L/M | 1-439 | PDB |
| AF-P54274-F1 | Predicted | AlphaFoldDB |
324 variants for P54274
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
rs756003740 CA4781847 |
2 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs201810500 CA4781848 |
2 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1008256583 CA371473940 |
3 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
rs1008256583 COSM4006966 COSM4006967 CA179278163 |
3 | E>Q | urinary_tract [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
rs772459332 CA4781850 |
5 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs374577619 CA4781849 |
5 | V>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs775882193 CA4781851 |
6 | S>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs747176197 CA4781852 |
6 | S>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371473992 rs1460074735 |
7 | S>L | No |
ClinGen TOPMed gnomAD |
|
|
rs560420585 CA4781854 |
8 | A>G | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA371473996 rs1276232415 |
8 | A>T | No |
ClinGen gnomAD |
|
|
rs560420585 CA4781855 |
8 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA371474010 rs1275326897 |
9 | A>T | No |
ClinGen gnomAD |
|
|
CA4781857 rs773615990 |
9 | A>V | No |
ClinGen ExAC gnomAD |
|
|
CA371474017 rs751228112 |
10 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1486699545 CA371474025 |
10 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs751228112 CA4781860 |
10 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA179278197 rs974794290 |
11 | S>N | No |
ClinGen gnomAD |
|
|
rs767125396 CA4781862 |
12 | P>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA179278230 rs767125396 |
12 | P>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371474051 rs754522241 |
12 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs754522241 CA4781861 |
12 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201438704 CA4781863 |
13 | R>G | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1375446621 CA371474085 |
15 | C>R | No |
ClinGen gnomAD |
|
|
CA371474089 rs1436053225 |
15 | C>Y | No |
ClinGen gnomAD |
|
|
CA4781865 rs777817409 |
16 | A>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4781868 rs377699337 |
17 | D>A | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA4781871 rs781389776 CA371474119 |
17 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4781869 rs377699337 |
17 | D>G | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA371474113 rs571219353 |
17 | D>H | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA4781867 rs571219353 |
17 | D>N | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs377699337 CA4781870 |
17 | D>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA179278303 rs571219353 |
17 | D>Y | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs748154619 CA371474122 |
18 | G>C | No |
ClinGen ExAC gnomAD |
|
|
rs748154619 CA4781872 |
18 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA4781873 rs769878289 |
19 | R>G | Variant assessed as Somatic; 4.654e-05 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs1285455128 CA371474144 |
19 | R>S | No |
ClinGen TOPMed gnomAD |
|
|
rs941755806 CA179278343 |
19 | R>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1164249959 CA371474162 |
20 | D>E | No |
ClinGen TOPMed |
|
|
rs1448063146 CA371474158 |
20 | D>G | No |
ClinGen gnomAD |
|
|
rs912506446 CA179278351 |
20 | D>N | No |
ClinGen Ensembl |
|
|
rs370999354 CA4781877 |
21 | A>G | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA4781874 rs773732535 |
21 | A>S | No |
ClinGen ExAC gnomAD |
|
|
rs773732535 CA4781875 |
21 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs370999354 CA4781876 |
21 | A>V | Variant assessed as Somatic; 4.652e-05 impact. [NCI-TCGA] | No |
ClinGen 1000Genomes ESP ExAC NCI-TCGA TOPMed gnomAD |
|
rs1192550531 CA371474191 |
23 | P>T | No |
ClinGen gnomAD |
|
|
rs1455164054 CA371474204 |
24 | T>P | No |
ClinGen gnomAD |
|
|
CA4781881 rs760130068 |
25 | E>A | No |
ClinGen ExAC gnomAD |
|
|
CA371474211 rs1156271324 |
25 | E>K | No |
ClinGen gnomAD |
|
|
CA371474233 rs1320213216 |
26 | E>G | No |
ClinGen gnomAD |
|
|
rs763644823 CA4781882 |
26 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371474258 rs919572139 |
27 | Q>P | No |
ClinGen TOPMed gnomAD |
|
|
CA179278408 rs919572139 |
27 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA4781884 rs757192129 |
30 | E>K | No |
ClinGen ExAC gnomAD |
|
|
rs1212424094 CA371474353 |
33 | R>G | No |
ClinGen TOPMed |
|
| TCGA novel | 33 | R>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs750169709 CA4781886 |
33 | R>T | No |
ClinGen ExAC gnomAD |
|
|
CA4781887 rs755276399 |
36 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA371474436 rs1288500571 |
37 | E>K | No |
ClinGen TOPMed |
|
|
rs777764676 CA4781891 |
41 | C>R | No |
ClinGen ExAC gnomAD |
|
|
CA4781892 rs749862674 |
44 | L>P | No |
ClinGen ExAC gnomAD |
|
|
rs1276344054 CA371474590 |
45 | L>F | No |
ClinGen TOPMed |
|
|
rs894879967 CA179278488 |
45 | L>P | No |
ClinGen Ensembl |
|
|
CA4781894 rs373985315 |
46 | E>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs759792293 CA4781895 |
51 | V>M | No |
ClinGen ExAC gnomAD |
|
|
rs554864170 CA4781896 |
53 | A>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA4781898 rs760314774 |
54 | P>L | No |
ClinGen ExAC gnomAD |
|
|
rs775024422 CA4781897 |
54 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs1444837457 CA371474737 |
55 | E>K | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs1444484041 CA371474783 |
56 | E>D | No |
ClinGen gnomAD |
|
|
CA371474776 rs1336363030 |
56 | E>G | No |
ClinGen gnomAD |
|
|
rs753391990 CA4781906 |
59 | E>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs761898094 CA4781907 |
61 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4781908 rs765243417 |
62 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371474904 rs750271429 |
63 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA4781909 rs750271429 |
63 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
rs201464789 CA371474936 |
64 | A>G | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
CA4781910 rs758151093 |
64 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA179278556 rs201464789 |
64 | A>V | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
CA179278581 rs775756503 |
65 | G>V | No |
ClinGen Ensembl |
|
|
CA371475009 rs1165654140 |
69 | E>Q | No |
ClinGen gnomAD |
|
|
CA4781916 rs777889745 |
70 | A>D | No |
ClinGen ExAC gnomAD |
|
|
CA4781915 rs756327332 |
70 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4781917 rs749350509 |
71 | E>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
| TCGA novel | 71 | E>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1332247257 CA371475081 |
72 | A>V | No |
ClinGen gnomAD |
|
| TCGA novel | 74 | A>T | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs757804917 CA4781918 |
76 | G>S | No |
ClinGen ExAC gnomAD |
|
|
CA371475167 rs1227194945 |
78 | M>V | No |
ClinGen gnomAD |
|
|
rs746332601 CA4781920 |
79 | L>R | No |
ClinGen ExAC |
|
| TCGA novel | 80 | D>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs891407231 CA179278634 |
80 | D>N | No |
ClinGen TOPMed |
|
|
CA371475243 rs772332822 |
81 | F>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371475255 rs1197247179 |
82 | L>H | No |
ClinGen gnomAD |
|
|
CA4781923 rs746722487 |
84 | L>F | No |
ClinGen ExAC gnomAD |
|
|
CA371475377 rs1192159098 |
89 | A>T | No |
ClinGen gnomAD |
|
|
CA179278667 rs999758009 |
91 | R>P | No |
ClinGen Ensembl |
|
|
rs1171106607 CA371475427 |
91 | R>S | No |
ClinGen gnomAD |
|
|
rs761374911 CA4781927 |
94 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1374854675 CA371475461 |
94 | R>S | No |
ClinGen gnomAD |
|
|
rs1359154641 CA371475478 |
95 | S>C | No |
ClinGen gnomAD |
|
|
rs762882340 CA4781930 |
96 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs893839558 CA179278686 |
101 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
CA371475562 rs1346453097 |
102 | R>G | No |
ClinGen gnomAD |
|
|
rs1346453097 CA371475561 |
102 | R>S | No |
ClinGen gnomAD |
|
|
rs756380562 CA4781933 |
103 | N>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs374169616 CA179278707 |
103 | N>S | No |
ClinGen TOPMed |
|
|
rs200166029 CA4781935 |
104 | S>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1430087208 CA371475636 |
106 | E>A | No |
ClinGen gnomAD |
|
|
rs1191932524 CA371475641 |
107 | A>T | No |
ClinGen gnomAD |
|
|
COSM751831 CA371476568 rs1312159913 COSM751830 |
108 | I>V | lung [Cosmic] | No |
ClinGen cosmic curated TOPMed gnomAD |
|
rs747874839 CA4781967 |
110 | H>R | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 114 | S>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA4781968 rs769472643 |
118 | C>G | No |
ClinGen ExAC gnomAD |
|
|
CA179281582 rs1030362778 |
119 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
CA4781972 rs770304702 |
121 | R>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs774290316 CA4781973 |
122 | T>M | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs375680818 CA4781975 |
124 | Y>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs375680818 CA4781976 |
124 | Y>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1486407144 CA371476792 |
125 | I>T | No |
ClinGen gnomAD |
|
|
rs762001700 CA4781977 |
125 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1259659354 CA371476804 |
126 | C>Y | No |
ClinGen TOPMed |
|
|
CA4781978 rs765477917 |
127 | Q>L | No |
ClinGen ExAC gnomAD |
|
|
rs908519269 CA179281610 |
128 | F>L | No |
ClinGen Ensembl |
|
|
rs750510415 CA4781979 |
130 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA4781980 rs763125104 |
130 | T>I | No |
ClinGen ExAC gnomAD |
|
|
CA179281623 rs962670320 |
134 | A>E | No |
ClinGen Ensembl |
|
|
CA4781982 rs371936856 |
134 | A>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA4781981 rs371936856 |
134 | A>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs755536594 CA4781983 |
137 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA371478148 rs1563459421 |
140 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen Ensembl NCI-TCGA |
|
CA371478164 rs1440363020 |
141 | Q>H | No |
ClinGen TOPMed gnomAD |
|
|
CA4781999 rs763028309 |
144 | N>S | No |
ClinGen ExAC gnomAD |
|
|
rs1332859982 CA371478227 |
145 | D>E | No |
ClinGen gnomAD |
|
|
CA4782000 rs766633252 |
147 | R>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1356242448 CA371478253 |
147 | R>Q | No |
ClinGen TOPMed |
|
|
CA4782003 rs768104625 |
150 | P>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4782004 rs372325146 |
152 | E>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA371478338 rs1436620878 |
153 | S>* | No |
ClinGen TOPMed |
|
|
rs1276094252 CA371478332 |
153 | S>T | No |
ClinGen TOPMed |
|
|
CA4782006 rs764304266 |
154 | A>G | No |
ClinGen ExAC gnomAD |
|
|
CA371478345 rs1452794461 |
154 | A>P | No |
ClinGen gnomAD |
|
|
CA371478350 rs764304266 |
154 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs753528562 CA4782008 |
159 | G>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4782007 rs753528562 |
159 | G>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs745362910 CA4782010 |
161 | I>T | No |
ClinGen ExAC gnomAD |
|
|
CA4782009 rs778456254 |
161 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA4782011 rs199678997 |
162 | E>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371478489 rs1360851634 |
164 | E>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
rs779999988 CA4782012 |
167 | K>R | No |
ClinGen ExAC gnomAD |
|
|
CA4782013 rs746873007 |
168 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA179286902 rs910994146 |
168 | L>H | No |
ClinGen TOPMed gnomAD |
|
|
CA371478550 rs746873007 |
168 | L>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs776284866 CA4782015 |
169 | H>L | No |
ClinGen ExAC |
|
|
rs1408484278 CA371478603 |
174 | N>S | No |
ClinGen TOPMed gnomAD |
|
|
CA371478625 rs1328249589 |
177 | K>R | No |
ClinGen gnomAD |
|
| TCGA novel | 180 | A>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA371478659 rs1408274753 |
180 | A>S | No |
ClinGen TOPMed |
|
|
rs1400554263 CA371478673 |
182 | A>V | No |
ClinGen gnomAD |
|
|
rs1431725842 CA371478683 |
184 | C>G | No |
ClinGen gnomAD |
|
|
COSM1700263 rs1311550307 COSM1700264 CA371478692 |
185 | M>L | skin [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs1375338189 CA371478718 |
188 | G>D | No |
ClinGen gnomAD |
|
|
rs1224720375 CA371478772 |
195 | E>D | No |
ClinGen gnomAD |
|
|
CA179287712 rs776820604 |
195 | E>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1405470587 CA371478787 |
197 | F>L | No |
ClinGen TOPMed |
|
|
CA4782035 rs754857546 |
201 | F>Y | No |
ClinGen ExAC gnomAD |
|
|
rs1342205308 CA371478817 |
202 | G>S | No |
ClinGen gnomAD |
|
|
rs781089542 CA4782036 |
203 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA371478830 rs1174154345 |
204 | P>T | No |
ClinGen TOPMed |
|
|
rs147608592 CA4782037 |
205 | N>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs147608592 CA4782038 |
205 | N>H | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
COSM1196782 rs201882345 COSM1196783 CA4782039 |
206 | S>Y | lung [Cosmic] | No |
ClinGen cosmic curated 1000Genomes ESP ExAC TOPMed gnomAD |
|
CA371479441 rs1252390809 |
209 | P>A | No |
ClinGen gnomAD |
|
|
rs752629975 CA371479473 |
210 | F>L | No |
ClinGen ExAC gnomAD |
|
|
CA4782063 rs140473975 |
212 | S>N | No |
ClinGen ESP ExAC gnomAD |
|
|
CA4782064 rs549966818 |
215 | L>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs199642410 CA179289601 |
216 | M>V | No |
ClinGen TOPMed |
|
|
CA4782065 rs746155678 |
217 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA179289607 rs373344515 |
218 | I>V | No |
ClinGen ESP |
|
|
CA4782066 rs772414283 |
220 | Q>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371479651 rs1458423889 |
220 | Q>R | No |
ClinGen gnomAD |
|
|
CA4782068 rs747030641 |
222 | D>G | No |
ClinGen ExAC gnomAD |
|
|
rs777027729 CA4782070 |
223 | T>K | No |
ClinGen ExAC gnomAD |
|
|
rs370183602 CA4782071 |
225 | H>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs547949193 CA4782072 |
226 | S>Y | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1268522469 CA371479787 |
227 | F>L | No |
ClinGen gnomAD |
|
| TCGA novel | 230 | H>Q | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA371479859 rs1257022048 |
232 | S>C | No |
ClinGen TOPMed |
|
|
rs1044876803 CA179289639 |
235 | H>Q | No |
ClinGen Ensembl |
|
|
CA4782076 rs765915995 |
236 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs1320180267 CA371479980 |
239 | K>E | No |
ClinGen gnomAD |
|
|
CA4782077 rs751181912 COSM360448 |
241 | K>N | lung [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
CA371480171 rs1324658452 |
247 | V>L | No |
ClinGen gnomAD |
|
|
rs1346401838 CA371480194 |
248 | L>P | No |
ClinGen TOPMed |
|
| TCGA novel | 248 | L>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs373606068 CA4782081 |
251 | K>R | No |
ClinGen ESP |
|
|
CA371480304 rs1348904763 |
253 | S>L | No |
ClinGen gnomAD |
|
|
rs752683283 CA4782083 |
254 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs752683283 CA4782084 |
254 | T>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs55834252 CA4782085 |
257 | M>K | No |
ClinGen ExAC gnomAD |
|
|
rs55834252 CA179289723 |
257 | M>T | No |
ClinGen ExAC gnomAD |
|
|
CA371480805 rs1393775494 |
258 | K>T | No |
ClinGen TOPMed gnomAD |
|
|
rs1345928090 CA371480969 |
260 | A>S | No |
ClinGen TOPMed |
|
|
rs748194937 COSM1228924 CA4782113 COSM1228925 |
260 | A>V | large_intestine [Cosmic] | No |
ClinGen cosmic curated ExAC TOPMed gnomAD |
|
rs1210877299 CA371480983 |
261 | A>V | No |
ClinGen gnomAD |
|
|
CA371480995 rs1238342462 |
262 | K>N | No |
ClinGen gnomAD |
|
|
rs778272685 CA4782115 |
265 | E>D | No |
ClinGen ExAC gnomAD |
|
|
CA371481031 rs1434748306 |
265 | E>G | No |
ClinGen TOPMed |
|
|
rs1183199204 CA371481073 |
268 | R>T | No |
ClinGen gnomAD |
|
|
CA4782117 rs528829977 |
272 | I>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1168661038 CA371481142 |
274 | S>F | No |
ClinGen gnomAD |
|
|
CA4782118 rs771202033 |
275 | Q>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1432715768 CA371481222 |
280 | G>S | No |
ClinGen gnomAD |
|
|
CA179291748 rs546968261 |
282 | D>G | No |
ClinGen 1000Genomes |
|
|
rs774770648 CA4782120 |
283 | V>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371481789 rs1423963835 |
285 | M>T | No |
ClinGen TOPMed |
|
|
rs558956901 CA4782121 |
286 | E>K | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs771730126 CA4782122 |
288 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA4782124 rs760297109 |
289 | A>G | No |
ClinGen ExAC gnomAD |
|
|
rs1476266060 CA371481853 |
289 | A>T | No |
ClinGen TOPMed |
|
|
CA4782125 rs763650903 |
293 | T>A | No |
ClinGen ExAC gnomAD |
|
|
CA371481940 rs1192823465 |
294 | R>K | No |
ClinGen TOPMed |
|
|
rs959071714 CA179291795 |
295 | K>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1175417685 CA371482827 |
298 | S>R | No |
ClinGen gnomAD |
|
|
rs1282237366 CA371482834 |
298 | S>R | No |
ClinGen TOPMed |
|
|
rs768286752 CA4782147 |
299 | D>E | No |
ClinGen ExAC gnomAD |
|
|
rs1554555497 CA4782145 |
299 | D>Y | No |
ClinGen Ensembl |
|
|
CA371482868 rs1472809349 |
301 | Q>* | No |
ClinGen gnomAD |
|
|
rs1161150953 CA371482889 |
302 | S>F | No |
ClinGen gnomAD |
|
|
CA4782149 rs533827129 |
303 | A>E | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
COSM354897 CA4782148 rs533827129 |
303 | A>V | lung Variant assessed as Somatic; 0.0 impact. large_intestine [Cosmic, NCI-TCGA] | No |
ClinGen cosmic curated 1000Genomes ExAC NCI-TCGA TOPMed gnomAD |
|
CA371482902 rs772982906 |
304 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4782151 rs772982906 |
304 | V>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA371482913 rs1201535999 |
305 | T>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1351688478 CA371482920 |
305 | T>I | No |
ClinGen gnomAD |
|
|
rs766103414 CA4782153 |
309 | E>Q | No |
ClinGen ExAC gnomAD |
|
|
CA371482971 rs1445490316 |
310 | G>S | No |
ClinGen TOPMed |
|
|
CA4782154 rs752919794 |
311 | T>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1053376388 CA179294737 |
312 | V>I | No |
ClinGen TOPMed gnomAD |
|
|
CA179294738 rs891688589 |
313 | S>Y | No |
ClinGen TOPMed gnomAD |
|
|
CA179296215 rs1034294837 |
317 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
CA4782182 rs761976906 |
319 | K>R | No |
ClinGen ExAC gnomAD |
|
|
rs536690082 CA179296227 |
322 | F>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1014284097 CA179296229 |
324 | S>P | No |
ClinGen gnomAD |
|
|
CA371483818 rs1432534131 |
325 | K>N | No |
ClinGen gnomAD |
|
|
CA371483842 rs1296142489 |
327 | Q>P | No |
ClinGen TOPMed gnomAD |
|
|
CA371483843 rs1296142489 |
327 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
rs200201517 CA4782185 |
328 | H>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1230452387 CA371483874 |
329 | G>V | No |
ClinGen gnomAD |
|
|
rs780622748 CA4782186 |
330 | T>I | No |
ClinGen ExAC gnomAD |
|
|
rs961910449 CA179296245 |
332 | Q>R | No |
ClinGen TOPMed |
|
|
CA4782187 rs147786410 |
334 | D>E | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
| TCGA novel | 334 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1280545423 CA371483945 |
335 | L>F | No |
ClinGen gnomAD |
|
|
rs1188174304 CA371483955 |
336 | N>H | No |
ClinGen TOPMed gnomAD |
|
|
CA4782189 rs754719025 |
336 | N>S | No |
ClinGen ExAC gnomAD |
|
|
rs1451436045 CA371484016 |
340 | R>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1197323769 CA371484017 |
340 | R>K | No |
ClinGen gnomAD |
|
|
CA371484027 rs1377530139 |
341 | R>G | No |
ClinGen gnomAD |
|
|
CA4782191 rs780918070 |
342 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA4782190 rs780918070 |
342 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs777142237 CA371484050 |
343 | G>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs777142237 CA179296297 |
343 | G>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs777142237 CA4782193 |
343 | G>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA179296307 rs1030219843 |
344 | T>S | No |
ClinGen TOPMed |
|
|
CA371484060 rs1322116521 |
345 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs770829605 CA4782195 |
345 | P>S | No |
ClinGen ExAC gnomAD |
|
|
rs954623608 CA179296346 |
346 | Q>L | No |
ClinGen TOPMed gnomAD |
|
|
rs767706750 CA4782209 |
347 | S>N | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 352 | K>E | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA371484465 rs1037530113 |
353 | E>G | No |
ClinGen TOPMed gnomAD |
|
|
CA179302465 rs1037530113 |
353 | E>V | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 356 | R>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA371484505 rs1214658044 |
359 | E>A | No |
ClinGen TOPMed |
|
|
CA4782212 rs777387846 |
362 | I>V | No |
ClinGen ExAC gnomAD |
|
|
CA371484531 rs1241522879 |
363 | P>T | No |
ClinGen Ensembl |
|
|
CA371484541 rs1264881321 |
364 | V>A | No |
ClinGen gnomAD |
|
|
CA371484537 rs1242887685 |
364 | V>I | No |
ClinGen TOPMed gnomAD |
|
|
rs200940062 CA4782214 |
366 | K>E | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs199829012 CA179302536 |
366 | K>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs148824563 CA4782216 |
369 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs148824563 CA371484574 |
369 | P>Q | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs767107444 CA179302545 |
369 | P>S | No |
ClinGen gnomAD |
|
|
rs771909875 CA4782218 |
370 | V>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
rs748462018 CA4782220 |
375 | H>L | No |
ClinGen ExAC gnomAD |
|
|
rs748462018 CA371484612 |
375 | H>R | No |
ClinGen ExAC gnomAD |
|
|
rs576511615 CA371484615 |
376 | R>* | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA4782221 rs576511615 |
376 | R>G | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA4782222 rs182826937 |
376 | R>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs143443923 CA4782223 |
377 | A>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1387703967 CA371484626 |
378 | R>T | No |
ClinGen gnomAD |
|
|
CA4782225 rs775002331 |
381 | Q>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1305398987 CA371484648 |
381 | Q>R | No |
ClinGen gnomAD |
|
|
rs367591734 CA4782242 |
385 | W>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs774558906 CA4782243 |
389 | K>Q | No |
ClinGen ExAC gnomAD |
|
|
CA371538999 rs1310999294 |
392 | R>I | No |
ClinGen TOPMed gnomAD |
|
|
rs1257013963 CA371539006 |
393 | S>C | No |
ClinGen gnomAD |
|
|
CA4782245 rs772422280 |
395 | V>M | No |
ClinGen ExAC gnomAD |
|
|
CA371539029 rs1448380465 |
397 | K>T | No |
ClinGen gnomAD |
|
|
CA4782247 rs760966818 |
398 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
CA4782248 rs371272884 |
400 | E>Q | No |
ClinGen ESP ExAC gnomAD |
|
|
CA371539057 rs1343560036 |
401 | G>E | No |
ClinGen TOPMed |
|
| TCGA novel | 401 | G>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs145124356 CA179632414 |
403 | W>* | No |
ClinGen ESP TOPMed |
|
|
CA4782249 rs768819687 |
406 | I>H | No |
ClinGen ExAC |
|
|
rs138974817 CA179632415 |
406 | I>M | No |
ClinGen ESP gnomAD |
|
|
CA371539111 rs964367595 |
409 | H>P | No |
ClinGen TOPMed gnomAD |
|
|
rs964367595 CA179632416 |
409 | H>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1586075915 CA371539119 |
410 | Y>C | No |
ClinGen Ensembl |
|
|
CA371539133 rs1380718635 |
412 | F>V | No |
ClinGen TOPMed |
|
|
CA4782250 rs753496443 |
413 | N>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA4782251 rs761454524 |
414 | N>H | No |
ClinGen ExAC gnomAD |
|
|
rs764789271 CA4782252 |
414 | N>S | No |
ClinGen ExAC gnomAD |
|
|
CA4782253 rs749879752 |
415 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA179632417 rs990190701 |
417 | S>R | No |
ClinGen TOPMed gnomAD |
|
|
rs751466126 CA4782256 |
422 | D>E | No |
ClinGen ExAC gnomAD |
|
|
rs754732788 CA4782257 |
424 | W>R | No |
ClinGen ExAC gnomAD |
|
|
rs1372704592 CA371539235 |
427 | M>V | No |
ClinGen gnomAD |
|
|
rs4092743 CA179632419 |
430 | L>V | No |
ClinGen Ensembl |
|
|
rs771256301 CA4782260 |
434 | S>F | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
| TCGA novel | 435 | S>A | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs779169421 CA4782261 |
436 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA371539304 rs1476960498 |
437 | S>N | No |
ClinGen gnomAD |
|
|
CA4782263 rs145702999 |
438 | E>K | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
No associated diseases with P54274
5 regional properties for P54274
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | CARP motif | 206 - 243 | IPR006599-1 |
| domain | CARP motif | 244 - 278 | IPR006599-2 |
| domain | Tubulin binding cofactor C-like domain | 199 - 316 | IPR012945 |
| domain | C-CAP/cofactor C-like domain | 163 - 318 | IPR017901 |
| domain | Tubulin-specific chaperone C, N-terminal | 26 - 134 | IPR031925 |
Functions
10 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromosome, telomeric region | The end of a linear chromosome, required for the integrity and maintenance of the end. A chromosome telomere usually includes a region of telomerase-encoded repeats the length of which rarely exceeds 20 bp each and that permits the formation of a telomeric loop (T-loop). The telomeric repeat region is usually preceded by a sub-telomeric region that is gene-poor but rich in repetitive elements. Some telomeres only consist of the latter part (for eg. D. melanogaster telomeres). |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| fibrillar center | A structure found most metazoan nucleoli, but not usually found in lower eukaryotes; surrounded by the dense fibrillar component; the zone of transcription from multiple copies of the pre-rRNA genes is in the border region between these two structures. |
| nuclear body | Extra-nucleolar nuclear domains usually visualized by confocal microscopy and fluorescent antibodies to specific proteins. |
| nuclear telomere cap complex | A complex of DNA and protein located at the end of a linear chromosome in the nucleus that protects and stabilizes a linear chromosome. |
| nucleolus | A small, dense body one or more of which are present in the nucleus of eukaryotic cells. It is rich in RNA and protein, is not bounded by a limiting membrane, and is not seen during mitosis. Its prime function is the transcription of the nucleolar DNA into 45S ribosomal-precursor RNA, the processing of this RNA into 5.8S, 18S, and 28S components of ribosomal RNA, and the association of these components with 5S RNA and proteins synthesized outside the nucleolus. This association results in the formation of ribonucleoprotein precursors; these pass into the cytoplasm and mature into the 40S and 60S subunits of the ribosome. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
| shelterin complex | A nuclear telomere cap complex that is formed by the association of telomeric ssDNA- and dsDNA-binding proteins with telomeric DNA, and is involved in telomere protection and recruitment of telomerase. The complex is known to contain TERF1, TERF2, POT1, RAP1, TINF2 and ACD in mammalian cells, and Pot1, Tpz1, Rap1, Rif1, Rif2 and Taz1 in Saccharomyces. Taz1 and Rap1 (or their mammalian equivalents) form a dsDNA-binding subcomplex, Pot1 and Tpz1 form an ssDNA-binding subcomplex, and the two subcomplexes are bridged by Poz1, which acts as an effector molecule along with Ccq1. |
| spindle | The array of microtubules and associated molecules that forms between opposite poles of a eukaryotic cell during mitosis or meiosis and serves to move the duplicated chromosomes apart. |
11 GO annotations of molecular function
| Name | Definition |
|---|---|
| ankyrin repeat binding | Binding to an ankyrin repeat of a protein. Ankyrin repeats are tandemly repeated modules of about 33 amino acids; each repeat folds into a helix-loop-helix structure with a beta-hairpin/loop region projecting out from the helices at a 90-degree angle, and repeats stack to form an L-shaped structure. |
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| DNA binding, bending | The activity of binding selectively and non-covalently to and distorting the original structure of DNA, typically a straight helix, into a bend, or increasing the bend if the original structure was intrinsically bent due to its sequence. |
| double-stranded telomeric DNA binding | Binding to double-stranded telomere-associated DNA. |
| G-rich strand telomeric DNA binding | Binding to G-rich, single-stranded, telomere-associated DNA. |
| identical protein binding | Binding to an identical protein or proteins. |
| microtubule binding | Binding to a microtubule, a filament composed of tubulin monomers. |
| molecular adaptor activity | The binding activity of a molecule that brings together two or more molecules through a selective, non-covalent, often stoichiometric interaction, permitting those molecules to function in a coordinated way. |
| protein C-terminus binding | Binding to a protein C-terminus, the end of a peptide chain at which the 1-carboxyl function of a constituent amino acid is not attached in peptide linkage to another amino-acid residue. |
| protein homodimerization activity | Binding to an identical protein to form a homodimer. |
| telomeric DNA binding | Binding to a telomere, a specific structure at the end of a linear chromosome required for the integrity and maintenance of the end. |
20 GO annotations of biological process
| Name | Definition |
|---|---|
| cell division | The process resulting in division and partitioning of components of a cell to form more cells; may or may not be accompanied by the physical separation of a cell into distinct, individually membrane-bounded daughter cells. |
| meiotic telomere clustering | The cell cycle process in which the dynamic reorganization of telomeres occurs in early meiotic prophase, during which meiotic chromosome ends are gathered in a bouquet arrangement at the inner surface of the nuclear envelope proximal to the spindle pole body. This plays an important role in progression through meiosis and precedes synapsis. |
| negative regulation of DNA replication | Any process that stops, prevents, or reduces the frequency, rate or extent of DNA replication. |
| negative regulation of establishment of protein localization to telomere | Any process that stops, prevents or reduces the frequency, rate or extent of establishment of protein localization to telomere. |
| negative regulation of establishment of protein-containing complex localization to telomere | Any process that stops, prevents or reduces the frequency, rate or extent of establishment of the localization of a protein-containing macromolecular complex to a telomere. |
| negative regulation of establishment of RNA localization to telomere | Any process that stops, prevents or reduces the frequency, rate or extent of establishment of RNA localization to telomere. |
| negative regulation of exonuclease activity | Any process that stops, prevents or reduces the frequency, rate or extent of exonuclease activity. |
| negative regulation of telomerase activity | Any process that stops or reduces the activity of the enzyme telomerase, which catalyzes of the reaction: deoxynucleoside triphosphate + DNA(n) = diphosphate + DNA(n+1). |
| negative regulation of telomere maintenance via semi-conservative replication | Any process that stops, prevents, or reduces the frequency, rate or extent of the semi-conservative replication of telomeric DNA. |
| negative regulation of telomere maintenance via telomerase | Any process that stops, prevents, or reduces the frequency, rate or extent of the addition of telomeric repeats by telomerase. |
| negative regulation of telomere maintenance via telomere lengthening | Any process that stops, prevents or reduces the frequency, rate or extent of telomere maintenance via telomere lengthening. |
| negative regulation of telomeric D-loop disassembly | Any process that stops, prevents or reduces the frequency, rate or extent of telomeric D-loop disassembly. |
| positive regulation of shelterin complex assembly | Any process that activates or increases the frequency, rate or extent of shelterin complex assembly. |
| positive regulation of telomere maintenance | Any process that activates or increases the frequency, rate or extent of a process that affects and monitors the activity of telomeric proteins and the length of telomeric DNA. |
| response to xenobiotic stimulus | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a stimulus from a xenobiotic, a compound foreign to the organim exposed to it. It may be synthesized by another organism (like ampicilin) or it can be a synthetic chemical. |
| t-circle formation | A telomere maintenance process that results in the formation of a telomeric circle, or t-circle. A t-circle is an extrachromosomal duplex or single-stranded circular DNA molecule composed of t-arrays. T-circles are involved in the control of telomere length via alternative-lengthening of telomeres (ALT) pathway and telomere rapid deletion (TRD). |
| telomere capping | A process in which telomeres are protected from degradation and fusion, thereby ensuring chromosome stability by protecting the ends from both degradation and from being recognized as damaged DNA. May be mediated by specific single- or double-stranded telomeric DNA binding proteins. |
| telomere maintenance | Any process that contributes to the maintenance of proper telomeric length and structure by affecting and monitoring the activity of telomeric proteins, the length of telomeric DNA and the replication and repair of the DNA. These processes includes those that shorten, lengthen, replicate and repair the telomeric DNA sequences. |
| telomere maintenance via telomerase | The maintenance of proper telomeric length by the addition of telomeric repeats by telomerase. |
| telomeric D-loop disassembly | A telomere loop disassembly process that results in the disassembly of telomeric D-loops. A telomeric D-loop is a three-stranded DNA displacement loop that forms at the site where the telomeric 3' single-stranded DNA overhang (formed of the repeat sequence TTAGGG in mammals) is tucked back inside the double-stranded component of telomeric DNA molecule, thus forming a t-loop or telomeric-loop and protecting the chromosome terminus. |
1 homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| P70371 | Terf1 | Telomeric repeat-binding factor 1 | Mus musculus (Mouse) | PR |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAEDVSSAAP | SPRGCADGRD | ADPTEEQMAE | TERNDEEQFE | CQELLECQVQ | VGAPEEEEEE |
| 70 | 80 | 90 | 100 | 110 | 120 |
| EEDAGLVAEA | EAVAAGWMLD | FLCLSLCRAF | RDGRSEDFRR | TRNSAEAIIH | GLSSLTACQL |
| 130 | 140 | 150 | 160 | 170 | 180 |
| RTIYICQFLT | RIAAGKTLDA | QFENDERITP | LESALMIWGS | IEKEHDKLHE | EIQNLIKIQA |
| 190 | 200 | 210 | 220 | 230 | 240 |
| IAVCMENGNF | KEAEEVFERI | FGDPNSHMPF | KSKLLMIISQ | KDTFHSFFQH | FSYNHMMEKI |
| 250 | 260 | 270 | 280 | 290 | 300 |
| KSYVNYVLSE | KSSTFLMKAA | AKVVESKRTR | TITSQDKPSG | NDVEMETEAN | LDTRKSVSDK |
| 310 | 320 | 330 | 340 | 350 | 360 |
| QSAVTESSEG | TVSLLRSHKN | LFLSKLQHGT | QQQDLNKKER | RVGTPQSTKK | KKESRRATES |
| 370 | 380 | 390 | 400 | 410 | 420 |
| RIPVSKSQPV | TPEKHRARKR | QAWLWEEDKN | LRSGVRKYGE | GNWSKILLHY | KFNNRTSVML |
| 430 | |||||
| KDRWRTMKKL | KLISSDSED |