O95456
Gene name |
PSMG1 (C21LRP, DSCR2, PAC1) |
Protein name |
Proteasome assembly chaperone 1 |
Names |
PAC-1, Chromosome 21 leucine-rich protein, C21-LRP, Down syndrome critical region protein 2 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:8624 |
EC number |
|
Protein Class |
|
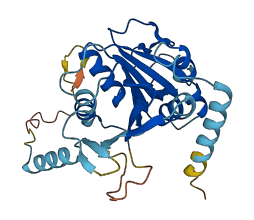
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
233 variants for O95456
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA320549862 rs866435612 |
2 | A>V | No |
ClinGen Ensembl |
|
|
CA409953130 rs1234735136 |
3 | A>G | No |
ClinGen gnomAD |
|
|
CA10026112 rs774016846 |
3 | A>S | No |
ClinGen ExAC gnomAD |
|
|
CA10026111 rs374405896 |
4 | T>M | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs762712818 CA10026110 |
5 | F>V | No |
ClinGen ExAC gnomAD |
|
|
rs773130013 CA10026109 |
6 | F>Y | No |
ClinGen ExAC gnomAD |
|
|
CA10026108 rs769699401 |
10 | V>L | No |
ClinGen ExAC gnomAD |
|
|
rs568027634 CA10026107 |
12 | A>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA10026105 rs150047855 |
13 | P>L | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA409953005 rs150047855 |
13 | P>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1239246938 CA409952998 |
14 | C>G | No |
ClinGen gnomAD |
|
|
CA409952985 rs1178582445 |
15 | R>* | No |
ClinGen TOPMed gnomAD |
|
|
CA409952987 rs1178582445 |
15 | R>G | Variant assessed as Somatic; 6.48e-05 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed gnomAD |
|
rs1456869014 CA409952980 |
15 | R>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1456869014 CA409952982 |
15 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1255278607 CA409952976 |
16 | A>T | No |
ClinGen gnomAD |
|
|
rs1249340333 CA409952926 |
19 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
rs973547342 CA320549833 |
20 | D>G | No |
ClinGen Ensembl |
|
|
rs747051823 CA10026104 |
20 | D>Y | No |
ClinGen ExAC gnomAD |
|
|
rs1230909834 CA409952858 |
24 | E>G | No |
ClinGen gnomAD |
|
|
CA409952842 rs1264515977 |
25 | E>A | No |
ClinGen gnomAD |
|
|
CA409952828 rs1401966239 |
26 | E>G | No |
ClinGen TOPMed |
|
|
rs1318204634 CA409952800 |
28 | R>Q | No |
ClinGen gnomAD |
|
|
rs940866544 CA320549800 |
31 | T>M | No |
ClinGen Ensembl |
|
|
CA320549799 rs908046069 |
32 | P>L | No |
ClinGen gnomAD |
|
|
CA409952751 rs1445942861 |
32 | P>S | No |
ClinGen gnomAD |
|
|
CA409952738 rs1390233703 |
33 | E>G | No |
ClinGen gnomAD |
|
|
rs758557571 CA10026099 |
33 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10026097 rs779138348 |
34 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA320549771 rs377036386 |
35 | R>G | No |
ClinGen ESP TOPMed |
|
|
rs1158196088 CA409952707 |
35 | R>S | No |
ClinGen gnomAD |
|
|
CA409952712 rs1380985322 |
35 | R>T | No |
ClinGen gnomAD |
|
|
CA320549729 rs1127135 |
39 | L>P | No |
ClinGen Ensembl |
|
|
CA409952641 rs1207718310 |
40 | Q>H | No |
ClinGen gnomAD |
|
|
rs1251625025 CA409952646 |
40 | Q>P | No |
ClinGen TOPMed |
|
|
rs756716291 CA10026092 |
43 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10026090 rs200000347 |
44 | K>M | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs200000347 CA10026091 |
44 | K>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA409952592 rs1280738908 |
45 | R>G | No |
ClinGen TOPMed |
|
|
CA409951964 rs1200261799 |
46 | E>K | No |
ClinGen gnomAD |
|
|
rs1318341073 CA409951949 |
47 | V>M | No |
ClinGen gnomAD |
|
|
CA409951934 rs1217019928 |
48 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs748645572 CA10026056 |
48 | R>W | No |
ClinGen ExAC gnomAD |
|
|
CA10026055 rs781746651 |
51 | R>* | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed gnomAD |
|
rs755573511 CA10026054 |
51 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA gnomAD |
|
CA409951894 rs1447461500 |
52 | R>K | No |
ClinGen gnomAD |
|
|
CA10026053 rs749882643 |
53 | Q>* | No |
ClinGen ExAC gnomAD |
|
|
CA409951881 rs1466411106 |
53 | Q>R | No |
ClinGen TOPMed gnomAD |
|
|
rs756920485 CA10026051 |
56 | T>P | No |
ClinGen ExAC gnomAD |
|
|
CA409951835 rs1175632413 |
57 | S>P | No |
ClinGen TOPMed |
|
|
rs139346791 CA320548319 |
59 | E>D | No |
ClinGen ESP TOPMed |
|
|
CA10026050 rs753499198 |
59 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA409951795 rs1471033956 |
60 | V>A | No |
ClinGen TOPMed |
|
|
rs147961251 CA320548312 |
60 | V>L | No |
ClinGen ESP |
|
|
CA10026049 rs763844375 |
61 | S>F | No |
ClinGen ExAC gnomAD |
|
|
CA409951771 rs1163282312 |
62 | L>F | No |
ClinGen gnomAD |
|
|
CA409951715 rs1344877314 |
66 | Y>* | No |
ClinGen TOPMed |
|
|
CA409951709 rs1428929555 |
67 | P>A | No |
ClinGen TOPMed |
|
|
CA409951698 rs1180445248 |
68 | C>S | No |
ClinGen gnomAD |
|
|
rs767398450 CA10026046 |
68 | C>S | No |
ClinGen ExAC gnomAD |
|
|
CA10026045 rs138957098 |
69 | S>F | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1323712341 CA409951657 |
71 | F>L | No |
ClinGen TOPMed gnomAD |
|
|
CA10026044 rs774480663 |
72 | I>T | No |
ClinGen ExAC gnomAD |
|
|
rs1043292705 CA320548295 |
72 | I>V | No |
ClinGen TOPMed |
|
|
rs139461009 CA10026043 |
74 | A>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA10026042 rs763206563 |
75 | I>M | No |
ClinGen ExAC gnomAD |
|
|
rs1354344970 CA409951608 |
75 | I>V | No |
ClinGen gnomAD |
|
|
rs1238975773 CA409951545 |
80 | V>I | No |
ClinGen gnomAD |
|
|
CA10026022 rs200021987 |
81 | A>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA10026023 rs200021987 |
81 | A>V | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1435305097 CA409951421 |
83 | L>R | No |
ClinGen gnomAD |
|
|
rs765587257 CA320547344 |
85 | S>T | No |
ClinGen Ensembl |
|
|
CA320547342 rs953515284 |
86 | F>L | No |
ClinGen TOPMed |
|
|
CA10026021 rs777122150 |
87 | V>I | No |
ClinGen ExAC gnomAD |
|
|
CA10026019 rs747517912 |
88 | M>I | No |
ClinGen ExAC gnomAD |
|
|
CA10026020 rs78317549 |
88 | M>T | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs775909905 CA10026018 |
89 | N>D | No |
ClinGen ExAC gnomAD |
|
|
CA10026017 rs187341087 |
89 | N>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA409951340 rs1377320295 |
90 | S>* | No |
ClinGen TOPMed |
|
|
rs370832635 CA10026016 |
91 | G>E | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA10026015 rs777266146 |
92 | V>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA320547311 rs1015195128 |
93 | W>C | No |
ClinGen TOPMed |
|
|
rs755701822 CA10026014 |
96 | V>F | No |
ClinGen ExAC gnomAD |
|
|
rs755701822 CA409951267 |
96 | V>I | No |
ClinGen ExAC gnomAD |
|
|
rs1190445481 CA409951253 |
97 | G>D | No |
ClinGen TOPMed gnomAD |
|
|
rs551566053 CA10026012 |
98 | C>R | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA409951237 rs1217380951 |
98 | C>W | No |
ClinGen gnomAD |
|
|
CA409951226 rs1488006578 |
99 | A>V | No |
ClinGen gnomAD |
|
|
CA10026010 rs751396324 |
100 | K>E | No |
ClinGen ExAC gnomAD |
|
|
CA409951212 rs1313366467 |
100 | K>N | No |
ClinGen gnomAD |
|
|
rs766188436 CA10026009 |
101 | L>F | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs910015439 CA409951186 |
102 | W>* | No |
ClinGen gnomAD |
|
|
rs910015439 CA320547281 |
102 | W>C | No |
ClinGen gnomAD |
|
|
CA409951197 rs1217887709 |
102 | W>R | No |
ClinGen gnomAD |
|
|
CA409951180 rs1279736473 |
103 | N>D | No |
ClinGen gnomAD |
|
|
rs758362425 CA10026008 |
104 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA409951149 rs1461057359 |
105 | W>R | No |
ClinGen TOPMed |
|
|
rs562774244 CA10026007 |
106 | C>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA10026006 rs183446739 |
106 | C>Y | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA10026004 rs777034165 |
107 | R>G | No |
ClinGen ExAC gnomAD |
|
|
rs143749424 CA10026003 |
108 | T>I | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs1468065603 CA409951094 |
109 | T>A | No |
ClinGen gnomAD |
|
|
CA409951096 rs1468065603 |
109 | T>P | No |
ClinGen gnomAD |
|
| TCGA novel | 110 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA409951059 rs1569143129 |
111 | T>I | No |
ClinGen Ensembl |
|
|
CA409951055 rs1348602777 |
112 | T>A | No |
ClinGen gnomAD |
|
|
rs780526161 CA320547236 |
113 | H>Y | No |
ClinGen Ensembl |
|
|
CA409951028 rs1186500201 |
114 | L>Q | No |
ClinGen TOPMed |
|
|
rs1290815110 CA409951012 |
116 | S>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1194672826 CA409950991 |
117 | T>I | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA gnomAD |
|
rs1477651901 CA409950968 |
119 | A>G | No |
ClinGen gnomAD |
|
|
rs1601187434 CA409950945 |
121 | C>Y | No |
ClinGen Ensembl |
|
|
rs1259739472 CA409950935 |
122 | V>L | No |
ClinGen gnomAD |
|
|
CA10026001 rs149520065 |
124 | Y>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA409950908 rs1208413855 |
124 | Y>H | No |
ClinGen gnomAD |
|
|
rs746383934 CA10025999 |
125 | H>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10026000 rs746383934 |
125 | H>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10025996 rs747781442 |
129 | N>K | No |
ClinGen ExAC gnomAD |
|
|
rs200278874 CA10025997 |
129 | N>S | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs780777266 CA10025995 |
131 | S>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs138014655 CA10025975 |
136 | Q>H | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA409950286 rs1356377477 |
136 | Q>R | No |
ClinGen TOPMed |
|
|
CA409950248 rs1291756915 |
139 | C>R | No |
ClinGen TOPMed |
|
|
CA10025973 rs200670808 |
140 | Y>C | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs776210231 CA10025972 |
141 | V>A | No |
ClinGen ExAC gnomAD |
|
|
rs1458427010 CA409950219 |
141 | V>I | No |
ClinGen gnomAD |
|
|
rs145581162 CA10025971 |
143 | E>D | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1178368013 CA409950176 |
144 | D>E | No |
ClinGen gnomAD |
|
|
CA10025970 rs746733243 |
144 | D>G | No |
ClinGen ExAC gnomAD |
|
|
CA409950184 rs1177683273 |
144 | D>N | No |
ClinGen TOPMed |
|
|
CA409950182 rs1177683273 |
144 | D>Y | No |
ClinGen TOPMed |
|
|
rs1436434533 CA409950171 |
145 | Q>E | No |
ClinGen gnomAD |
|
|
rs1247908958 CA409950163 |
145 | Q>L | No |
ClinGen gnomAD |
|
|
rs1488641517 CA409950145 |
146 | Q>H | No |
ClinGen TOPMed gnomAD |
|
|
CA409950136 rs1290360110 |
147 | Y>C | No |
ClinGen gnomAD |
|
|
CA409950125 rs1219681663 |
148 | Q>* | No |
ClinGen gnomAD |
|
|
CA10025969 rs779709634 |
151 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA10025968 rs772032936 |
152 | K>E | No |
ClinGen ExAC gnomAD |
|
|
rs754072332 CA320545645 |
154 | F>L | No |
ClinGen Ensembl |
|
|
rs775255191 CA10025948 |
155 | G>D | No |
ClinGen ExAC gnomAD |
|
|
rs899535833 CA320545631 |
161 | N>D | No |
ClinGen TOPMed |
|
|
rs771873690 CA10025947 |
162 | M>T | No |
ClinGen ExAC gnomAD |
|
|
rs745617678 CA10025946 |
163 | Q>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10025945 rs770931237 |
164 | I>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10025944 rs770931237 |
164 | I>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1352941557 CA409949903 |
165 | T>I | No |
ClinGen TOPMed |
|
|
CA10025942 rs375585989 |
166 | I>S | No |
ClinGen ESP ExAC gnomAD |
|
|
CA10025943 rs8131611 RCV000887207 VAR_054014 |
166 | I>V | No |
ClinGen ClinVar UniProt 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs1258190748 CA409949888 |
168 | T>K | No |
ClinGen gnomAD |
|
|
CA409949887 rs1258190748 |
168 | T>R | No |
ClinGen gnomAD |
|
| TCGA novel | 169 | C>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs756269433 CA10025941 |
169 | C>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10025940 rs372682958 |
170 | R>Q | Variant assessed as Somatic; 0.0 impact. [NCI-TCGA] | No |
ClinGen ESP ExAC NCI-TCGA gnomAD |
|
CA10025937 rs751864587 |
174 | D>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen ExAC NCI-TCGA TOPMed |
|
CA10025935 rs145022066 |
175 | Y>F | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA10025936 rs766787420 |
175 | Y>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA409949829 rs1418412514 |
177 | T>I | No |
ClinGen TOPMed |
|
|
CA10025934 rs750980554 |
177 | T>P | No |
ClinGen ExAC gnomAD |
|
|
CA10025931 rs370704900 |
182 | G>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1173841916 CA409949781 |
185 | P>S | No |
ClinGen gnomAD |
|
|
CA409949769 rs1466856022 |
187 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA10025929 rs767210983 |
188 | F>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1474160664 CA409949743 |
191 | A>V | No |
ClinGen gnomAD |
|
|
rs1416018464 CA409949739 |
192 | L>V | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 194 | T>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 195 | Q>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA10025928 rs759272360 |
197 | F>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10025926 rs1375980395 |
199 | D>A | No |
ClinGen TOPMed |
|
|
rs774270699 CA320545461 |
200 | S>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA10025925 rs774270699 |
200 | S>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs113955862 CA320545448 |
201 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA409949666 rs1458338456 |
202 | C>W | No |
ClinGen gnomAD |
|
|
rs773155392 CA10025922 |
203 | C>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs769653352 CA10025921 |
203 | C>Y | No |
ClinGen ExAC gnomAD |
|
|
rs748196540 CA10025920 |
204 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA409949649 rs1470018073 |
205 | L>F | No |
ClinGen TOPMed |
|
|
rs1214633979 CA409949645 |
206 | L>Q | No |
ClinGen TOPMed |
|
| TCGA novel | 207 | E>D | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1238015714 CA409949640 |
207 | E>K | No |
ClinGen TOPMed |
|
|
CA10025918 rs755180823 |
209 | P>L | No |
ClinGen ExAC gnomAD |
|
|
rs1333723523 CA409949617 |
210 | N>S | No |
ClinGen gnomAD |
|
|
rs202176293 CA10025916 |
211 | I>T | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA409949613 rs1206083719 |
211 | I>V | No |
ClinGen Ensembl |
|
|
CA10025915 rs200756272 |
212 | V>I | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA409949596 rs752793382 |
213 | H>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs970810152 CA320545325 |
214 | D>N | No |
ClinGen TOPMed gnomAD |
|
|
rs148120925 CA10025911 |
217 | A>G | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs757707960 CA10025912 |
217 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA320545305 rs879815069 |
218 | A>G | No |
ClinGen TOPMed gnomAD |
|
|
CA10025910 rs767190360 |
218 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA409949565 rs1180203920 |
219 | V>F | No |
ClinGen gnomAD |
|
|
rs768118227 CA320544612 |
221 | S>N | No |
ClinGen Ensembl |
|
|
rs1403740620 CA409949537 |
222 | Y>N | No |
ClinGen gnomAD |
|
|
CA409949497 rs1236485570 |
227 | K>E | No |
ClinGen TOPMed |
|
|
rs143701237 CA10025877 |
227 | K>N | No |
ClinGen ESP ExAC gnomAD |
|
|
CA10025876 rs746131426 |
228 | I>T | No |
ClinGen ExAC |
|
|
rs779327198 COSM3423958 CA10025875 |
229 | P>L | Variant assessed as Somatic; 0.0 impact. large_intestine [NCI-TCGA, Cosmic] | No |
ClinGen cosmic curated ExAC NCI-TCGA TOPMed gnomAD |
|
rs779327198 CA409949481 |
229 | P>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1304213656 CA409949485 |
229 | P>T | No |
ClinGen TOPMed |
|
|
rs1359542733 CA409949473 |
231 | I>V | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 233 | Y>* | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1415995312 CA409949458 |
233 | Y>C | No |
ClinGen gnomAD |
|
|
CA409949445 rs1430192678 |
235 | C>R | No |
ClinGen gnomAD |
|
|
rs756696002 CA10025871 |
237 | T>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA320544576 rs890938558 |
238 | D>G | No |
ClinGen gnomAD |
|
|
CA409949407 rs1194549531 |
240 | M>I | No |
ClinGen gnomAD |
|
|
CA409949380 rs1213399019 |
244 | L>V | No |
ClinGen TOPMed |
|
|
CA10025869 rs779492117 |
247 | V>A | No |
ClinGen ExAC gnomAD |
|
|
CA10025870 rs779492117 |
247 | V>G | No |
ClinGen ExAC gnomAD |
|
|
CA10025868 rs758066017 |
249 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA637819566 rs1428101436 |
250 | F>* | No |
ClinGen TOPMed gnomAD |
|
|
CA409949306 rs1222485756 |
255 | S>F | No |
ClinGen gnomAD |
|
|
rs1339157784 CA409949291 |
258 | S>G | No |
ClinGen Ensembl |
|
|
CA409949289 rs1029466081 |
258 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
CA320544537 rs1029466081 |
258 | S>T | No |
ClinGen TOPMed gnomAD |
|
|
CA10025867 rs556876616 |
259 | L>W | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs761548890 CA409949271 |
261 | G>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs761548890 CA10025865 |
261 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1417952964 CA409949257 |
263 | V>A | No |
ClinGen TOPMed |
|
|
rs537846197 CA10025863 |
263 | V>I | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1202537922 CA409949231 |
265 | N>S | No |
ClinGen TOPMed |
|
| TCGA novel | 267 | P>H | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 269 | S>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA409949178 rs1484223212 |
272 | I>M | No |
ClinGen gnomAD |
|
| TCGA novel | 274 | K>N | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
| TCGA novel | 275 | K>R | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs34970037 CA10025838 RCV000907532 |
276 | L>F | No |
ClinGen ClinVar 1000Genomes ESP ExAC TOPMed dbSNP gnomAD |
|
|
rs1441958551 CA409949134 |
279 | T>A | No |
ClinGen gnomAD |
|
|
CA409949094 rs766653960 |
284 | S>I | No |
ClinGen ExAC gnomAD |
|
|
CA10025837 rs766653960 |
284 | S>N | No |
ClinGen ExAC gnomAD |
|
|
CA409949090 rs1187169158 |
285 | N>D | No |
ClinGen TOPMed |
|
|
rs1195991315 CA409949087 |
285 | N>S | No |
ClinGen gnomAD |
|
|
rs763327980 CA10025836 |
286 | I>V | No |
ClinGen ExAC gnomAD |
No associated diseases with O95456
No regional properties for O95456
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for O95456 | |||
7 GO annotations of cellular component
| Name | Definition |
|---|---|
| chaperone complex | A protein complex required for the non-covalent folding or unfolding, maturation, stabilization or assembly or disassembly of macromolecular structures. Usually active during or immediately after completion of translation. Many chaperone complexes contain heat shock proteins. |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| endoplasmic reticulum | The irregular network of unit membranes, visible only by electron microscopy, that occurs in the cytoplasm of many eukaryotic cells. The membranes form a complex meshwork of tubular channels, which are often expanded into slitlike cavities called cisternae. The ER takes two forms, rough (or granular), with ribosomes adhering to the outer surface, and smooth (with no ribosomes attached). |
| Golgi apparatus | A membrane-bound cytoplasmic organelle of the endomembrane system that further processes the core oligosaccharides (e.g. N-glycans) added to proteins in the endoplasmic reticulum and packages them into membrane-bound vesicles. The Golgi apparatus operates at the intersection of the secretory, lysosomal, and endocytic pathways. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
2 GO annotations of molecular function
| Name | Definition |
|---|---|
| molecular adaptor activity | The binding activity of a molecule that brings together two or more molecules through a selective, non-covalent, often stoichiometric interaction, permitting those molecules to function in a coordinated way. |
| proteasome binding | Binding to a proteasome, a large multisubunit protein complex that catalyzes protein degradation. |
3 GO annotations of biological process
| Name | Definition |
|---|---|
| cerebellar granule cell precursor proliferation | The multiplication or reproduction of neuroblasts that will give rise to granule cells. A granule cell is a glutamatergic interneuron found in the cerebellar cortex. |
| chaperone-mediated protein complex assembly | The aggregation, arrangement and bonding together of a set of components to form a protein complex, mediated by chaperone molecules that do not form part of the finished complex. |
| proteasome core complex assembly | The aggregation, arrangement and bonding together of a mature, active 20S proteasome core particle complex that does not contain any regulatory particles. |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAATFFGEVV | KAPCRAGTED | EEEEEEGRRE | TPEDREVRLQ | LARKREVRLL | RRQTKTSLEV |
| 70 | 80 | 90 | 100 | 110 | 120 |
| SLLEKYPCSK | FIIAIGNNAV | AFLSSFVMNS | GVWEEVGCAK | LWNEWCRTTD | TTHLSSTEAF |
| 130 | 140 | 150 | 160 | 170 | 180 |
| CVFYHLKSNP | SVFLCQCSCY | VAEDQQYQWL | EKVFGSCPRK | NMQITILTCR | HVTDYKTSES |
| 190 | 200 | 210 | 220 | 230 | 240 |
| TGSLPSPFLR | ALKTQNFKDS | ACCPLLEQPN | IVHDLPAAVL | SYCQVWKIPA | ILYLCYTDVM |
| 250 | 260 | 270 | 280 | ||
| KLDLITVEAF | KPILSTRSLK | GLVKNIPQST | EILKKLMTTN | EIQSNIYT |