O94992
Gene name |
HEXIM1 (CLP1, EDG1, HIS1, MAQ1) |
Protein name |
Protein HEXIM1 |
Names |
Cardiac lineage protein 1, Estrogen down-regulated gene 1 protein, Hexamethylene bis-acetamide-inducible protein 1, Menage a quatre protein 1 |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:10614 |
EC number |
|
Protein Class |
|
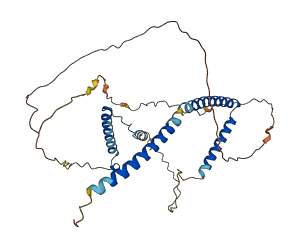
Descriptions
(Annotation from UniProt)
HEXIM1 is a transcriptional regulator which functions as a general RNA polymerase II transcription inhibitor.
Autoinhibitory domains (AIDs)
Target domain |
202-205 (P-TEFb interaction region) |
Relief mechanism |
Partner binding |
Assay |
|
Accessory elements
No accessory elements
References
Autoinhibited structure

Activated structure
3 structures for O94992
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| 2GD7 | NMR | - | A/B | 255-359 | PDB |
| 3S9G | X-ray | 210 A | A/B | 255-359 | PDB |
| AF-O94992-F1 | Predicted | AlphaFoldDB |
245 variants for O94992
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA8611956 rs761441239 |
2 | A>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399858013 rs1350671005 |
3 | E>K | No |
ClinGen gnomAD |
|
|
rs754411480 CA8611958 |
4 | P>R | No |
ClinGen ExAC gnomAD |
|
|
rs755261268 CA8611959 |
5 | F>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8611960 rs765719338 |
9 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
CA8611961 rs752910152 |
11 | H>P | No |
ClinGen ExAC gnomAD |
|
|
rs758700108 CA8611962 |
13 | P>L | No |
ClinGen ExAC gnomAD |
|
|
CA8611963 rs778210451 |
14 | Q>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs747061601 CA8611964 |
16 | S>G | No |
ClinGen ExAC gnomAD |
|
|
rs373817429 CA291015664 |
16 | S>N | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8611965 rs373817429 |
16 | S>T | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs1282628191 CA399858120 |
18 | C>F | No |
ClinGen TOPMed |
|
|
rs1332293289 CA399858127 |
19 | T>I | No |
ClinGen Ensembl |
|
|
CA291015675 rs367729540 |
20 | G>D | No |
ClinGen ESP TOPMed |
|
|
rs140416514 CA8611966 |
22 | A>V | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA8611967 rs745839893 |
23 | A>V | No |
ClinGen ExAC gnomAD |
|
|
rs777735067 CA8611969 |
24 | V>I | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1183486343 CA399858170 |
26 | E>D | No |
ClinGen gnomAD |
|
|
CA291015698 rs370597507 |
30 | P>L | No |
ClinGen ESP gnomAD |
|
|
CA399858200 rs1428912076 |
31 | E>G | No |
ClinGen TOPMed |
|
|
CA8611971 rs768281978 |
31 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA8611972 rs774042737 |
32 | R>G | No |
ClinGen ExAC gnomAD |
|
|
CA399858204 rs774042737 |
32 | R>S | No |
ClinGen ExAC gnomAD |
|
|
CA8611976 rs767088972 |
34 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs767088972 CA399858215 |
34 | P>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399858238 rs1372440542 |
37 | E>D | No |
ClinGen gnomAD |
|
|
rs758892714 CA399858245 |
38 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs758892714 CA8611981 |
38 | E>D | No |
ClinGen ExAC gnomAD |
|
|
CA8611980 rs139710804 |
38 | E>K | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs764378739 CA8611982 |
39 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
CA8611983 rs149955210 |
40 | V>L | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA8611984 rs149955210 |
40 | V>M | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA291015818 rs994661450 |
41 | P>S | No |
ClinGen Ensembl |
|
|
rs745722539 CA8611987 |
42 | E>A | No |
ClinGen ExAC gnomAD |
|
|
rs903988968 CA291015819 |
42 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA399858259 rs903988968 |
42 | E>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA8611989 rs780022419 |
43 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs756070648 CA8611988 |
43 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA8611991 rs372695634 |
46 | R>M | No |
ClinGen ESP ExAC gnomAD |
|
|
CA399858318 rs1436544175 |
50 | R>K | No |
ClinGen TOPMed gnomAD |
|
|
rs868552409 CA291015835 |
51 | A>E | No |
ClinGen TOPMed |
|
|
rs1567917731 CA399858323 |
51 | A>T | No |
ClinGen Ensembl |
|
|
CA399858327 rs868552409 |
51 | A>V | No |
ClinGen TOPMed |
|
|
rs772784303 CA8611995 |
52 | F>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399858340 rs1180267674 |
53 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
CA291015933 rs11558627 |
54 | Q>H | No |
ClinGen Ensembl |
|
|
rs11558627 CA291015939 |
54 | Q>H | No |
ClinGen Ensembl |
|
|
rs1190141107 CA399858341 |
54 | Q>K | No |
ClinGen gnomAD |
|
|
CA8611996 rs760170895 |
56 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs770412496 CA8611997 |
58 | R>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1168034197 CA399858371 |
59 | P>A | No |
ClinGen TOPMed gnomAD |
|
|
rs1334775996 CA399858384 |
61 | P>A | No |
ClinGen gnomAD |
|
|
CA8612000 rs764574971 |
62 | E>D | No |
ClinGen ExAC gnomAD |
|
|
CA8612001 rs751673575 |
63 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs762094836 CA8612002 |
64 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8612003 rs767694506 |
66 | S>I | No |
ClinGen ExAC gnomAD |
|
|
rs1346533085 CA399858438 |
69 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
rs1156906487 CA399858435 |
69 | S>P | No |
ClinGen gnomAD |
|
|
CA399858451 rs1024700122 |
71 | P>L | No |
ClinGen TOPMed |
|
|
CA291015990 rs1024700122 |
71 | P>R | No |
ClinGen TOPMed |
|
|
CA291015991 rs967415341 |
72 | P>L | No |
ClinGen gnomAD |
|
|
CA399858462 rs1279959416 |
73 | P>L | No |
ClinGen gnomAD |
|
|
rs756233346 CA8612005 |
75 | Q>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs977466725 CA291015994 |
76 | T>I | No |
ClinGen Ensembl |
|
|
CA399858478 rs1567917775 |
76 | T>S | No |
ClinGen Ensembl |
|
|
rs753806975 CA8612007 |
77 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
rs1188224043 CA399858490 |
78 | A>S | No |
ClinGen gnomAD |
|
|
CA399858499 rs1419783939 |
79 | C>S | No |
ClinGen TOPMed |
|
|
rs147427660 CA8612009 |
80 | P>Q | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA8612010 rs572482083 |
81 | E>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1424394316 CA399858516 |
82 | S>P | No |
ClinGen gnomAD |
|
|
CA8612011 rs536393664 |
83 | S>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA399858527 rs536393664 |
83 | S>R | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1161061696 CA399858533 |
84 | C>F | No |
ClinGen gnomAD |
|
|
CA8612012 rs777350008 |
86 | R>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8612013 rs746508181 |
87 | E>G | No |
ClinGen ExAC gnomAD |
|
|
rs776090403 CA8612015 |
88 | G>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA291016055 rs975607932 |
88 | G>S | No |
ClinGen gnomAD |
|
|
rs201788609 CA8612016 |
89 | E>K | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs774768717 CA8612018 |
91 | G>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs774768717 CA399858577 |
91 | G>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399858600 rs1208304257 |
95 | D>Y | No |
ClinGen gnomAD |
|
|
rs1307931916 CA399858614 |
96 | D>E | No |
ClinGen TOPMed |
|
|
rs372722263 CA291016082 |
96 | D>N | No |
ClinGen ESP TOPMed gnomAD |
|
|
rs762138738 CA8612020 |
97 | S>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
COSM1521387 CA8612021 rs767754935 |
97 | S>L | lung [Cosmic] | No |
ClinGen cosmic curated ExAC gnomAD |
|
rs1230905768 CA399858622 |
98 | S>Y | No |
ClinGen TOPMed |
|
|
CA8612022 rs201778839 |
99 | A>T | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA399858630 rs1479401477 |
100 | G>S | No |
ClinGen gnomAD |
|
|
CA8612023 rs760708795 |
101 | G>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1385600674 CA399858649 |
103 | F>I | No |
ClinGen TOPMed |
|
|
rs753721065 CA8612025 |
103 | F>L | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1156426623 CA399858658 |
104 | P>S | No |
ClinGen gnomAD |
|
|
rs1392413805 CA399858665 |
105 | P>L | No |
ClinGen gnomAD |
|
|
rs778783867 CA399858692 |
109 | V>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs778783867 CA8612027 |
109 | V>G | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs12051846 CA399858699 |
110 | E>D | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
CA399858696 rs1403587482 |
110 | E>G | No |
ClinGen gnomAD |
|
|
CA291016162 rs17850101 |
110 | E>K | No |
ClinGen Ensembl |
|
|
rs1403587482 CA399858697 |
110 | E>V | No |
ClinGen gnomAD |
|
|
CA8612030 rs371316696 |
111 | P>S | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs756767765 CA8612032 |
112 | T>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1210709779 CA399858713 |
113 | P>H | No |
ClinGen gnomAD |
|
|
CA399858712 rs1358696096 |
113 | P>S | No |
ClinGen gnomAD |
|
|
CA399858720 rs1489888388 |
114 | E>G | No |
ClinGen gnomAD |
|
|
CA399858718 rs1289175326 |
114 | E>K | No |
ClinGen gnomAD |
|
|
CA8612033 rs780853522 |
115 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA399858728 rs1360903050 |
115 | A>V | No |
ClinGen Ensembl |
|
|
CA291016187 rs775152336 |
116 | E>D | No |
ClinGen Ensembl |
|
|
CA8612034 rs745438153 |
116 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA291016192 rs868242690 |
117 | L>M | No |
ClinGen Ensembl |
|
|
rs769192457 CA8612035 |
118 | L>F | No |
ClinGen ExAC gnomAD |
|
|
rs774768886 CA8612036 |
119 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA291016200 rs867729042 |
120 | Q>K | No |
ClinGen Ensembl |
|
|
CA291016201 rs898947076 |
121 | P>L | No |
ClinGen gnomAD |
|
|
rs748513171 CA8612037 |
123 | H>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs772356897 CA8612038 |
123 | H>Q | No |
ClinGen ExAC |
|
|
rs564812671 CA399858778 |
124 | D>A | No |
ClinGen 1000Genomes |
|
|
rs564812671 CA291016219 |
124 | D>G | No |
ClinGen 1000Genomes |
|
|
CA8612040 rs202151146 |
125 | S>F | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA8612043 rs759674454 |
126 | E>G | No |
ClinGen ExAC gnomAD |
|
|
CA8612042 rs776691576 |
126 | E>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1305275030 CA399858811 |
129 | K>M | No |
ClinGen gnomAD |
|
|
CA8612044 rs765202046 |
129 | K>N | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs752620066 CA399858815 |
130 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399858818 rs1598115635 |
130 | L>W | No |
ClinGen Ensembl |
|
|
rs1246796223 CA399858827 |
132 | A>T | No |
ClinGen TOPMed |
|
|
rs894323965 CA291016292 |
132 | A>V | No |
ClinGen Ensembl |
|
|
CA291016306 rs763269543 |
134 | A>T | No |
ClinGen Ensembl |
|
|
rs1283821897 CA399858842 |
134 | A>V | No |
ClinGen gnomAD |
|
|
CA399858845 rs1207364761 |
135 | A>S | No |
ClinGen gnomAD |
|
|
CA8612048 rs763806684 |
136 | G>E | No |
ClinGen ExAC |
|
|
CA291016351 rs763806684 |
136 | G>V | No |
ClinGen ExAC |
|
|
CA291016360 rs573692319 |
138 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA399858859 rs573692319 |
138 | E>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1391342239 CA399858868 |
139 | E>K | No |
ClinGen TOPMed |
|
|
CA399858883 rs1598115647 |
141 | W>R | No |
ClinGen Ensembl |
|
|
CA399858892 rs1442822402 |
142 | G>R | No |
ClinGen gnomAD |
|
|
CA8612049 rs751186893 |
142 | G>V | No |
ClinGen ExAC gnomAD |
|
|
CA8612050 rs756961690 |
146 | R>K | No |
ClinGen ExAC gnomAD |
|
|
CA8612051 rs756961690 |
146 | R>T | No |
ClinGen ExAC gnomAD |
|
|
rs1168673902 CA399858930 |
147 | Q>L | No |
ClinGen gnomAD |
|
|
CA399858936 rs1310202424 |
148 | L>R | No |
ClinGen TOPMed |
|
|
rs745348258 CA8612052 |
148 | L>V | No |
ClinGen ExAC gnomAD |
|
|
CA8612053 rs755618582 |
149 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA291016406 rs1024230967 |
149 | G>V | No |
ClinGen Ensembl |
|
|
rs1163903505 CA399858953 |
151 | K>R | No |
ClinGen TOPMed |
|
|
rs1567917922 CA399858970 |
153 | H>R | No |
ClinGen Ensembl |
|
|
rs998890294 CA291016430 |
159 | K>Q | No |
ClinGen Ensembl |
|
|
CA399859020 rs1419632893 |
161 | K>Q | No |
ClinGen TOPMed |
|
|
rs1380848991 CA399859035 |
163 | H>Y | No |
ClinGen gnomAD |
|
|
CA8612059 rs747440430 |
169 | K>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8612065 rs762800485 |
178 | F>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1168879110 CA399859183 |
182 | Q>R | No |
ClinGen gnomAD |
|
|
CA291016503 rs997548764 |
184 | L>F | No |
ClinGen TOPMed gnomAD |
|
|
CA399859229 rs1222065251 |
189 | I>M | No |
ClinGen TOPMed |
|
|
CA8612069 rs142819745 |
193 | M>R | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8612070 rs530470552 |
194 | F>V | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1380620464 CA399859282 |
197 | G>A | No |
ClinGen gnomAD |
|
|
CA291016544 rs866763268 |
199 | P>Q | No |
ClinGen Ensembl |
|
|
rs1388175038 CA399859299 |
200 | V>I | No |
ClinGen TOPMed |
|
|
rs778315232 CA8612075 |
203 | Y>C | No |
ClinGen ExAC gnomAD |
|
|
rs1267115653 CA399859397 |
214 | D>N | No |
ClinGen gnomAD |
|
|
rs908824824 CA291016603 |
216 | E>G | No |
ClinGen TOPMed |
|
|
rs771328485 CA8612077 |
216 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA291016605 rs17845094 |
219 | D>H | No |
ClinGen Ensembl |
|
|
CA291016612 rs17845094 |
219 | D>Y | No |
ClinGen Ensembl |
|
|
CA399859458 rs1459162610 |
222 | T>I | No |
ClinGen TOPMed gnomAD |
|
|
rs552016551 CA291016624 |
223 | G>C | No |
ClinGen TOPMed |
|
|
rs552016551 CA291016622 |
223 | G>S | No |
ClinGen TOPMed |
|
|
rs1451987103 CA399859464 |
224 | L>V | No |
ClinGen gnomAD |
|
|
CA399859478 rs1429765117 |
226 | S>P | No |
ClinGen TOPMed |
|
|
CA399859490 rs1404212859 |
228 | R>G | No |
ClinGen gnomAD |
|
|
rs1435093631 CA399859503 |
230 | A>S | No |
ClinGen TOPMed |
|
|
rs774469216 CA8612085 |
233 | S>C | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs774469216 CA291016633 |
233 | S>Y | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1319471293 CA399859525 |
234 | D>N | No |
ClinGen Ensembl |
|
|
CA399859546 rs1270508067 |
236 | T>I | No |
ClinGen TOPMed |
|
|
rs761658949 CA8612086 |
240 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1598115801 CA399859590 |
242 | M>T | No |
ClinGen Ensembl |
|
|
CA399859616 rs1284362154 |
245 | G>A | No |
ClinGen TOPMed |
|
|
rs1323219016 CA399859611 |
245 | G>R | No |
ClinGen TOPMed |
|
|
rs1284362154 CA399859615 |
245 | G>V | No |
ClinGen TOPMed |
|
|
rs536863589 CA291016673 |
246 | G>R | No |
ClinGen 1000Genomes |
|
|
rs930368194 CA291016676 |
247 | E>K | No |
ClinGen Ensembl |
|
|
rs199709995 CA8612089 |
248 | E>A | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs766123446 CA8612090 |
248 | E>D | No |
ClinGen ExAC gnomAD |
|
|
rs1267342278 CA399859629 |
248 | E>K | No |
ClinGen gnomAD |
|
|
CA8612093 rs778225514 |
251 | G>V | No |
ClinGen ExAC |
|
|
rs781539082 CA8612096 |
254 | G>A | No |
ClinGen ExAC gnomAD |
|
|
rs746307675 CA8612097 |
255 | M>I | No |
ClinGen ExAC gnomAD |
|
|
rs1473892250 CA399859685 |
256 | G>E | No |
ClinGen gnomAD |
|
|
CA291016724 rs77347587 |
256 | G>R | No |
ClinGen 1000Genomes |
|
|
CA399859711 rs1469256984 |
260 | S>N | No |
ClinGen TOPMed |
|
|
rs749295351 CA8612101 |
269 | E>K | No |
ClinGen ExAC gnomAD |
|
|
CA291016786 rs556337511 |
276 | T>M | No |
ClinGen ExAC gnomAD |
|
|
CA8612102 rs556337511 |
276 | T>R | No |
ClinGen ExAC gnomAD |
|
|
CA8612105 rs771927060 |
285 | Q>R | No |
ClinGen ExAC gnomAD |
|
|
CA399859911 rs1312995284 |
288 | I>L | No |
ClinGen gnomAD |
|
|
CA399859915 rs1598115865 |
288 | I>M | No |
ClinGen Ensembl |
|
|
CA399859910 rs1312995284 |
288 | I>V | No |
ClinGen gnomAD |
|
|
CA399859969 rs1243121610 |
296 | K>T | No |
ClinGen gnomAD |
|
|
CA8612109 rs753570394 |
304 | E>D | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1232619623 CA399860040 |
306 | N>H | No |
ClinGen gnomAD |
|
|
rs1232619623 CA399860042 |
306 | N>Y | No |
ClinGen gnomAD |
|
|
CA399860054 rs1190663893 |
308 | L>M | No |
ClinGen TOPMed gnomAD |
|
|
CA399860090 rs1328105652 |
313 | K>N | No |
ClinGen TOPMed gnomAD |
|
|
CA399860088 rs1598115894 |
313 | K>R | No |
ClinGen Ensembl |
|
|
rs577043303 CA8612115 |
314 | R>Q | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
rs1451337883 CA399860102 |
316 | G>R | No |
ClinGen TOPMed |
|
|
CA399860107 rs1449979802 |
317 | G>S | No |
ClinGen gnomAD |
|
|
CA399860116 rs1598115906 |
318 | D>G | No |
ClinGen Ensembl |
|
|
rs780098711 CA8612118 |
318 | D>N | No |
ClinGen ExAC gnomAD |
|
|
CA399860120 rs1429662127 |
319 | D>N | No |
ClinGen gnomAD |
|
|
rs749545313 CA8612119 |
320 | A>T | No |
ClinGen ExAC gnomAD |
|
|
CA399860136 rs1167511541 |
321 | R>H | No |
ClinGen TOPMed |
|
|
CA399860140 rs1215631440 |
322 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
rs1306322141 CA399860156 |
324 | E>D | No |
ClinGen TOPMed gnomAD |
|
|
rs755049061 CA8612120 |
327 | L>V | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA8612122 rs748306481 |
330 | D>E | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399860202 rs1250294114 |
332 | L>Q | No |
ClinGen TOPMed |
|
|
CA399860200 rs1181994252 |
332 | L>V | No |
ClinGen gnomAD |
|
|
rs1343823870 CA399860215 |
334 | A>V | No |
ClinGen TOPMed |
|
|
CA291016903 rs1047809248 |
335 | E>D | No |
ClinGen TOPMed |
|
|
CA8612125 rs773251342 |
337 | L>F | No |
ClinGen ExAC gnomAD |
|
|
CA8612128 rs541011575 |
341 | T>N | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA399860260 rs1334912340 |
342 | E>K | No |
ClinGen TOPMed |
|
|
CA8612130 rs776102182 |
343 | N>K | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA399860275 COSM356845 rs1217172915 |
344 | E>K | lung [Cosmic] | No |
ClinGen cosmic curated gnomAD |
|
rs368302641 CA8612131 |
347 | R>G | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
rs774964207 CA8612132 |
347 | R>Q | No |
ClinGen ExAC gnomAD |
|
|
rs368302641 CA291016923 |
347 | R>W | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA8612135 rs750970888 |
349 | Q>E | No |
ClinGen ExAC gnomAD |
|
|
rs1598115979 CA399860309 |
349 | Q>R | No |
ClinGen Ensembl |
|
|
rs1264081938 CA399860322 |
351 | R>* | No |
ClinGen gnomAD |
|
|
rs756384069 CA399860323 |
351 | R>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs756384069 CA8612136 |
351 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs762293916 CA8612138 |
352 | A>P | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs201459082 CA8612140 |
353 | P>L | No |
ClinGen 1000Genomes ExAC |
|
|
CA8612141 rs201018268 |
356 | K>N | No |
ClinGen 1000Genomes ExAC gnomAD |
|
|
CA399860350 rs1240497147 |
356 | K>T | No |
ClinGen gnomAD |
|
|
rs1567918222 CA399860358 |
357 | F>S | No |
ClinGen Ensembl |
|
|
CA399860366 rs1191712738 |
358 | G>A | No |
ClinGen gnomAD |
|
|
rs755970749 CA8612142 |
360 | D>D | No |
ClinGen ExAC |
|
|
CA8612143 rs758595649 |
360 | D>E | No |
ClinGen ExAC gnomAD |
No associated diseases with O94992
No regional properties for O94992
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for O94992 | |||
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| 7SK snRNP | A ribonucleoprotein complex that contains the 7SK snRNA. The 7SK snRNP plays a central role in RNA polymerase II elongation control by regulating the availability of active P-TEFb. |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| intracellular membrane-bounded organelle | Organized structure of distinctive morphology and function, bounded by a single or double lipid bilayer membrane and occurring within the cell. Includes the nucleus, mitochondria, plastids, vacuoles, and vesicles. Excludes the plasma membrane. |
| nucleoplasm | That part of the nuclear content other than the chromosomes or the nucleolus. |
| nucleus | A membrane-bounded organelle of eukaryotic cells in which chromosomes are housed and replicated. In most cells, the nucleus contains all of the cell's chromosomes except the organellar chromosomes, and is the site of RNA synthesis and processing. In some species, or in specialized cell types, RNA metabolism or DNA replication may be absent. |
6 GO annotations of molecular function
| Name | Definition |
|---|---|
| 7SK snRNA binding | Binding to a 7SK small nuclear RNA (7SK snRNA). |
| cyclin-dependent protein serine/threonine kinase inhibitor activity | Binds to and stops, prevents or reduces the activity of a cyclin-dependent protein serine/threonine kinase. |
| identical protein binding | Binding to an identical protein or proteins. |
| P-TEFb complex binding | Binding to a P-TEFb complex. |
| protein kinase inhibitor activity | Binds to and stops, prevents or reduces the activity of a protein kinase, an enzyme which phosphorylates a protein. |
| snRNA binding | Binding to a small nuclear RNA (snRNA). |
9 GO annotations of biological process
| Name | Definition |
|---|---|
| activation of innate immune response | Any process that initiates an innate immune response. Innate immune responses are defense responses mediated by germline encoded components that directly recognize components of potential pathogens. Examples of this process include activation of the hypersensitive response of Arabidopsis thaliana and activation of any NOD or TLR signaling pathway in vertebrate species. |
| heart development | The process whose specific outcome is the progression of the heart over time, from its formation to the mature structure. The heart is a hollow, muscular organ, which, by contracting rhythmically, keeps up the circulation of the blood. |
| innate immune response | Innate immune responses are defense responses mediated by germline encoded components that directly recognize components of potential pathogens. |
| negative regulation of cyclin-dependent protein serine/threonine kinase activity | Any process that stops, prevents, or reduces the frequency, rate or extent of cyclin-dependent protein serine/threonine kinase activity. |
| negative regulation of transcription by RNA polymerase II | Any process that stops, prevents, or reduces the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| negative regulation of transcription elongation from RNA polymerase II promoter | Any process that stops, prevents, or reduces the frequency, rate or extent of transcription elongation, the extension of an RNA molecule after transcription initiation and promoter clearance by the addition of ribonucleotides, catalyzed by RNA polymerase II. |
| negative regulation of transcription, DNA-templated | Any process that stops, prevents, or reduces the frequency, rate or extent of cellular DNA-templated transcription. |
| negative regulation of viral transcription | Any process that stops, prevents, or reduces the frequency, rate or extent of viral transcription. |
| positive regulation of signal transduction by p53 class mediator | Any process that activates or increases the frequency, rate or extent of signal transduction by p53 class mediator. |
| 10 | 20 | 30 | 40 | 50 | 60 |
| MAEPFLSEYQ | HQPQTSNCTG | AAAVQEELNP | ERPPGAEERV | PEEDSRWQSR | AFPQLGGRPG |
| 70 | 80 | 90 | 100 | 110 | 120 |
| PEGEGSLESQ | PPPLQTQACP | ESSCLREGEK | GQNGDDSSAG | GDFPPPAEVE | PTPEAELLAQ |
| 130 | 140 | 150 | 160 | 170 | 180 |
| PCHDSEASKL | GAPAAGGEEE | WGQQQRQLGK | KKHRRRPSKK | KRHWKPYYKL | TWEEKKKFDE |
| 190 | 200 | 210 | 220 | 230 | 240 |
| KQSLRASRIR | AEMFAKGQPV | APYNTTQFLM | DDHDQEEPDL | KTGLYSKRAA | AKSDDTSDDD |
| 250 | 260 | 270 | 280 | 290 | 300 |
| FMEEGGEEDG | GSDGMGGDGS | EFLQRDFSET | YERYHTESLQ | NMSKQELIKE | YLELEKCLSR |
| 310 | 320 | 330 | 340 | 350 | |
| MEDENNRLRL | ESKRLGGDDA | RVRELELELD | RLRAENLQLL | TENELHRQQE | RAPLSKFGD |