Q9VPH2
Gene name |
Prim2 |
Protein name |
DNA primase large subunit |
Names |
DNA polymerase subunit beta, Suppressor of fat facets 240 |
Species |
Drosophila melanogaster (Fruit fly) |
KEGG Pathway |
dme:Dmel_CG5553 |
EC number |
|
Protein Class |
|
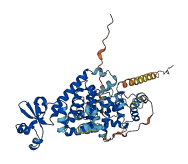
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q9VPH2
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q9VPH2-F1 | Predicted | AlphaFoldDB |
No variants for Q9VPH2
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
| No variants for Q9VPH2 | |||||
No associated diseases with Q9VPH2
No regional properties for Q9VPH2
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| No domain, repeats, and functional sites for Q9VPH2 | |||
1 GO annotations of cellular component
| Name | Definition |
|---|---|
| alpha DNA polymerase:primase complex | A complex of four polypeptides, comprising large and small DNA polymerase alpha subunits and two primase subunits, which are capable of catalyzing the synthesis of an RNA primer on the lagging strand of replicating DNA and the subsequent synthesis of a smal stretch of DNA. The smaller of the two primase subunits alone can catalyze oligoribonucleotide synthesis. |
3 GO annotations of molecular function
| Name | Definition |
|---|---|
| 4 iron, 4 sulfur cluster binding | Binding to a 4 iron, 4 sulfur (4Fe-4S) cluster; this cluster consists of four iron atoms, with the inorganic sulfur atoms found between the irons and acting as bridging ligands. |
| DNA binding | Any molecular function by which a gene product interacts selectively and non-covalently with DNA (deoxyribonucleic acid). |
| metal ion binding | Binding to a metal ion. |
6 GO annotations of biological process
| Name | Definition |
|---|---|
| compound eye morphogenesis | The morphogenetic process in which the anatomical structures of the compound eye are generated and organized. The adult compound eye is a precise assembly of 700-800 ommatidia. Each ommatidium is composed of 20 cells, identified by cell type and position. An example of compound eye morphogenesis is found in Drosophila melanogaster. |
| DNA replication | The cellular metabolic process in which a cell duplicates one or more molecules of DNA. DNA replication begins when specific sequences, known as origins of replication, are recognized and bound by initiation proteins, and ends when the original DNA molecule has been completely duplicated and the copies topologically separated. The unit of replication usually corresponds to the genome of the cell, an organelle, or a virus. The template for replication can either be an existing DNA molecule or RNA. |
| DNA replication initiation | The process in which DNA-dependent DNA replication is started; this begins with the ATP dependent loading of an initiator complex onto the DNA, this is followed by DNA melting and helicase activity. In bacteria, the gene products that enable the helicase activity are loaded after the initial melting and in archaea and eukaryotes, the gene products that enable the helicase activity are inactive when they are loaded and subsequently activate. |
| DNA replication, synthesis of RNA primer | The synthesis of a short RNA polymer, usually 4-15 nucleotides long, using one strand of unwound DNA as a template; the RNA then serves as a primer from which DNA polymerases extend synthesis. |
| DNA-templated DNA replication | A DNA replication process that uses parental DNA as a template for the DNA-dependent DNA polymerases that synthesize the new strands. |
| mitotic cell cycle | Progression through the phases of the mitotic cell cycle, the most common eukaryotic cell cycle, which canonically comprises four successive phases called G1, S, G2, and M and includes replication of the genome and the subsequent segregation of chromosomes into daughter cells. In some variant cell cycles nuclear replication or nuclear division may not be followed by cell division, or G1 and G2 phases may be absent. |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MEFGLKKRAR | HEVKVEVASL | ETKYPHNVML | YHYPPTEDVH | IDEFEELALE | RLRLLRVLDR |
| 70 | 80 | 90 | 100 | 110 | 120 |
| ASTRNLRVLS | DEWKEIVSAD | LTREGLRSYL | RLCSTGGSAK | HEADIQTRRR | DYLSHFILRL |
| 130 | 140 | 150 | 160 | 170 | 180 |
| AYCRSEDLAR | WFVAREMELF | RYKFAALSSF | EVKQFLEANG | FEIHPLTEAQ | KDEVKDGLYE |
| 190 | 200 | 210 | 220 | 230 | 240 |
| STVGQSVAKI | ELLDFYKVPF | TQVLDLVRGR | RCFLKAGYAY | VNTHDLVSLV | GTKQQDEIEQ |
| 250 | 260 | 270 | 280 | 290 | 300 |
| GLQAAKTMVE | DVEADERISR | TLKALHNSYT | GRDYTVCRDA | AVPIESLDQL | SKTSMPLCMR |
| 310 | 320 | 330 | 340 | 350 | 360 |
| MCHEHIRANH | HIKHSGRMQY | GLFLKGIGVA | LEDSLRFWRE | EFTKKMDADK | FTRSYEYNIY |
| 370 | 380 | 390 | 400 | 410 | 420 |
| HNYGKKGSMV | NYTPYSCAKI | IKDVAGPGDC | HGCPYKNMDQ | GSLKTKLSSY | GLSASAIDEV |
| 430 | 440 | 450 | 460 | 470 | 480 |
| MFFVSRGHYQ | IGCGKYFQLT | HNSPVEPSIN | HPNNYFEESQ | IAMGNRQKRA | NGSAPPKARI |
| 490 | 500 | 510 | 520 | 530 | |
| RPDIKGHGDR | SMLMGDDDDE | LWRIAETQER | IMQSQKDISE | AFNDDLDLTQ | IDY |