Q96IU2
Gene name |
ZBED3 |
Protein name |
Zinc finger BED domain-containing protein 3 |
Names |
Axin-interacting protein |
Species |
Homo sapiens (Human) |
KEGG Pathway |
hsa:84327 |
EC number |
|
Protein Class |
|
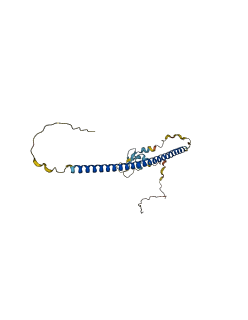
Descriptions
The autoinhibited protein was predicted that may have potential autoinhibitory elements via cis-regPred.
Autoinhibitory domains (AIDs)
Target domain |
|
Relief mechanism |
|
Assay |
cis-regPred |
Accessory elements
No accessory elements
Autoinhibited structure

Activated structure
1 structures for Q96IU2
| Entry ID | Method | Resolution | Chain | Position | Source |
|---|---|---|---|---|---|
| AF-Q96IU2-F1 | Predicted | AlphaFoldDB |
212 variants for Q96IU2
| Variant ID(s) | Position | Change | Description | Diseaes Association | Provenance |
|---|---|---|---|---|---|
|
CA121424011 rs904312589 |
2 | R>S | No |
ClinGen TOPMed gnomAD |
|
|
CA121424009 rs915246544 |
3 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
rs1229557200 CA360327364 |
5 | E>K | No |
ClinGen TOPMed |
|
|
CA360327347 rs1265378384 |
6 | P>Q | No |
ClinGen gnomAD |
|
|
CA360327338 rs1398040546 |
7 | A>D | No |
ClinGen TOPMed |
|
|
rs752492611 CA3314741 |
9 | T>A | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 9 | T>I | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1041821286 CA121424004 |
10 | M>T | No |
ClinGen TOPMed gnomAD |
|
|
rs956984173 CA360327283 CA121424000 |
11 | D>E | No |
ClinGen TOPMed |
|
|
CA3314740 rs764954901 |
11 | D>H | No |
ClinGen ExAC gnomAD |
|
|
rs945742135 CA121423996 |
12 | Q>E | No |
ClinGen TOPMed gnomAD |
|
|
rs945742135 CA121423998 |
12 | Q>K | No |
ClinGen TOPMed gnomAD |
|
|
CA360327258 rs1337492939 |
13 | A>V | No |
ClinGen gnomAD |
|
|
CA360327254 rs1329520106 |
14 | R>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1343840583 CA360327251 |
14 | R>H | No |
ClinGen TOPMed |
|
|
CA360327253 rs1329520106 |
14 | R>S | No |
ClinGen TOPMed gnomAD |
|
|
rs759492668 CA3314739 |
15 | G>R | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA360327227 rs1281460716 |
17 | D>N | No |
ClinGen TOPMed |
|
|
CA121423992 rs911534498 |
19 | A>P | No |
ClinGen Ensembl |
|
|
rs1178250657 CA360327162 |
20 | A>V | No |
ClinGen gnomAD |
|
|
CA360327151 rs1470426154 |
21 | A>E | No |
ClinGen TOPMed gnomAD |
|
|
rs1470426154 CA360327147 |
21 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1424672007 CA360327137 |
22 | R>L | No |
ClinGen TOPMed gnomAD |
|
|
CA360327139 rs1424672007 |
22 | R>P | No |
ClinGen TOPMed gnomAD |
|
|
rs1424672007 CA360327141 |
22 | R>Q | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 22 | R>W | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1174551837 CA360327121 |
24 | G>S | No |
ClinGen TOPMed |
|
|
CA360327110 rs1377521165 |
25 | Q>* | No |
ClinGen TOPMed |
|
|
rs1417585318 CA360327105 |
25 | Q>R | No |
ClinGen TOPMed |
|
|
CA360327092 rs1471227567 |
26 | C>S | No |
ClinGen TOPMed gnomAD |
|
|
CA360327079 rs1383913560 |
27 | P>Q | No |
ClinGen TOPMed |
|
|
rs987741438 CA121423989 |
28 | G>R | No |
ClinGen TOPMed |
|
|
CA360327067 rs1277688715 |
28 | G>V | No |
ClinGen gnomAD |
|
| TCGA novel | 30 | G>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1181801448 CA360327038 |
31 | P>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1181801448 CA360327036 |
31 | P>R | No |
ClinGen TOPMed gnomAD |
|
|
rs1351095754 CA360327018 |
33 | P>A | No |
ClinGen TOPMed |
|
|
rs1486476503 CA360327007 |
34 | T>A | No |
ClinGen TOPMed |
|
| TCGA novel | 37 | P>missing | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA121423980 rs965588295 |
37 | P>L | No |
ClinGen TOPMed gnomAD |
|
|
rs181914313 CA3314736 |
38 | P>L | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA3314735 rs762005321 |
39 | G>D | No |
ClinGen ExAC gnomAD |
|
| TCGA novel | 43 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1374479650 CA360326899 |
44 | P>S | No |
ClinGen gnomAD |
|
|
CA360326890 rs1455256601 |
45 | Y>H | No |
ClinGen TOPMed |
|
|
CA3314734 rs774283853 |
46 | S>A | No |
ClinGen ExAC gnomAD |
|
|
rs952348044 CA360326873 |
46 | S>C | No |
ClinGen TOPMed gnomAD |
|
|
CA121423972 rs952348044 |
46 | S>F | No |
ClinGen TOPMed gnomAD |
|
|
CA121423968 rs973602994 |
47 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
rs1352812467 CA360326855 |
48 | A>T | No |
ClinGen Ensembl |
|
|
rs963840012 CA121423966 |
50 | G>V | No |
ClinGen Ensembl |
|
|
rs1026640852 CA121423964 |
52 | F>C | No |
ClinGen TOPMed gnomAD |
|
|
rs1239063624 CA360326773 |
53 | H>Q | No |
ClinGen TOPMed |
|
|
CA360326755 rs1158064923 |
55 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA360326705 rs1468430853 |
60 | G>R | No |
ClinGen TOPMed |
|
|
CA360326678 rs1214334889 |
61 | H>Q | No |
ClinGen TOPMed |
|
|
CA360326656 rs1448310713 |
63 | S>* | No |
ClinGen gnomAD |
|
|
CA360326608 rs566987172 CA3314732 |
66 | W>C | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA360326620 rs1456608084 |
66 | W>R | No |
ClinGen TOPMed |
|
|
rs1420609348 CA360326604 |
67 | A>T | No |
ClinGen TOPMed |
|
|
rs1215204857 CA360326600 |
67 | A>V | No |
ClinGen gnomAD |
|
|
rs544486879 CA121423955 |
68 | T>P | No |
ClinGen Ensembl |
|
|
rs1162474070 CA360326578 |
69 | C>R | No |
ClinGen TOPMed |
|
|
rs1246582133 CA360326561 |
70 | R>C | No |
ClinGen TOPMed gnomAD |
|
|
CA360326562 rs1246582133 |
70 | R>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1345944526 CA360326517 |
74 | E>A | No |
ClinGen TOPMed gnomAD |
|
|
CA3314730 rs749458270 |
74 | E>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1345944526 CA360326515 |
74 | E>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1297693864 CA360326475 |
77 | G>D | No |
ClinGen TOPMed gnomAD |
|
|
rs905713001 CA121423948 |
78 | R>C | No |
ClinGen TOPMed gnomAD |
|
| TCGA novel | 78 | R>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs546975061 CA121423946 |
79 | G>S | No |
ClinGen 1000Genomes gnomAD |
|
|
rs1405289107 CA360326441 |
80 | P>L | No |
ClinGen gnomAD |
|
|
CA360326446 rs1187138825 |
80 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
CA360326433 rs1316197020 |
81 | G>D | No |
ClinGen TOPMed |
|
|
CA360326412 rs1203942840 |
83 | H>D | No |
ClinGen TOPMed |
|
|
CA360326388 rs1412156294 |
84 | A>V | No |
ClinGen gnomAD |
|
|
rs746201187 CA3314727 |
87 | S>* | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs746201187 CA3314728 |
87 | S>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1256617234 CA360326284 |
92 | H>Y | No |
ClinGen TOPMed |
|
|
CA360326243 rs1223208497 |
95 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
rs1320982653 CA360326236 |
95 | S>R | No |
ClinGen gnomAD |
|
|
rs1185145619 CA360326227 |
96 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA360326213 rs1287476679 |
97 | H>Q | No |
ClinGen TOPMed gnomAD |
|
|
CA360326206 rs1216069043 |
98 | R>Q | No |
ClinGen gnomAD |
|
|
CA360326209 rs1301453202 |
98 | R>W | No |
ClinGen TOPMed |
|
|
rs781745383 CA3314726 |
99 | R>Q | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA360326199 rs1362947437 |
99 | R>W | No |
ClinGen gnomAD |
|
|
rs1398353695 CA360326156 |
103 | S>G | No |
ClinGen gnomAD |
|
|
CA360326135 rs1415914622 |
106 | A>T | No |
ClinGen TOPMed |
|
| TCGA novel | 106 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs1339139279 CA360326041 |
113 | A>V | No |
ClinGen TOPMed |
|
|
rs1309471555 CA360325999 |
116 | P>L | No |
ClinGen TOPMed |
|
|
CA360325997 rs1309471555 |
116 | P>Q | No |
ClinGen TOPMed |
|
|
CA360325983 rs1279311355 |
117 | P>L | No |
ClinGen TOPMed |
|
|
CA121423924 rs924160741 |
119 | P>S | No |
ClinGen TOPMed |
|
|
rs977050633 CA121423922 |
120 | G>S | No |
ClinGen TOPMed gnomAD |
|
|
CA121423916 rs965890540 |
121 | P>H | No |
ClinGen TOPMed gnomAD |
|
|
rs1243436694 CA360325932 |
121 | P>S | No |
ClinGen TOPMed gnomAD |
|
|
rs911403053 CA121423914 |
126 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
rs1430721372 CA360325890 |
127 | G>S | No |
ClinGen TOPMed |
|
|
rs1348604631 CA360325878 |
129 | W>R | No |
ClinGen gnomAD |
|
|
CA360325859 rs1214598709 |
131 | R>H | No |
ClinGen gnomAD |
|
|
CA121423912 rs985167445 |
135 | Q>* | No |
ClinGen TOPMed |
|
|
rs1190097266 CA360325810 |
135 | Q>R | No |
ClinGen TOPMed |
|
|
CA360325771 rs1410922986 |
138 | A>S | No |
ClinGen gnomAD |
|
| TCGA novel | 138 | A>V | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
rs952501477 CA121423909 |
141 | V>M | No |
ClinGen TOPMed gnomAD |
|
|
rs1270427314 CA360325722 |
142 | R>C | No |
ClinGen gnomAD |
|
|
rs530122380 CA360325711 |
143 | G>C | No |
ClinGen 1000Genomes TOPMed |
|
|
CA360325709 rs1191202738 |
143 | G>D | No |
ClinGen gnomAD |
|
|
CA121423907 rs530122380 |
143 | G>S | No |
ClinGen 1000Genomes TOPMed |
|
|
rs1356279707 CA360325695 |
144 | S>N | No |
ClinGen TOPMed gnomAD |
|
|
rs1580145662 CA360325698 |
144 | S>R | No |
ClinGen Ensembl |
|
|
rs1206511115 CA360325670 |
146 | R>Q | No |
ClinGen gnomAD |
|
|
CA360325675 rs1244860051 |
146 | R>W | No |
ClinGen TOPMed gnomAD |
|
|
CA360325651 rs1257189430 |
147 | E>D | No |
ClinGen gnomAD |
|
|
rs1325861019 CA360325644 |
148 | R>Q | No |
ClinGen gnomAD |
|
|
CA360325646 rs1217098356 |
148 | R>W | No |
ClinGen gnomAD |
|
|
CA360325635 rs1284032590 |
149 | E>A | No |
ClinGen TOPMed gnomAD |
|
|
CA360325626 rs1386231543 |
149 | E>D | No |
ClinGen gnomAD |
|
|
CA360325632 rs1284032590 |
149 | E>G | No |
ClinGen TOPMed gnomAD |
|
|
CA360325617 rs1365544592 |
150 | L>P | No |
ClinGen gnomAD |
|
|
rs1365544592 CA360325615 |
150 | L>R | No |
ClinGen gnomAD |
|
|
CA360325612 rs1395244951 |
151 | E>K | No |
ClinGen TOPMed |
|
|
CA360325584 rs1444877126 |
152 | R>L | No |
ClinGen TOPMed gnomAD |
|
|
rs1444877126 CA360325585 |
152 | R>Q | No |
ClinGen TOPMed gnomAD |
|
|
rs1443557132 CA360325590 |
152 | R>W | No |
ClinGen gnomAD |
|
|
rs1329655804 CA360325575 |
153 | R>C | No |
ClinGen gnomAD |
|
|
CA360325562 rs1175906662 |
154 | E>K | No |
ClinGen TOPMed |
|
|
CA3314723 rs2303713 |
155 | L>P | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs2303714 CA3314724 |
155 | L>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
rs1422410152 CA360325523 |
157 | V>M | No |
ClinGen gnomAD |
|
|
CA360325475 rs1196480586 |
159 | Q>H | No |
ClinGen gnomAD |
|
|
CA360325490 rs1237360765 |
159 | Q>K | No |
ClinGen gnomAD |
|
|
rs1035990533 CA360325461 |
160 | G>C | No |
ClinGen TOPMed gnomAD |
|
|
rs1256859897 CA360325459 |
160 | G>D | No |
ClinGen TOPMed gnomAD |
|
|
rs1035990533 CA121423899 |
160 | G>R | No |
ClinGen TOPMed gnomAD |
|
|
CA360325448 rs1232764544 |
161 | E>* | No |
ClinGen gnomAD |
|
|
rs1310584847 CA360325435 |
161 | E>D | No |
ClinGen gnomAD |
|
|
rs1309218640 CA360325428 |
162 | R>C | No |
ClinGen gnomAD |
|
|
CA360325424 rs1325316264 |
162 | R>P | No |
ClinGen TOPMed |
|
|
CA360325407 rs1307572192 |
163 | A>D | No |
ClinGen TOPMed gnomAD |
|
|
rs1376725093 CA360325417 |
163 | A>T | No |
ClinGen gnomAD |
|
|
CA360325409 rs1307572192 |
163 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1243496788 CA360325375 |
166 | R>G | No |
ClinGen gnomAD |
|
|
CA360325371 rs1349751465 |
166 | R>Q | No |
ClinGen TOPMed |
|
|
CA360325360 rs1234199523 |
167 | R>K | No |
ClinGen gnomAD |
|
|
rs1286211143 CA360325348 |
168 | R>W | No |
ClinGen TOPMed |
|
|
rs1002792929 CA121423897 |
172 | Q>E | No |
ClinGen TOPMed |
|
|
rs1407273887 CA360325285 |
176 | R>C | No |
ClinGen gnomAD |
|
|
CA360325287 rs1407273887 |
176 | R>S | No |
ClinGen gnomAD |
|
|
rs1469532694 CA360325277 |
177 | A>G | No |
ClinGen TOPMed |
|
|
CA360325280 rs1341204674 |
177 | A>P | No |
ClinGen Ensembl |
|
|
CA360325273 rs1450536143 |
178 | A>T | No |
ClinGen gnomAD |
|
|
CA360325270 rs1288423479 |
178 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
CA3314721 rs531117283 |
179 | A>G | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA121423893 rs531117283 |
179 | A>V | No |
ClinGen 1000Genomes ExAC TOPMed gnomAD |
|
|
CA121423891 rs565365861 |
180 | Q>R | No |
ClinGen 1000Genomes TOPMed gnomAD |
|
|
rs1356991879 CA360325255 |
181 | A>E | No |
ClinGen gnomAD |
|
|
CA360325253 rs1356991879 |
181 | A>V | No |
ClinGen gnomAD |
|
|
CA360325247 rs1160586164 |
182 | R>L | No |
ClinGen gnomAD |
|
|
CA121423889 rs545218118 |
183 | R>W | No |
ClinGen 1000Genomes TOPMed |
|
|
CA360325212 rs1580145398 |
188 | E>A | No |
ClinGen Ensembl |
|
|
rs1379554220 CA360325215 |
188 | E>K | No |
ClinGen TOPMed gnomAD |
|
|
CA360325206 rs765047926 |
189 | R>W | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1446262847 CA360325190 |
191 | A>G | No |
ClinGen TOPMed gnomAD |
|
|
rs1446262847 CA360325189 |
191 | A>V | No |
ClinGen TOPMed gnomAD |
|
|
rs1200150891 CA360325181 |
193 | Q>* | No |
ClinGen gnomAD |
|
|
rs1482365114 CA360325172 |
194 | A>E | No |
ClinGen TOPMed gnomAD |
|
|
CA360325168 rs1262572928 |
195 | R>W | No |
ClinGen TOPMed gnomAD |
|
|
rs1336230119 CA360325149 |
198 | D>V | No |
ClinGen TOPMed |
|
|
CA360325134 rs1271765589 |
200 | S>R | No |
ClinGen TOPMed |
|
|
rs753609606 CA3314718 |
201 | R>H | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs1182964236 CA360325125 |
202 | R>C | No |
ClinGen TOPMed |
|
|
CA360325123 rs1248767332 |
202 | R>L | No |
ClinGen gnomAD |
|
|
CA360325118 rs1235028321 |
203 | E>A | No |
ClinGen TOPMed |
|
|
rs766400104 CA3314717 |
205 | A>T | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA360325099 rs1419238185 |
206 | L>P | No |
ClinGen TOPMed |
|
|
CA360325092 rs1376441807 |
207 | G>D | No |
ClinGen TOPMed gnomAD |
|
|
CA360325094 rs1376441807 |
207 | G>V | No |
ClinGen TOPMed gnomAD |
|
|
CA360325083 rs1290153829 |
208 | W>C | No |
ClinGen TOPMed gnomAD |
|
|
CA121423876 rs944339162 |
209 | A>D | No |
ClinGen TOPMed gnomAD |
|
|
CA3314715 rs774498544 |
209 | A>T | No |
ClinGen ExAC gnomAD |
|
|
rs763294757 CA3314714 |
210 | P>A | No |
ClinGen ExAC TOPMed gnomAD |
|
|
CA360325075 rs1561297155 |
210 | P>L | No |
ClinGen Ensembl |
|
|
rs763294757 CA3314713 |
210 | P>S | No |
ClinGen ExAC TOPMed gnomAD |
|
|
rs75274568 CA3314709 |
213 | P>T | No |
ClinGen 1000Genomes ESP ExAC TOPMed gnomAD |
|
|
rs776853797 CA3314708 |
214 | P>S | No |
ClinGen ExAC gnomAD |
|
|
CA360325047 rs1488027999 |
215 | P>L | No |
ClinGen gnomAD |
|
|
rs1194630385 CA360325052 |
215 | P>T | No |
ClinGen gnomAD |
|
|
rs747416575 CA360325033 |
217 | K>N | No |
ClinGen ExAC gnomAD |
|
|
rs1244445943 CA360325027 |
218 | D>V | No |
ClinGen gnomAD |
|
| TCGA novel | 219 | D>G | Variant assessed as Somatic; impact. [NCI-TCGA] | No | NCI-TCGA |
|
CA360325012 rs1357602823 |
220 | P>L | No |
ClinGen gnomAD |
|
|
CA3314704 rs370739839 |
221 | E>* | No |
ClinGen ESP ExAC TOPMed gnomAD |
|
|
CA121423858 rs868441142 |
222 | G>D | No |
ClinGen Ensembl |
|
|
CA121423856 rs868441142 |
222 | G>V | No |
ClinGen Ensembl |
|
|
CA360324999 rs747628565 |
223 | D>N | No |
ClinGen ExAC TOPMed |
|
|
rs747628565 CA3314702 |
223 | D>Y | No |
ClinGen ExAC TOPMed |
|
|
rs778587173 CA3314701 |
224 | R>M | No |
ClinGen ExAC gnomAD |
|
|
rs1279738019 CA360324988 |
224 | R>S | No |
ClinGen gnomAD |
|
|
rs778587173 CA360324989 |
224 | R>T | No |
ClinGen ExAC gnomAD |
|
|
rs1373898812 CA360324977 |
226 | G>R | No |
ClinGen TOPMed |
|
|
CA360324978 rs1373898812 |
226 | G>S | Variant assessed as Somatic; impact. [NCI-TCGA] | No |
ClinGen NCI-TCGA TOPMed |
|
CA360324973 rs1214989019 |
226 | G>V | No |
ClinGen gnomAD |
|
|
CA360324968 rs1580145200 |
227 | C>S | No |
ClinGen Ensembl |
|
|
rs1388449812 CA360324955 |
229 | I>T | No |
ClinGen TOPMed gnomAD |
|
|
CA360324957 rs1295745219 |
229 | I>V | No |
ClinGen gnomAD |
|
|
rs1391314698 CA360324944 |
231 | K>E | No |
ClinGen gnomAD |
|
|
rs1456244447 CA360324927 |
233 | L>P | No |
ClinGen gnomAD |
|
|
rs1171743793 CA360324914 |
235 | L>Y | No |
ClinGen TOPMed gnomAD |
No associated diseases with Q96IU2
1 regional properties for Q96IU2
| Type | Name | Position | InterPro Accession |
|---|---|---|---|
| domain | Zinc finger, BED-type | 43 - 104 | IPR003656 |
5 GO annotations of cellular component
| Name | Definition |
|---|---|
| chromatin | The ordered and organized complex of DNA, protein, and sometimes RNA, that forms the chromosome. |
| cytoplasm | The contents of a cell excluding the plasma membrane and nucleus, but including other subcellular structures. |
| cytosol | The part of the cytoplasm that does not contain organelles but which does contain other particulate matter, such as protein complexes. |
| extracellular space | That part of a multicellular organism outside the cells proper, usually taken to be outside the plasma membranes, and occupied by fluid. |
| membrane | A lipid bilayer along with all the proteins and protein complexes embedded in it an attached to it. |
3 GO annotations of molecular function
| Name | Definition |
|---|---|
| DNA-binding transcription factor activity, RNA polymerase II-specific | A DNA-binding transcription factor activity that modulates the transcription of specific gene sets transcribed by RNA polymerase II. |
| metal ion binding | Binding to a metal ion. |
| transcription cis-regulatory region binding | Binding to a specific sequence of DNA that is part of a regulatory region that controls transcription of that section of the DNA. The transcribed region might be described as a gene, cistron, or operon. |
13 GO annotations of biological process
| Name | Definition |
|---|---|
| actin filament organization | A process that is carried out at the cellular level which results in the assembly, arrangement of constituent parts, or disassembly of cytoskeletal structures comprising actin filaments. Includes processes that control the spatial distribution of actin filaments, such as organizing filaments into meshworks, bundles, or other structures, as by cross-linking. |
| endoplasmic reticulum localization | Any process in which endoplasmic reticulum is transported to, and/or maintained in, a specific location within the cell. |
| establishment of spindle localization | The directed movement of the spindle to a specific location in the cell. |
| mitochondrion localization | Any process in which a mitochondrion or mitochondria are transported to, and/or maintained in, a specific location within the cell. |
| negative regulation of protein phosphorylation | Any process that stops, prevents or reduces the rate of addition of phosphate groups to amino acids within a protein. |
| positive regulation of canonical Wnt signaling pathway | Any process that increases the rate, frequency, or extent of the Wnt signaling pathway through beta-catenin, the series of molecular signals initiated by binding of a Wnt protein to a frizzled family receptor on the surface of the target cell, followed by propagation of the signal via beta-catenin, and ending with a change in transcription of target genes. |
| positive regulation of embryonic development | Any process that activates or increases the frequency, rate or extent of embryonic development. |
| positive regulation of transcription by RNA polymerase II | Any process that activates or increases the frequency, rate or extent of transcription from an RNA polymerase II promoter. |
| protein stabilization | Any process involved in maintaining the structure and integrity of a protein and preventing it from degradation or aggregation. |
| regulation of transcription by RNA polymerase II | Any process that modulates the frequency, rate or extent of transcription mediated by RNA polymerase II. |
| response to glucose | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of a glucose stimulus. |
| response to insulin | Any process that results in a change in state or activity of a cell or an organism (in terms of movement, secretion, enzyme production, gene expression, etc.) as a result of an insulin stimulus. Insulin is a polypeptide hormone produced by the islets of Langerhans of the pancreas in mammals, and by the homologous organs of other organisms. |
| Wnt signaling pathway | The series of molecular signals initiated by binding of a Wnt protein to a frizzled family receptor on the surface of the target cell and ending with a change in cell state. |
No homologous proteins in AiPD
| UniProt AC | Gene Name | Protein Name | Species | Evidence Code |
|---|---|---|---|---|
| No homologous proteins | ||||
| 10 | 20 | 30 | 40 | 50 | 60 |
| MRSGEPACTM | DQARGLDDAA | ARGGQCPGLG | PAPTPTPPGR | LGAPYSEAWG | YFHLAPGRPG |
| 70 | 80 | 90 | 100 | 110 | 120 |
| HPSGHWATCR | LCGEQVGRGP | GFHAGTSALW | RHLRSAHRRE | LESSGAGSSP | PAAPCPPPPG |
| 130 | 140 | 150 | 160 | 170 | 180 |
| PAAAPEGDWA | RLLEQMGALA | VRGSRREREL | ERRELAVEQG | ERALERRRRA | LQEEERAAAQ |
| 190 | 200 | 210 | 220 | 230 | |
| ARRELQAERE | ALQARLRDVS | RREGALGWAP | AAPPPLKDDP | EGDRDGCVIT | KVLL |